JEV-27B-VL Pairs Vision-Language With Calibrated Odds
A 27B vision-language model from autotrust aims to output typed decisions with probabilities you can actually trust.
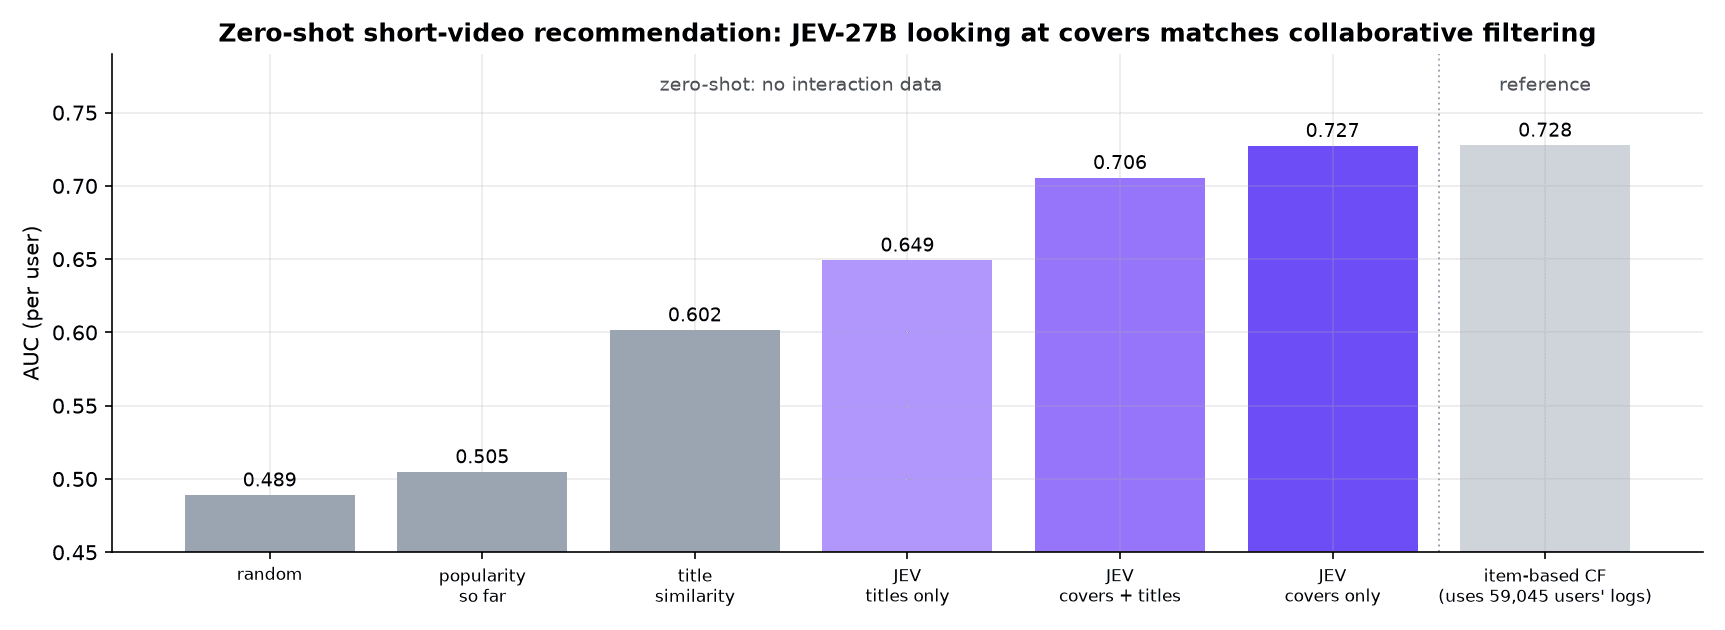
The team at autotrust has released JEV-27B-VL, a 27-billion-parameter vision-language model built around an unusual goal: producing not just answers, but typed decisions accompanied by calibrated probabilities. The model is now available on Hugging Face.
Most multimodal systems return free-form text, leaving downstream applications to guess how confident the model really is. JEV-27B-VL instead frames its outputs as structured decisions with attached probability estimates — a design that matters most when a wrong answer carries real cost and a system needs to know when to defer, escalate, or abstain.
Why it matters
Calibration is one of the quieter problems in applied AI. A model that is confidently wrong is harder to deploy safely than one that signals uncertainty honestly. By emphasizing calibrated probabilities over raw generations, JEV-27B-VL is positioning itself for workflows where decisions must be auditable.
- Size: 27B parameters, a dense (non-MoE) architecture
- Modality: vision-language, handling both images and text
- Focus: typed decisions with calibrated probability outputs
Key details remain thin — the listing does not specify context length or publish benchmark figures, and the license is marked as "other," so teams evaluating it for production should check the terms on the model card closely. Still, as an opening release for the JEV family, it stakes out a clear and practical niche in the crowded field of open vision-language models.
Sources
- Visit
autotrust/JEV-27B-VL
Hugging Face
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
0 comments
No comments yet. Be the first to weigh in.