Cactus Compute's Whistle brings speech-to-text to the edge
A compact on-device ASR model built for edge hardware and WebAssembly, with early support for English, German, and French.
Cactus Compute has released Whistle, a speech-to-text model designed to run directly on edge devices and in the browser via WebAssembly. Rather than chasing the largest possible accuracy ceiling, the project aims squarely at deployment where cloud round-trips aren't an option — phones, embedded hardware, and web apps that need transcription without a server.
The initial release covers three languages — English, German, and French — according to its Hugging Face repository. That focused scope fits the on-device brief: a tighter language set keeps the model small enough to load and run locally without specialized accelerators.
Why it matters
On-device automatic speech recognition addresses two concerns that dominate real-world deployments:
- Privacy: audio never leaves the device, which matters for regulated industries and consumer trust.
- Latency and cost: local inference removes network dependence and per-request API fees, making always-on transcription practical.
The WebAssembly angle is notable. Shipping ASR that runs in a standard browser sandbox lowers the barrier for web developers who want transcription features without maintaining backend infrastructure or asking users to install native software.
The release is an initial version, and key details — parameter count, context handling, and benchmark figures — aren't specified in the record. Developers evaluating Whistle for production should test transcription quality against their own audio and language needs, since edge-optimized models typically trade some accuracy for footprint and speed.
Sources
More from Cactus Compute
All Cactus Compute releases →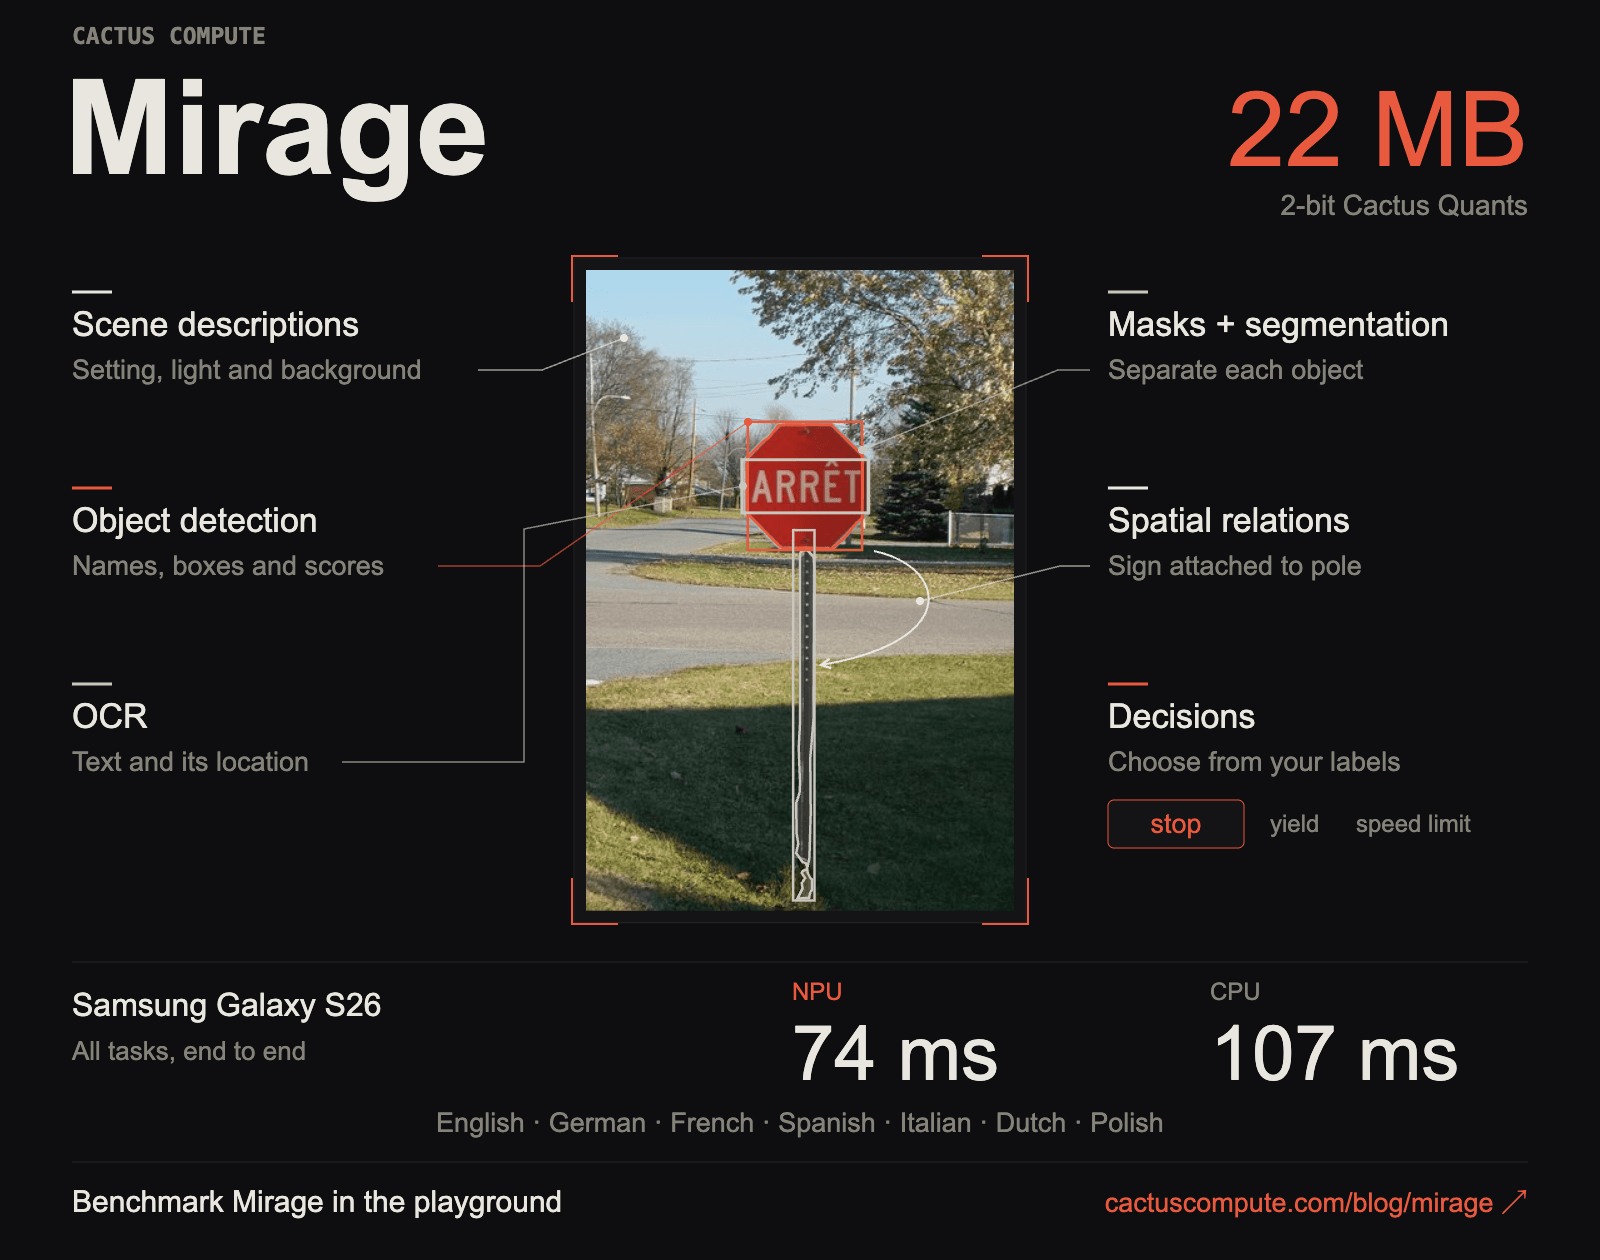
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
Cactus Needle 3: tiny on-device tool-calling models
Cactus Compute's 8–29MB models aim to run automation and tool-calling entirely on-device, rivaling far larger cloud systems.
Needle2 Packs an Agentic LLM Into 14MB
Cactus Compute's tiny model brings tool and function calling to phones, wearables, and robots.
More in Speech → Text
All Speech → Text →
Reson8's Rumble-2-Flash Puts ASR in 0.5B Params
A compact open speech recognition model aims to transcribe more than 40 languages without heavyweight infrastructure.

Haru-4B Brings Full-Duplex Speech to Six Languages
A compact 4-billion-parameter model handles real-time, two-way voice conversation across six languages in a single system.
ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.
0 comments
No comments yet. Be the first to weigh in.