Swift-1.5 Trims Reasoning Tokens on a 27B Qwen Model
XingChen-AGI's new tune aims to make Qwen3.8-27B reason faster by cutting its thinking budget roughly in half.
XingChen-AGI has released Swift-1.5-Qwen3.8-27B, a 27-billion-parameter reasoning model built on the Qwen3.8 base. The headline pitch is efficiency: the team says the tune cuts the number of "thinking" tokens a model generates by roughly 58 percent, translating to about twice the inference speed.
That focus addresses a real pain point. Reasoning models often arrive at better answers by producing long internal chains of thought, but those extra tokens cost time and money. A tune that preserves answer quality while shortening the deliberation step is attractive for anyone running these models at scale or on constrained hardware.
What it offers
- A dense 27B model (not a mixture-of-experts) in the 13B–34B class
- Reasoning as the primary focus, with listed vision-language capabilities
- A claimed ~58% reduction in thinking tokens and roughly 2x speedup
A few important details are not spelled out in the release record, including the context length and the specifics of the custom license, which is marked simply as "other." Prospective users should check the model card for terms and usage guidance before deploying.
The efficiency claims here are the model's own, and independent benchmarks will be the real test. Still, the release reflects a broader trend in open-weight AI: after a wave of models chasing ever-longer reasoning traces, the next competitive frontier may be doing more with fewer tokens.
Sources
- Visit
ukisai/Swift-1.5-Qwen3.8-27b
Hugging Face
More in Reasoning
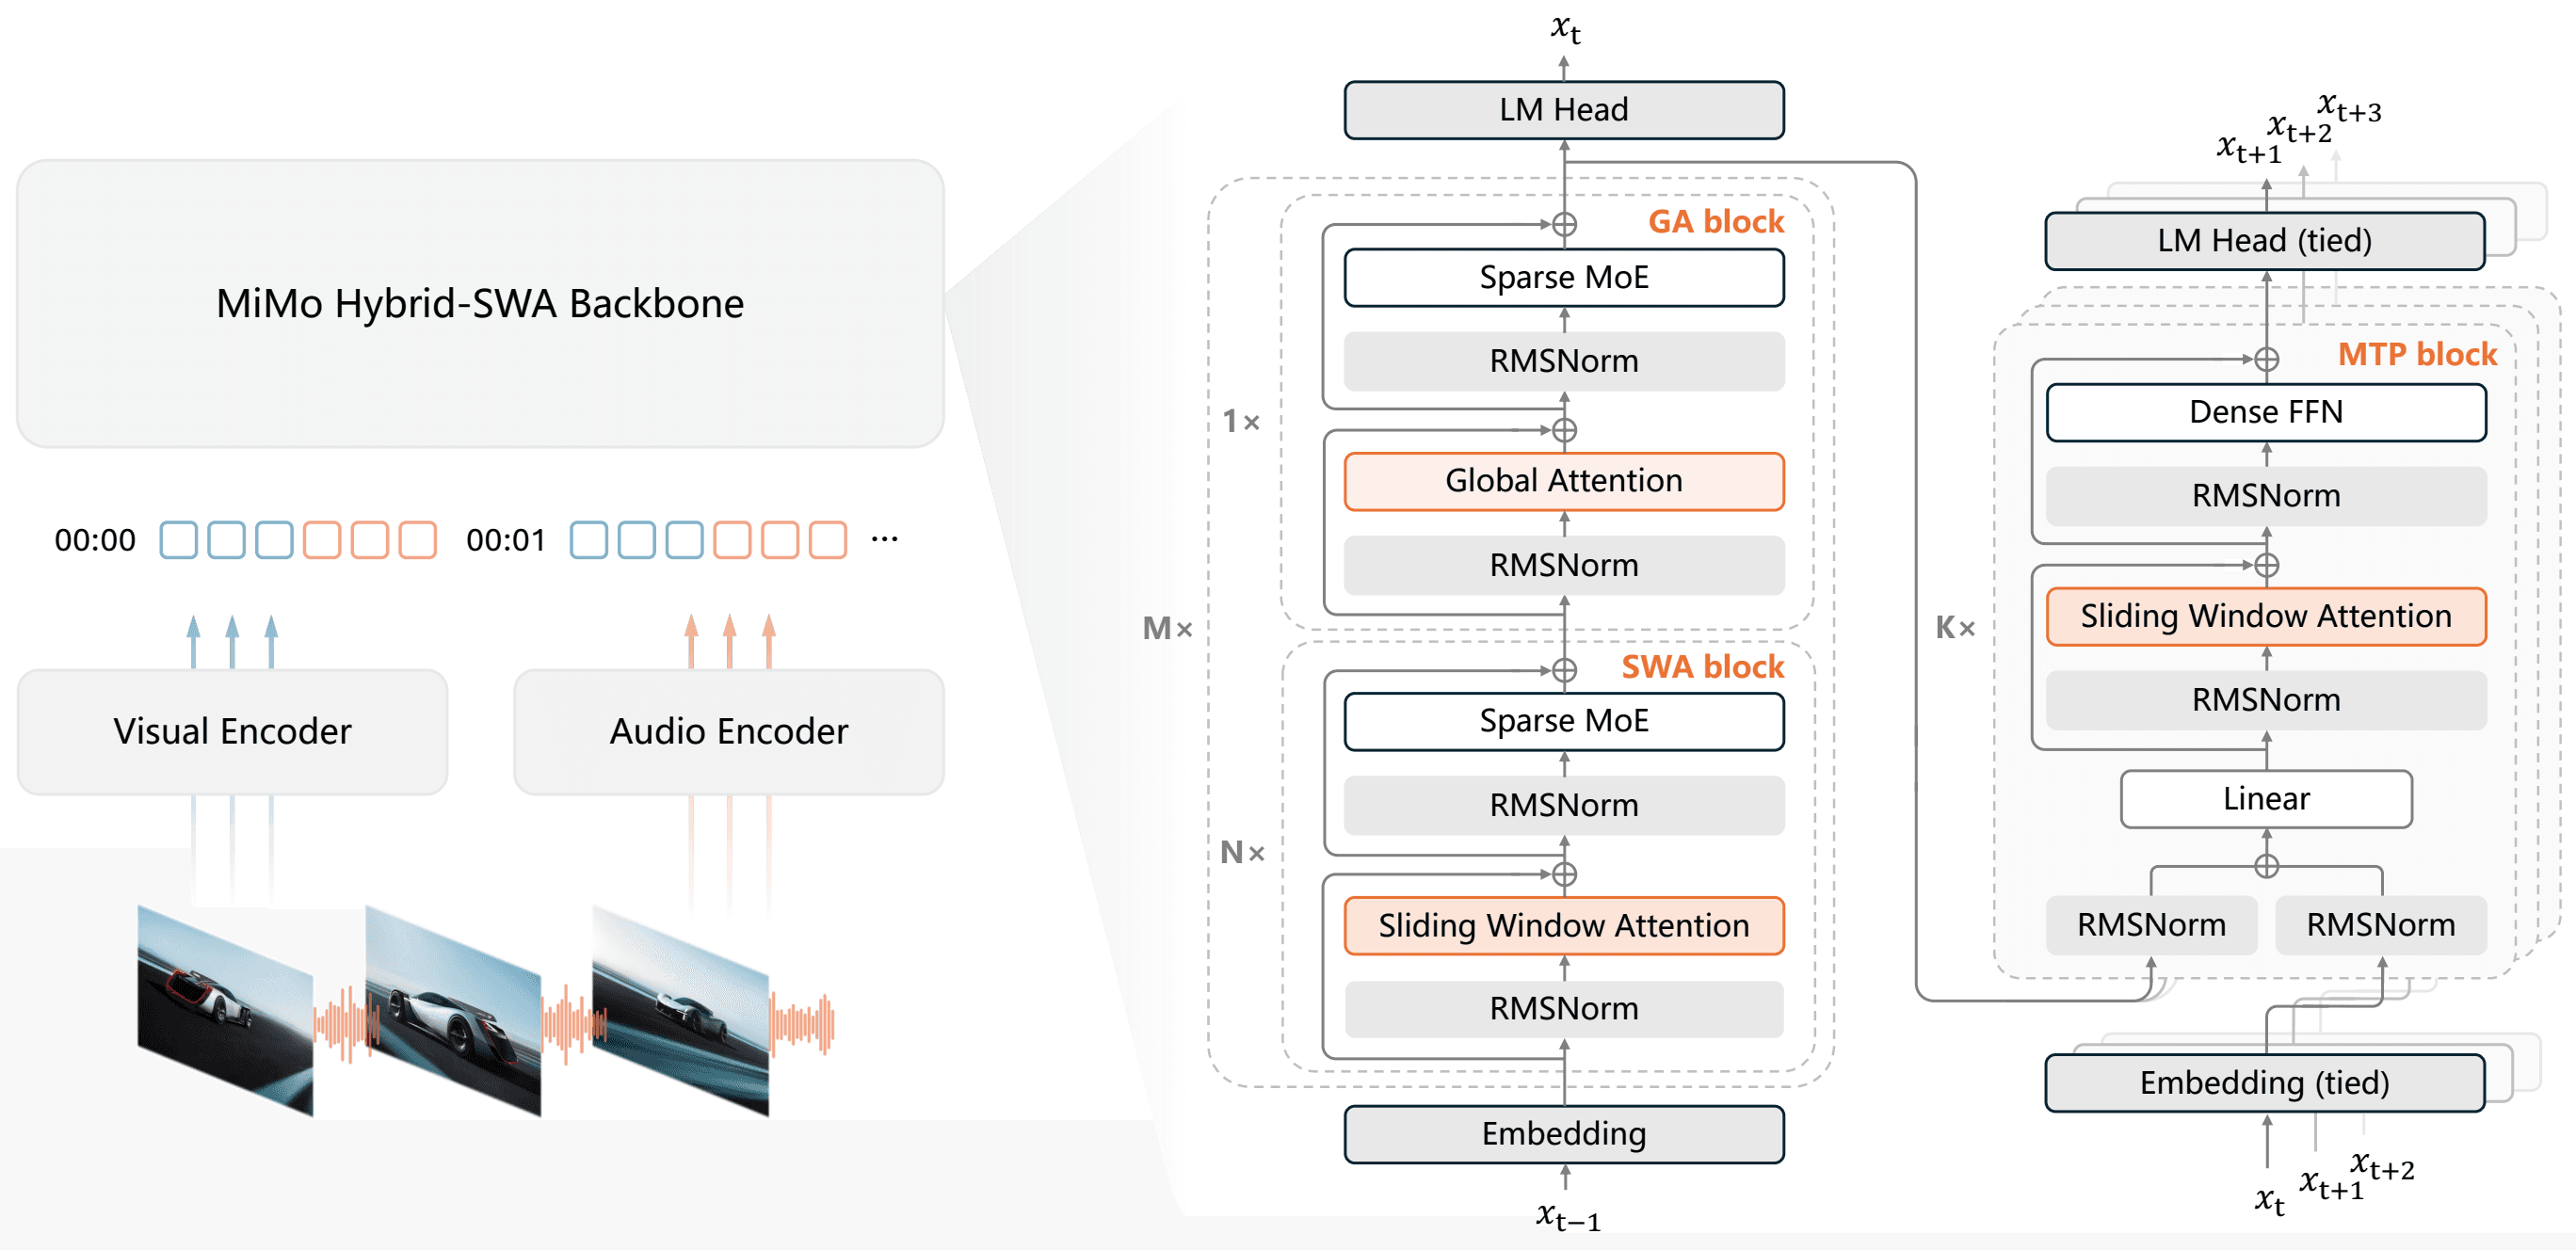
Xiaomi expands MiMo line with V2.6 multimodal models
The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.
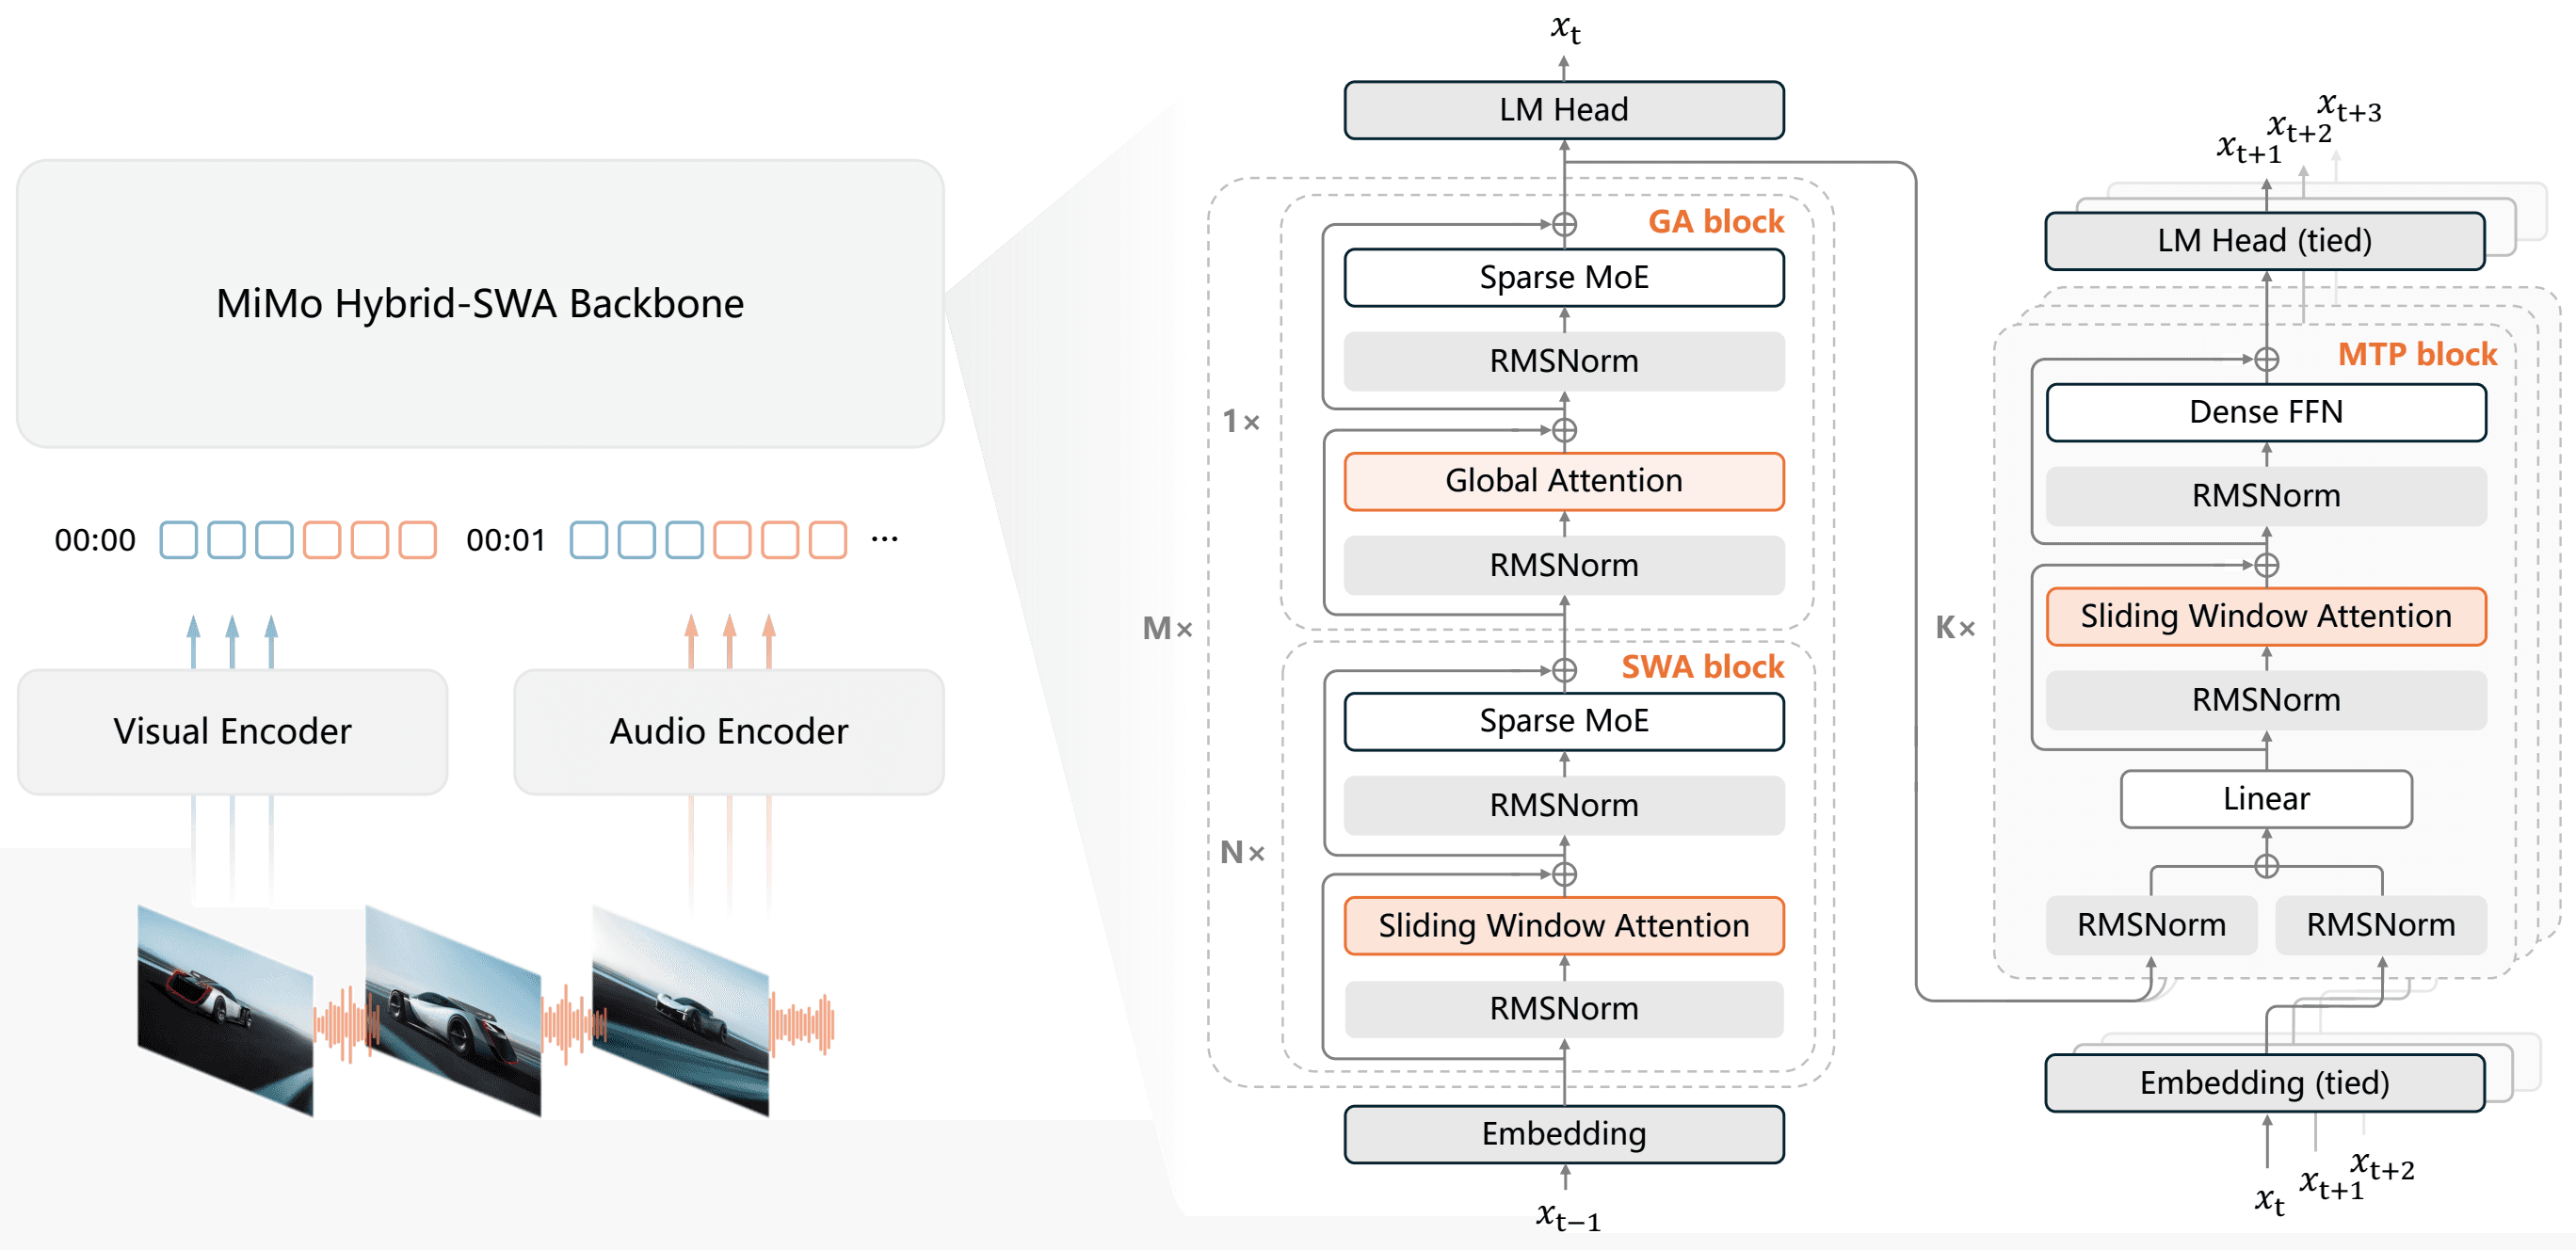
Xiaomi's MiMo V2.6-Pro-RL Targets Agentic Multimodal Work
An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.
Agnes-3.0-Flash arrives as a multimodal reasoning model
The new release pairs vision-language understanding with a hybrid-attention design aimed at long-context reasoning.
0 comments
No comments yet. Be the first to weigh in.