Zhipu releases GLM-5.3-Flash under MIT license
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
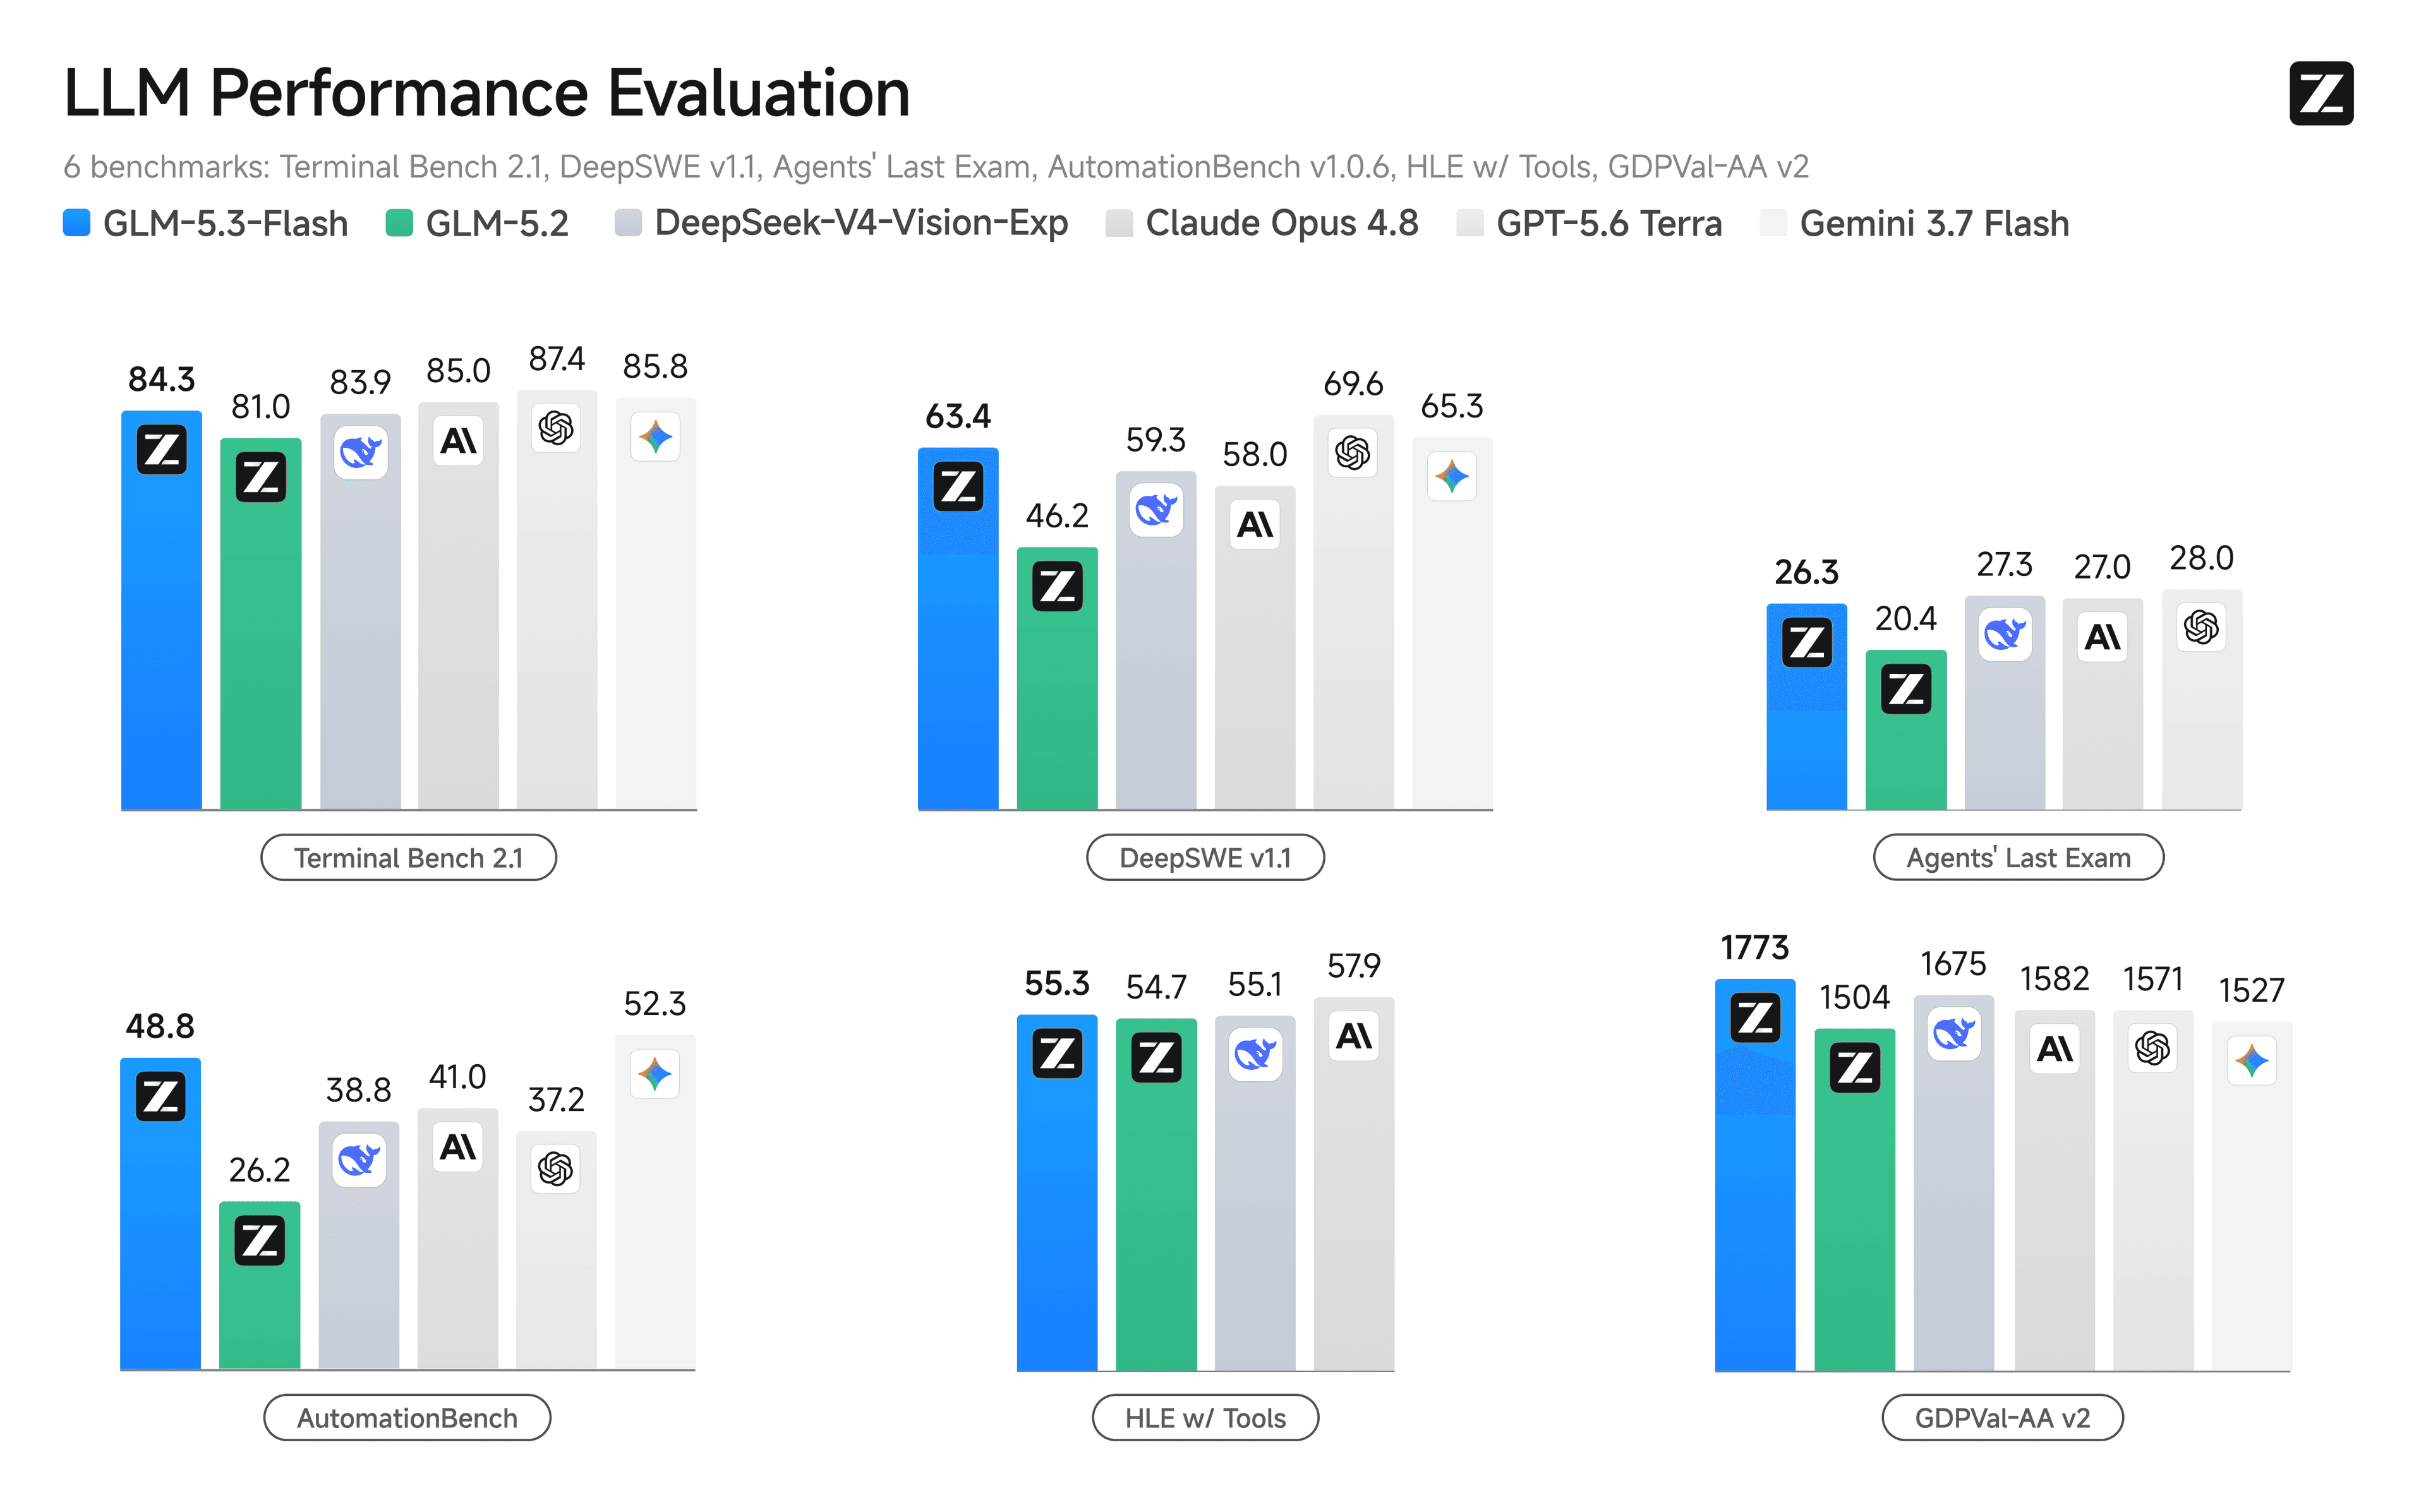
Zhipu AI has published GLM-5.3-Flash on Hugging Face, a speed-oriented variant of its GLM-5.3 line released under the permissive MIT license. The model ships as an open-weights download, letting developers run and modify it without the usage restrictions attached to many competing releases (Hugging Face).
The "Flash" designation signals a build tuned for lower latency and cheaper inference rather than maximum capability. It uses a mixture-of-experts (MoE) architecture, which activates only a subset of parameters per token — a common way to hold down compute cost while keeping a large total parameter pool. Zhipu positions the broader GLM-5.3 family as competitive with frontier closed models.
What's included
- Open weights distributed under the MIT license
- A mixture-of-experts design geared toward fast inference
- Support for text, vision-language, and reasoning tasks
Why it matters
Fast, permissively licensed models are increasingly where open-source AI competes hardest, since teams often care as much about serving cost and deployment freedom as raw benchmark scores. An MIT-licensed Flash tier lets startups and researchers build on GLM without negotiating commercial terms, and adds to the growing roster of capable Chinese open-weight models challenging the assumption that frontier-adjacent quality requires a closed API. Buyers should confirm exact context length and parameter details on the model card, which the record leaves unspecified.
Sources
- Visit
zai-org/GLM-5.3-Flash
Hugging Face
More from Zhipu AI
All Zhipu AI releases →Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
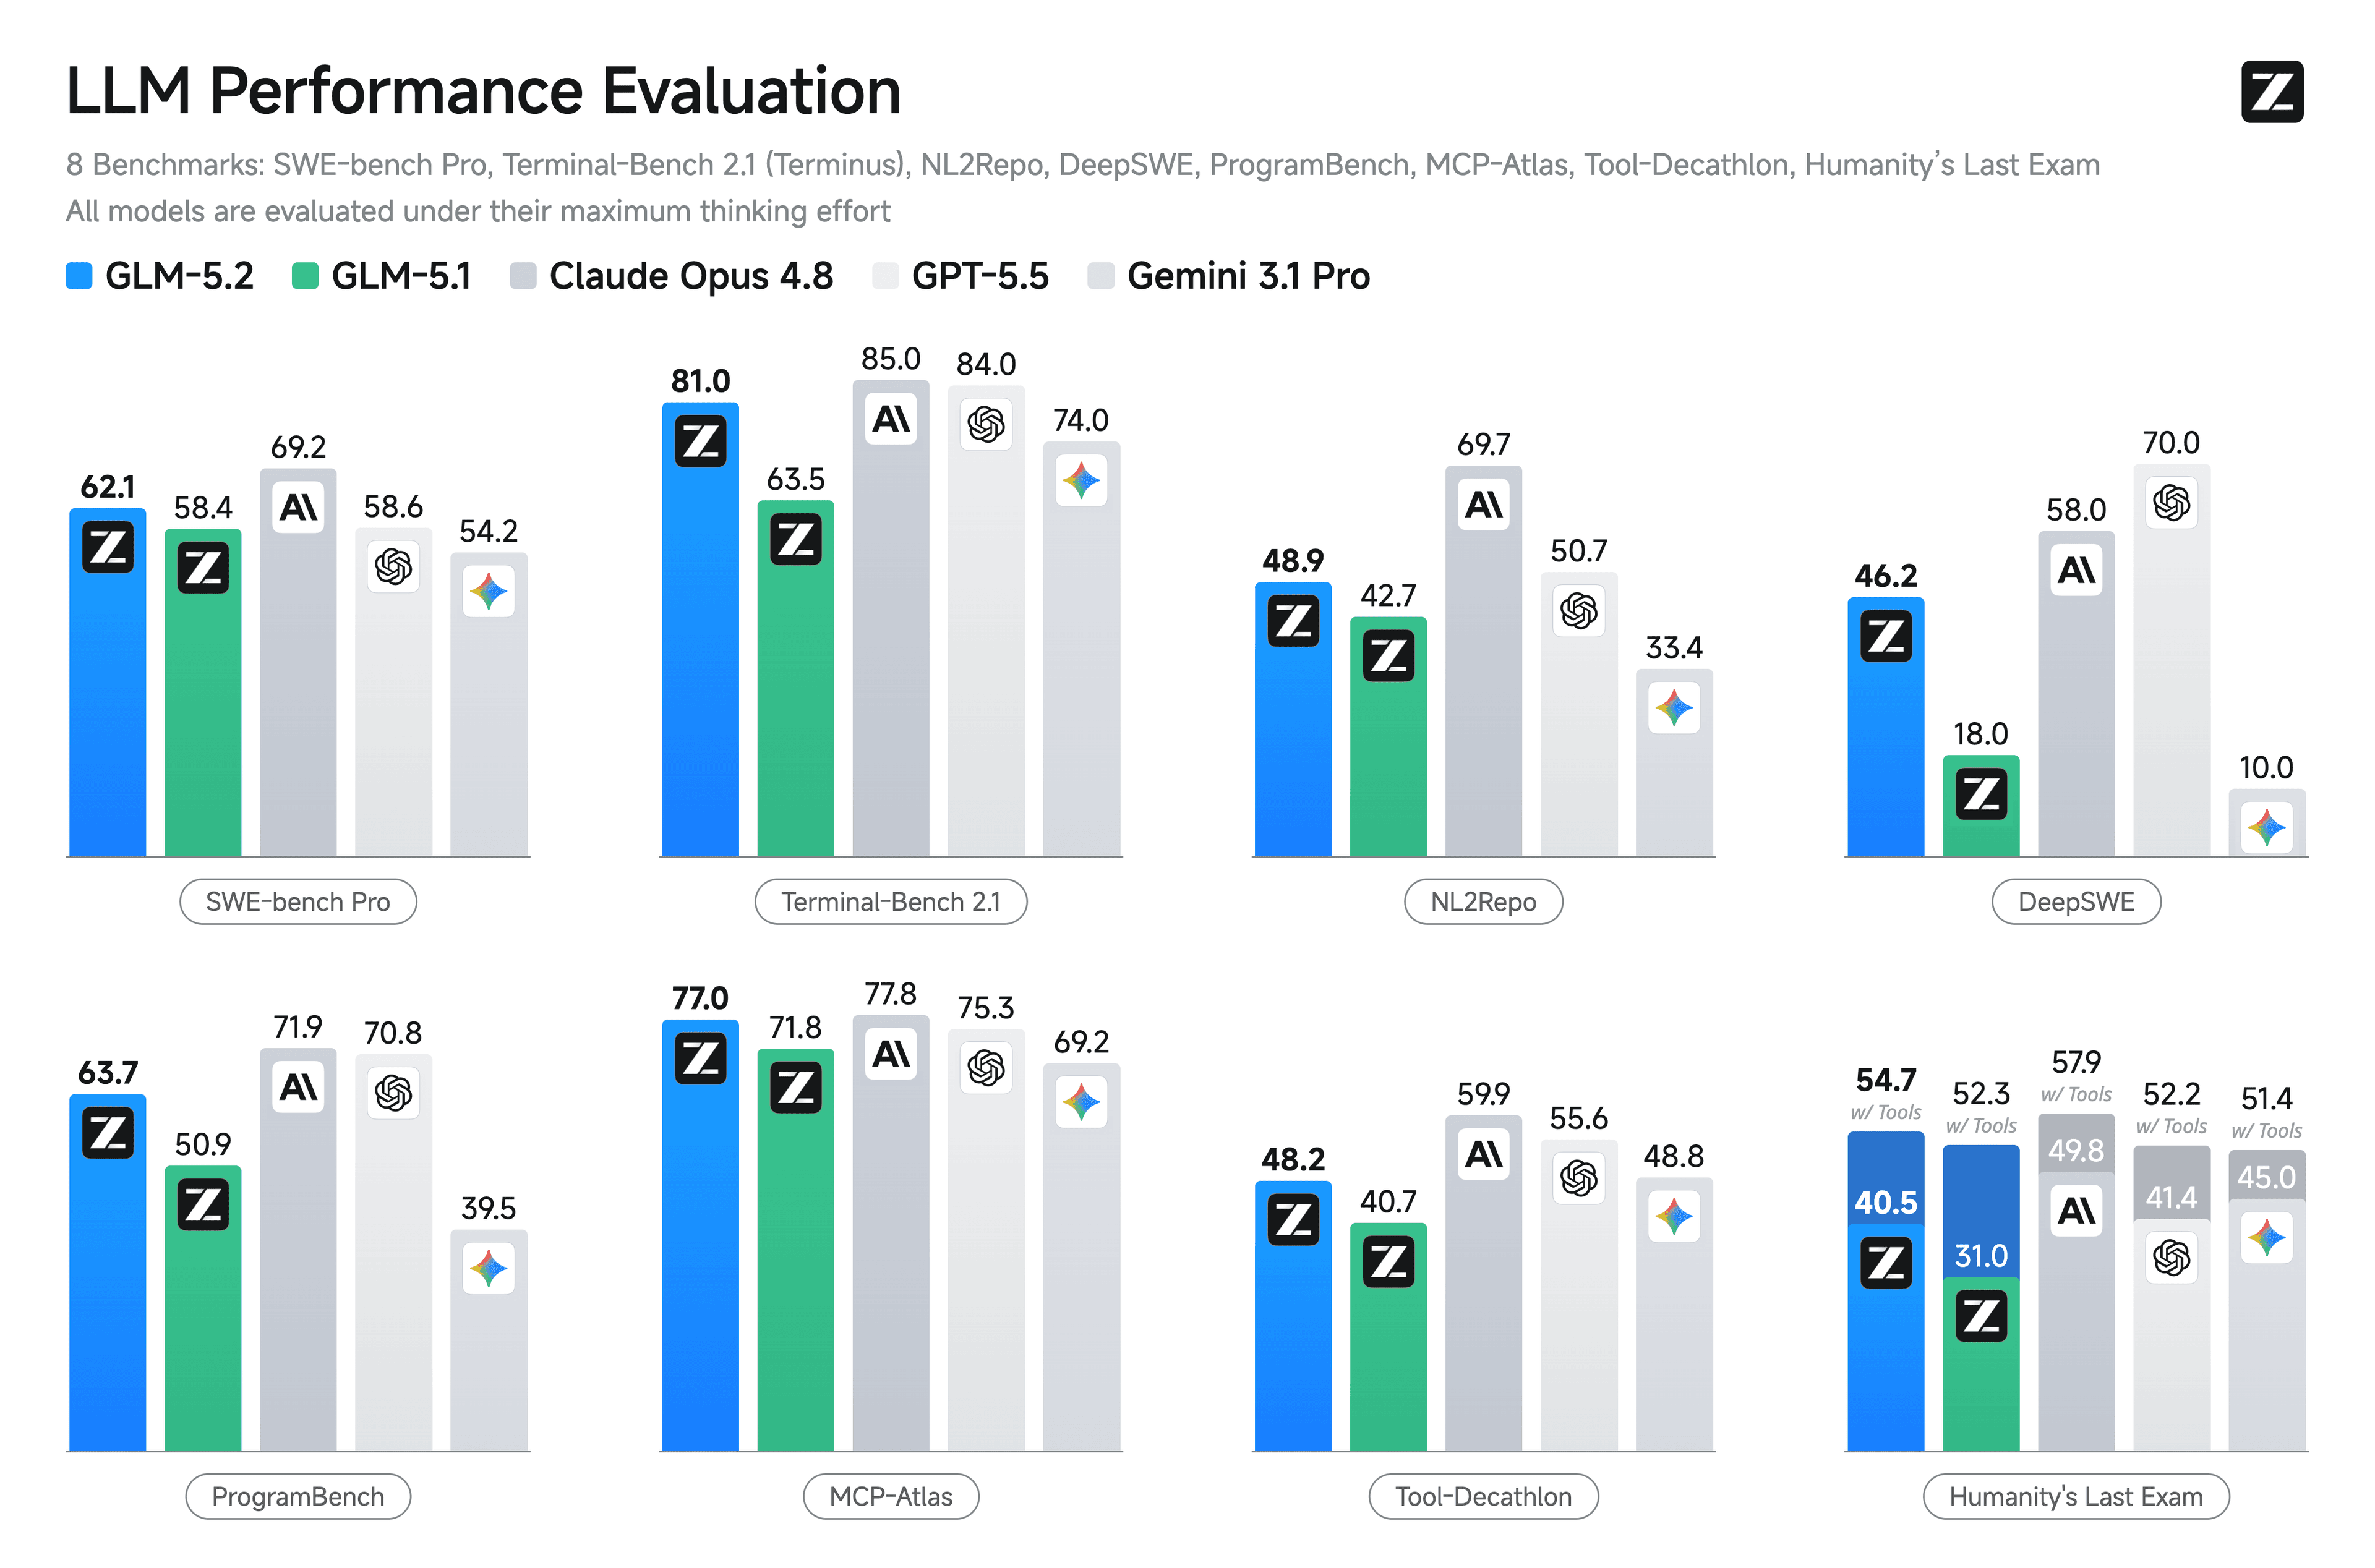
Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
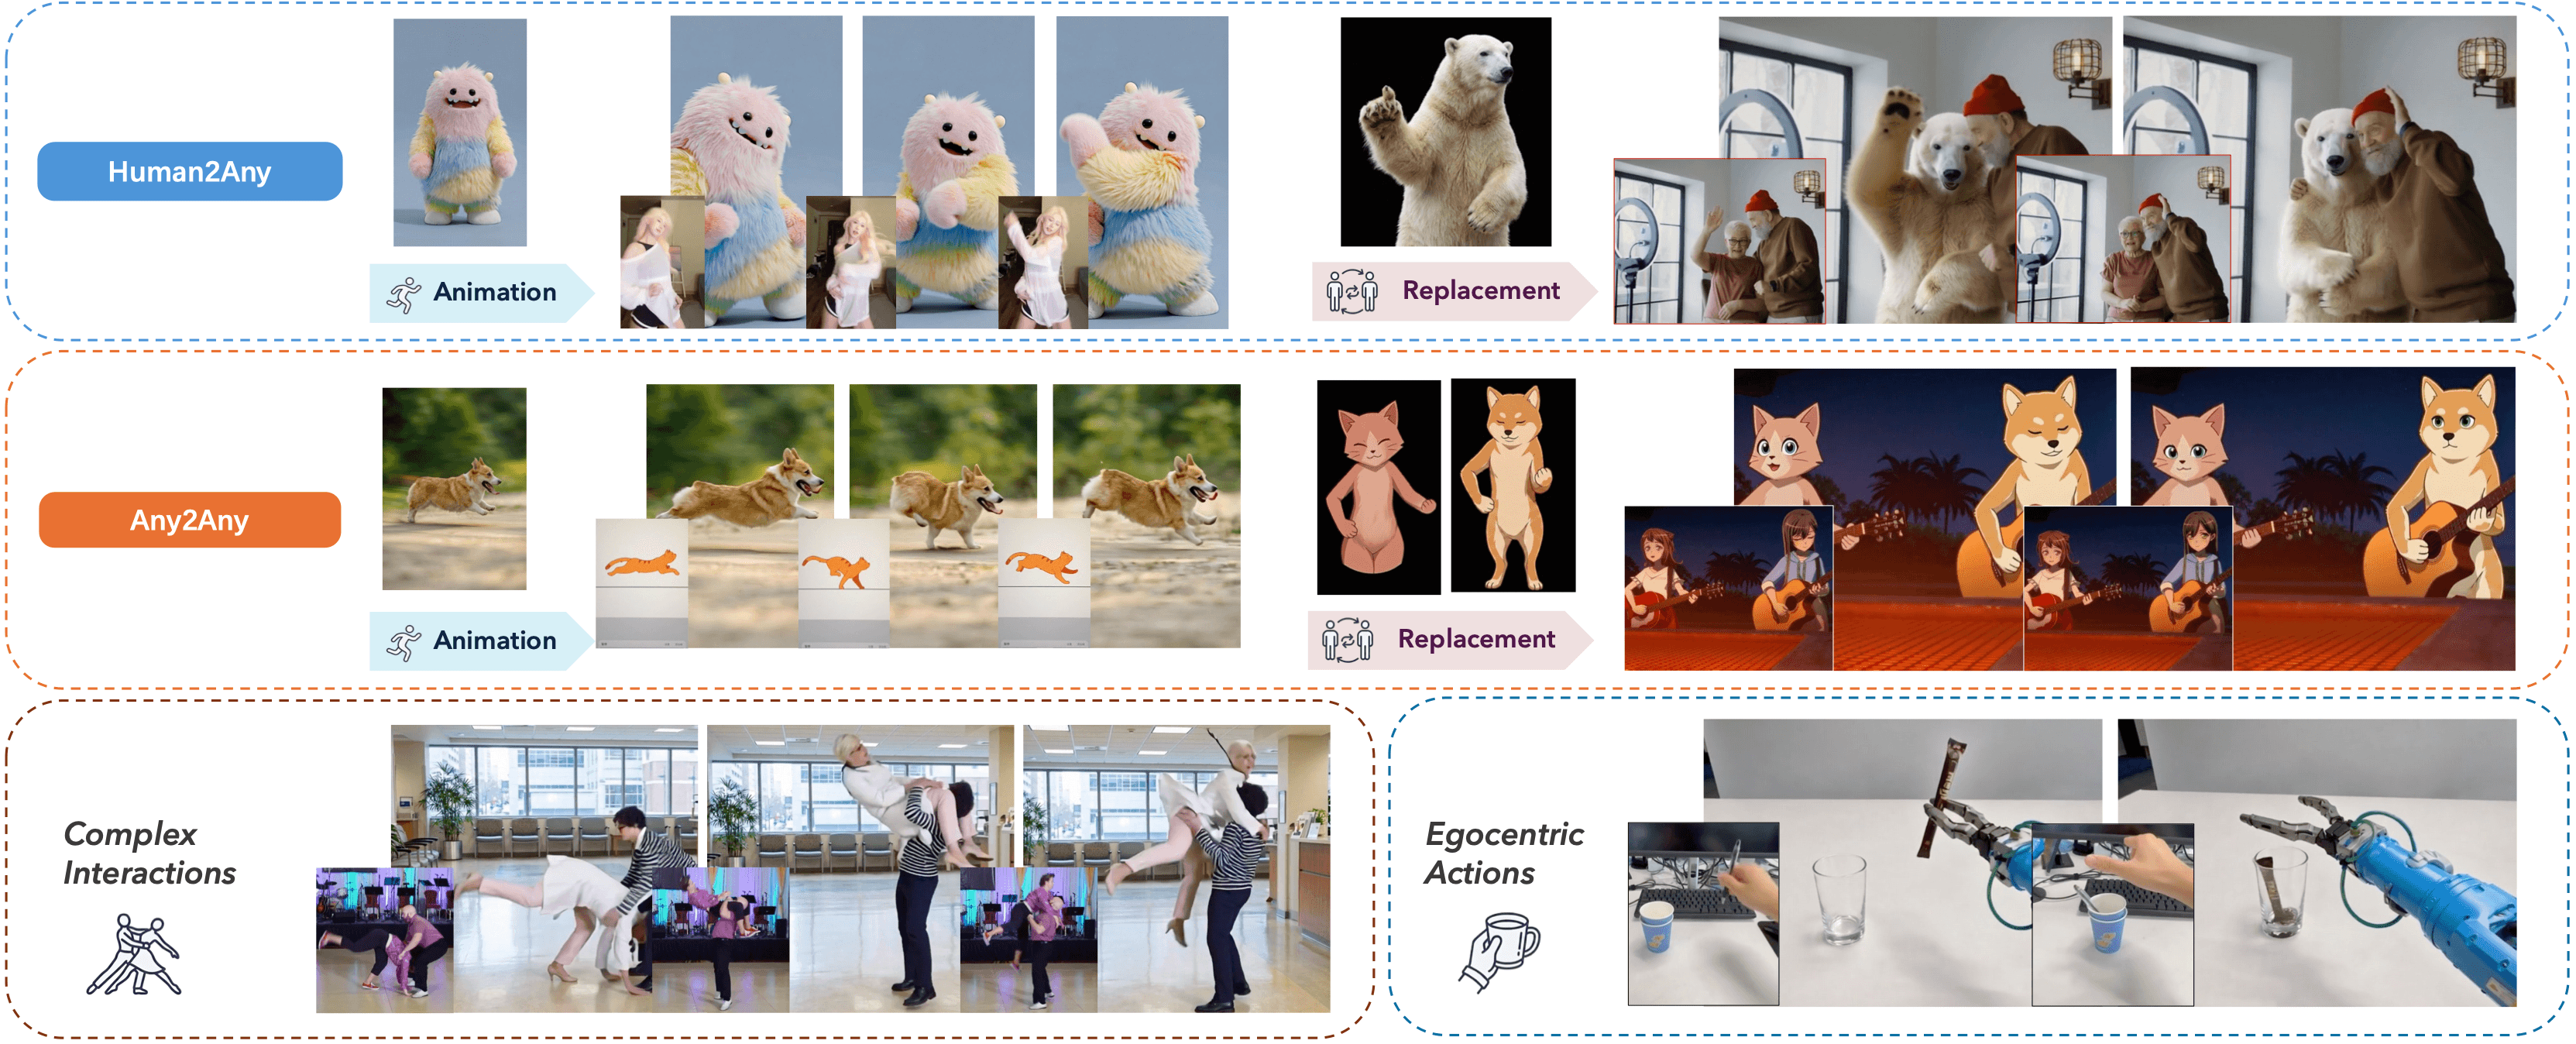
Zhipu AI Releases SCAIL-2 for Character Animation
The new open-source diffusion model from the company's research arm generates video clips from a single character image and a sequence of poses.
More in Text / LLM
All Text / LLM →Mistral Large 4 arrives as a trillion-param MoE
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
Falcon-Emirati tunes an LLM for local dialect
TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.
Reflection releases Beam, a 501B open-weight model
The startup's first frontier-scale model ships with downloadable weights and a mixture-of-experts design aimed at reasoning.
0 comments
No comments yet. Be the first to weigh in.