Aleph Alpha releases Kolibri, a sovereign reasoning model
The German AI company's open-weight mixture-of-experts model targets European needs with strong German and English reasoning.
Aleph Alpha has released Kolibri-1, an open-weight reasoning model that the German company frames as a sovereign alternative to models trained primarily for English-speaking markets. The release is available on Hugging Face and detailed in the company's launch announcement.
Kolibri-1 uses a mixture-of-experts (MoE) architecture, which activates only a subset of its parameters for any given token. That design has become a popular way to deliver stronger reasoning performance without paying the full compute cost of a dense model at inference time.
Why it matters
Aleph Alpha has positioned itself as a European champion in a field dominated by American and Chinese labs, and the "sovereign" framing speaks directly to that pitch. For public-sector and regulated industries in Europe, the appeal is concrete:
- Open weights that can be run on-premises or within controlled infrastructure
- First-class support for German alongside English
- A reasoning-focused model rather than a general chat assistant
The emphasis on native German capability is notable. Many leading open models treat European languages as an afterthought, and a model tuned for German reasoning could find a receptive audience among organizations with data-residency and language requirements.
Aleph Alpha has not published detailed specifications such as parameter counts or context length in this record, so practical evaluation will depend on hands-on testing. Still, the arrival of another credible open-weight reasoning model from a European lab adds welcome diversity to a crowded but geographically narrow landscape.
Sources
- Visit
Aleph-Alpha/Kolibri-1
Hugging Face
More in Reasoning
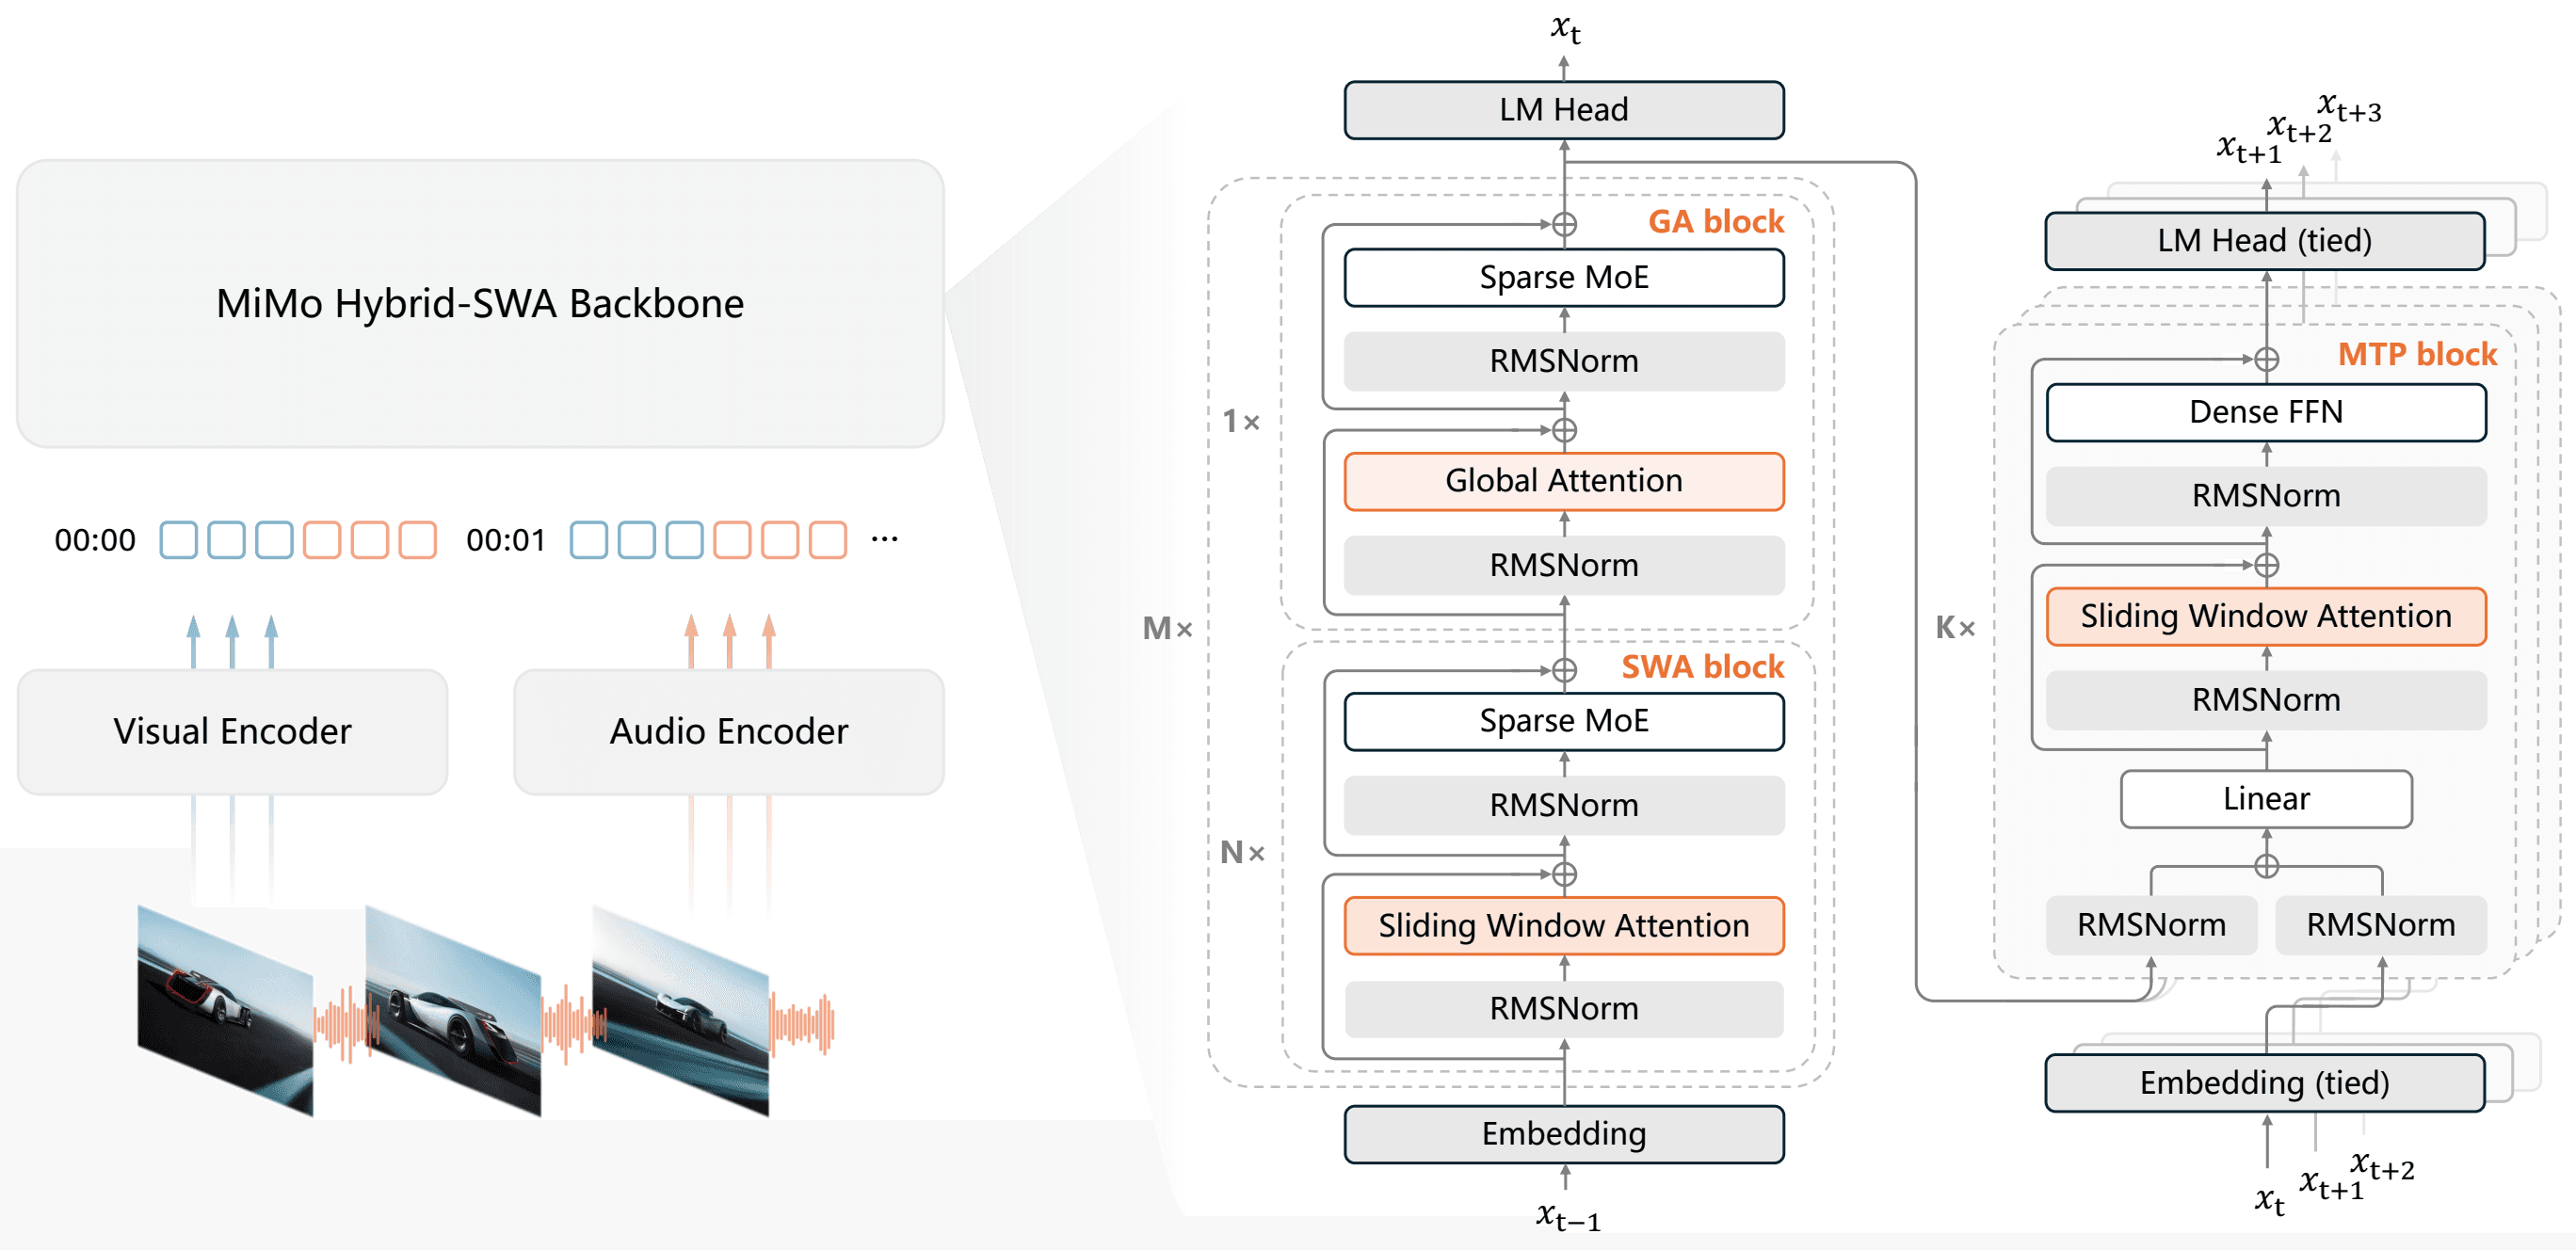
Xiaomi expands MiMo line with V2.6 multimodal models
The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.
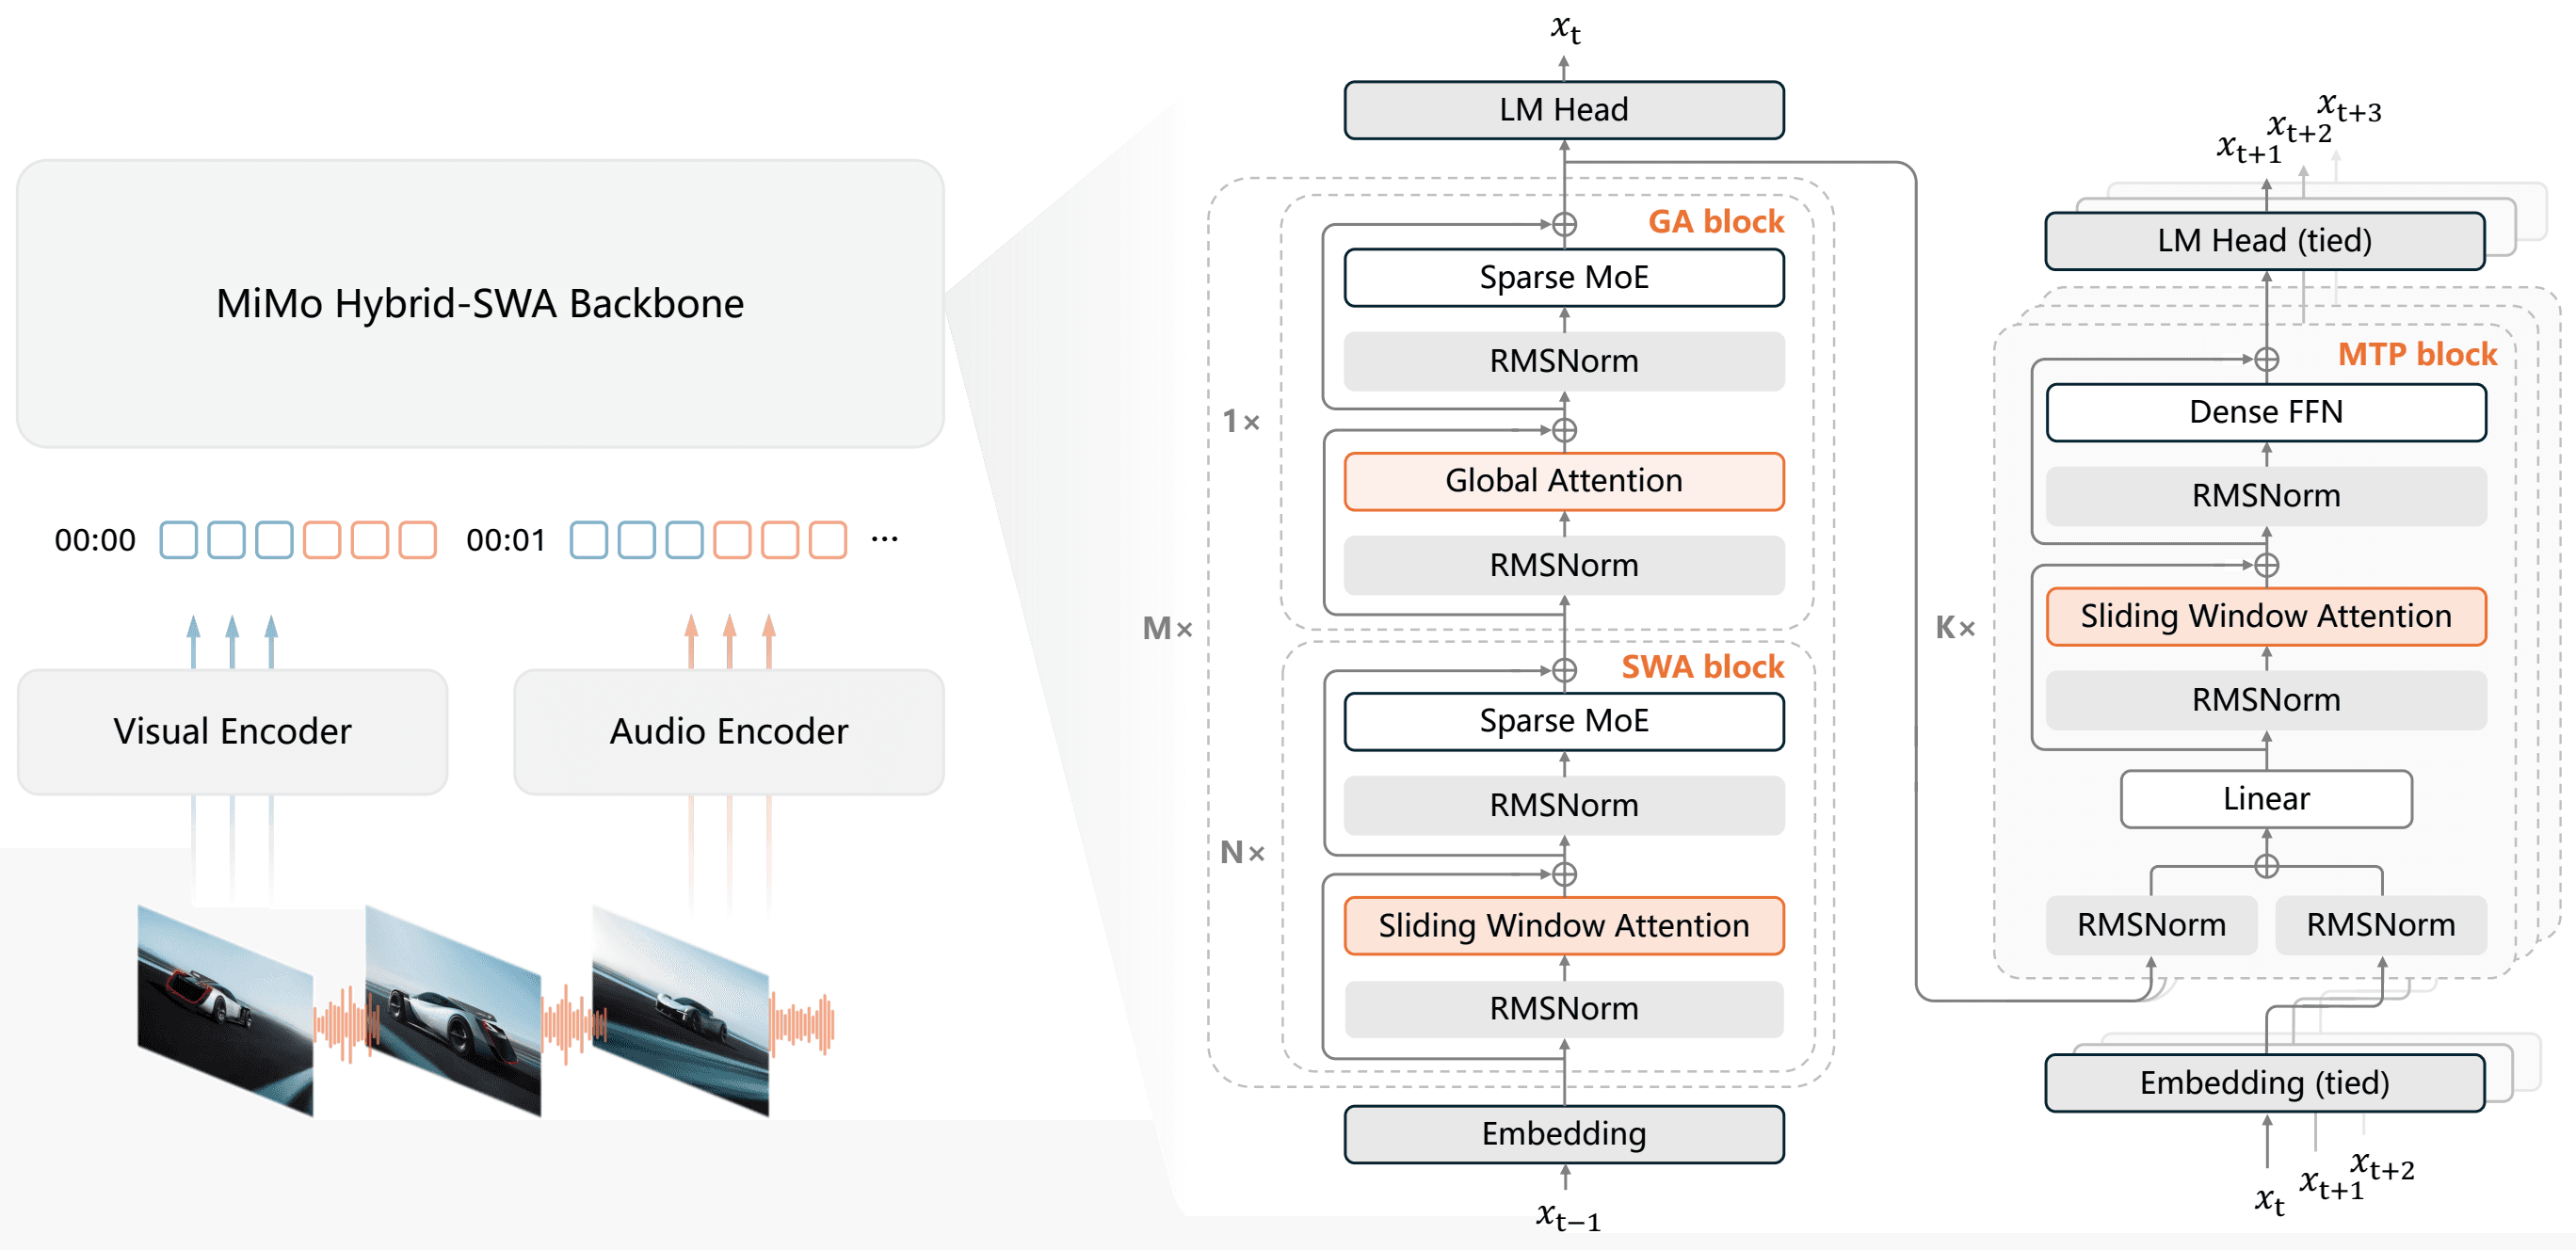
Xiaomi's MiMo V2.6-Pro-RL Targets Agentic Multimodal Work
An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.
Swift-1.5 Trims Reasoning Tokens on a 27B Qwen Model
XingChen-AGI's new tune aims to make Qwen3.8-27B reason faster by cutting its thinking budget roughly in half.
0 comments
No comments yet. Be the first to weigh in.