Perplexity releases a 27B model for multimodal routing
The open-weight 'decider' model is designed to classify queries and route them inside Perplexity's stack.

Perplexity has quietly published pplx-decider-v1-27b on Hugging Face, a 27-billion-parameter vision-language model built for decision-making and classification rather than open-ended chat. As the name suggests, the model is a "decider" — the kind of component that sits upstream in a pipeline and routes incoming requests to the right downstream system.
The release is dense model (not a mixture-of-experts) in the 13B–34B class, and it handles multimodal inputs, meaning it can weigh both text and images when making routing decisions. That fits Perplexity's product, where a single query might need web search, a direct answer, or a specialized tool, and where getting that triage right has an outsized effect on latency and cost.
Why it matters
Routing and classification models rarely get headlines, but they are increasingly where production AI systems live or die. A few reasons this release is notable:
- It is published under a permissive Apache 2.0 license, so others can study or adapt it.
- It targets a practical, unglamorous job — classification and routing — that most labs keep internal.
- A multimodal decider hints at how Perplexity is handling image-bearing queries in its stack.
Perplexity has not accompanied the weights with extensive documentation or benchmarks, so the model's exact capabilities and intended integration points remain thinly described on the model page. Still, the move continues a trend of search and assistant companies opening up the supporting infrastructure around their flagship systems, even when the flagship itself stays closed.
Sources
- Visit
perplexity-ai/pplx-decider-v1-27b
Hugging Face
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
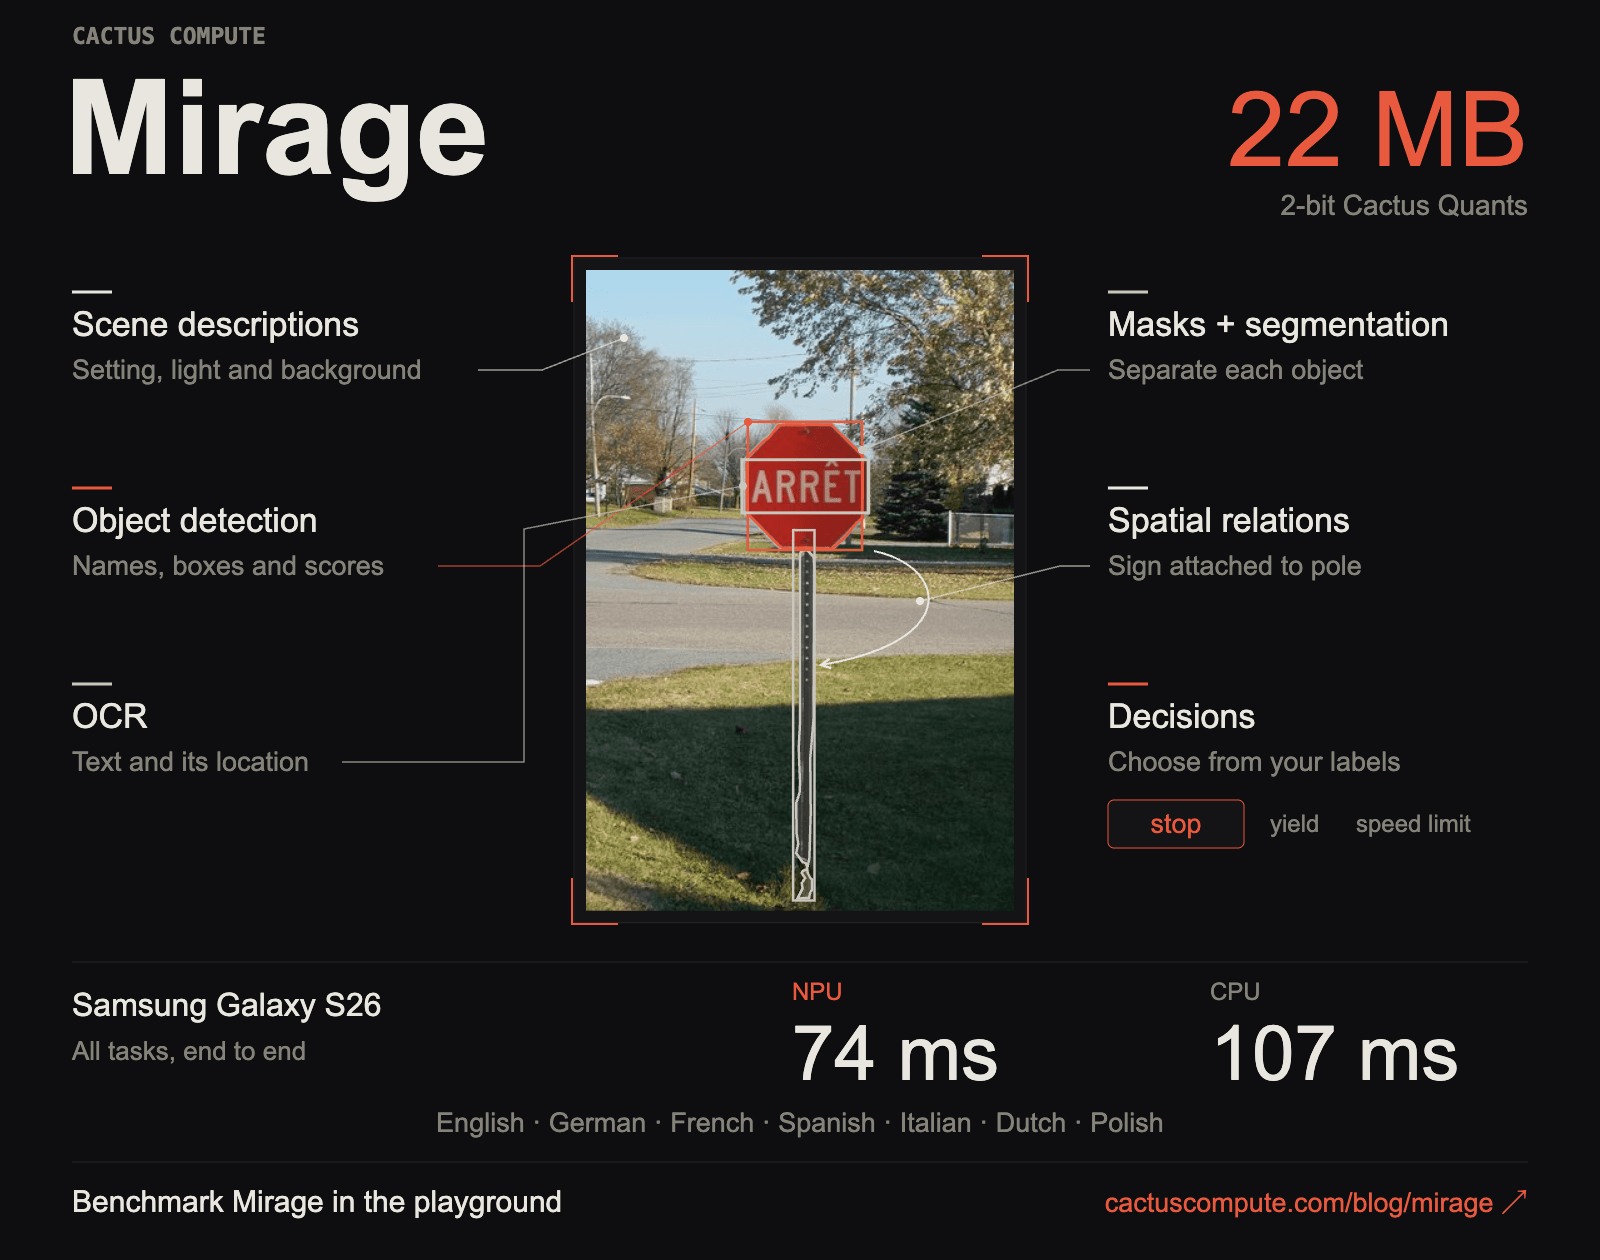
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
0 comments
No comments yet. Be the first to weigh in.