LG AI Research debuts K-EXAONE 2.0, a 750B MoE model
The new mixture-of-experts model activates 37B parameters per token and targets English, Korean, and Spanish reasoning tasks.
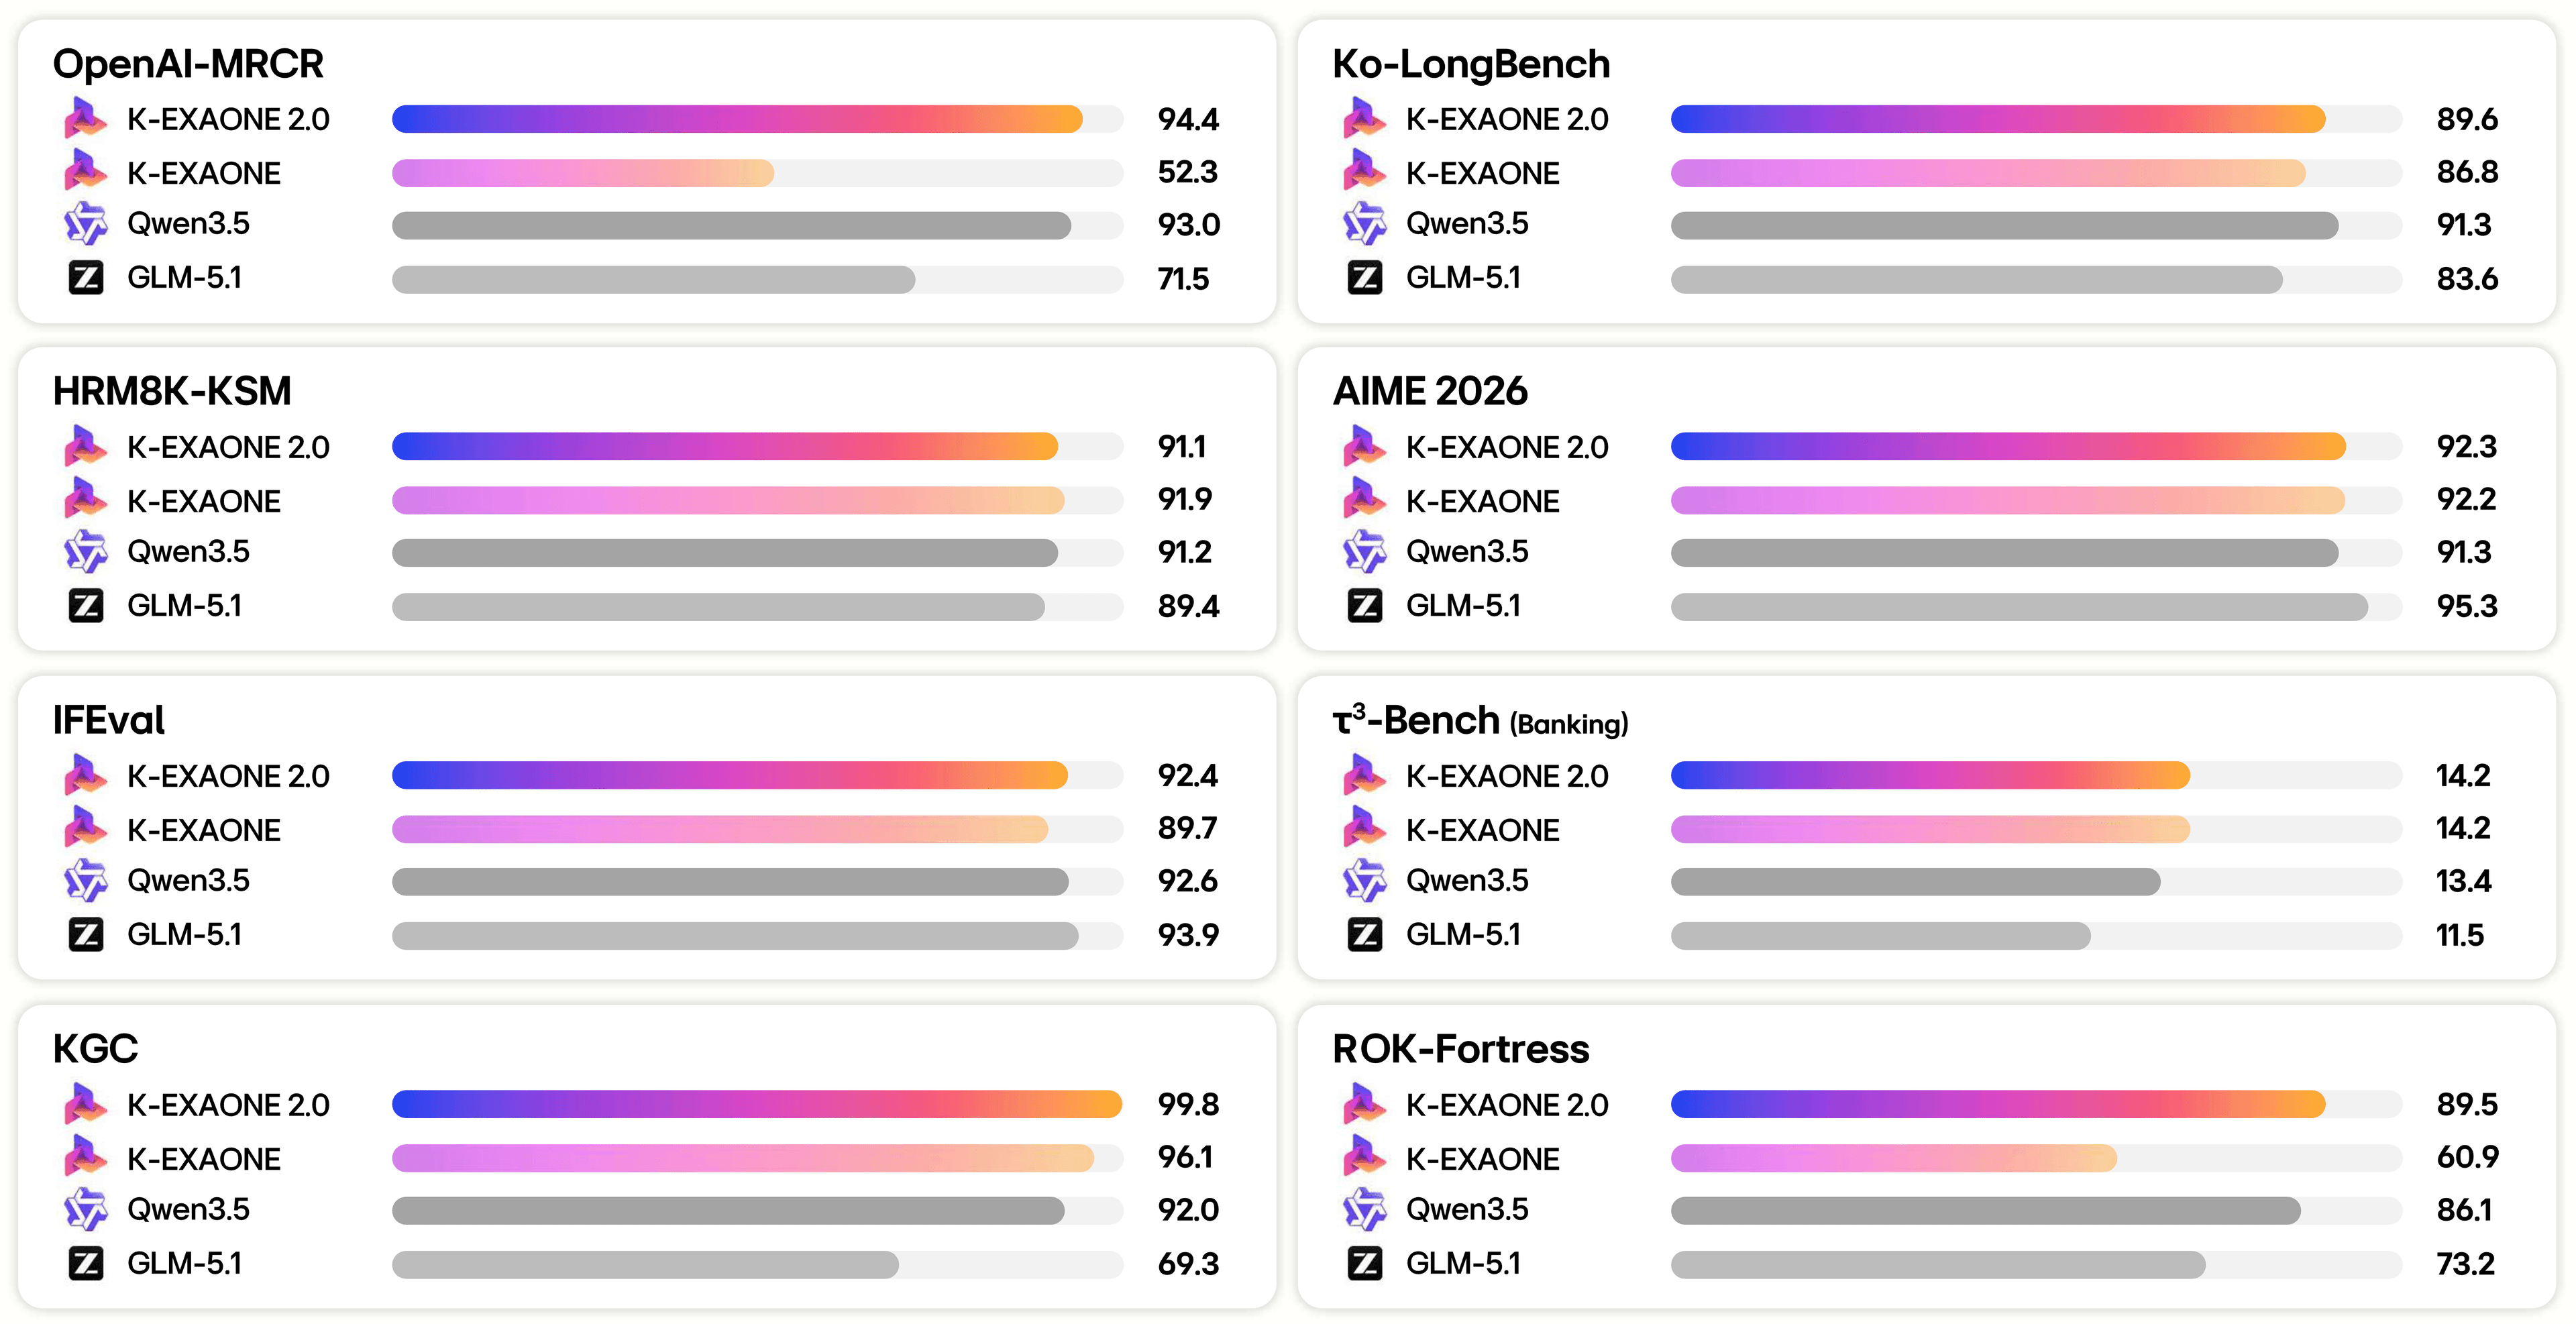
LG AI Research has published K-EXAONE 2.0 750B-A37B, its largest EXAONE model to date, on Hugging Face. The model uses a mixture-of-experts (MoE) design with 750 billion total parameters but activates only 37 billion for any given token, a structure that keeps inference costs closer to a mid-sized dense model while retaining the capacity of a much larger one.
The release is positioned as a text and reasoning model, with support for English, Korean, and Spanish. That trilingual focus is notable: it signals LG's intent to compete beyond its home market in Korea, and to build reasoning capability rather than chase raw generation alone.
Why it matters
MoE architectures have become the preferred path for scaling frontier models without proportionally scaling compute, and a 750B/37B split places K-EXAONE 2.0 among the more ambitious open-weight efforts from an industrial lab outside the US and China.
- Total size: 750B parameters across experts
- Active per token: 37B, keeping serving costs manageable
- Languages: English, Korean, Spanish
- Focus: text generation and reasoning
The model is distributed under a custom license rather than a standard open-source one, so teams evaluating it for production should read the terms on the model card carefully. Details on context length and benchmark performance were not specified in the initial listing.
Sources
- Visit
LGAI-EXAONE/K-EXAONE-2.0-750B-A37B
Hugging Face
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.