Zhipu AI Open-Sources 9B Vision Model with 'Thinking' Mode
The new GLM-4.1V-9B-Thinking model makes its vision and chain-of-thought reasoning capabilities available under a permissive MIT license.
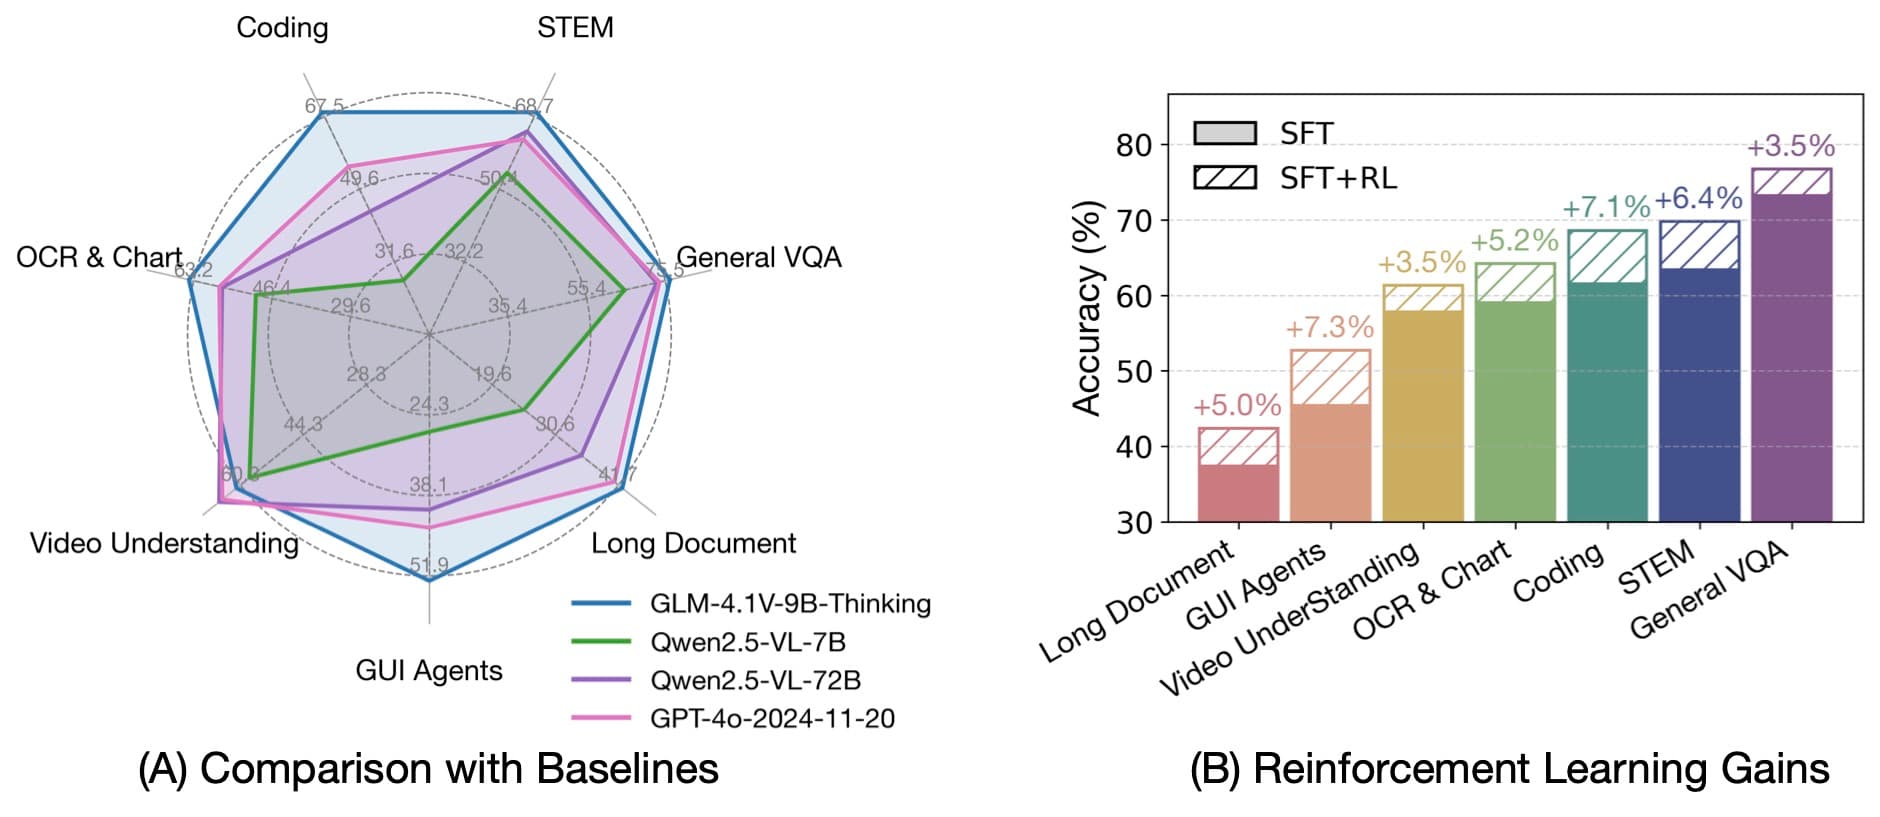
Zhipu AI has released a new open-source vision-language model, GLM-4.1V-9B-Thinking. At 9 billion parameters, the model is designed to interpret and reason about visual inputs, marking another significant entry into the competitive field of multimodal AI.
The model's most distinct feature is its explicit "thinking" mode. This enables a chain-of-thought process, where the model generates intermediate reasoning steps before arriving at a final answer. For developers and researchers, this transparency can make it easier to understand and debug the model's conclusions on complex visual question-answering tasks.
Permissive Licensing for Broader Use
Perhaps most notably for the open-source community, Zhipu AI has released the model under the highly permissive MIT license. This choice removes significant barriers to adoption, allowing for broad use in both commercial applications and academic research. The move encourages wider experimentation and integration compared to models with more restrictive licenses.
The complete model weights and details are available for download on Hugging Face. This release provides developers with a powerful and transparent tool for building applications that require a sophisticated understanding of both language and imagery.
Sources
- Visit
zai-org/GLM-4.1V-9B-Thinking
Hugging Face
More from Zhipu AI
All Zhipu AI releases →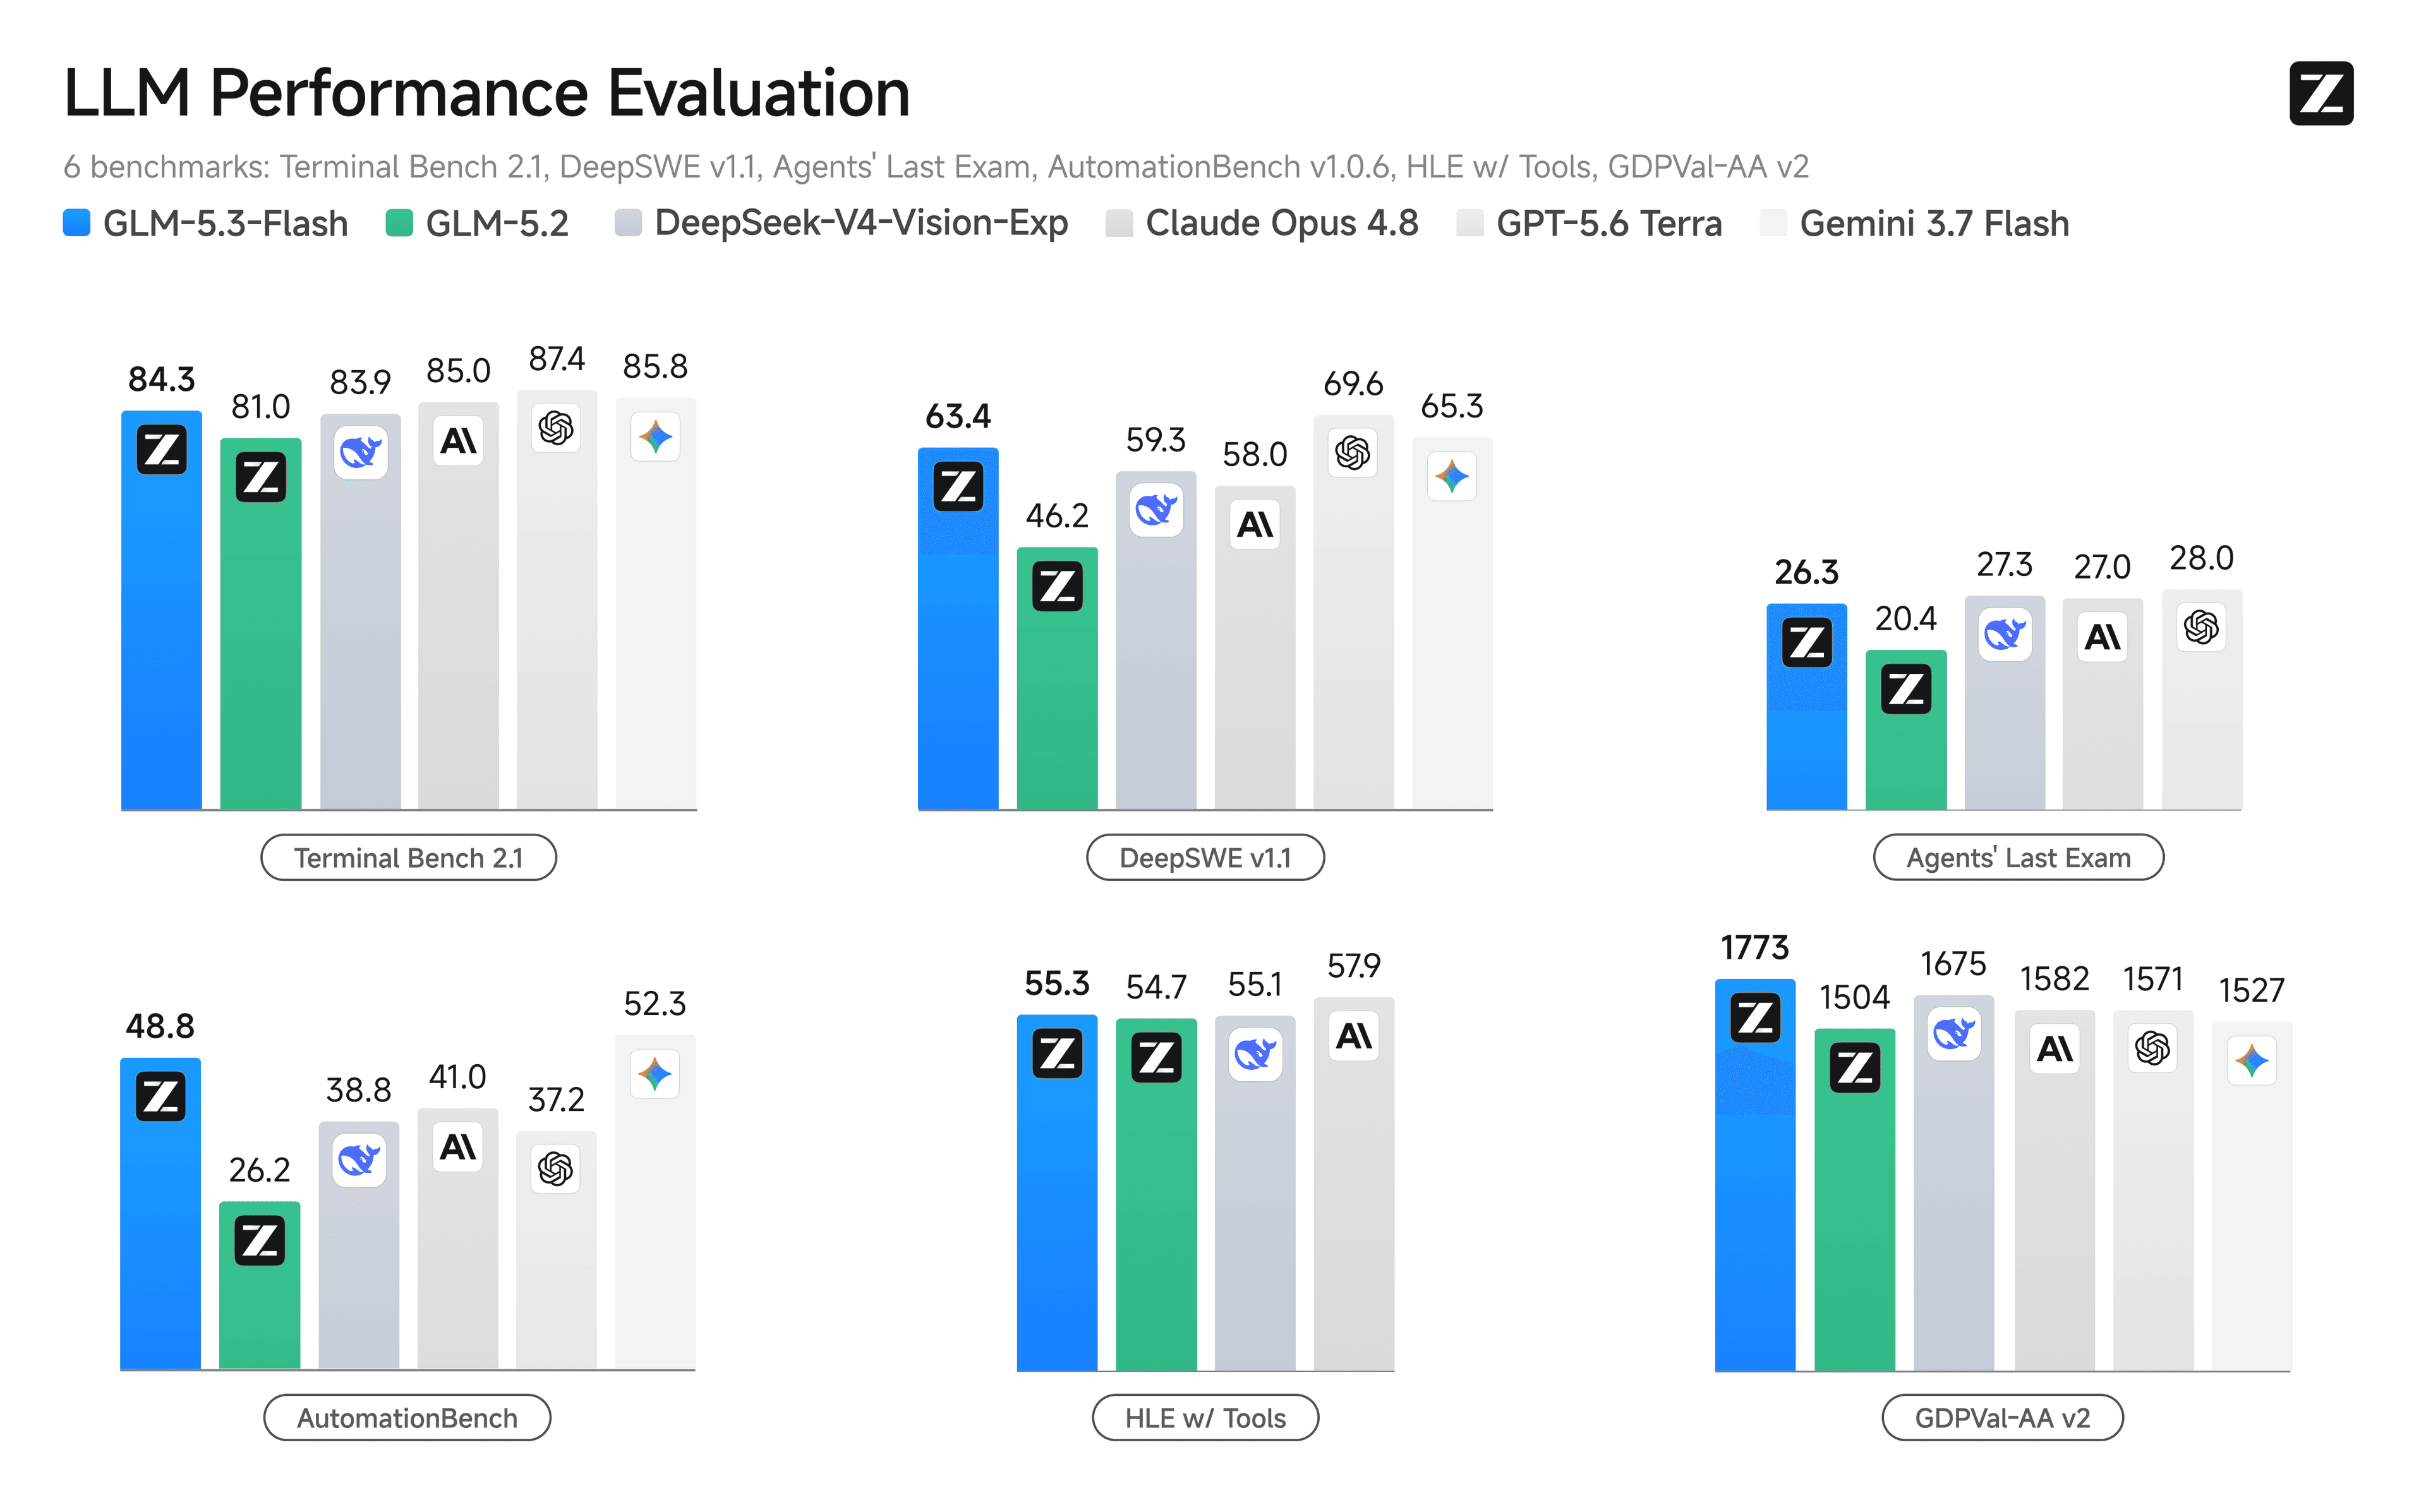
Zhipu releases GLM-5.3-Flash under MIT license
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
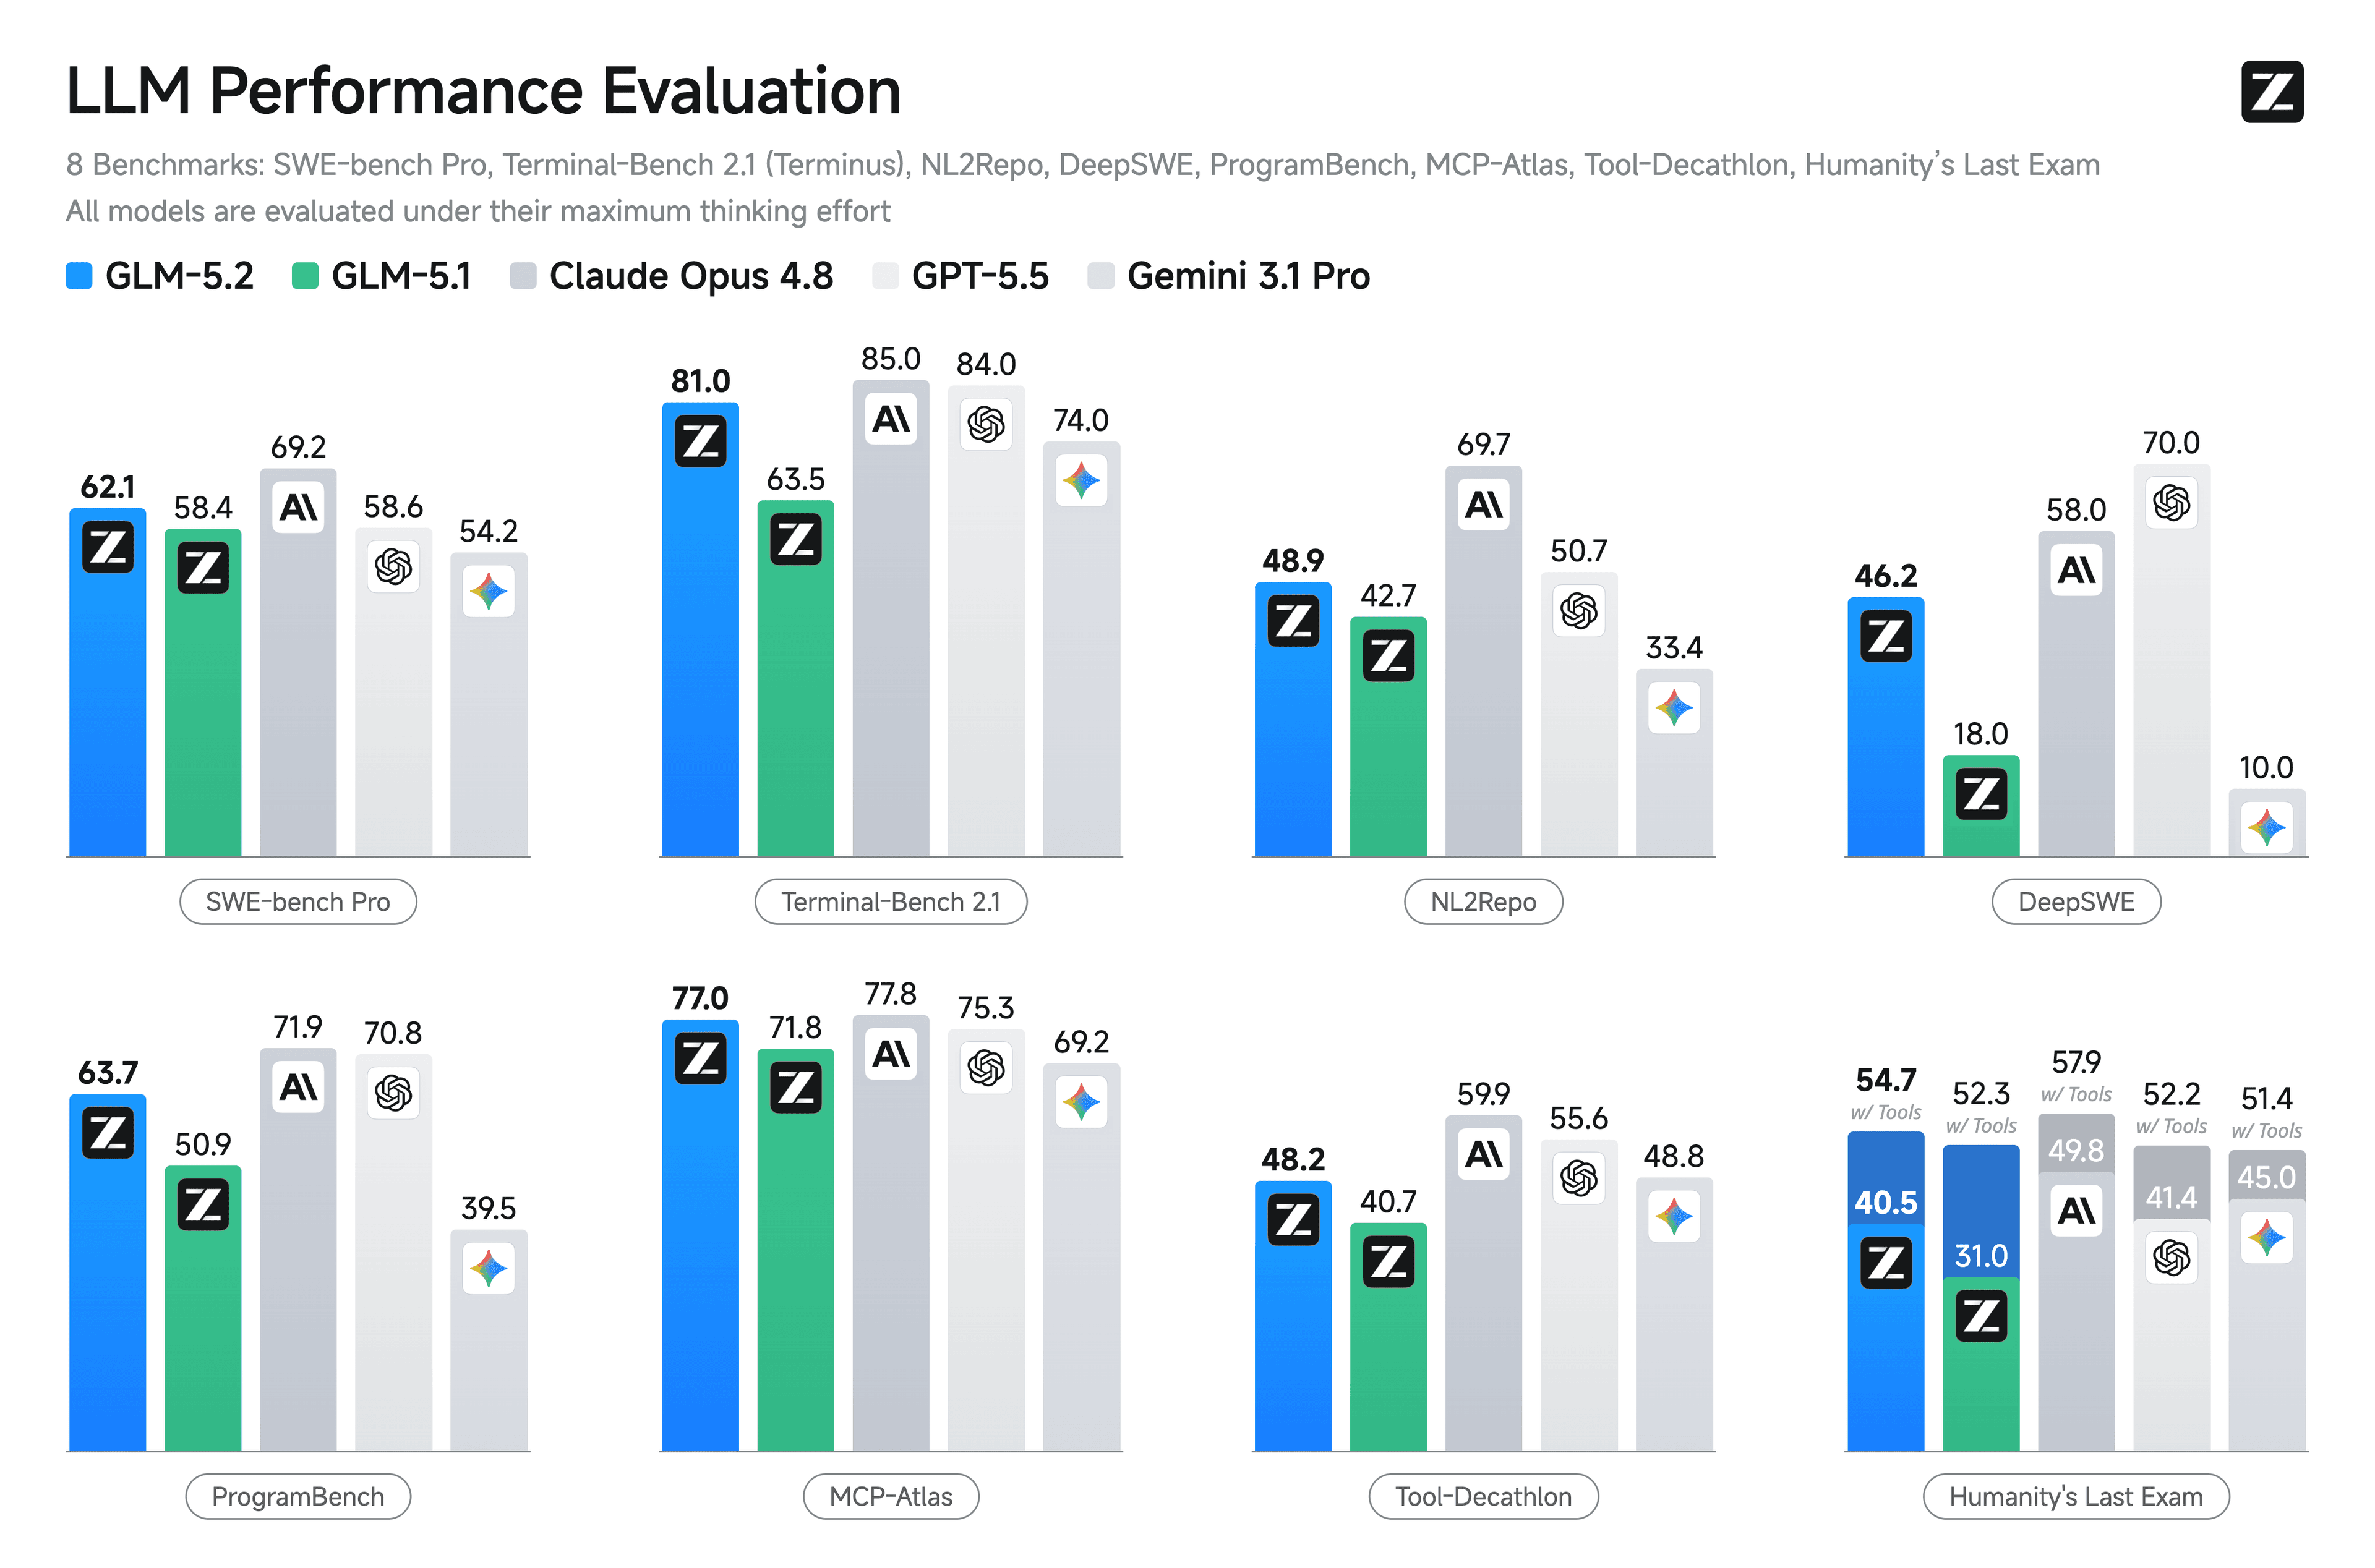
Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.