NeoHorse-1-9B targets agentic coding tasks
A 9-billion-parameter model built on Qwen3.5 aims squarely at tool use and code generation.
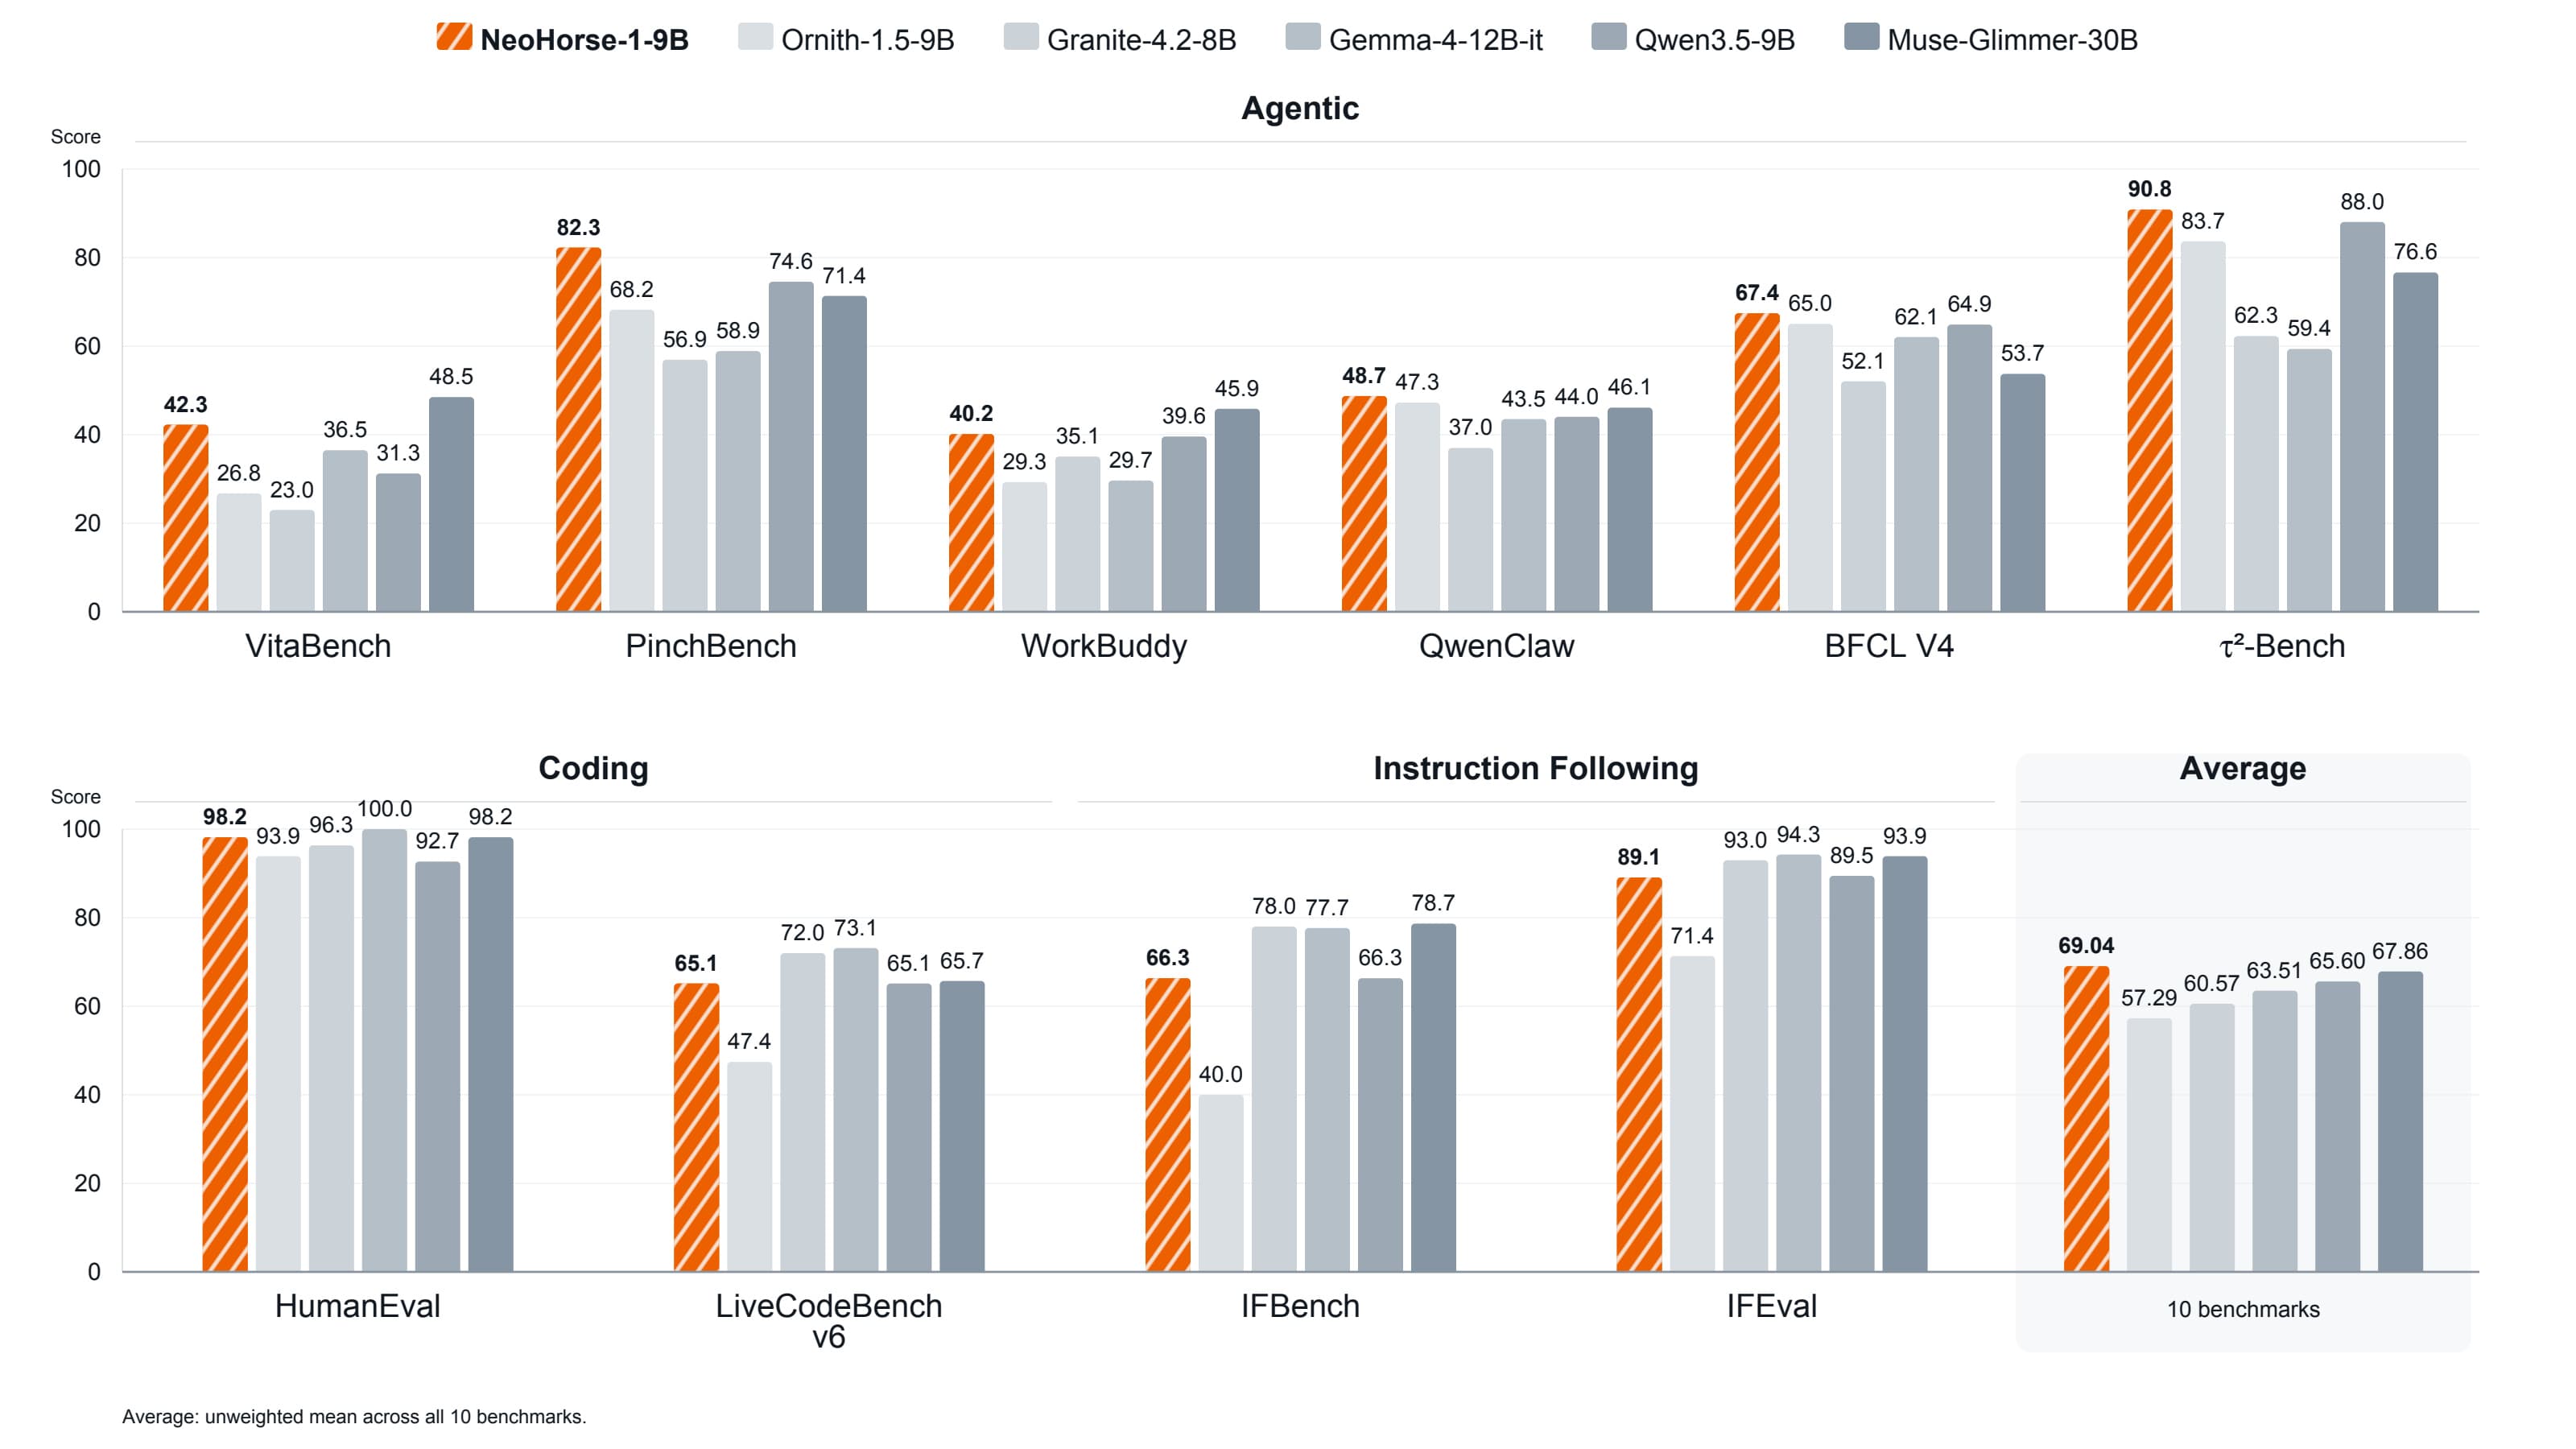
inclusionAI has released NeoHorse-1-9B, a dense 9-billion-parameter language model aimed at agentic tool use and coding. Published on Hugging Face under the TokenRhythm namespace, the model is described as being built on the Qwen3.5 foundation and tuned for the kinds of multi-step, tool-calling workflows that increasingly define practical developer tooling. You can find it at its Hugging Face page.
The 9B size puts NeoHorse-1 in a familiar sweet spot for teams that want a capable model they can run without the infrastructure demands of larger systems. Rather than chasing raw scale, this release leans into a specialization: agentic behavior and code, the two areas where smaller models have shown the most consistent gains over the past year.
Why it matters
Agentic coding assistants live or die by reliability, not just fluency. A model that reasons through a task and calls the right tools in the right order can outperform a much larger general-purpose model on real work. Positioning a 9B model specifically for this niche is a bet that focused tuning beats size for these jobs.
- Dense 9B model (not a mixture-of-experts design)
- Built on the Qwen3.5 base
- Focused on tool use, reasoning, and code
- Released under a custom ("other") license
A few practical details remain unspecified in the release record, including context length and formal license terms, so teams evaluating NeoHorse-1-9B for production should confirm those directly on the model card before committing.
Sources
- Visit
TokenRhythm/NeoHorse-1-9B
Hugging Face
More from TokenRhythm
All TokenRhythm releases →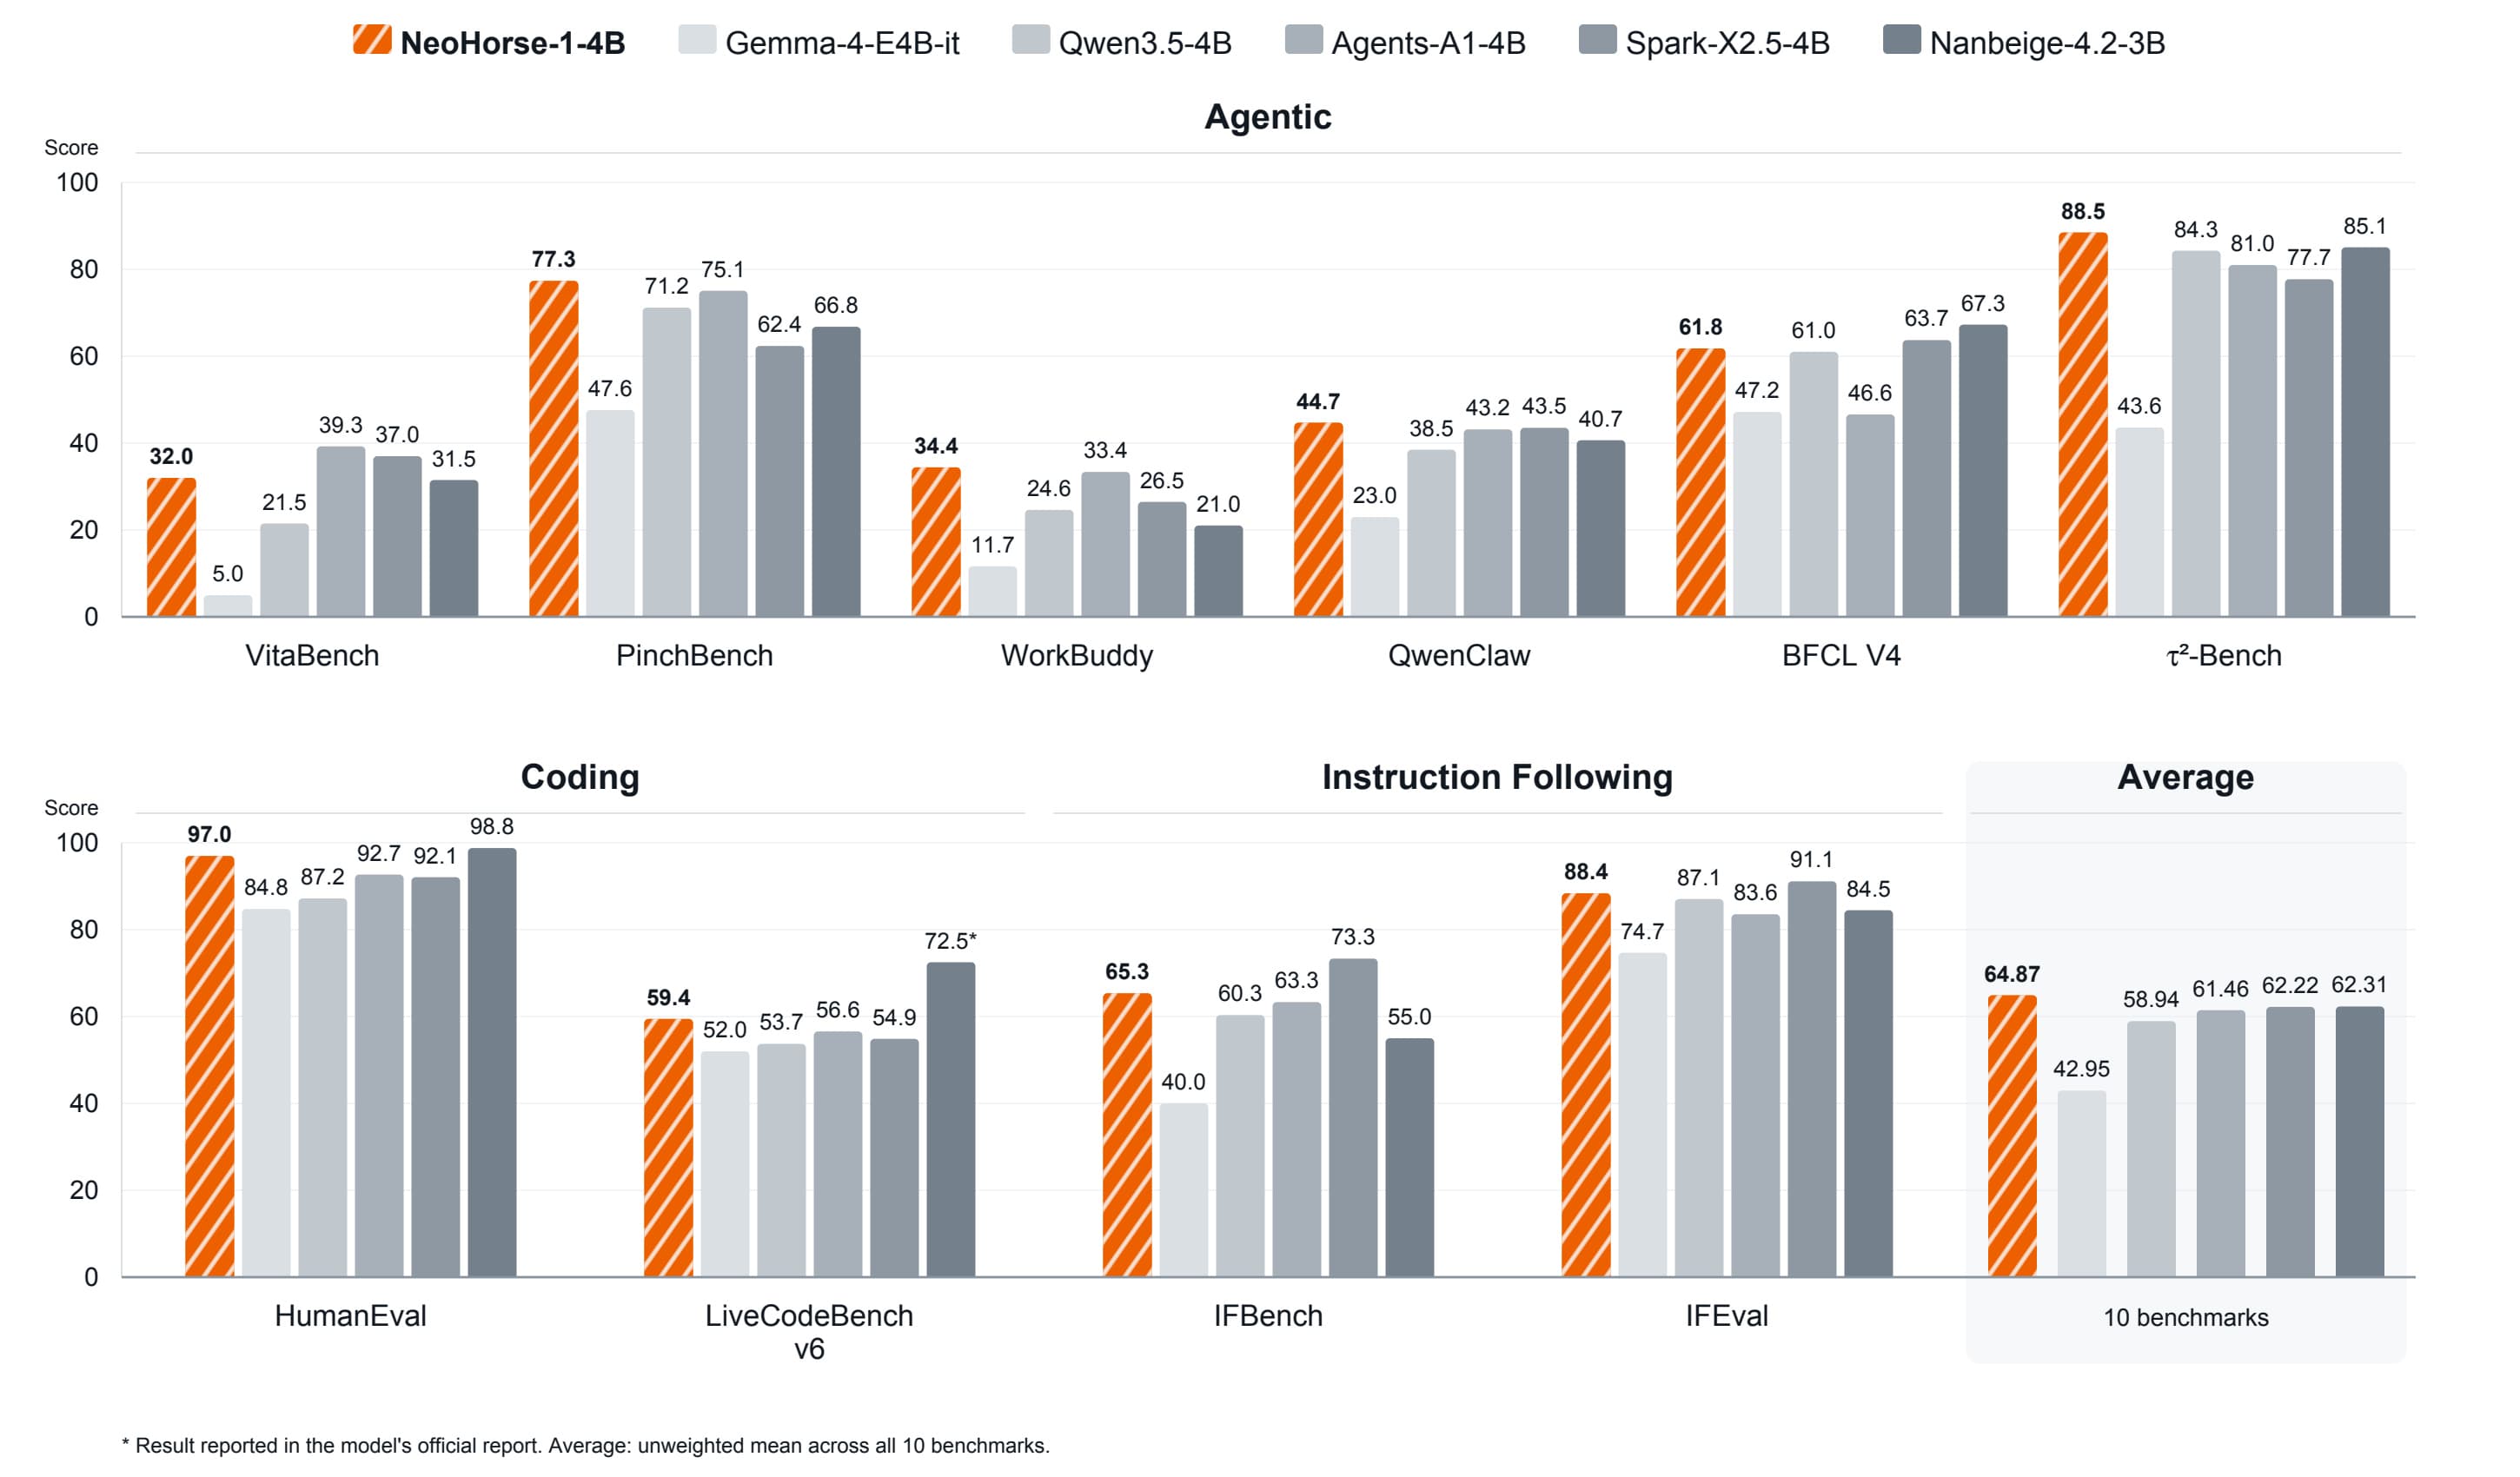
NeoHorse-1-4B tunes Qwen3.5 for agentic work
A compact 4-billion-parameter model built for tool use, coding, and multi-step reasoning arrives from TokenRhythm.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.