Zhipu AI Releases Open-Source GLM-5 MoE Model
The new Mixture-of-Experts model from the Chinese AI company combines an advanced architecture with a fully permissive MIT license for commercial use.
Chinese AI research firm Zhipu AI has released GLM-5, a significant new open-source language model. This release marks a major addition to the open-source ecosystem, offering a sophisticated new architecture from a prominent AI company.
Efficient by Design
GLM-5 is built on a Mixture-of-Experts (MoE) architecture, a technique that improves computational efficiency by activating only specialized parts of the network for any given task. The model also incorporates sparse attention, further optimizing its performance and resource usage. This combination is designed to deliver powerful reasoning capabilities while maintaining manageable inference costs.
Perhaps most notably, Zhipu AI has released GLM-5 under the permissive MIT license, which allows for broad and unrestricted commercial application. The choice of such an open license for an advanced model encourages wide adoption and makes it a valuable asset for developers and businesses building with AI.
The release of GLM-5 provides a new, highly capable foundation for the open-source community, blending an efficient, modern architecture with the freedom to innovate and build commercial products.
Sources
- Visit
zai-org/GLM-5
Hugging Face
More from Zhipu AI
All Zhipu AI releases →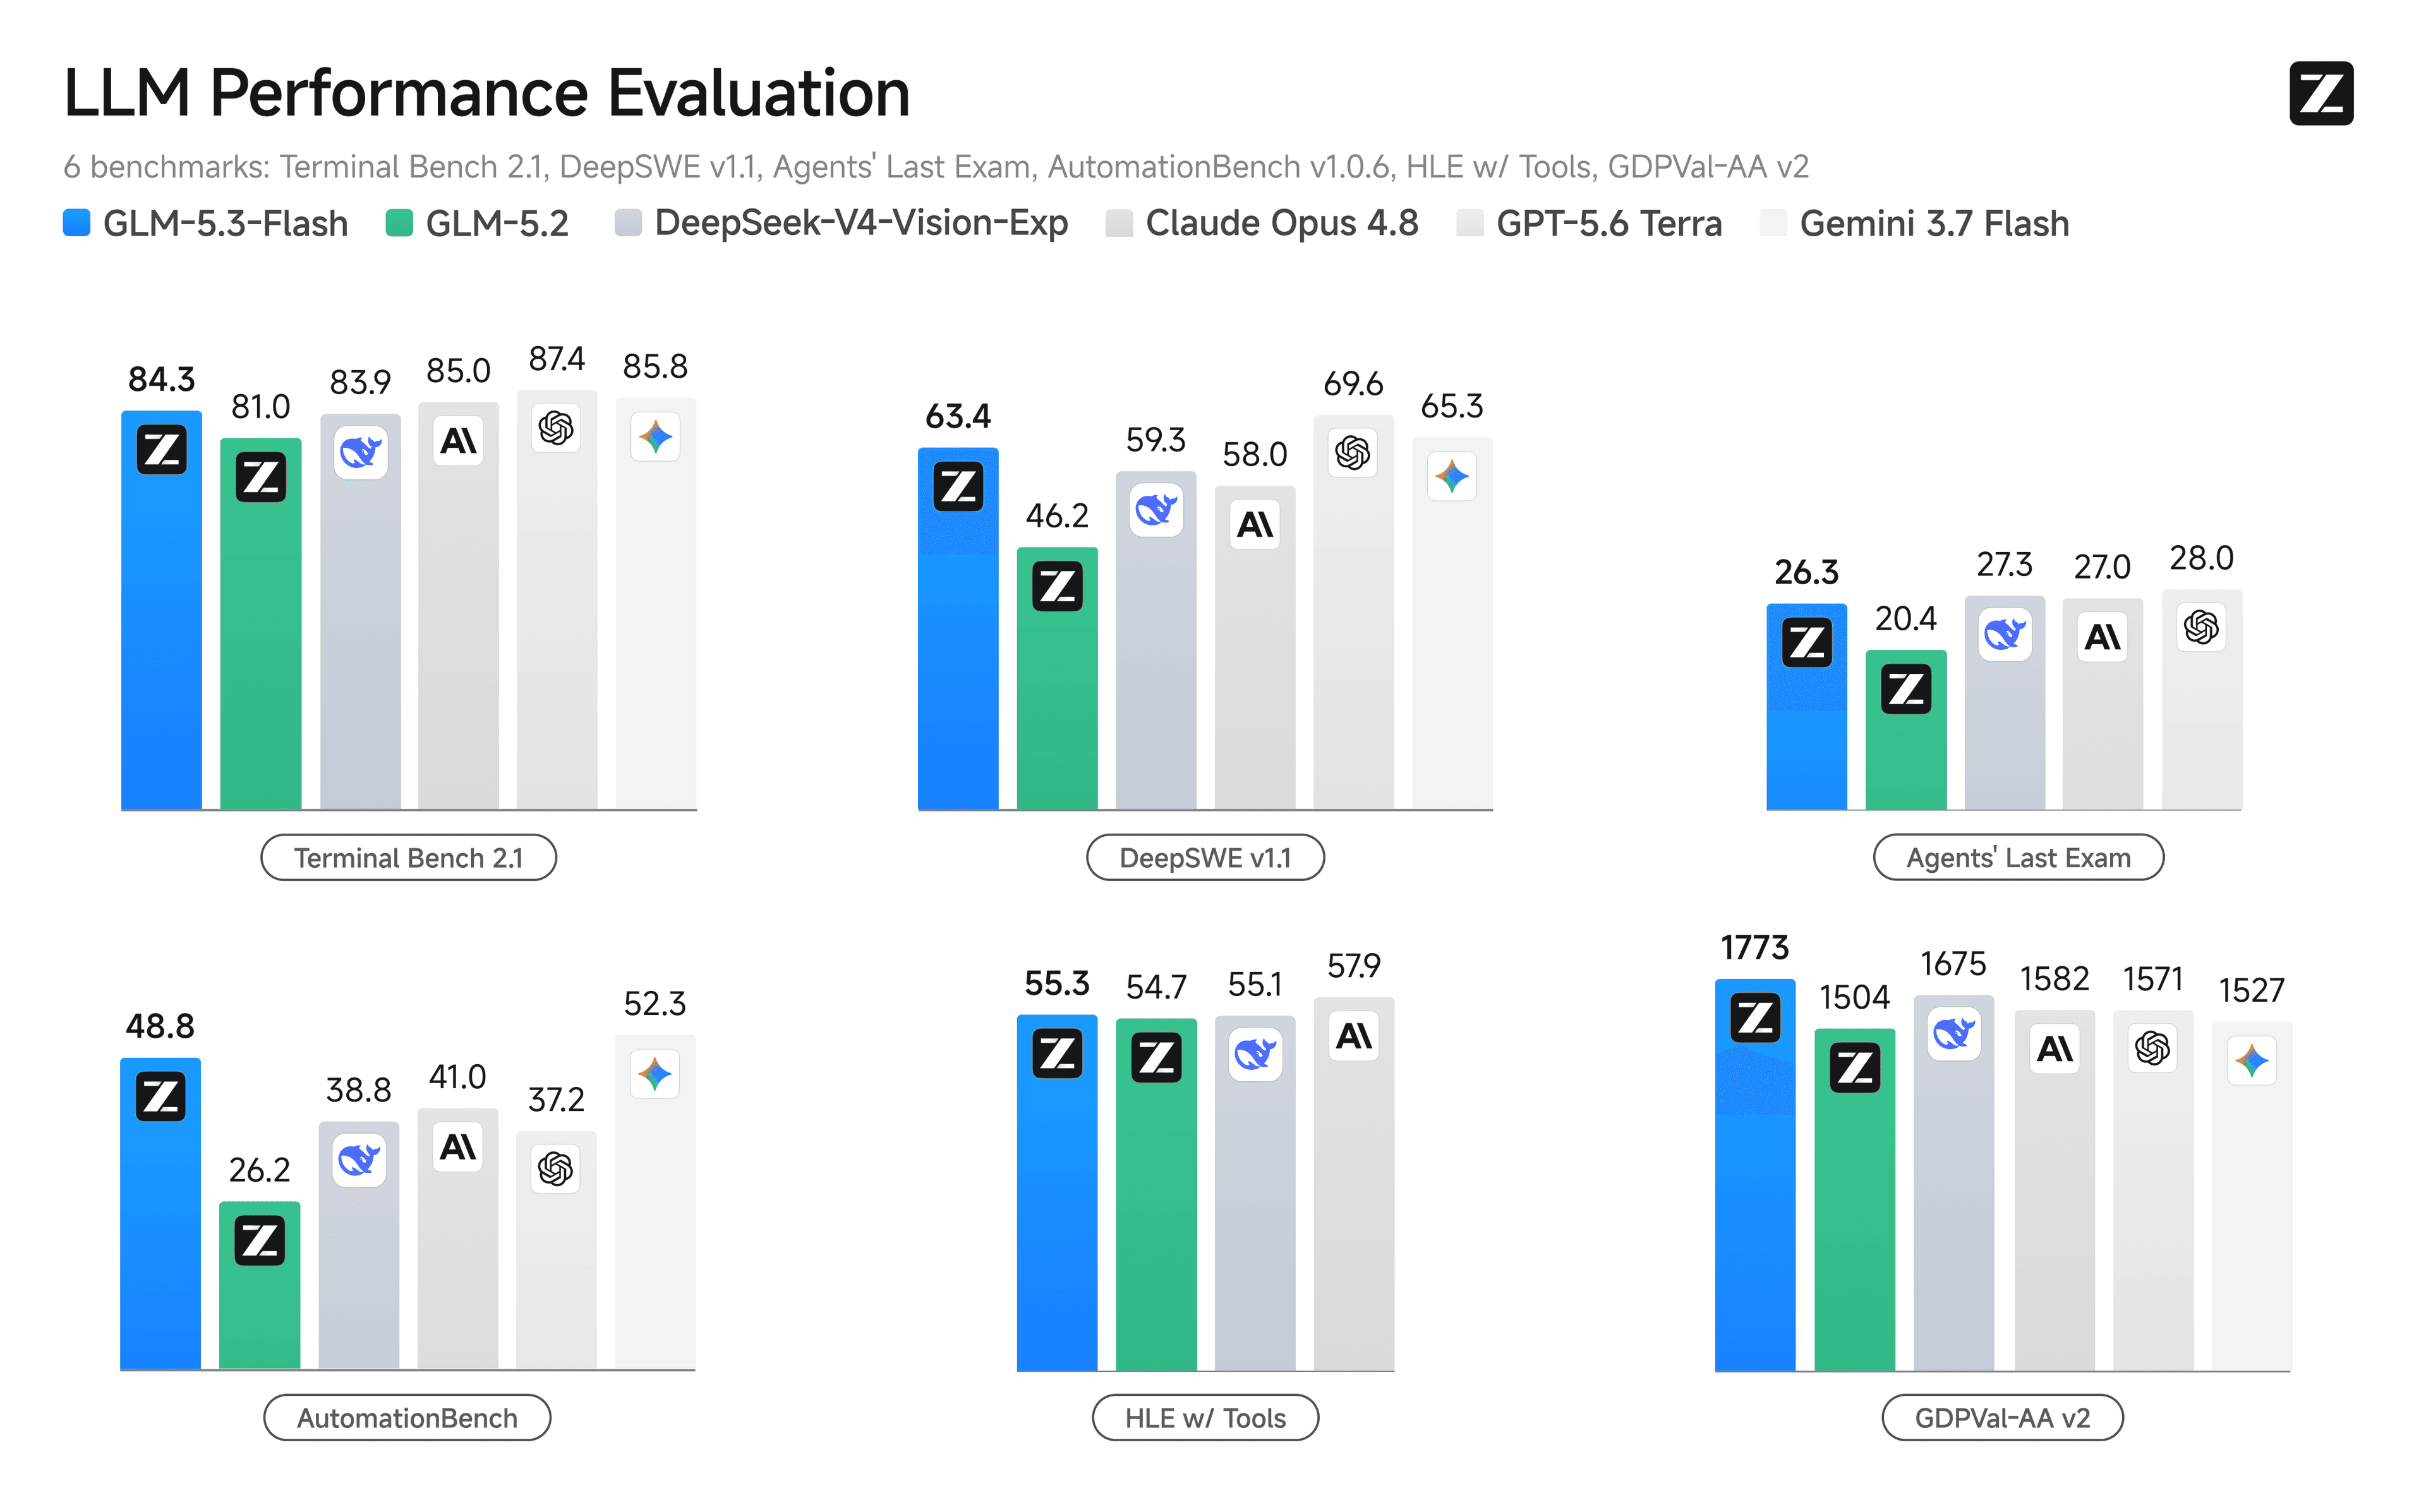
Zhipu releases GLM-5.3-Flash under MIT license
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
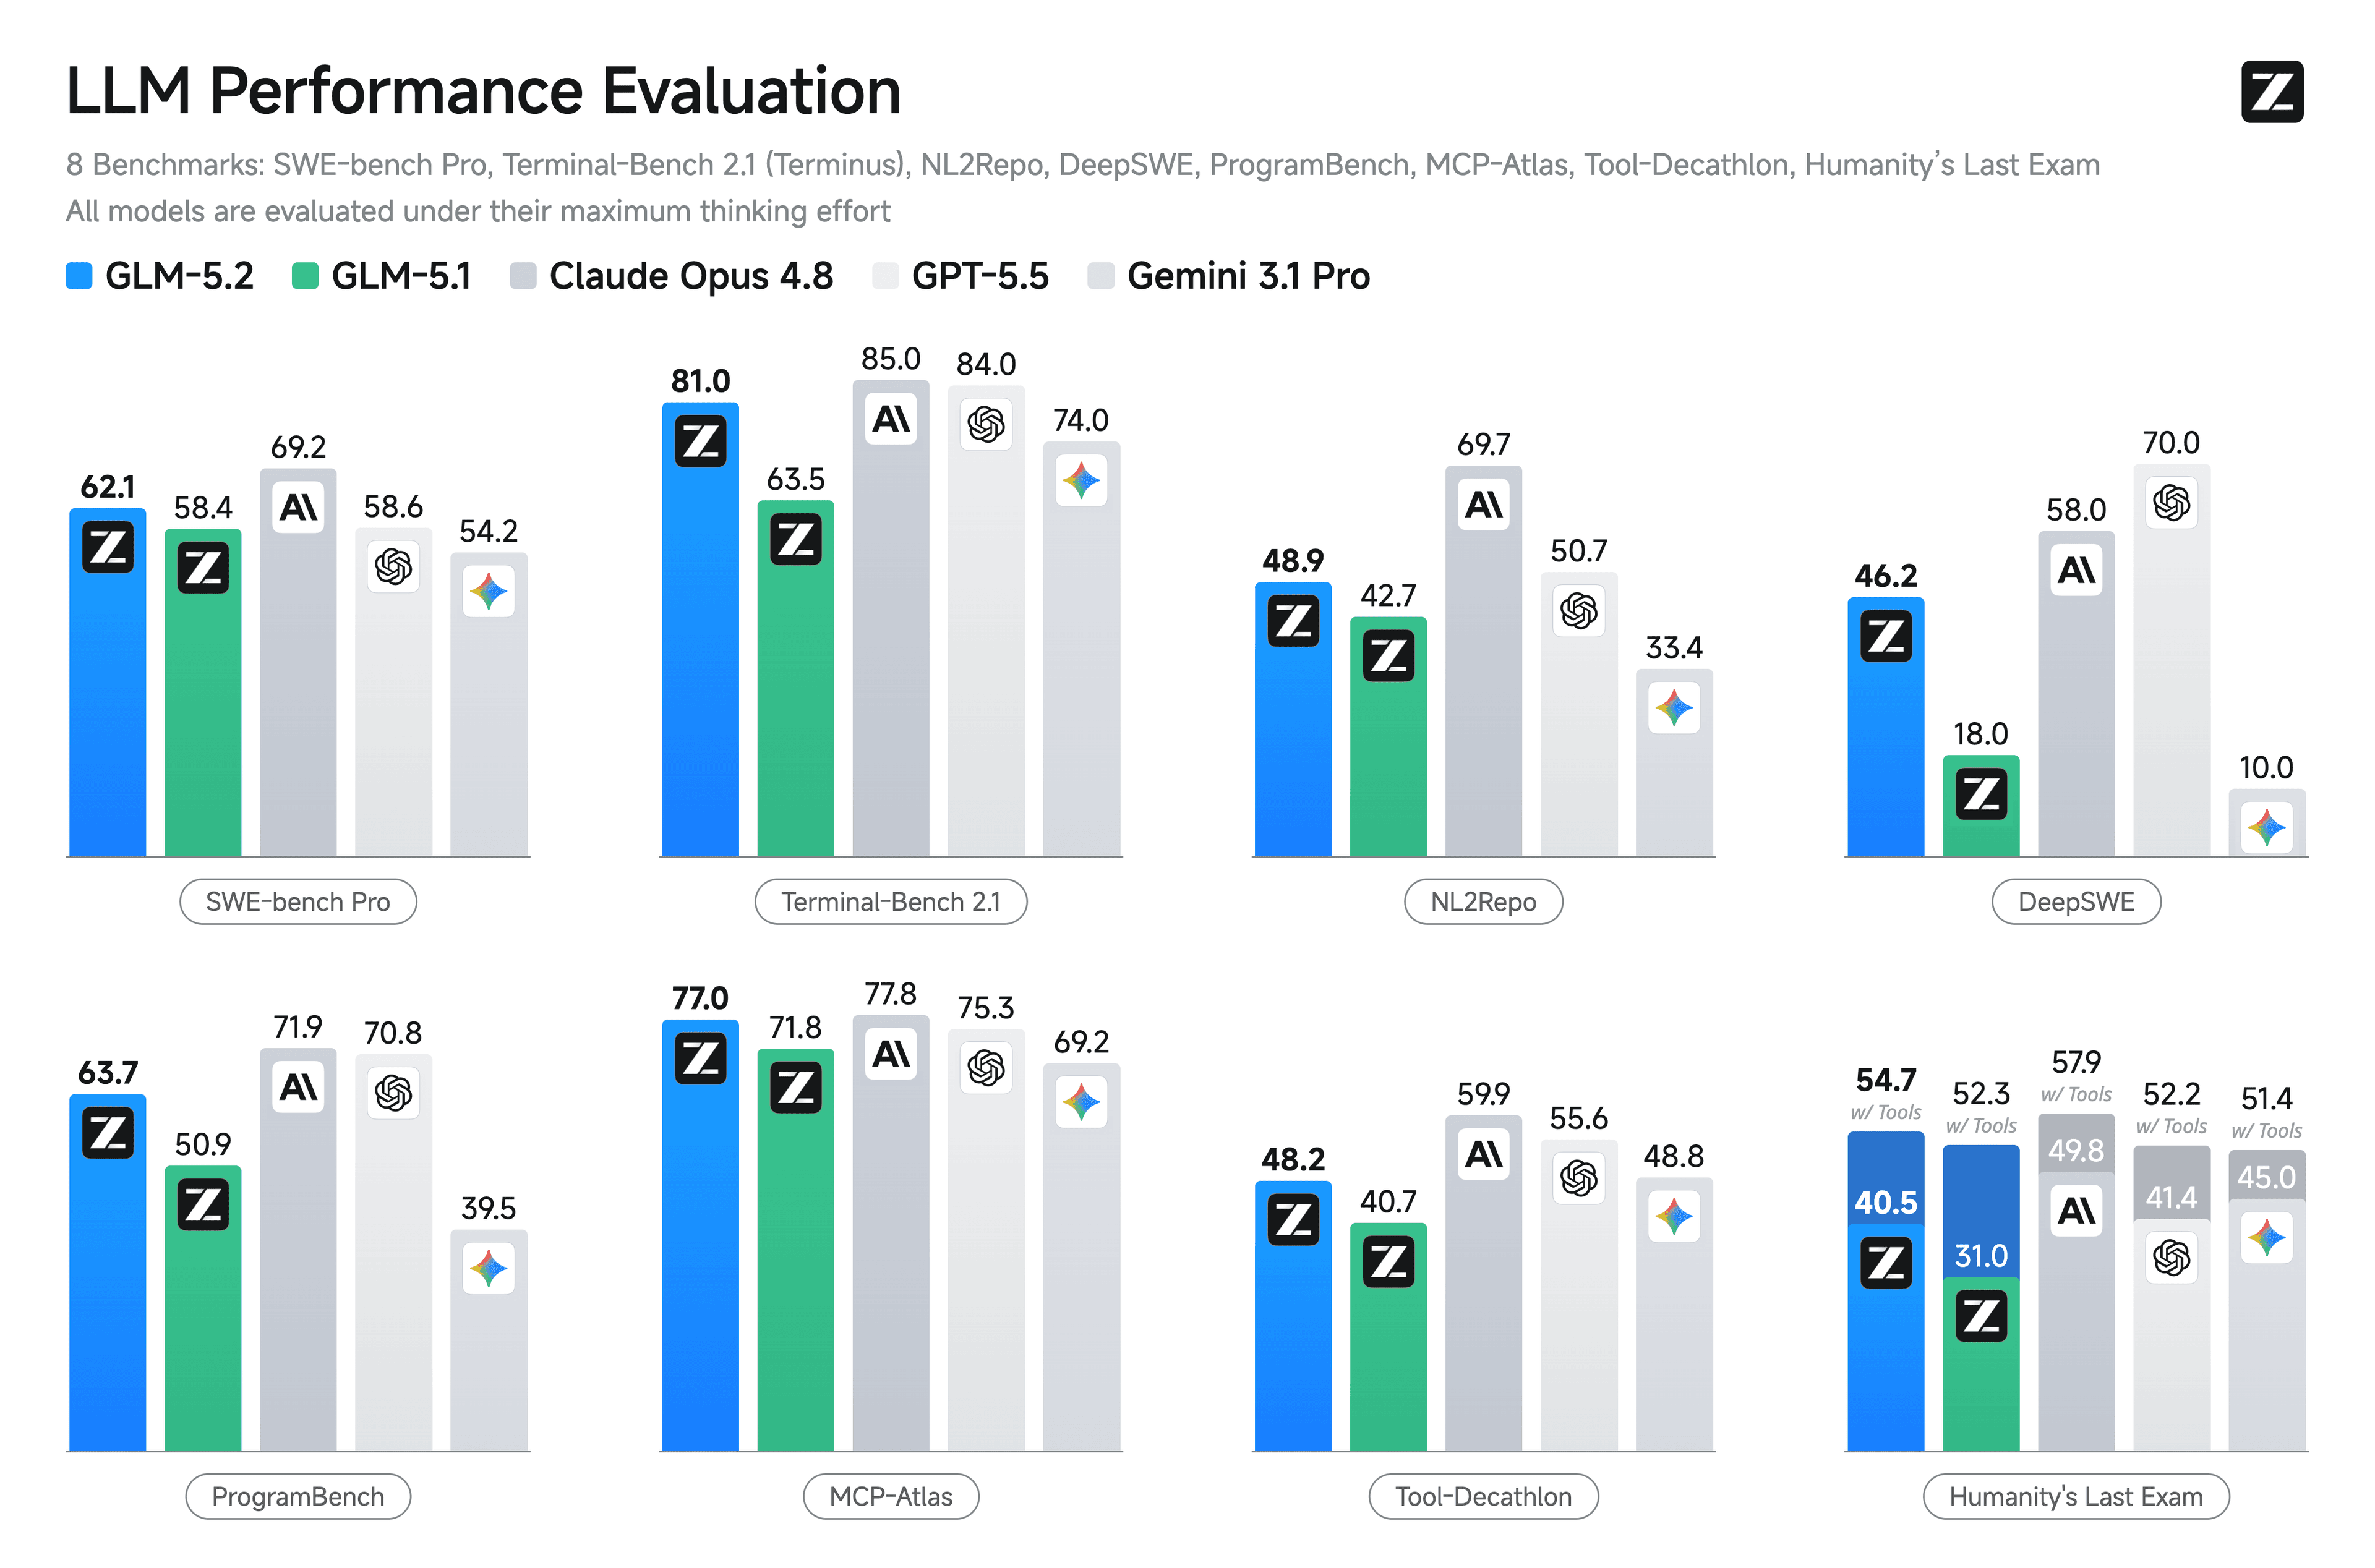
Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.