Baidu Releases Open Vision-Language MoE Model
The new ERNIE 4.5 VL model brings advanced multimodal reasoning to the open-source community with an efficient Mixture-of-Experts architecture.
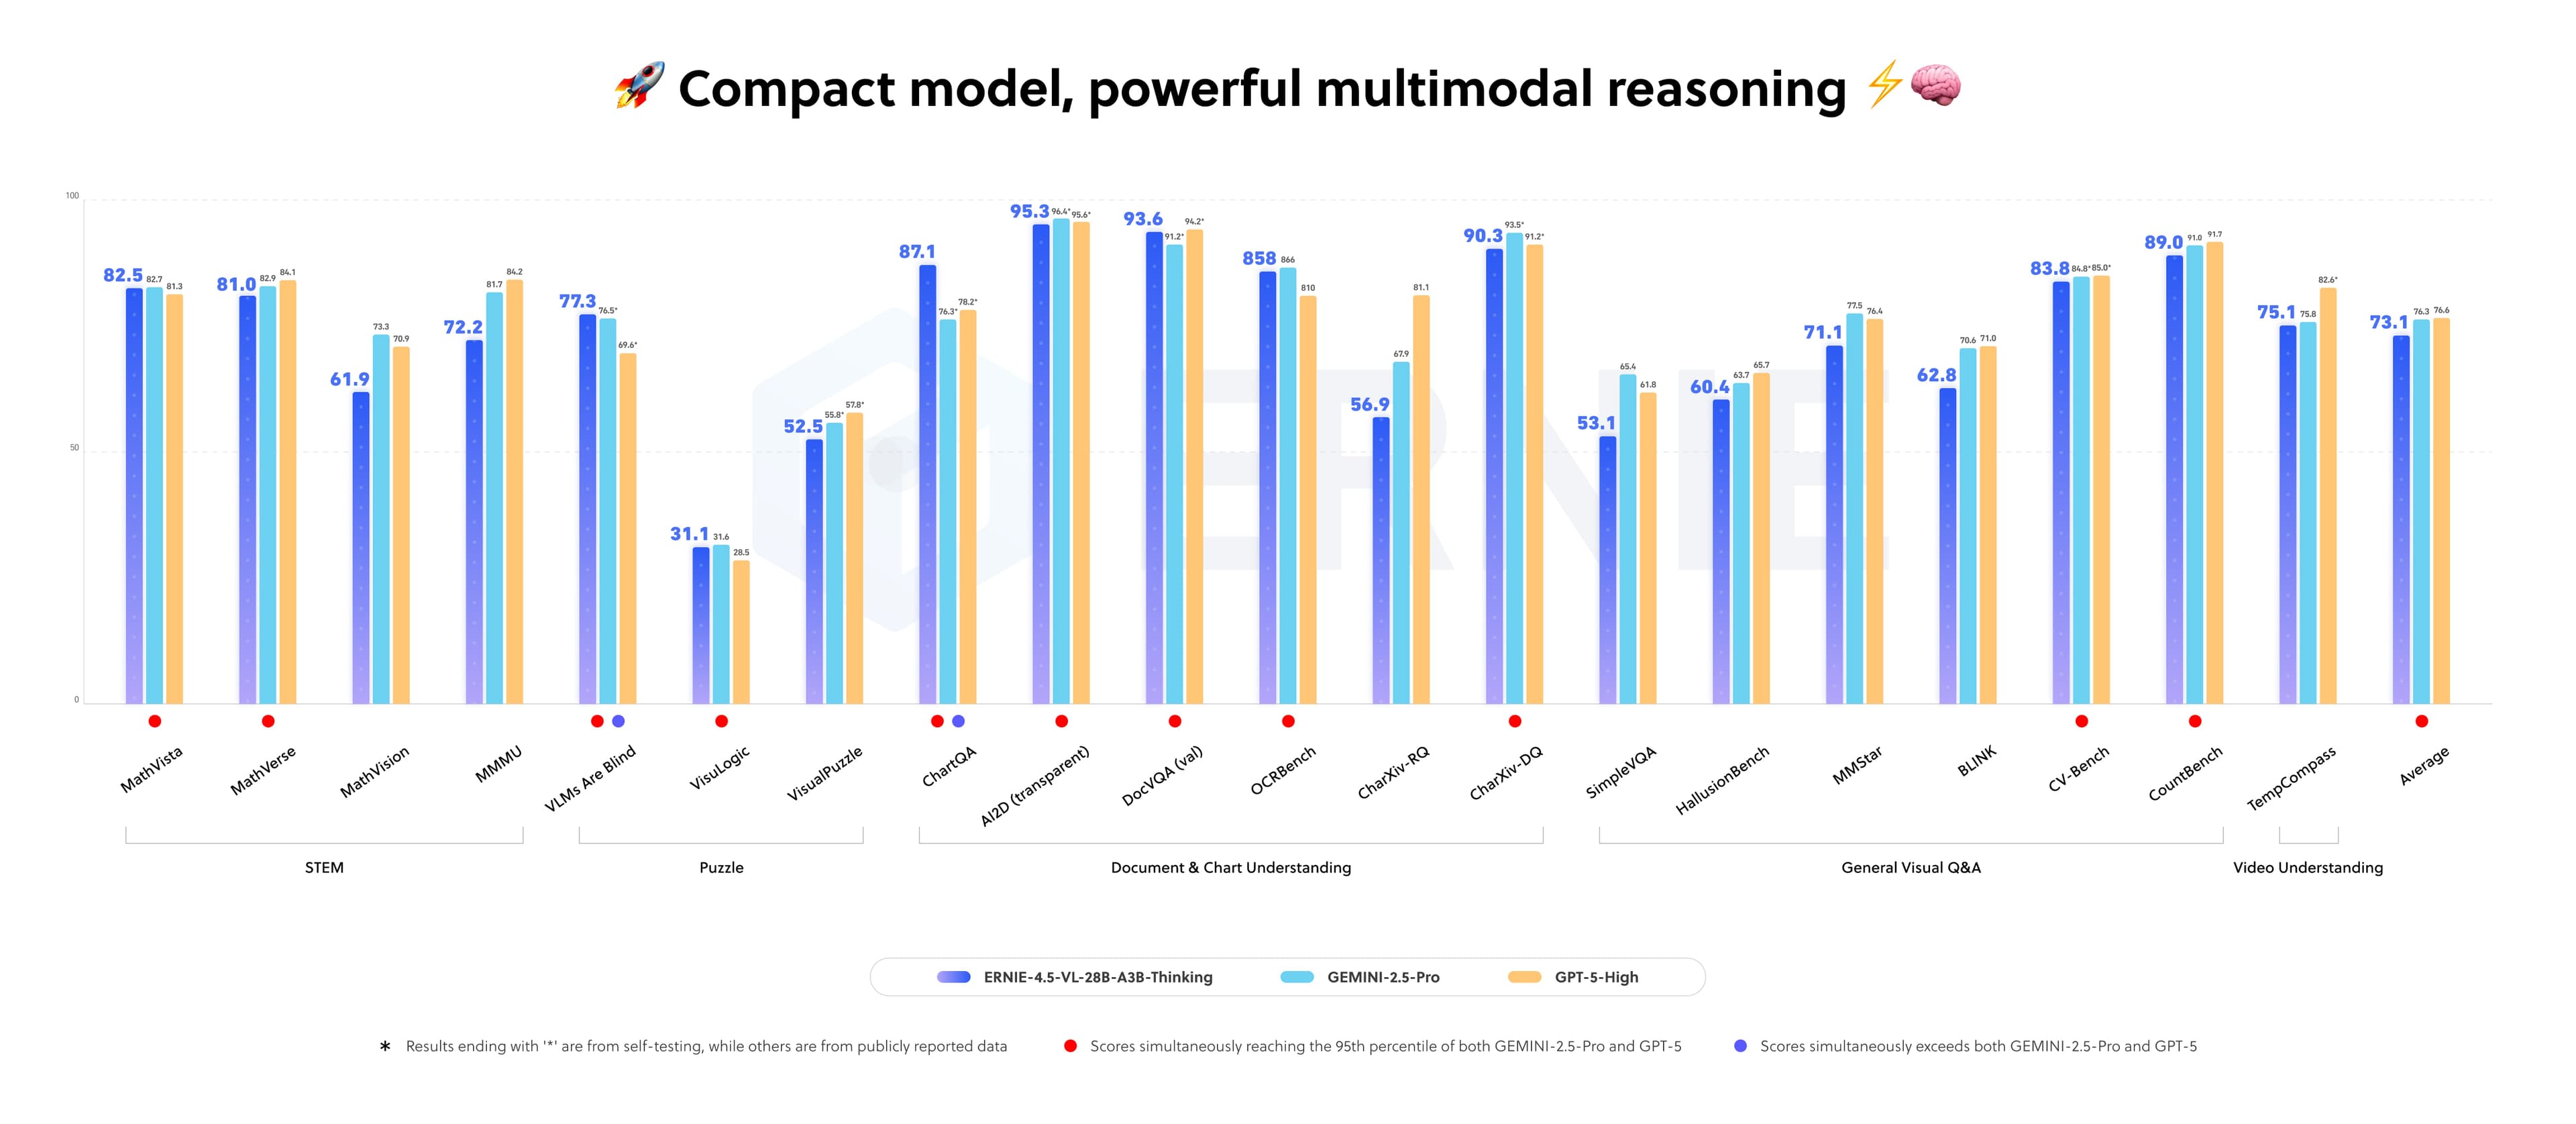
Chinese tech giant Baidu has released ERNIE 4.5 VL, a powerful new vision-language model available under a permissive open-source license. The model is designed for complex reasoning tasks that require understanding both images and text, positioning it as a capable new entry in the open multimodal space.
Efficient by Design
At its core, ERNIE 4.5 VL is a sparse Mixture-of-Experts (MoE) model. While it contains a total of 28 billion parameters, it only activates a fraction—around 3 billion—for any given inference task. This design, hinted at by the 'A3B' (Active 3 Billion) in its name, aims to provide the power of a much larger model while maintaining greater computational efficiency during use.
The model's full name, ERNIE 4.5 VL 28B A3B Thinking, emphasizes its focus on multi-step reasoning. It's built to analyze visual information and perform logical thinking, a challenging frontier for AI development.
By releasing this model under the Apache 2.0 license, Baidu is making a notable contribution to the open-source ecosystem. This gives researchers and developers a sophisticated, efficient, and freely usable foundation for building the next generation of multimodal applications.
Sources
- Visit
baidu/ERNIE-4.5-VL-28B-A3B-Thinking
Hugging Face
More from Baidu
All Baidu releases →
Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
Baidu's PP-OCRv6 packs 50-language OCR into tiny models
The latest release of PaddlePaddle's optical character recognition suite spans models from 1.5M to 34.5M parameters under an Apache 2.0 license.
Baidu releases Unlimited-OCR under permissive MIT license
The Chinese tech giant's multilingual vision-language model targets text extraction across languages and document types.
More in Vision-Language
All Vision-Language →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.