Mistral's Leanstral 1.5 puts 119B in a lean MoE
The new Apache-2.0 mixture-of-experts model activates just 6B parameters per token, trading raw density for cheaper inference.
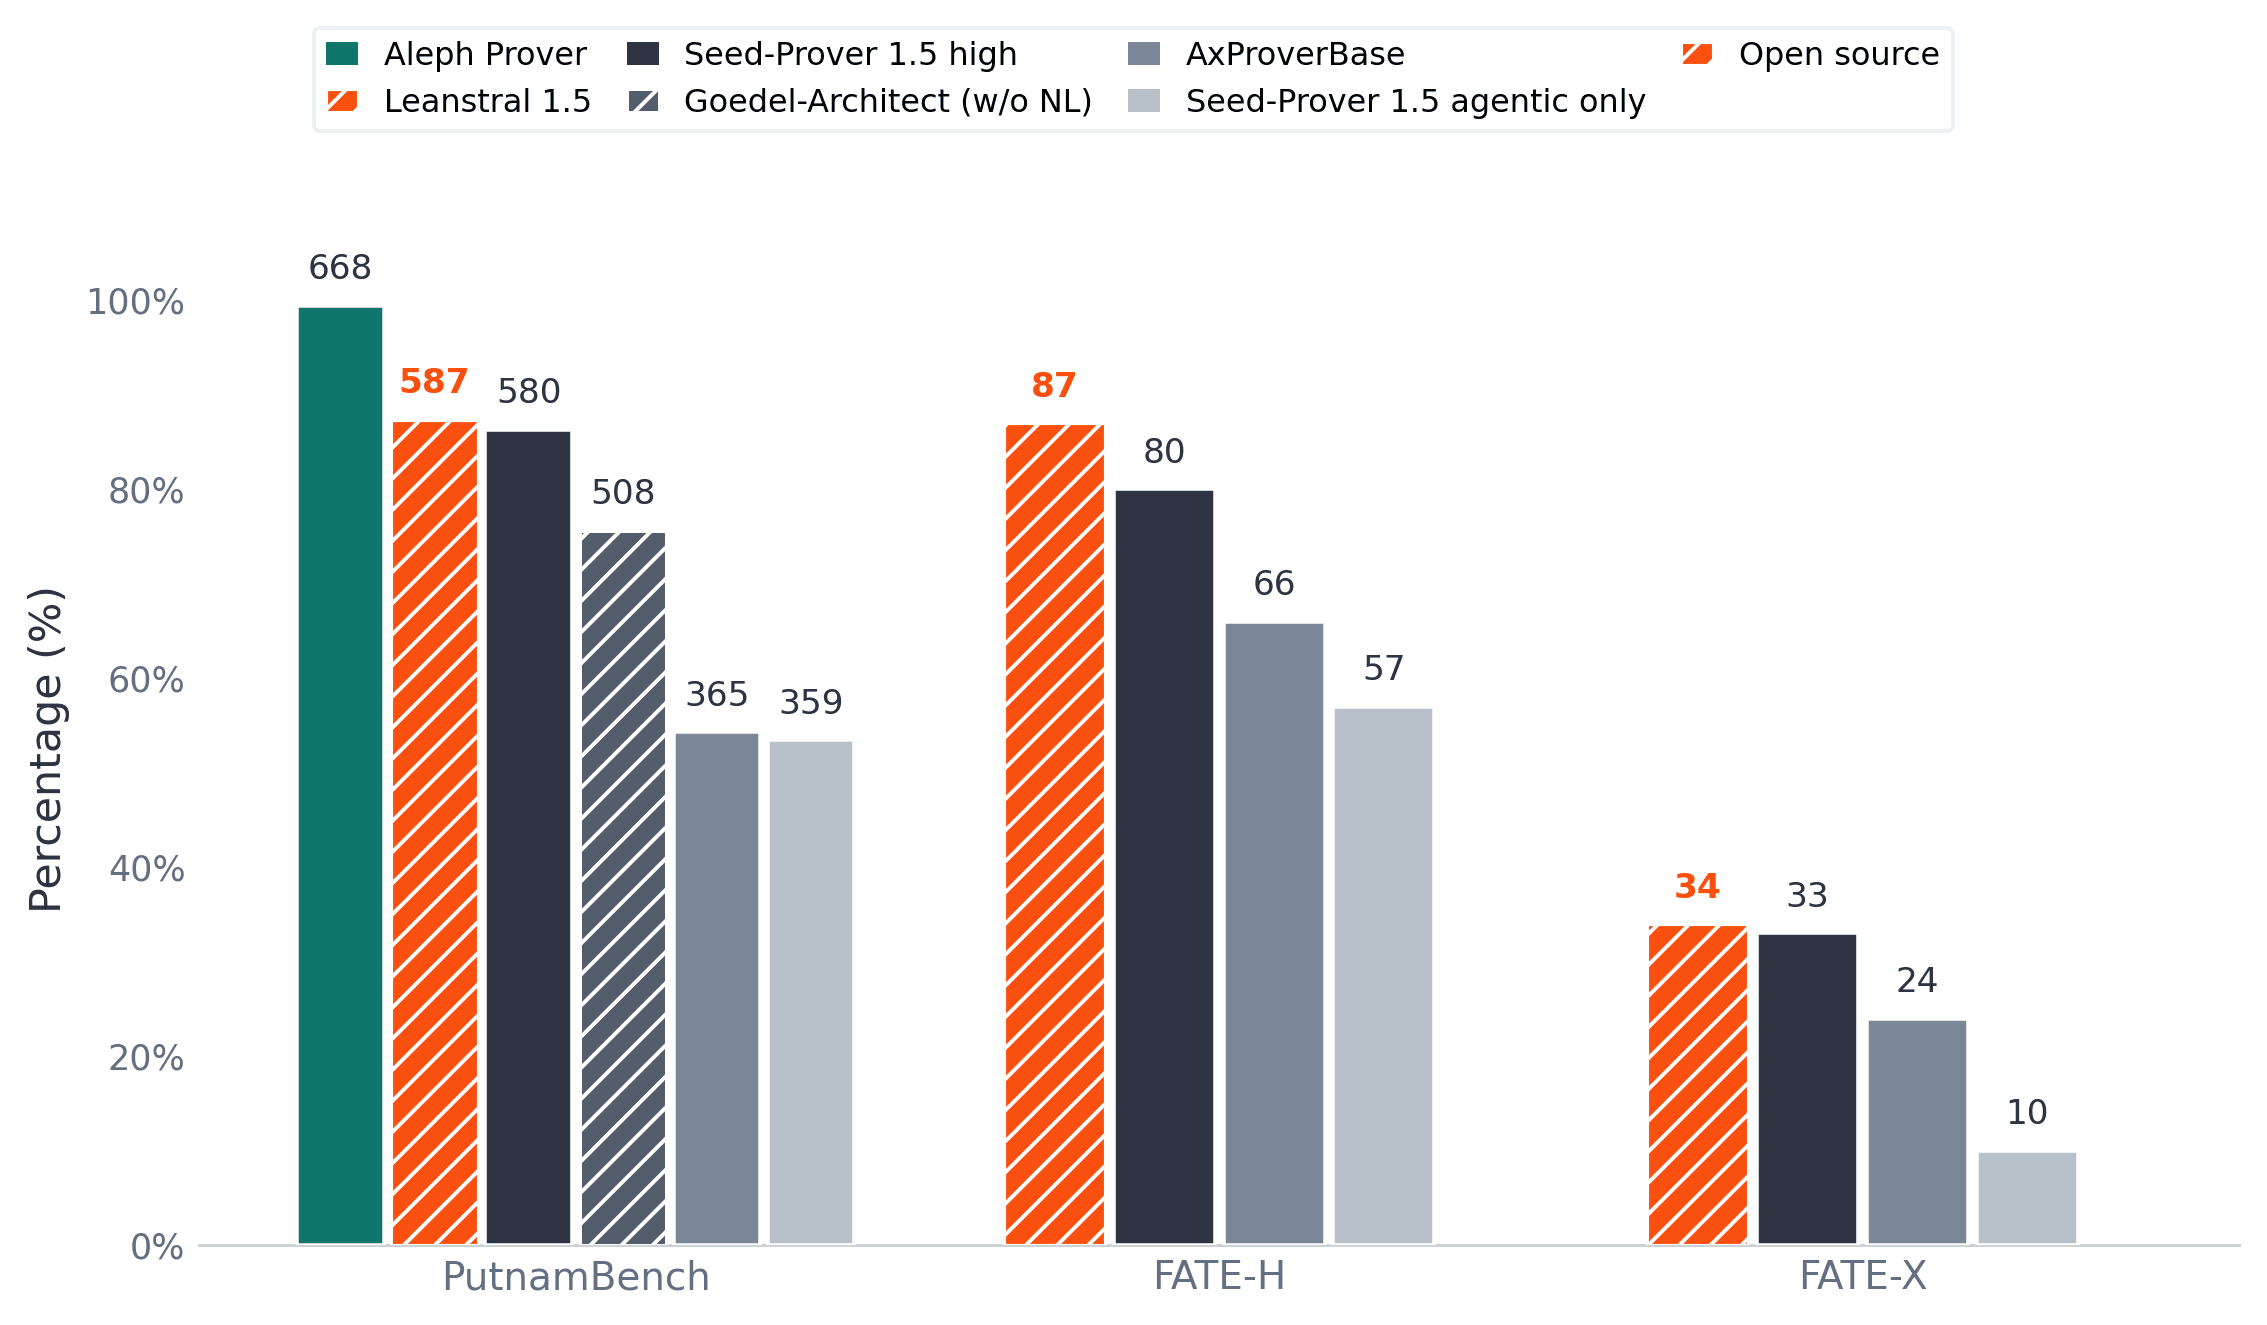
Mistral AI has published Leanstral 1.5, a mixture-of-experts language model with 119 billion total parameters but only about 6 billion active for any given token. The release is available on Hugging Face under the permissive Apache-2.0 license, which allows commercial use and modification without the usage restrictions attached to many competing open-weight models.
The naming hints at the design goal. A sparse MoE routes each token through a small subset of specialized experts, so a model can hold a large pool of knowledge while keeping the compute per forward pass closer to that of a much smaller dense model. In Leanstral's case, the roughly 6B active footprint is what determines inference cost and latency, not the full 119B.
Why it matters
The economics of running large models remain the biggest barrier to open deployment, and sparse activation is one of the more practical answers.
- Total capacity: 119B parameters across experts
- Active per token: about 6B, keeping serving costs down
- License: Apache-2.0, friendly to commercial and downstream use
- Focus: text generation with reasoning among its listed modalities
Mistral has built much of its reputation on efficient, openly licensed models, and Leanstral 1.5 continues that pattern by targeting teams that want a capable model they can host themselves without heavy hardware demands. Full context-window details and benchmark figures were not specified in the release record; readers should consult the model card for configuration and evaluation specifics as they are published.
Sources
- Visit
mistralai/Leanstral-1.5-119B-A6B
Hugging Face
More from Mistral AI
All Mistral AI releases →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
Mistral's Timestral brings forecasting to open weights
The French lab releases a compact 209M-parameter foundation model aimed squarely at time-series prediction.
Mistral Large 4 arrives as a trillion-param MoE
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.

Liquid AI debuts LFM3-1.7B for edge deployment
A compact 1.7B-parameter multilingual model built to run locally and serve as the base for specialized multimodal variants.
0 comments
No comments yet. Be the first to weigh in.