Zhipu AI Releases Open Vision Model GLM-4.5V
The new Mixture-of-Experts model offers strong multimodal reasoning capabilities under a permissive MIT license.

Chinese AI firm Zhipu AI has released GLM-4.5V, a new open-source vision-language model (VLM). The model, which uses a Mixture-of-Experts (MoE) architecture, is designed for sophisticated tasks that require understanding and reasoning about both text and images simultaneously.
According to the release notes, GLM-4.5V is built upon the company's GLM-4.5-Air-Base model. The key advancement is its capacity for what Zhipu AI describes as strong multimodal reasoning. This makes it suitable for complex applications like detailed image analysis, visual question answering, and generating text grounded in visual information. The model weights and code are available now on Hugging Face.
Why it matters
The release is significant for two main reasons. First, it adds a powerful, openly accessible VLM to the ecosystem, a domain where proprietary models have often dominated. Second, its release under the permissive MIT license removes significant barriers for both commercial and research applications, allowing developers to freely build upon and integrate the technology.
The MoE architecture also suggests an efficient design, capable of activating only the necessary expert sub-networks during inference. This can lead to faster performance and lower computational costs compared to dense models of a similar capability level, making advanced multimodal AI more accessible to a wider range of developers and organizations.
Sources
- Visit
zai-org/GLM-4.5V
Hugging Face
More from Zhipu AI
All Zhipu AI releases →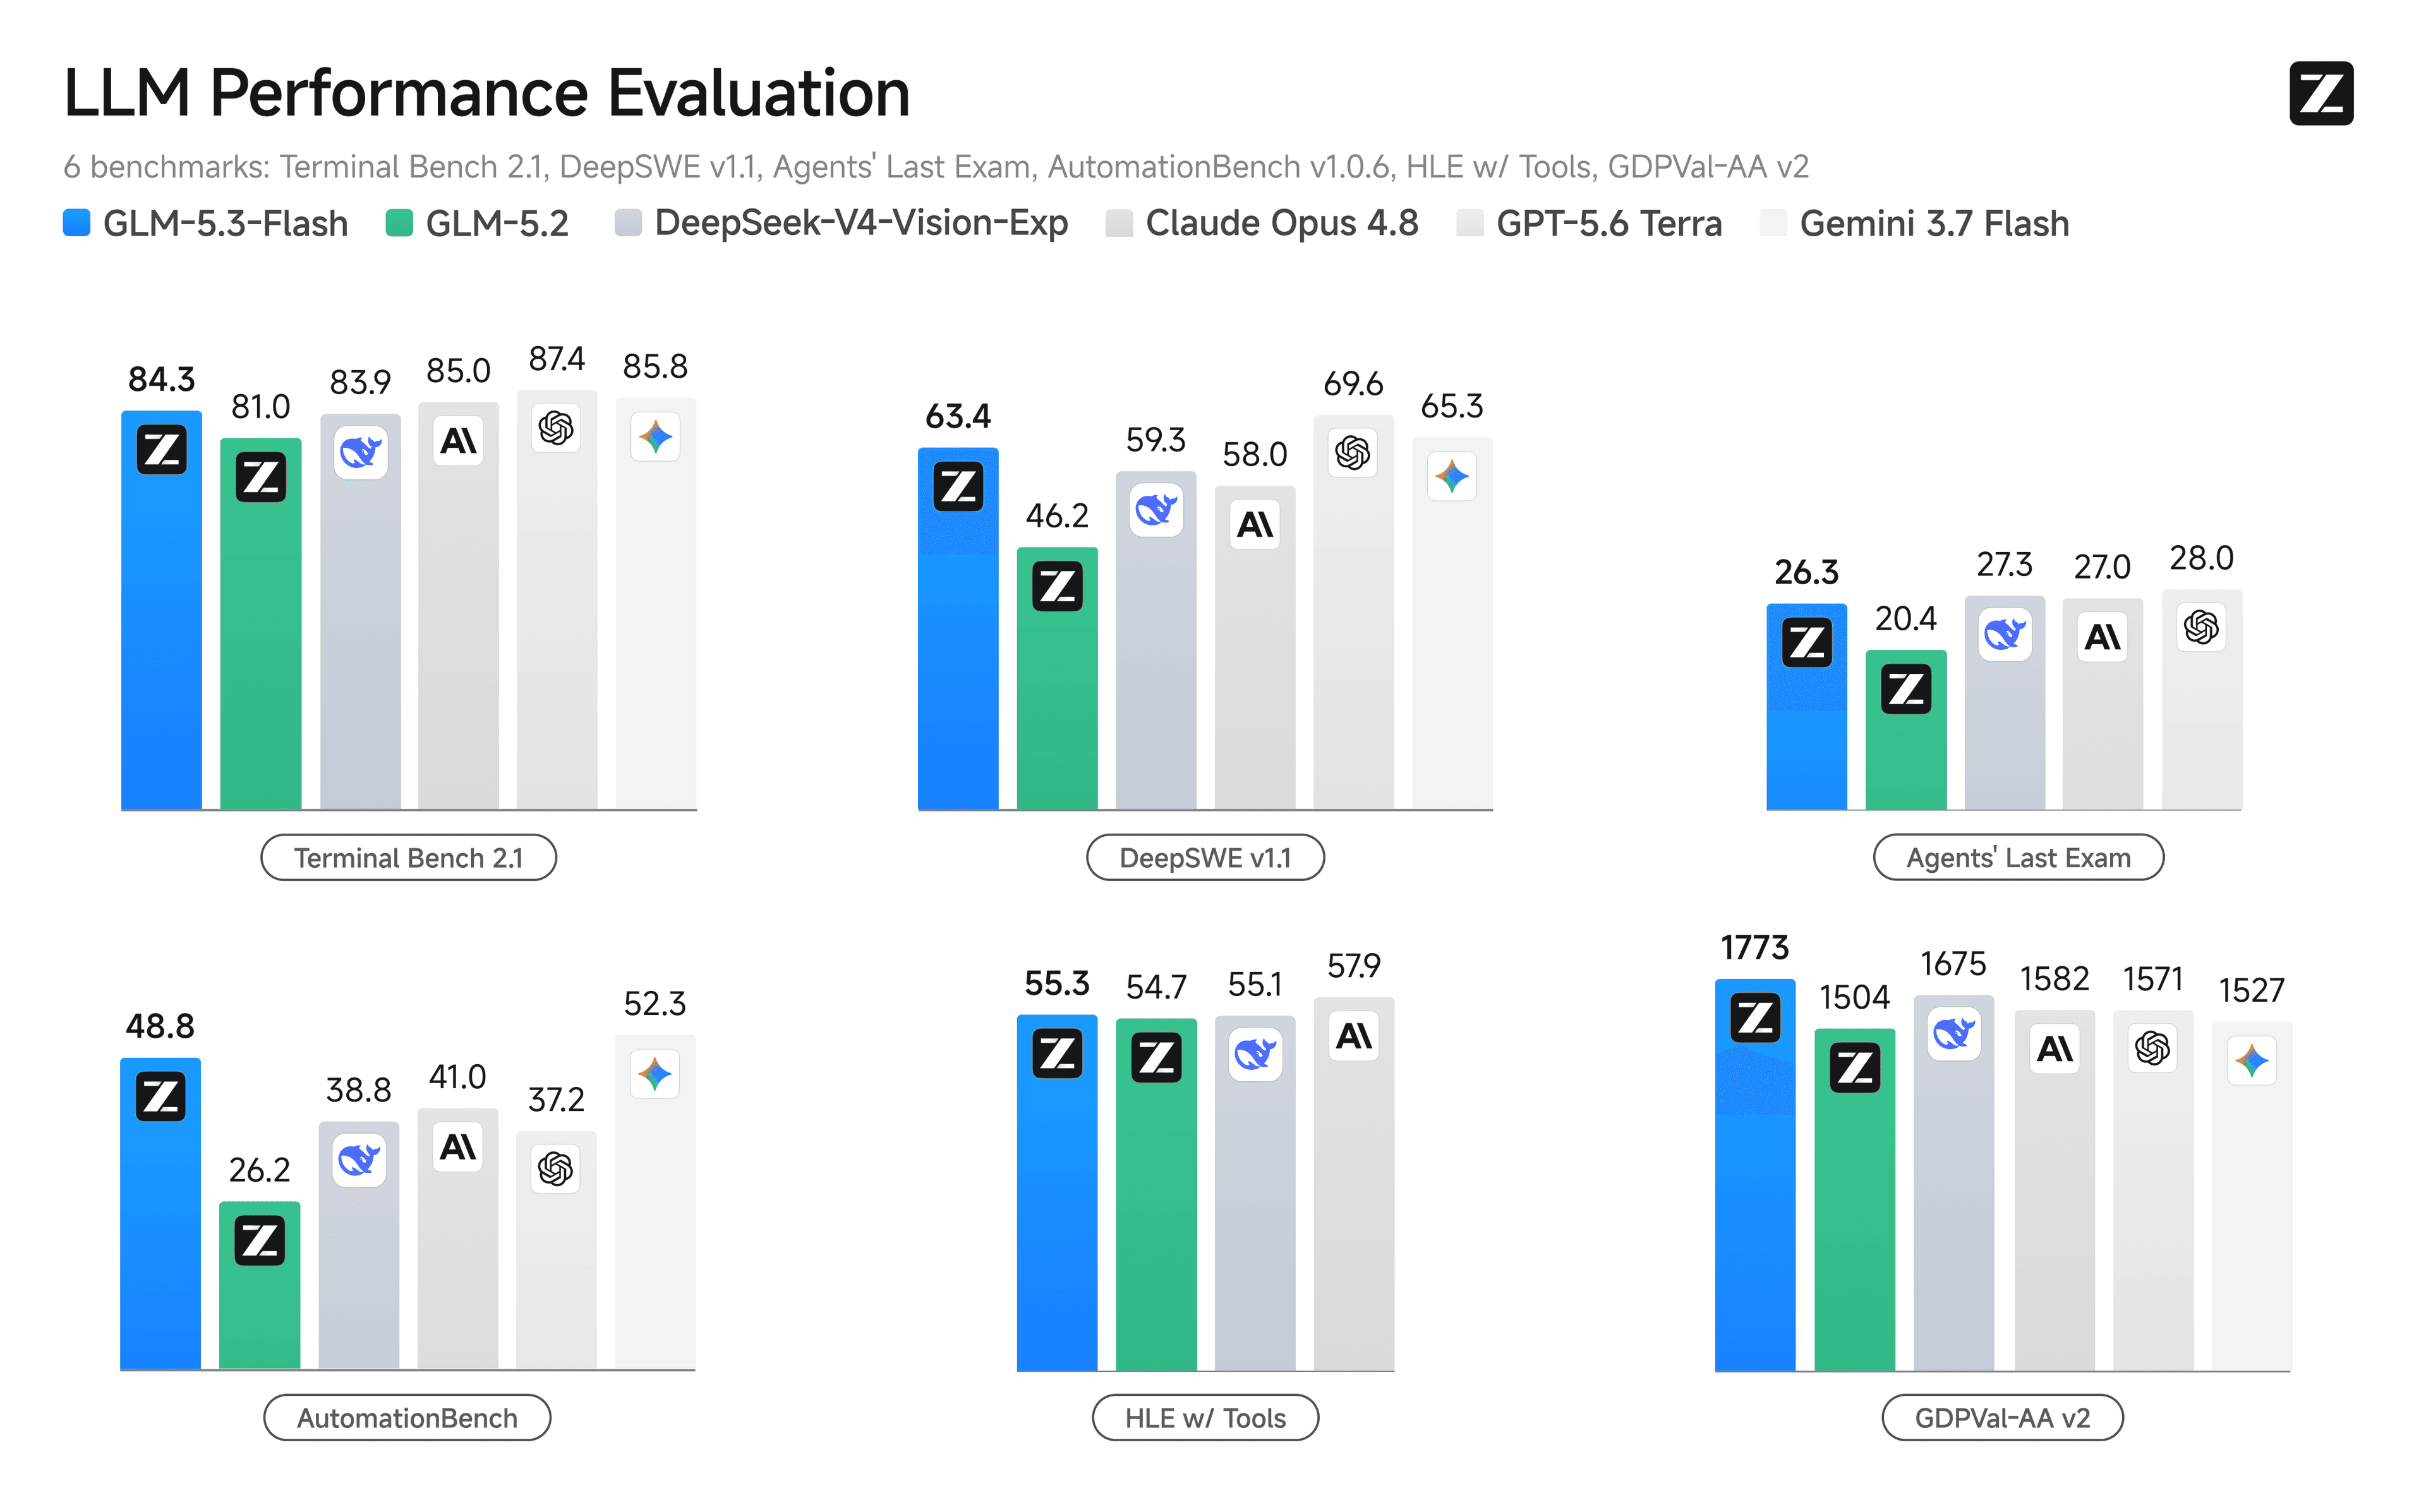
Zhipu releases GLM-5.3-Flash under MIT license
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
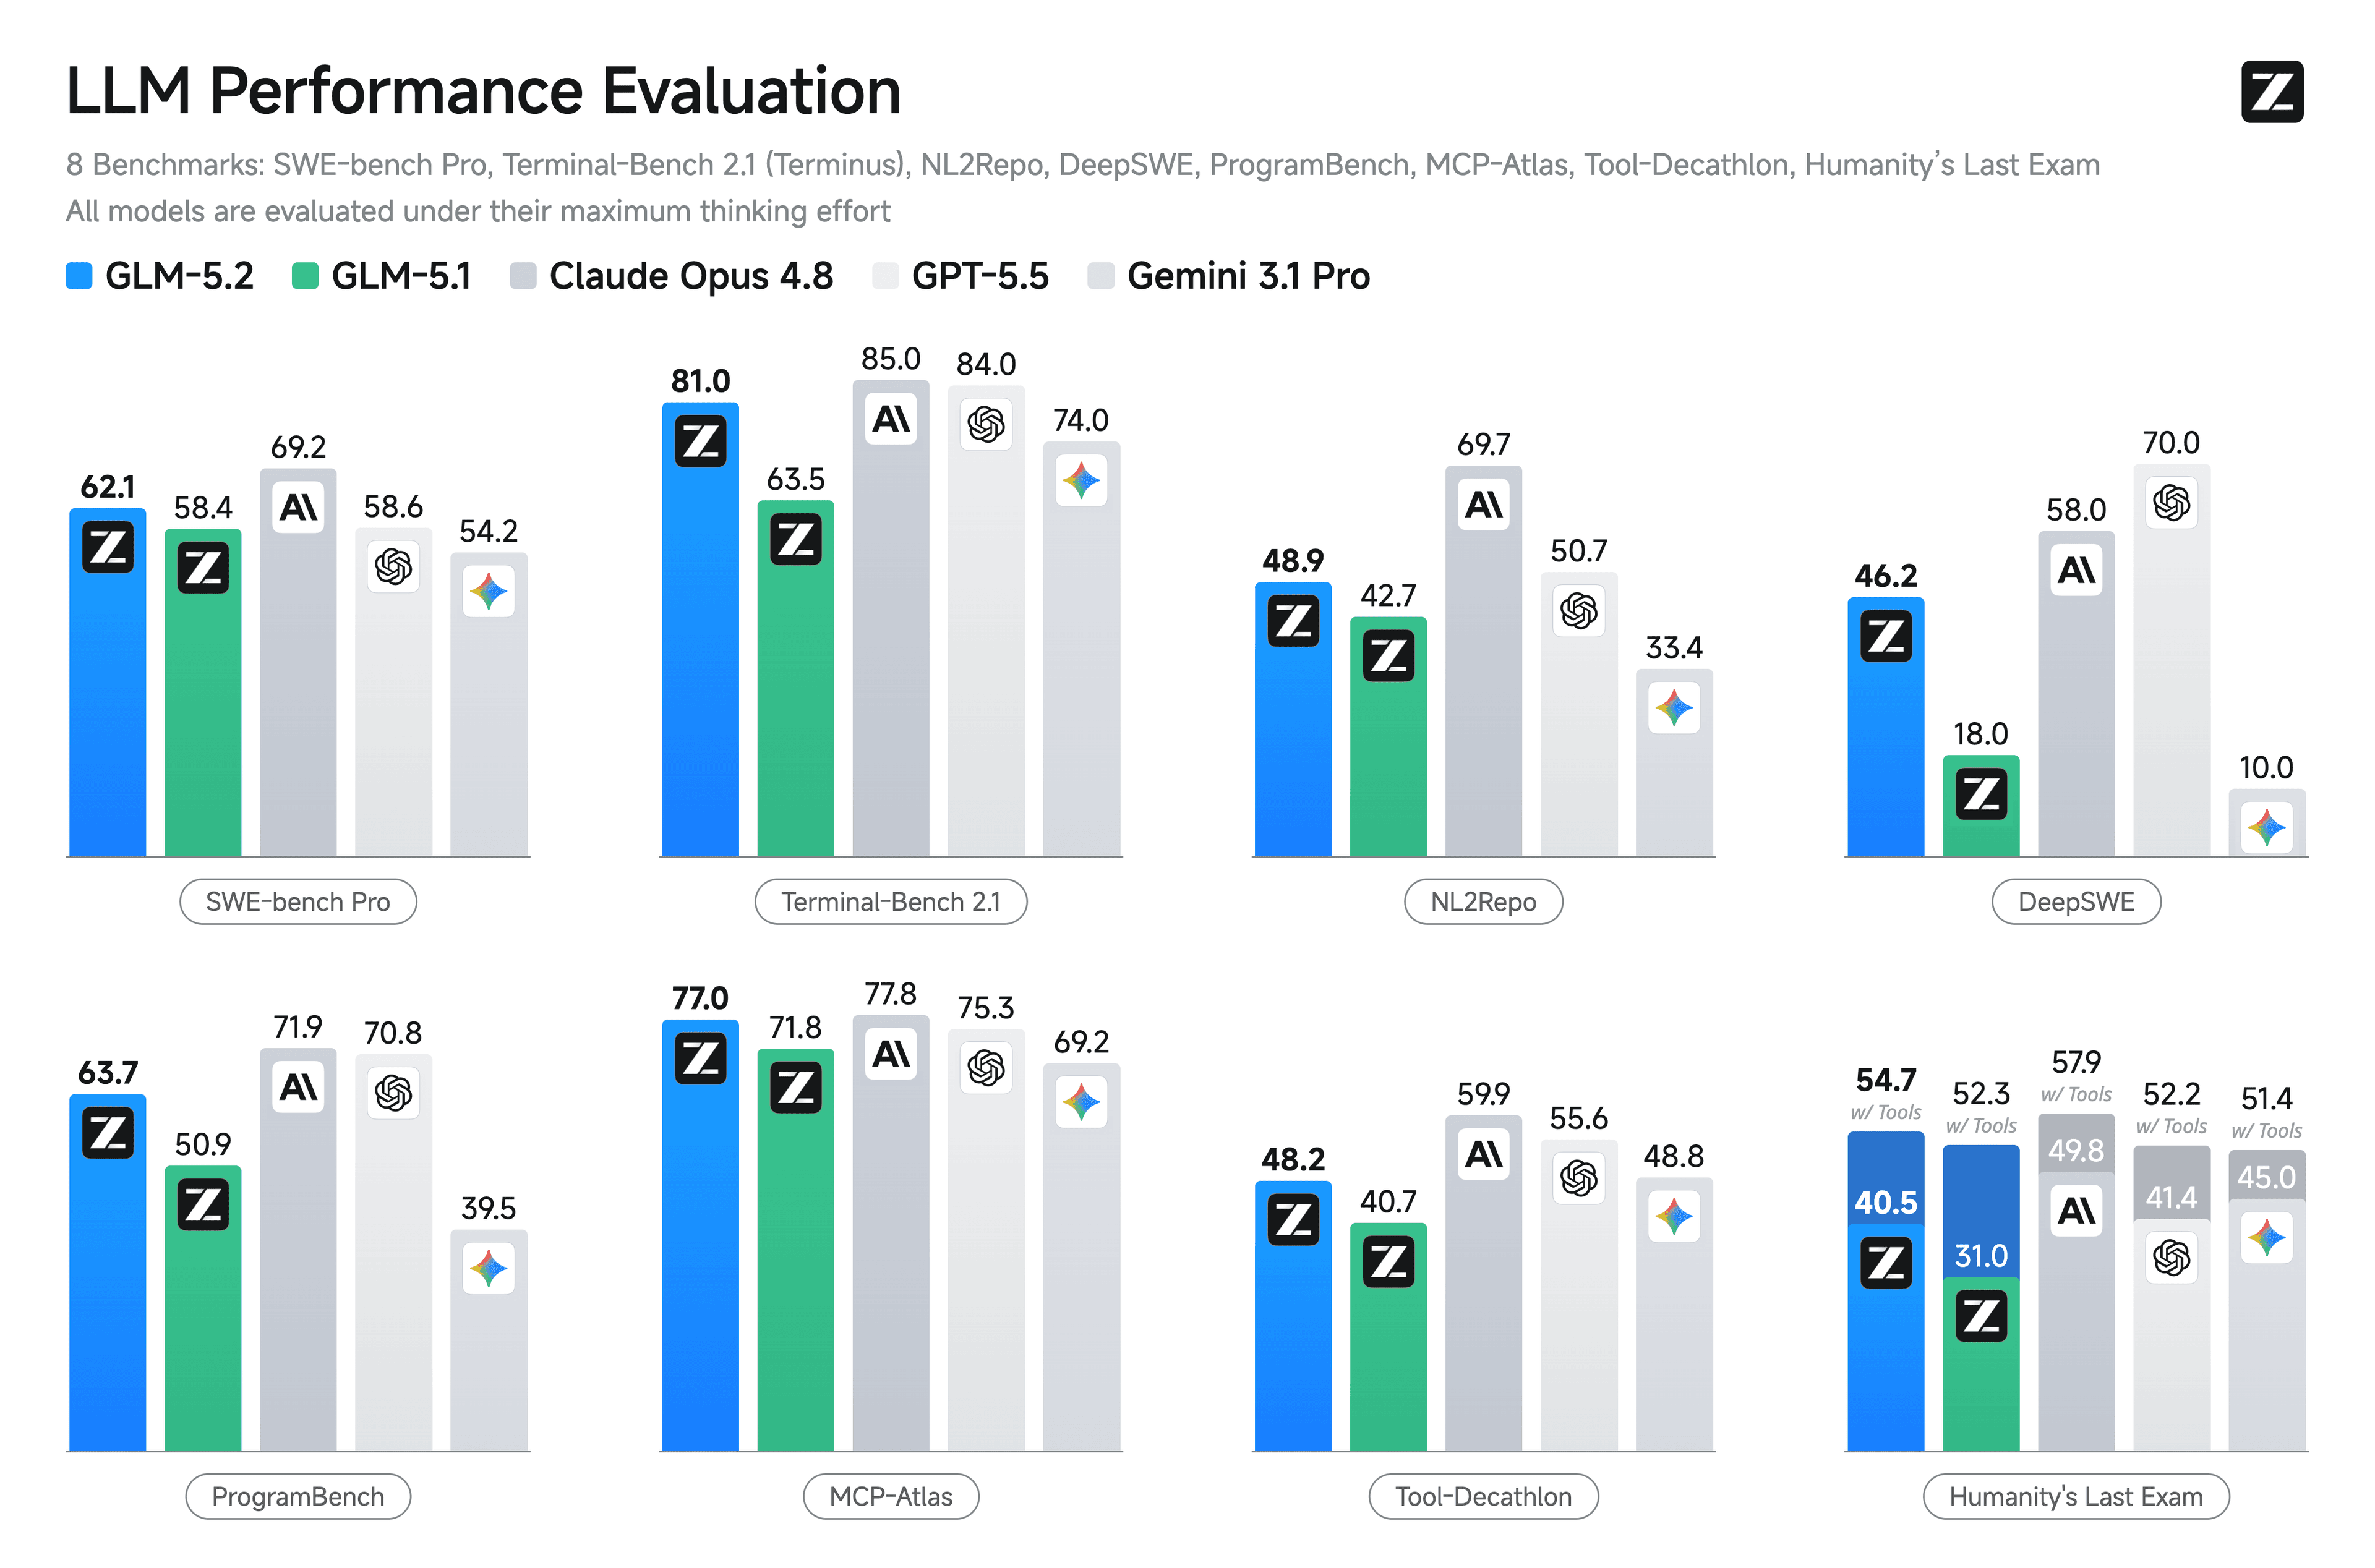
Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.