JetBrains ships Mellum 2.1, a reasoning MoE for code
The updated Mellum packs 12B total parameters but activates just 2.5B, pairing code specialization with a new thinking mode under Apache-2.0.
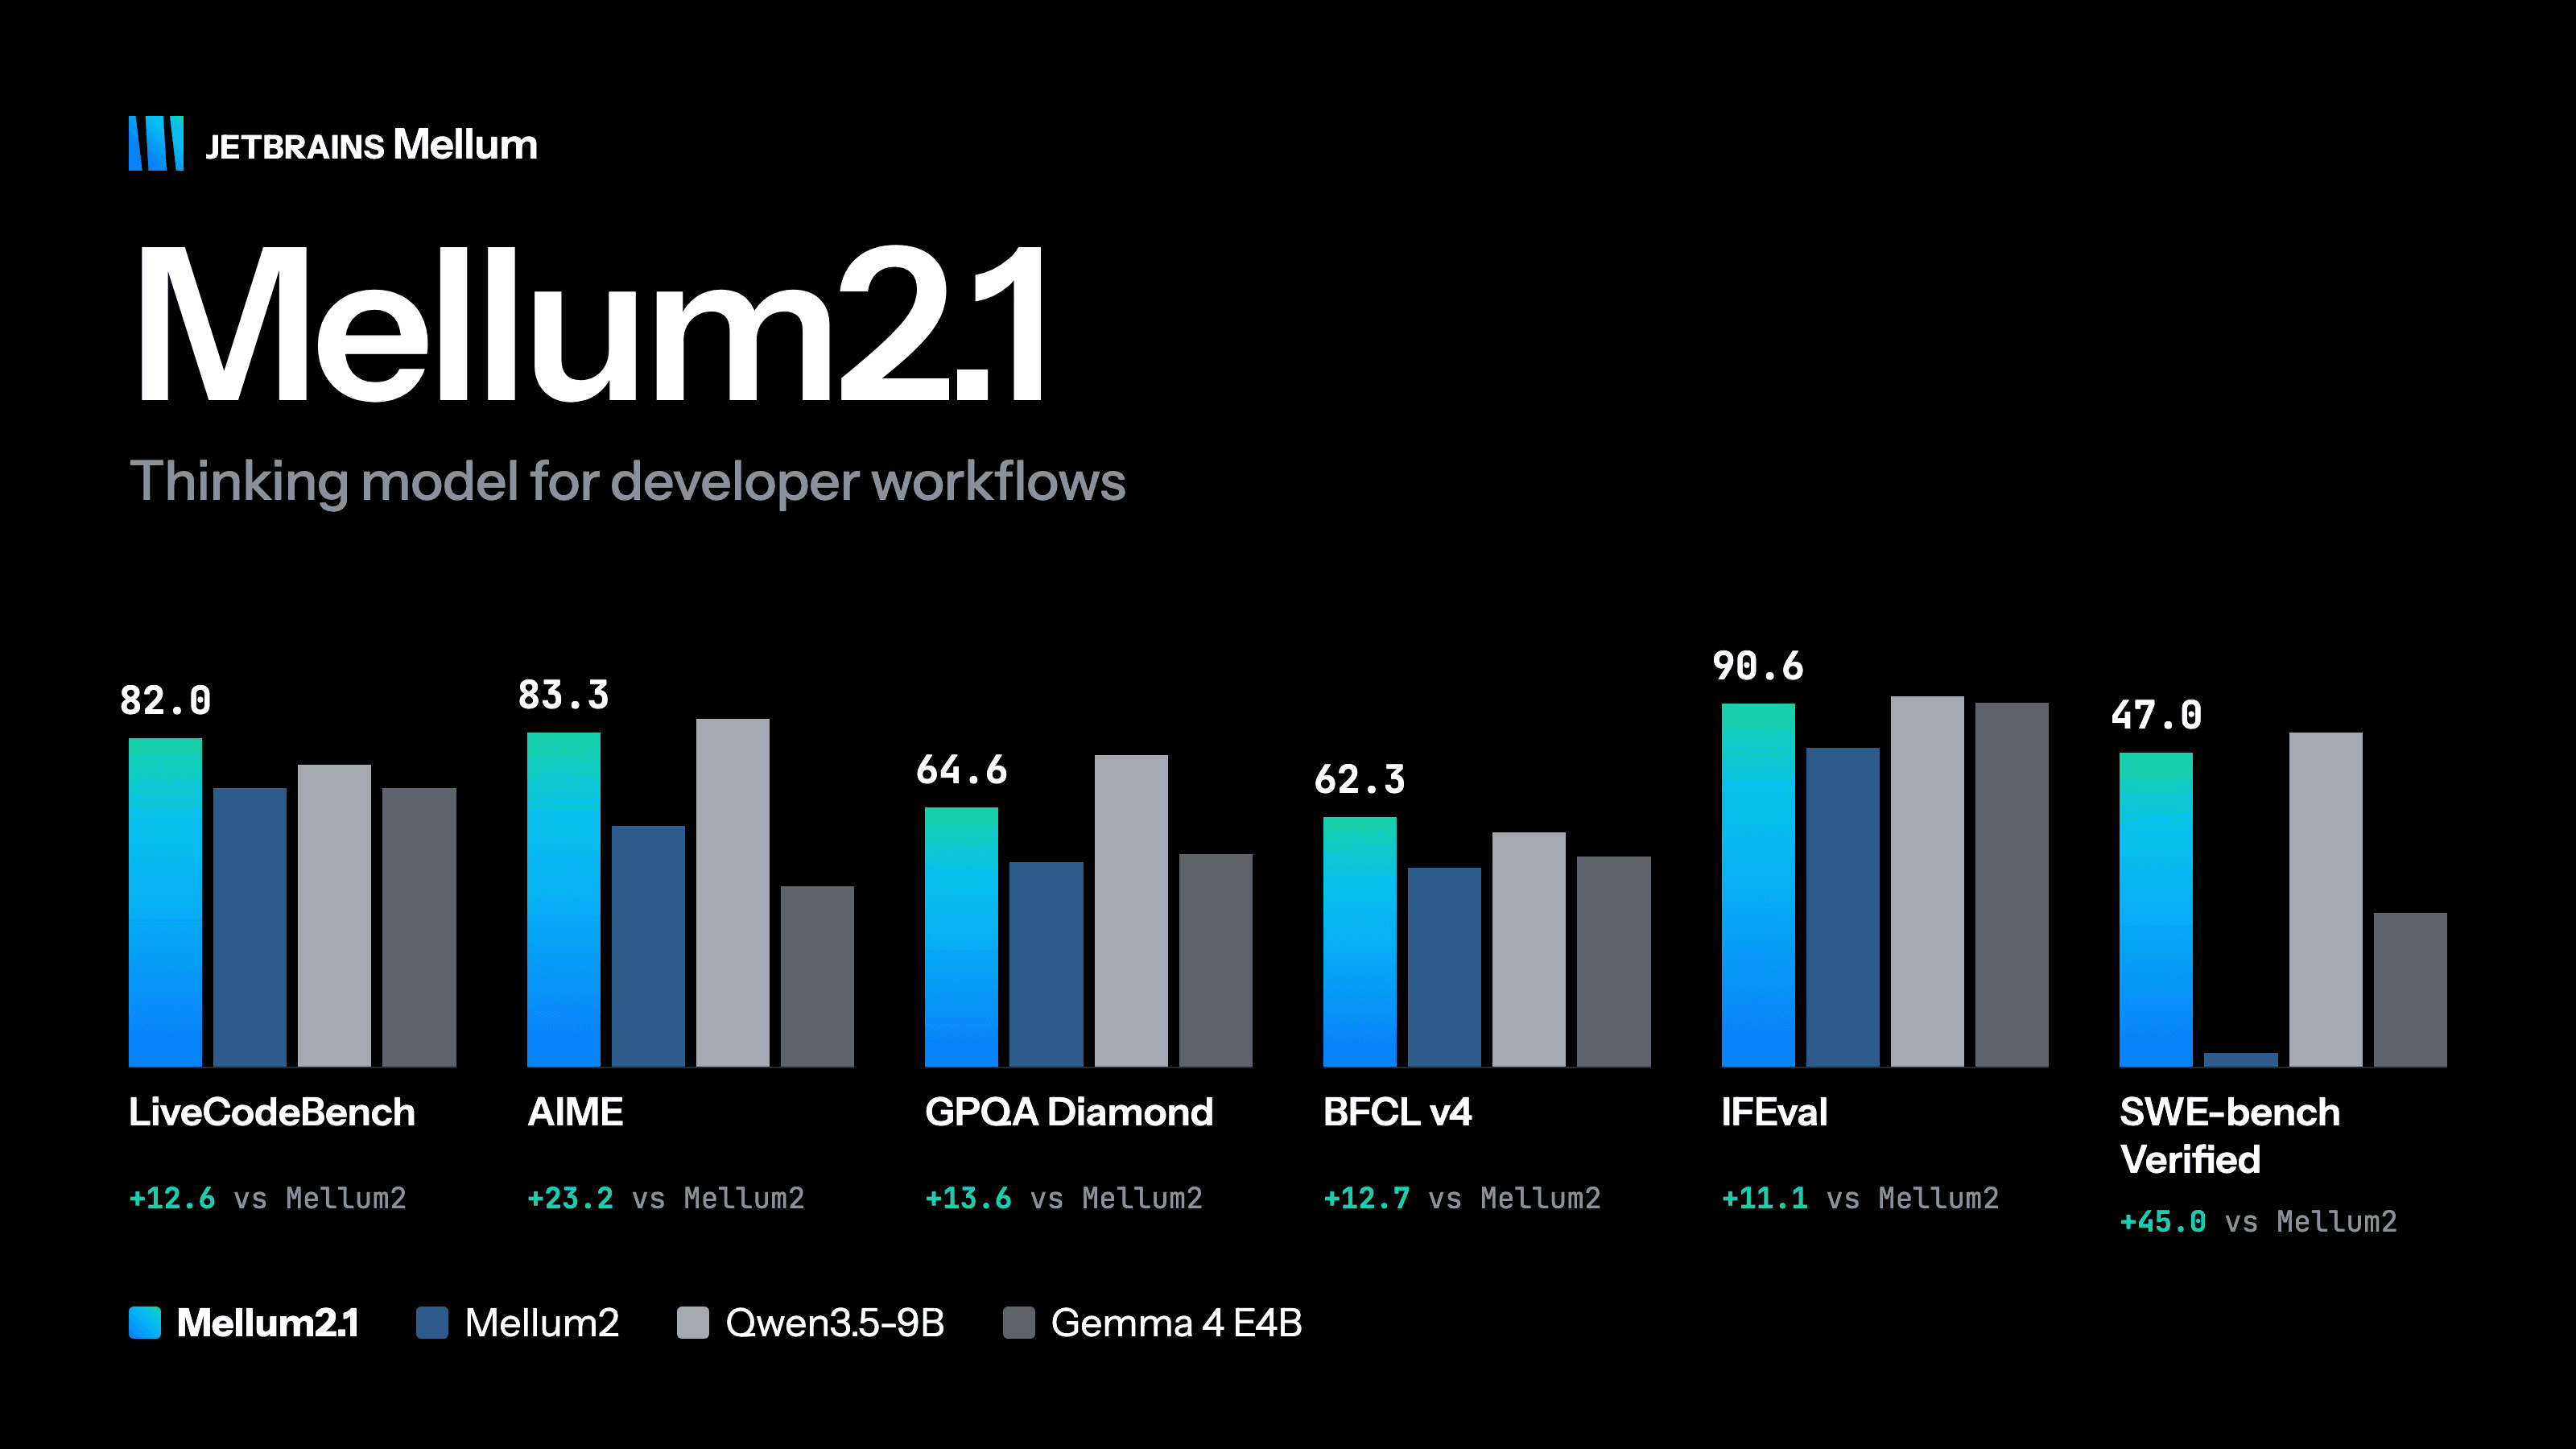
JetBrains has released Mellum 2.1, the latest version of its code-focused language model line. The new build is a mixture-of-experts design with 12B total parameters but only 2.5B active per token, and it adds a reasoning-oriented "Thinking" variant aimed at harder programming tasks.
The sparse layout is the headline here. By routing each token through a small fraction of the network, an MoE model can offer the capacity of a larger system while keeping inference costs closer to a 2.5B dense model. For a company whose core business is developer tooling, that efficiency matters: code assistance is latency-sensitive and often runs at scale across IDEs.
Why it matters
- Permissive licensing. Mellum 2.1 ships under Apache-2.0, making it straightforward to fine-tune, self-host, or embed in commercial products.
- Reasoning for code. The Thinking configuration signals a push toward multi-step problem solving rather than pure autocompletion.
- Lean active footprint. At 2.5B active parameters, it is designed to be practical to run outside of heavyweight datacenter setups.
JetBrains has positioned Mellum as a purpose-built family rather than a general-purpose chatbot, and this update continues that focus on software development workloads. Teams evaluating open models for coding can find the weights and details on the Hugging Face repository.
Sources
- Visit
JetBrains/Mellum2.1-12B-A2.5B-Thinking
Hugging Face
More in Code
All Code →
Xiaomi distills MiMo V2.6 into a 9B model
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
Cactus Needle 3: tiny on-device tool-calling models
Cactus Compute's 8–29MB models aim to run automation and tool-calling entirely on-device, rivaling far larger cloud systems.
Tencent's T1 Targets Long-Horizon Terminal Work
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.
0 comments
No comments yet. Be the first to weigh in.