StepFun Posts Step-5-Preview Vision-Language Model
The Chinese AI lab's early look at its next multimodal system arrives on Hugging Face ahead of a full release.
StepFun has quietly posted Step-5-Preview, an early build of its next-generation vision-language model, on Hugging Face. As the name suggests, this is a preview rather than a finished release, giving researchers and developers an initial window into the direction of the company's Step-5 family.
The model is multimodal, handling both image and text inputs, with vision-language understanding as its primary focus. StepFun has not published detailed specifications alongside the preview, including parameter counts, context length, or benchmark results, so the model's precise capabilities remain to be measured by the community.
Why it matters
StepFun is among a growing group of Chinese labs releasing increasingly capable multimodal systems into the open ecosystem. Preview drops like this one serve a few purposes:
- They let external developers kick the tires before a stable version lands.
- They signal a lab's technical roadmap to the wider research community.
- They invite early feedback that can shape the eventual general release.
The model carries a custom license rather than a standard permissive one, so teams considering it for production should read the terms on the model page closely. As a preview, it is best treated as an experimental artifact — a sign of what StepFun intends to ship, with the full Step-5 release still to come.
Sources
- Visit
stepfun-ai/Step-5-Preview
Hugging Face
More from StepFun
All StepFun releases →StepFun's StepAudio 3 Realtime targets live voice AI
The audio-language foundation model builds a listen-converse-think-act loop aimed at natural, low-latency spoken interaction.
StepFun's StepAudio 3 Music Plans Before It Plays
The new open model separates musical structure from sound, generating long-form tracks from text prompts with an explicit planning stage.
StepFun's StepAudio 3 Gen Unifies TTS and Music
A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.
More in Vision-Language
All Vision-Language →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
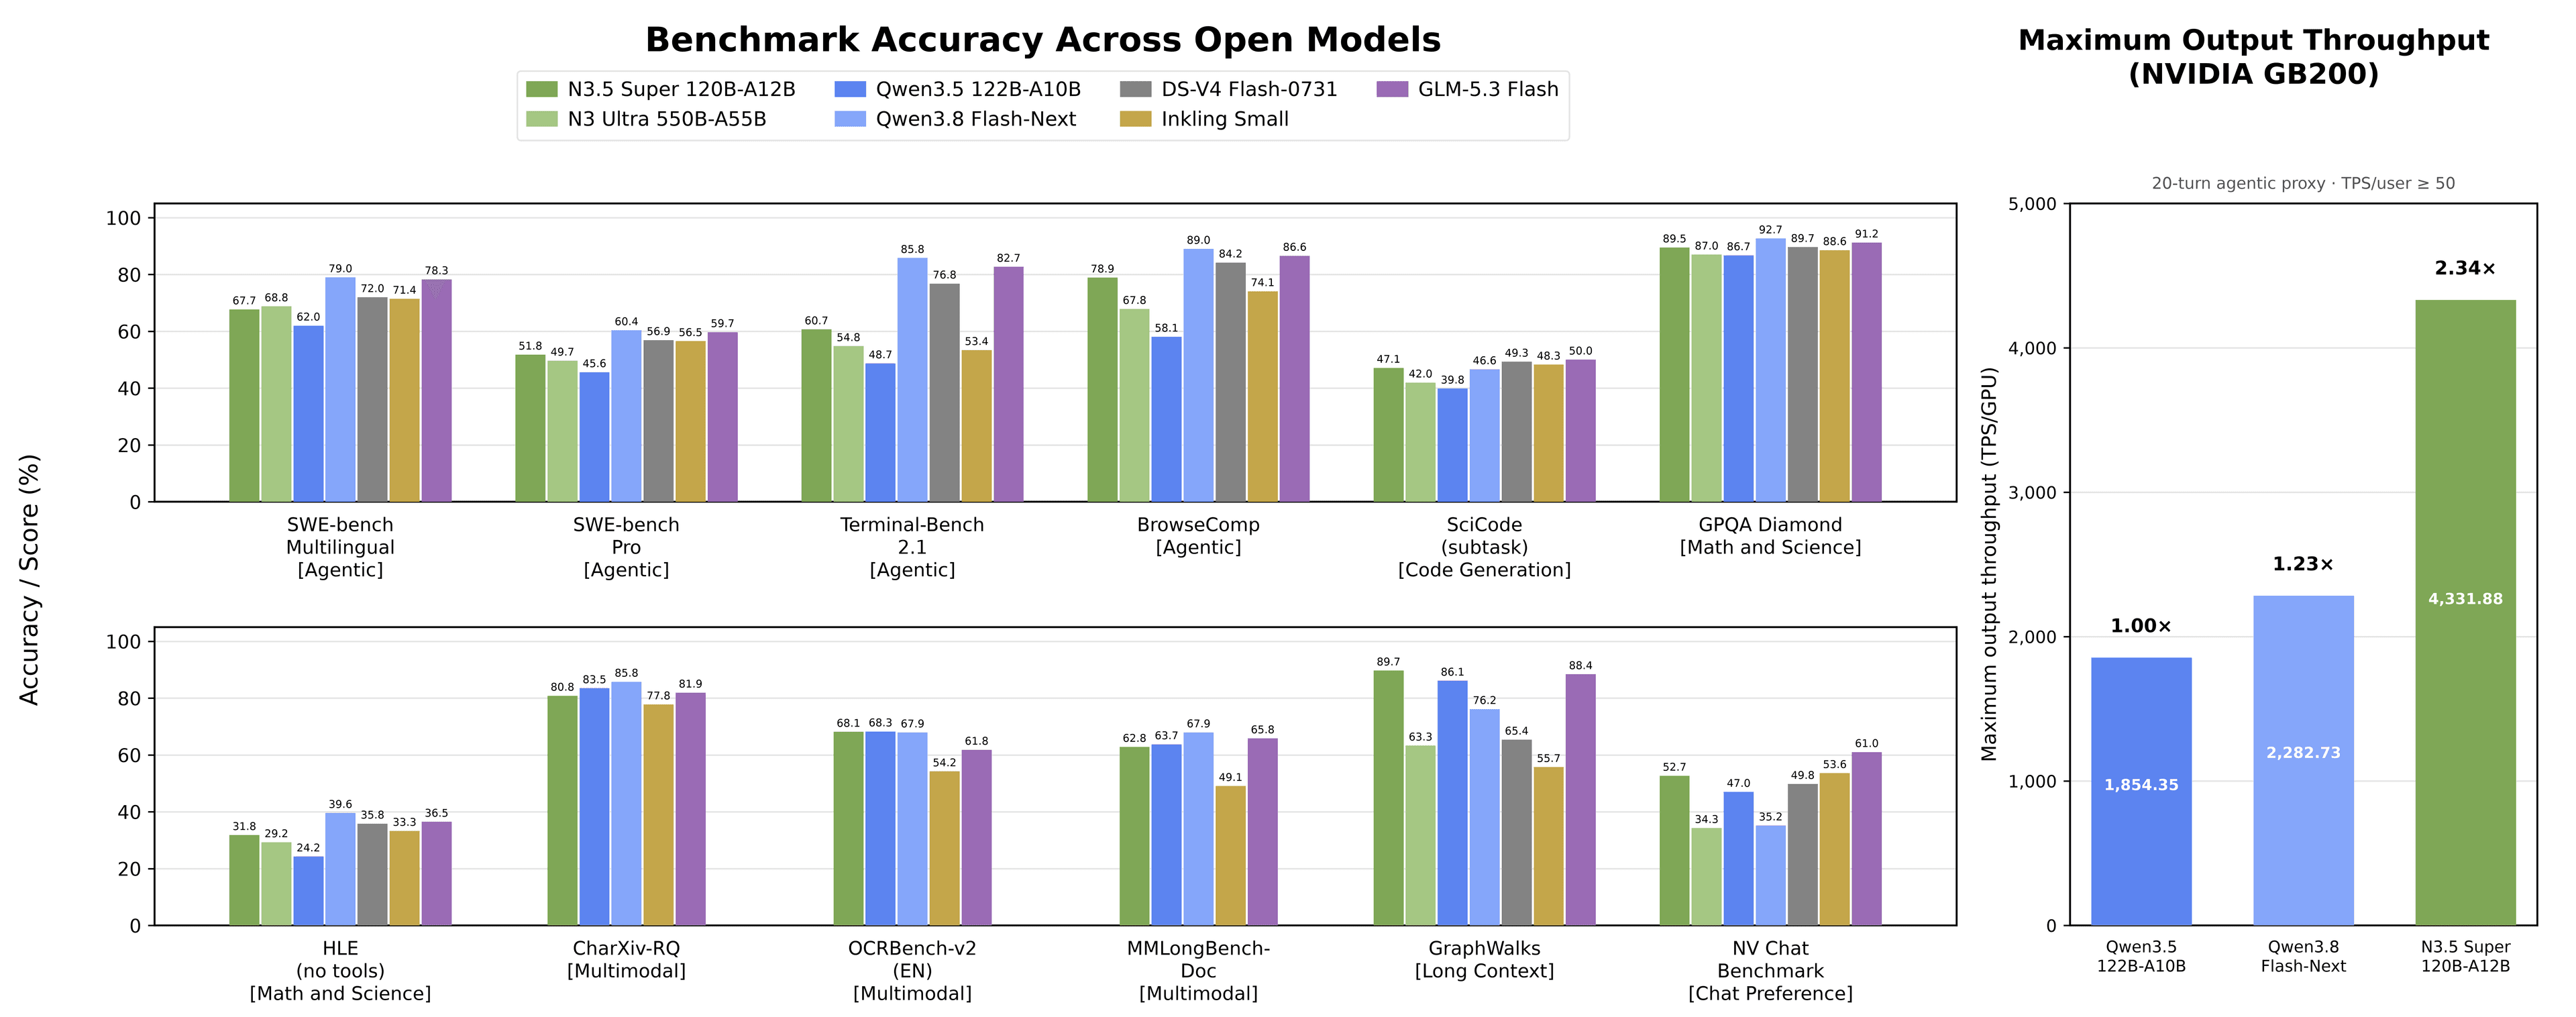
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
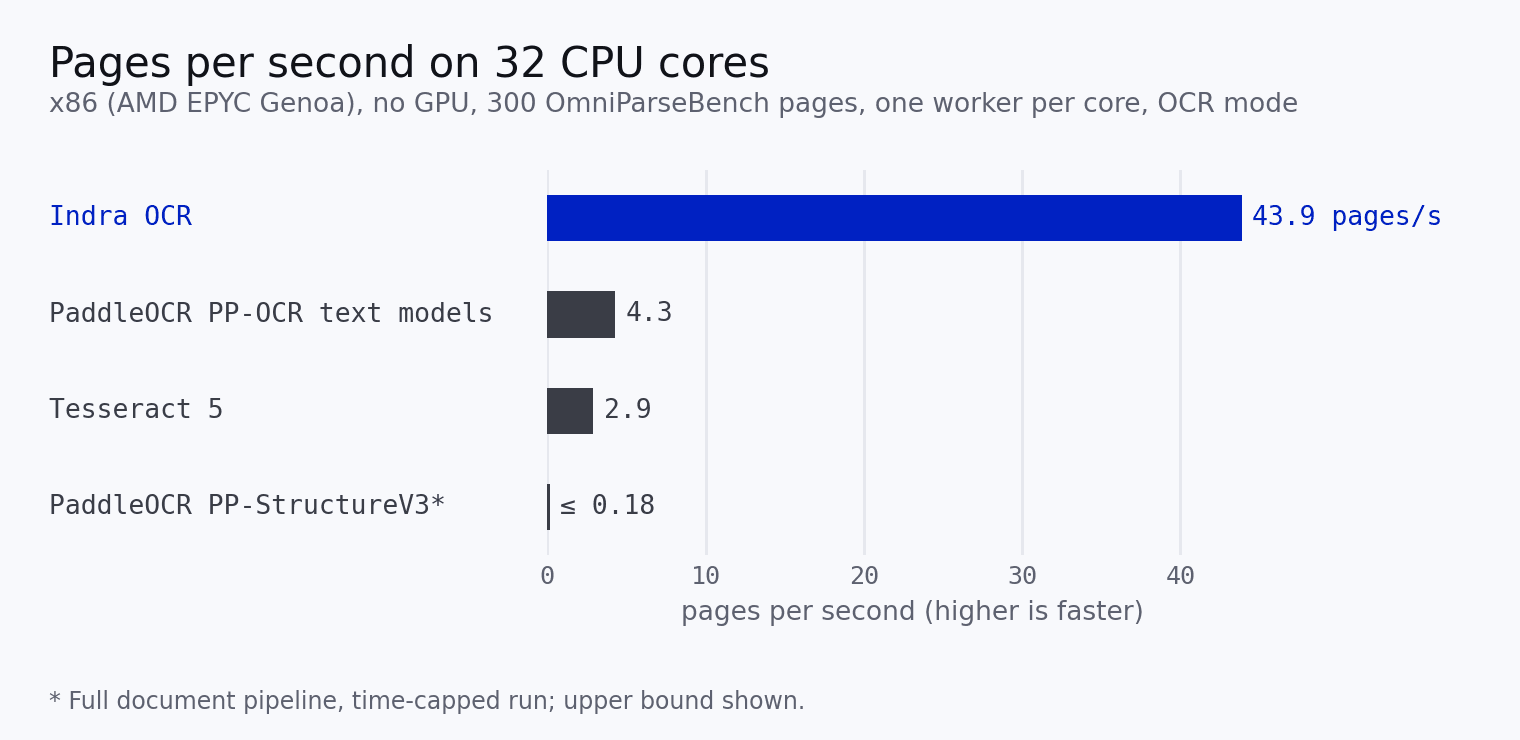
Indra OCR brings CPU-friendly document parsing
A new open vision-language model targets layout, handwriting and multilingual text extraction without a GPU.
0 comments
No comments yet. Be the first to weigh in.