Moondream shrinks Parakeet ASR for CPUs
A ternary-quantized take on the Parakeet TDT speech model aims to run transcription without a GPU.
Moondream has released Parakeet Redux, a reworked version of the Parakeet TDT speech recognition architecture that has been quantized down to ternary weights so it can run efficiently on ordinary processors. According to the model's Hugging Face page, the release is tuned specifically for CPU inference and Apple Silicon, and supports transcription in English, German and French.
Ternary quantization compresses a model's weights to just three possible values, dramatically reducing memory footprint and the compute needed per operation. That trade-off is what makes it feasible to run automatic speech recognition on a laptop or edge device rather than a dedicated accelerator.
Why it matters
Most high-quality speech-to-text still assumes access to a GPU. A model designed from the outset to work well on commodity hardware lowers the barrier for developers who want on-device transcription without sending audio to a cloud service.
- Targets CPU and Apple Silicon rather than discrete GPUs
- Ternary-quantized for a smaller memory footprint
- Handles English, German and French out of the box
The release is a minor update within the broader Parakeet lineage, and Moondream lists it under a custom license, so teams evaluating it for production should check the terms on the repository before shipping. For anyone experimenting with local, privacy-preserving voice interfaces, it is a low-cost model worth a look.
Sources
- Visit
moondream/parakeet-redux
Hugging Face
More from moondream
All moondream releases →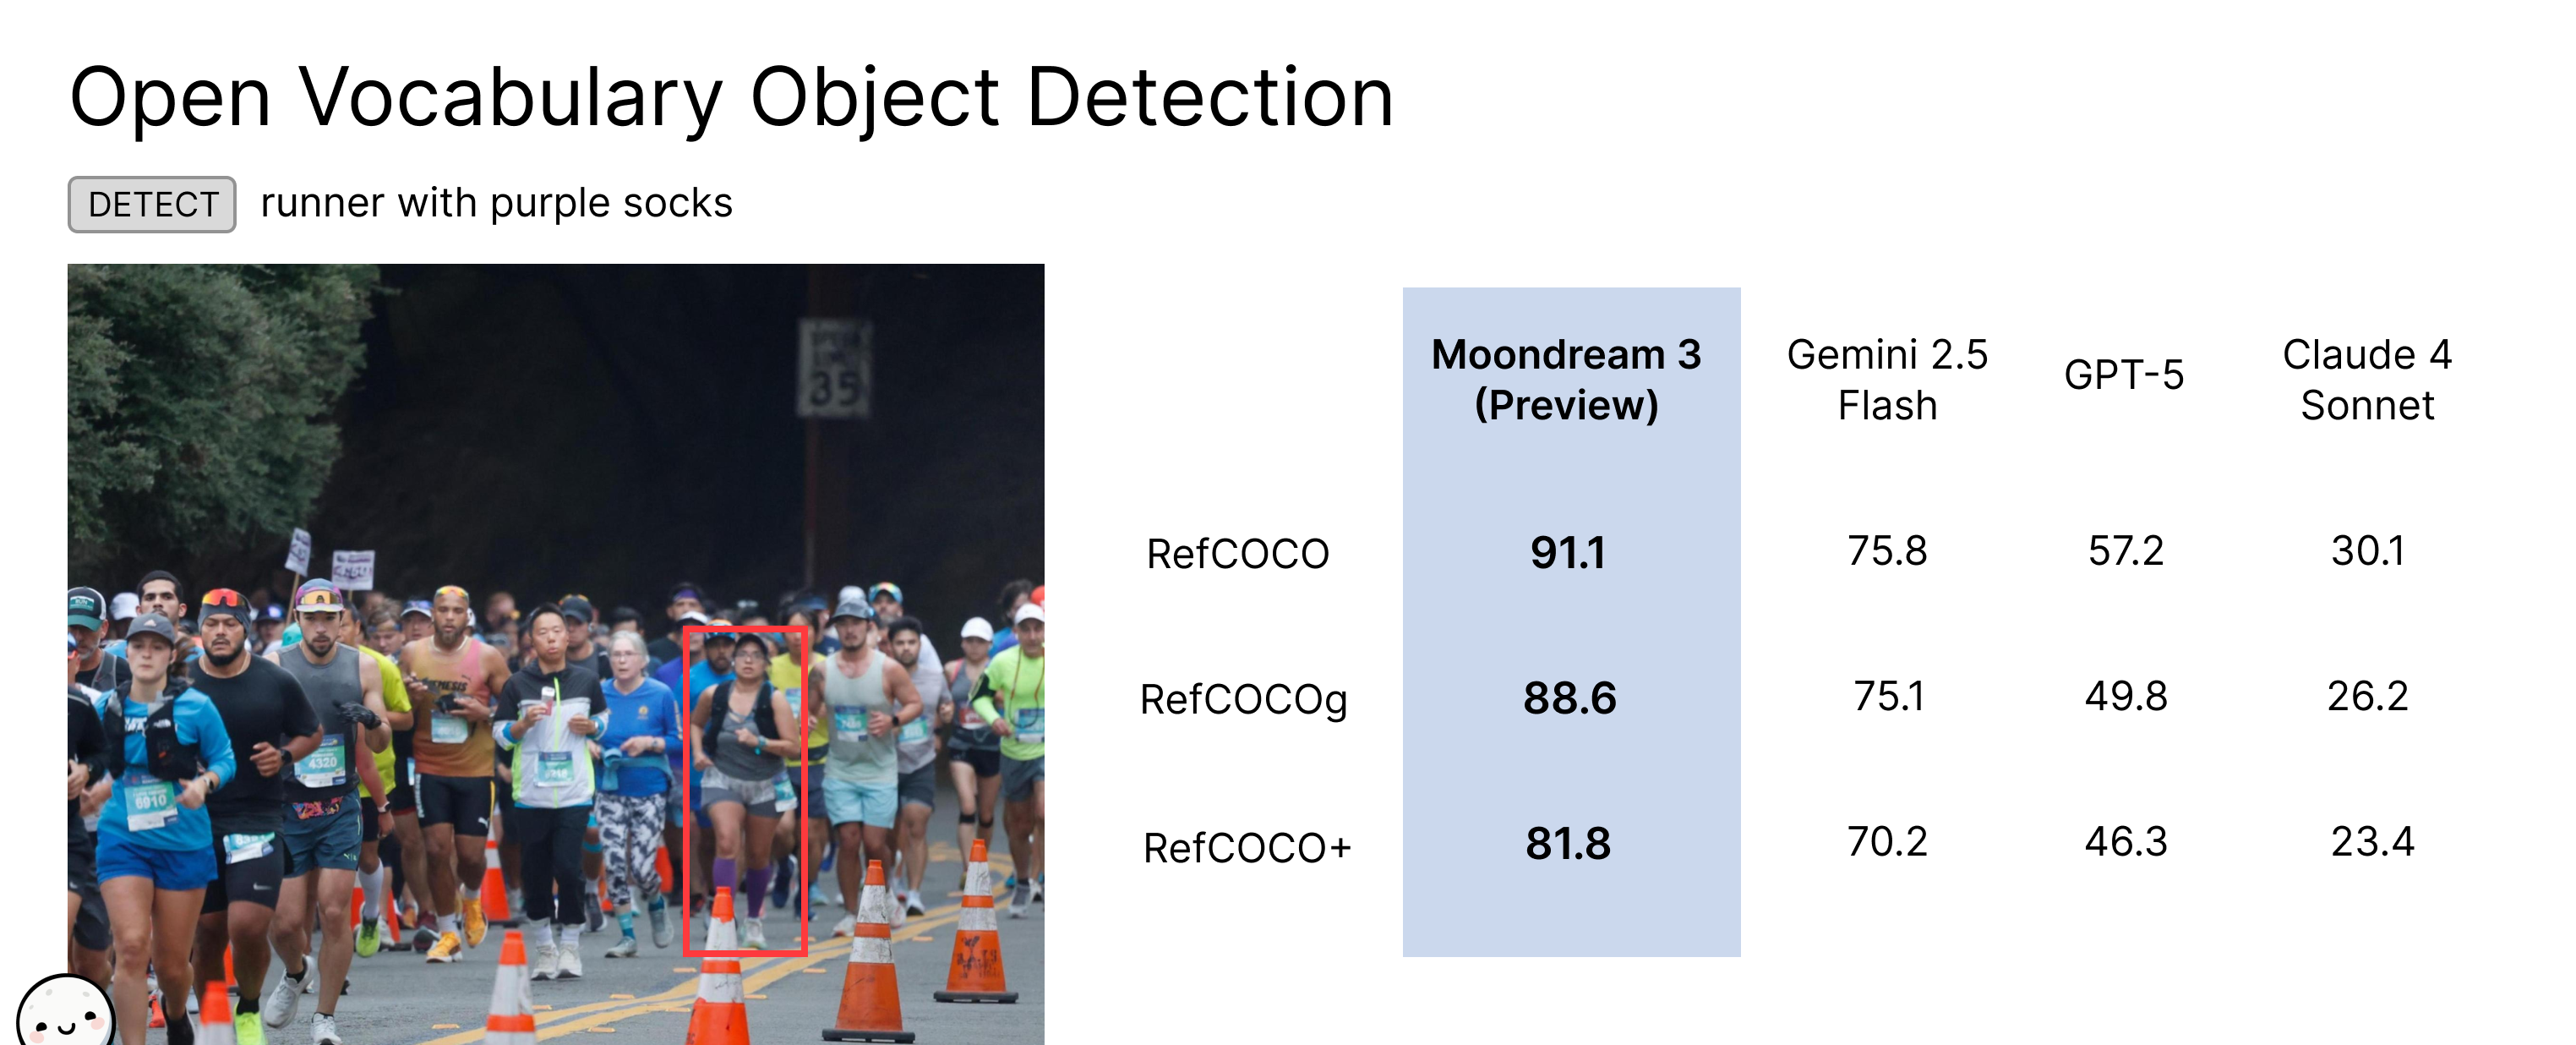
Moondream 3 Arrives in Preview Release
The next generation of the efficient, open-source vision-language model is now available for early testing and feedback.
More in Speech → Text
All Speech → Text →ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.
IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
0 comments
No comments yet. Be the first to weigh in.