NVIDIA's Nemotron 3.5 Lightning Blends Mamba and MoE
A 30B mixture-of-experts model with just 3B active parameters aims at fast, agentic coding workloads.

NVIDIA has published Nemotron 3.5 Lightning 30B-A3B on Hugging Face, a text-generation and reasoning model that leans on an unusual architecture to keep inference costs down. It is a mixture-of-experts design with 30 billion total parameters but only about 3 billion active per token, released here in BF16 precision.
The standout detail is the hybrid layout: the model combines Mamba-style state-space components with a mixture-of-experts structure. That pairing is meant to deliver the throughput advantages of both approaches — Mamba's linear-scaling sequence handling and MoE's ability to route work to a small slice of the network at a time.
Built for agentic coding
NVIDIA positions the release specifically for agentic coding, the kind of multi-step, tool-using workflows where a model plans, edits, and iterates rather than answering a single prompt. A few things stand out for that use case:
- Only 3B parameters activate per token, which lowers the compute and memory bill for long, repeated inference loops.
- The reasoning modality suggests it is tuned to produce structured, multi-step outputs.
- The compact active footprint makes it a candidate for teams that want capable coding assistance without frontier-scale serving costs.
Why it matters: agentic tools call models constantly, so per-token efficiency compounds fast. A sparse, hybrid model that keeps quality up while cutting active compute is exactly the trade-off developers building autonomous coding agents have been looking for.
The model ships under a custom NVIDIA license rather than a standard open license, so teams should review the terms before deploying it. Context length and benchmark figures were not specified in the release record.
Sources
- Visit
nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16
Hugging Face
More from NVIDIA
All NVIDIA releases →NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
More in Text / LLM
All Text / LLM →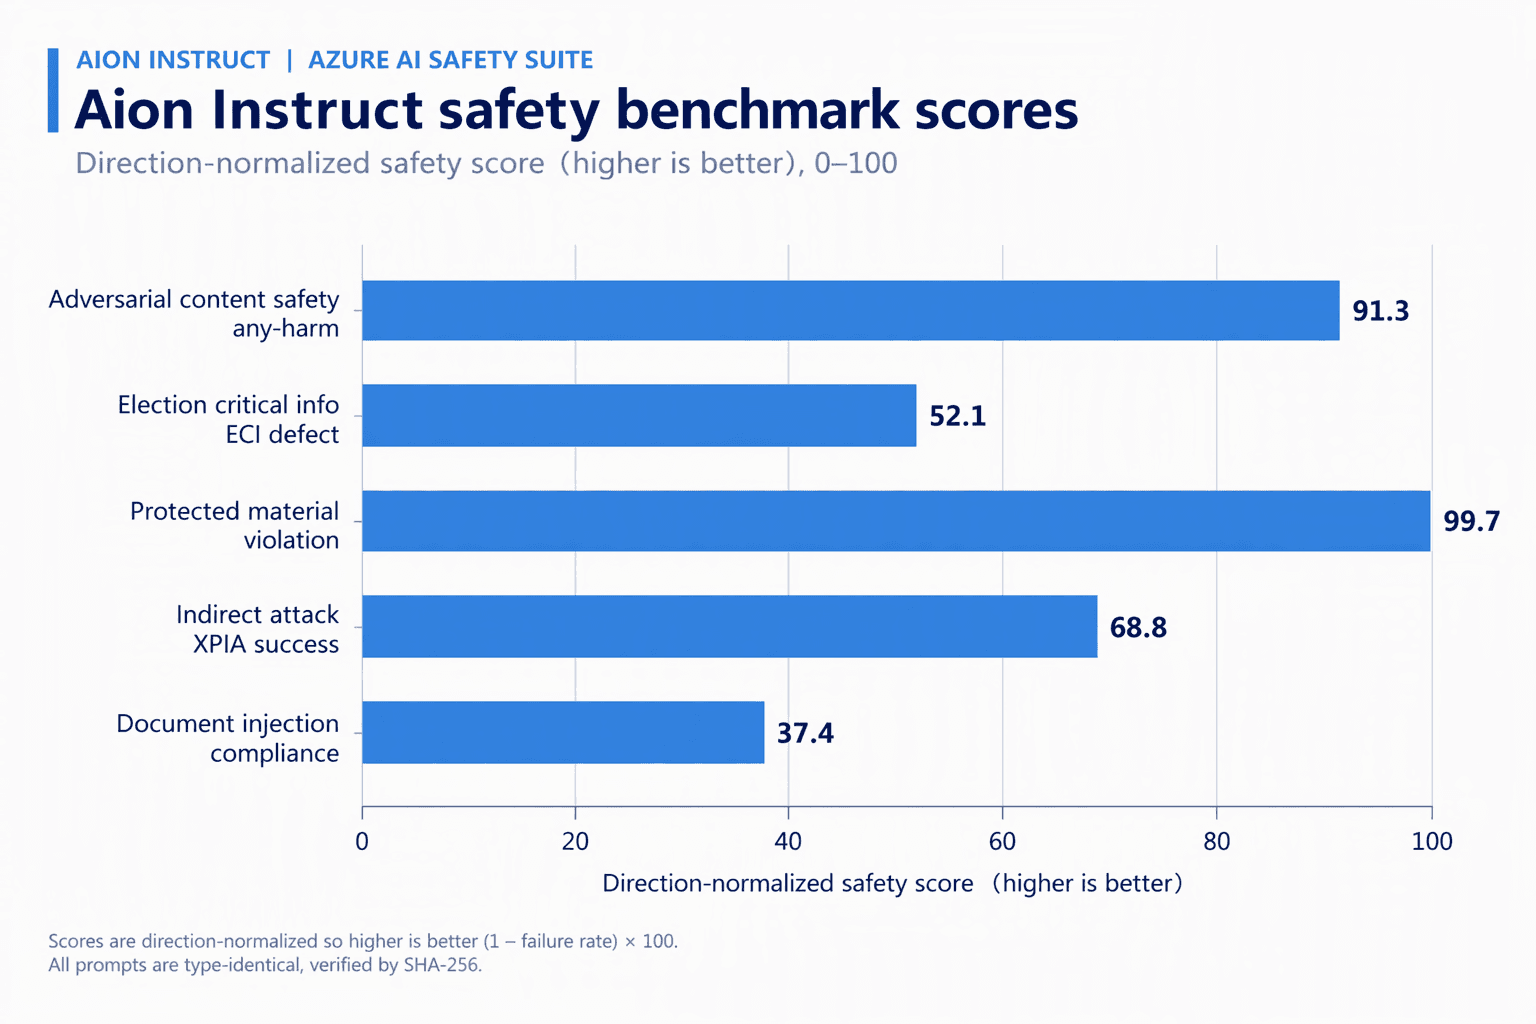
Microsoft's Aion 1.0 Instruct is a compact 2.3B chat model
A small, multilingual instruction-tuned model aimed at chat and summarization lands on Hugging Face.

SenseTime Releases Looped 9B Multimodal Model
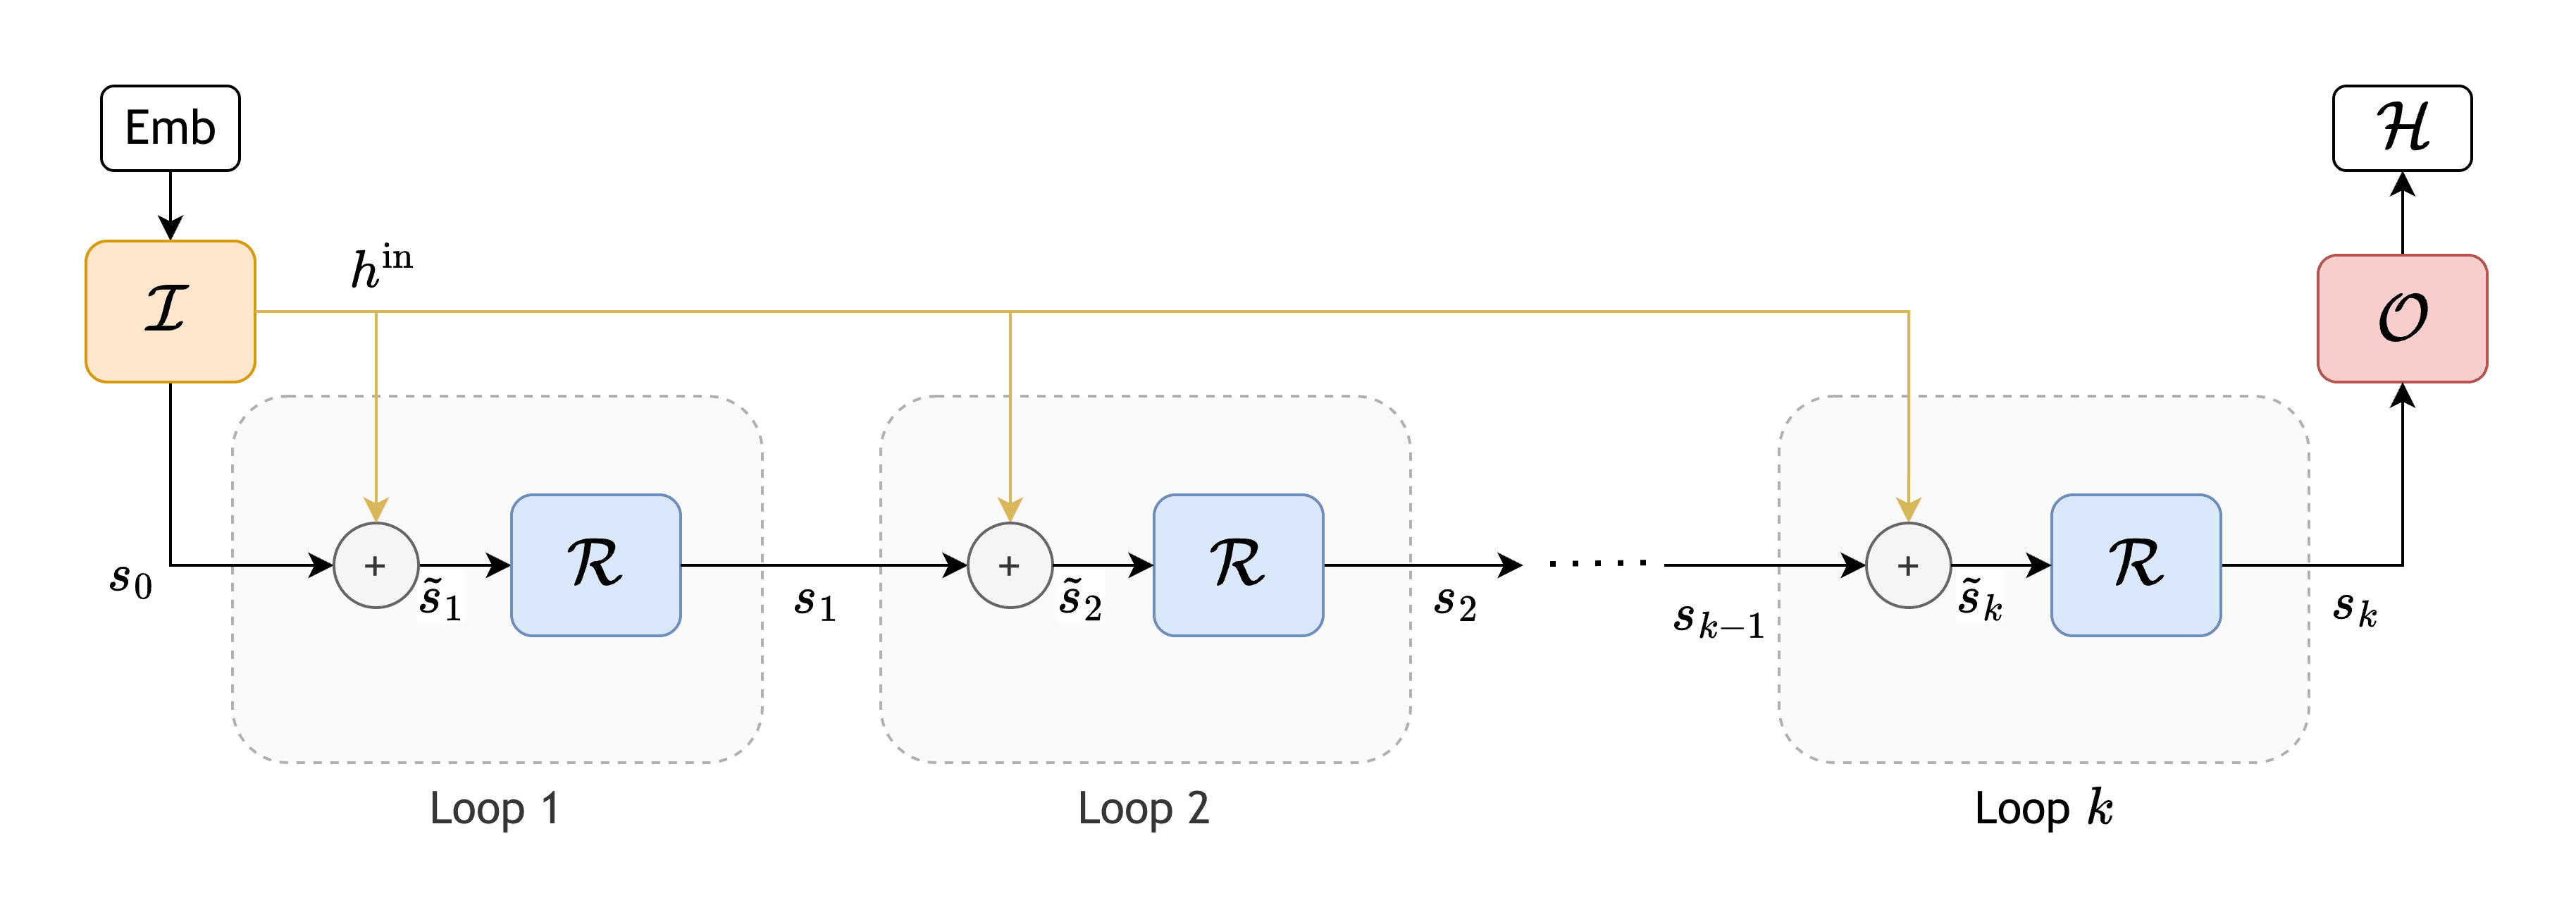
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
0 comments
No comments yet. Be the first to weigh in.