Agents-A1: A 35B MoE Built for Agentic Scaling
InclusionAI's new mixture-of-experts model bets that agent-horizon scaling can rival far larger systems on long-running tasks.

InclusionAI has released Agents-A1, a 35-billion-parameter mixture-of-experts (MoE) model aimed squarely at agentic workloads — the kind of multi-step, tool-using reasoning tasks that increasingly define how AI systems get deployed in practice. The model is available now on Hugging Face under a permissive Apache 2.0 license.
The headline claim is ambitious: that Agents-A1 reaches performance comparable to trillion-parameter systems through what its makers call agent-horizon scaling. Rather than simply growing parameter counts, the approach emphasizes a model's ability to plan and act over longer task horizons — a shift in where the gains come from.
Why it matters
Most frontier-scale capability has come from raw size, which keeps the best models out of reach for teams without large compute budgets. A 35B MoE that punches above its weight on agentic benchmarks would be meaningful for a few reasons:
- Efficiency: MoE architectures activate only a fraction of parameters per token, keeping inference costs lower than the headline size suggests.
- Open licensing: Apache 2.0 allows commercial use and modification without the restrictions seen in some other open releases.
- Focus: Optimizing for agent horizons rather than general chat reflects where a lot of real-world demand is heading.
As with any launch-day performance claims, the trillion-parameter comparison will need independent verification on public benchmarks. For now, Agents-A1 is an interesting data point in the growing argument that smarter training and architecture — not just scale — can close the gap with the largest models.
Sources
- Visit
InternScience/Agents-A1
Hugging Face
More from InternScience
All InternScience releases →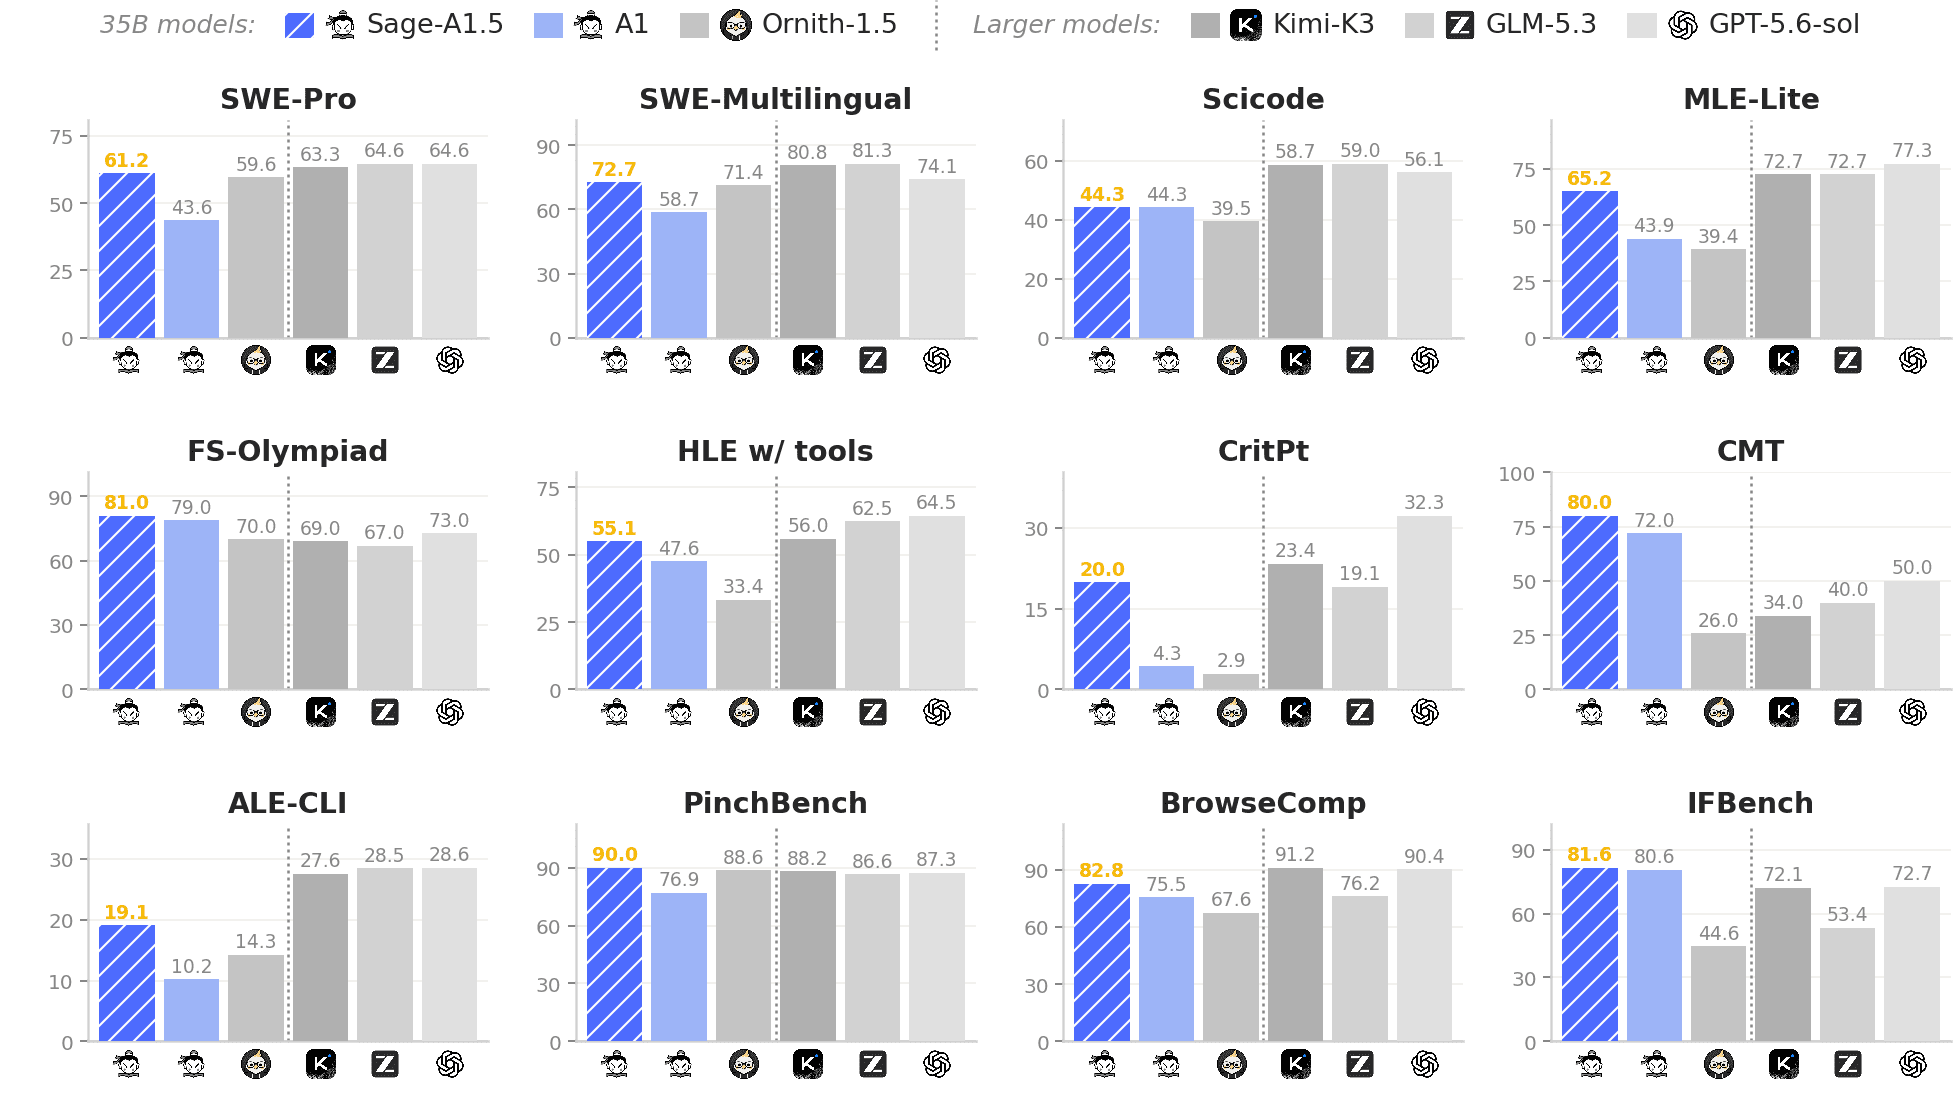
Sage-A1.5 Brings Agentic Vision to Open MoE Models
InclusionAI's new mixture-of-experts model pairs visual understanding with tool use and code, aiming at agentic workflows under an Apache 2.0 license.
More in Reasoning
All Reasoning →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
Meta's Muse Spark Open Targets Agentic Coding
The new open-weight model pairs a million-token context window with Meta's bet on long-horizon coding agents.
Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
0 comments
No comments yet. Be the first to weigh in.