Tencent Previews Hunyuan Hy4, an Apache MoE Model
The company's next-generation Hunyuan language model arrives as an early preview with a permissive license and a mixture-of-experts design.

Tencent has quietly posted an early preview of its next-generation Hunyuan language model, Hy4-preview, on Hugging Face. The release marks the debut of the v4 line and arrives under the permissive Apache 2.0 license, which allows commercial use and modification without the restrictions that accompany many large open-weight models.
The model uses a mixture-of-experts (MoE) architecture and is positioned for both general text generation and reasoning tasks. Tencent has not published parameter counts, context-length figures, or benchmark numbers in the preview listing, so the model's exact scale and capabilities remain to be detailed.
Why it matters
MoE designs have become the dominant approach for scaling large models efficiently, activating only a subset of parameters per token to keep inference costs manageable. A permissively licensed preview from Tencent adds another serious entrant to a field where Chinese labs — including Alibaba's Qwen and DeepSeek — have been shipping increasingly capable open weights.
A few things worth noting about this release:
- It is an explicit preview, suggesting a fuller v4 launch may follow with more documentation.
- The Apache 2.0 license is unusually permissive for a flagship model line.
- Key specifications are still absent, so independent evaluation will have to wait.
For now, developers can inspect the weights and configuration directly on the Hugging Face repository, though those hoping for official benchmarks or a technical report will need to wait for Tencent to say more about how Hy4 compares to its predecessors and rivals.
Sources
- Visit
tencent/Hy4-preview
Hugging Face
More from Tencent
All Tencent releases →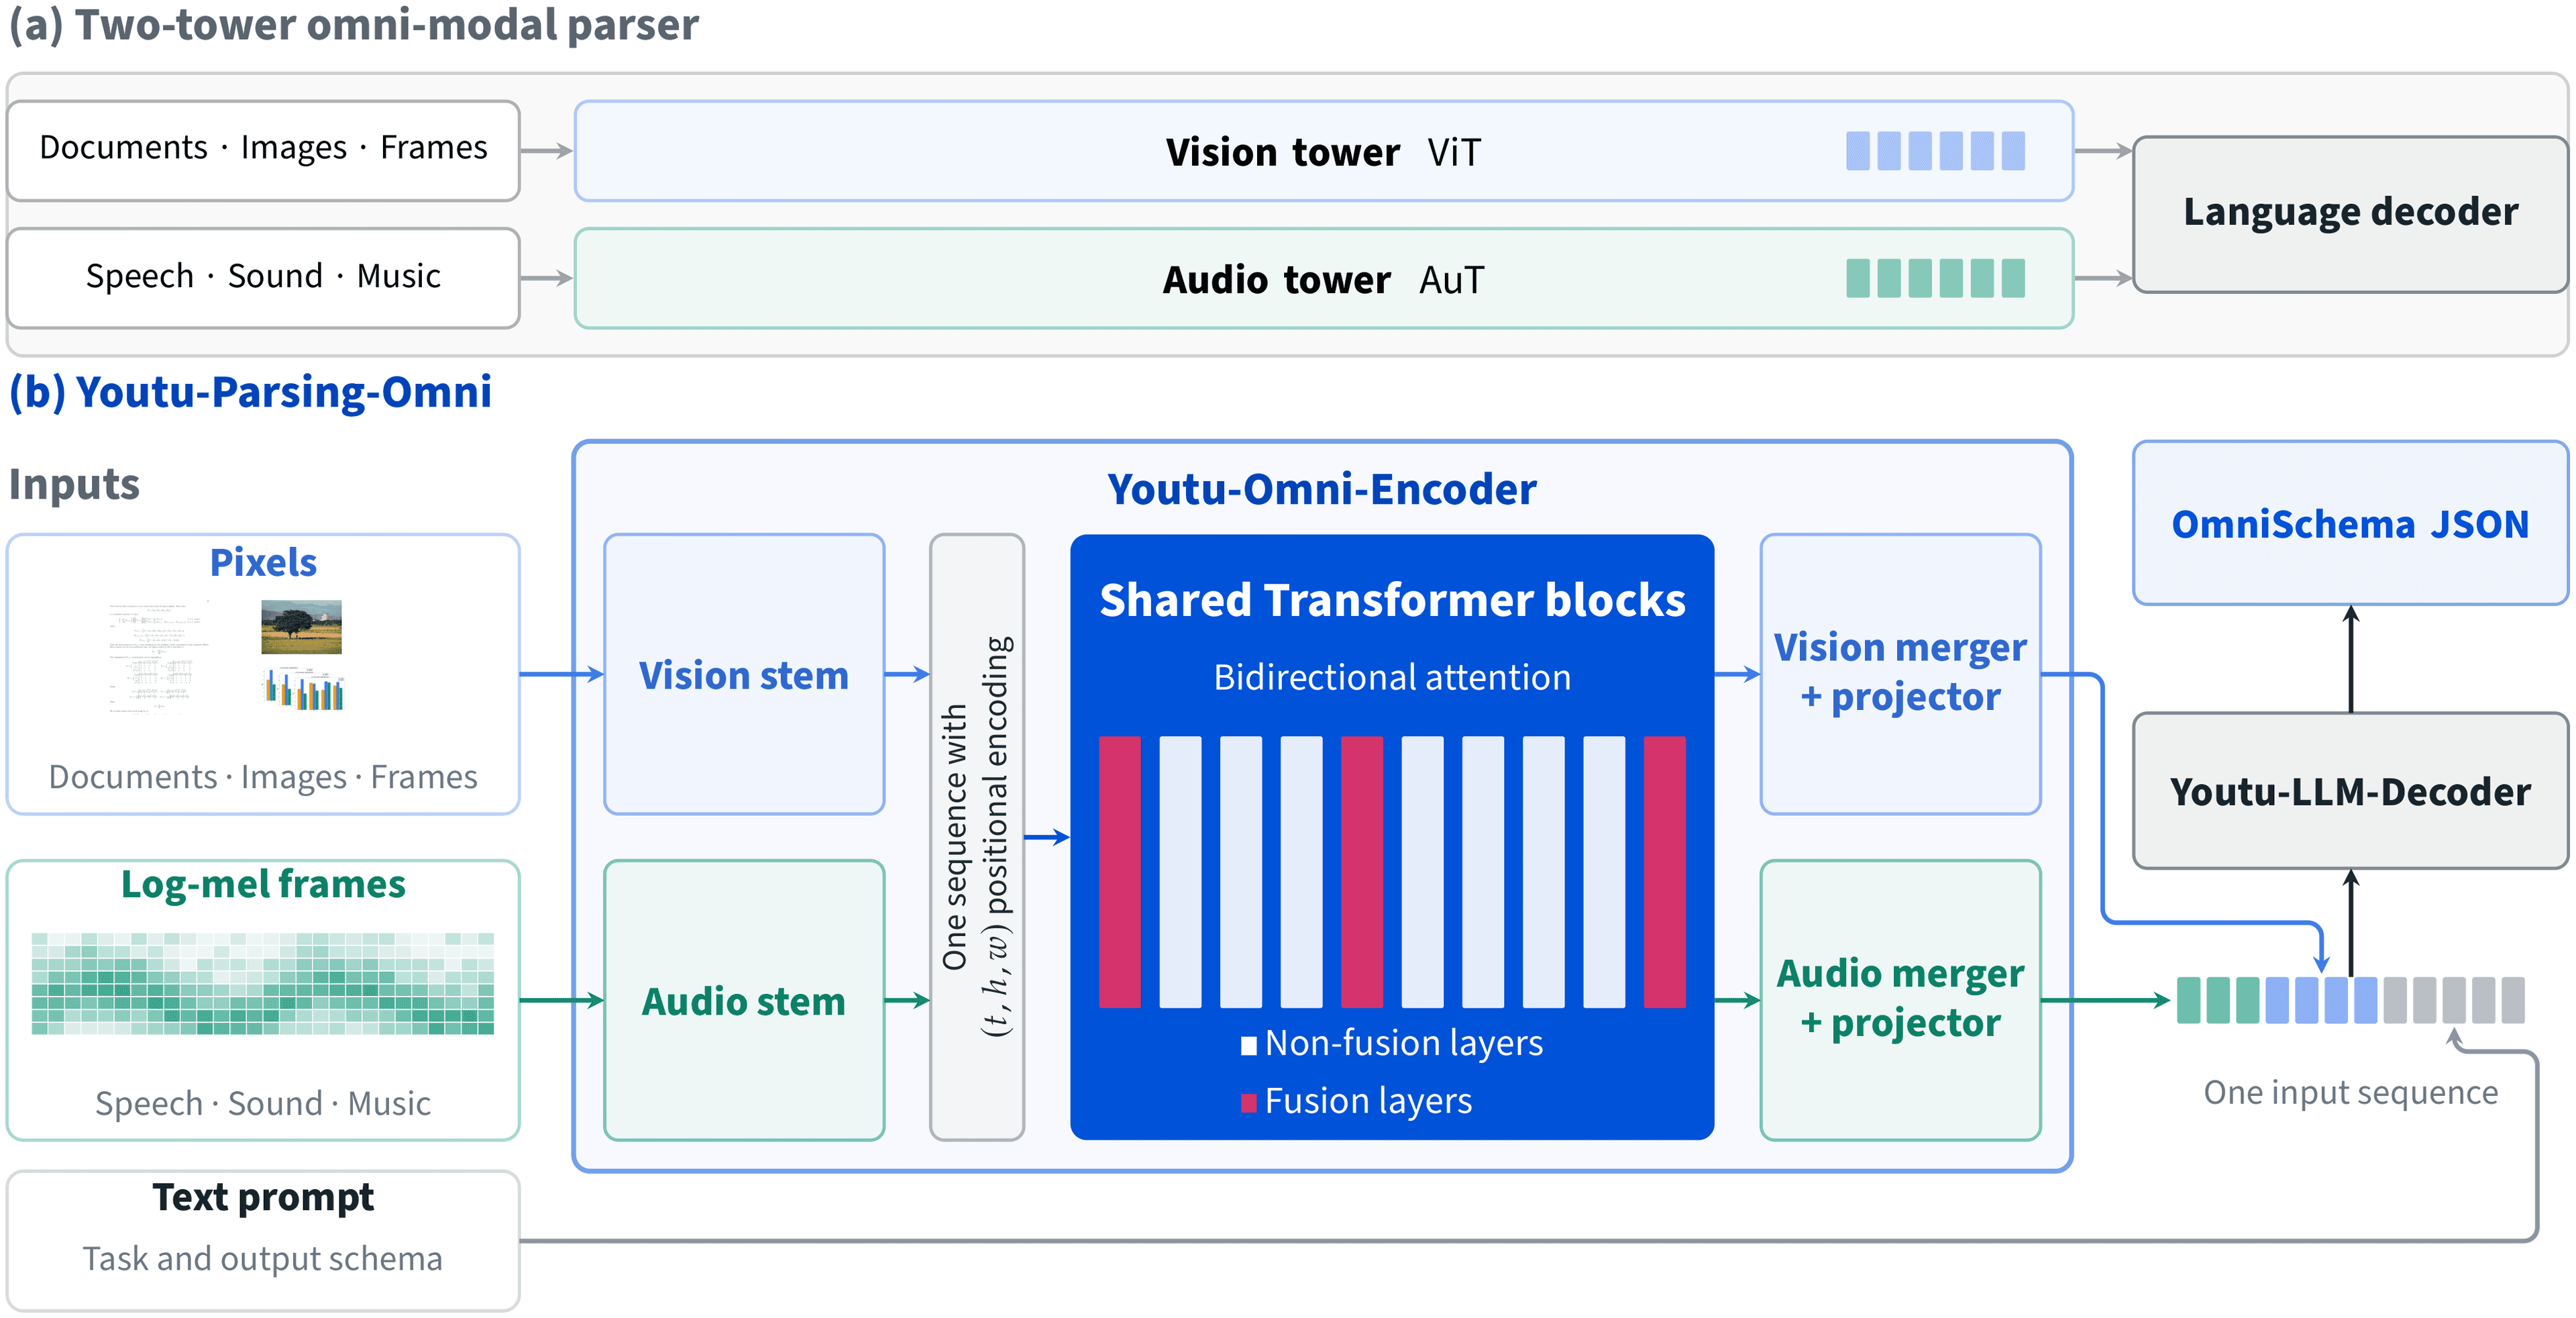
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Tencent's T1 Targets Long-Horizon Terminal Work
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.
Tencent's WeMM-Embedding-9B Unifies Text, Image and Video
The WeChat team releases a 9-billion-parameter multimodal embedding model that maps three modalities into one shared vector space.
More in Text / LLM
All Text / LLM →Mistral Large 4 arrives as a trillion-param MoE
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
Falcon-Emirati tunes an LLM for local dialect
TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.
Reflection AI debuts Beam, a 501B open model
The startup's first open-weight release is a dense 501-billion-parameter model aimed at text and reasoning tasks.
0 comments
No comments yet. Be the first to weigh in.