JD.com Enters Open-Source AI Video with JoyAI-Echo
The Chinese e-commerce giant has released a new model capable of generating long-form, multi-shot videos with synchronized audio from text prompts.
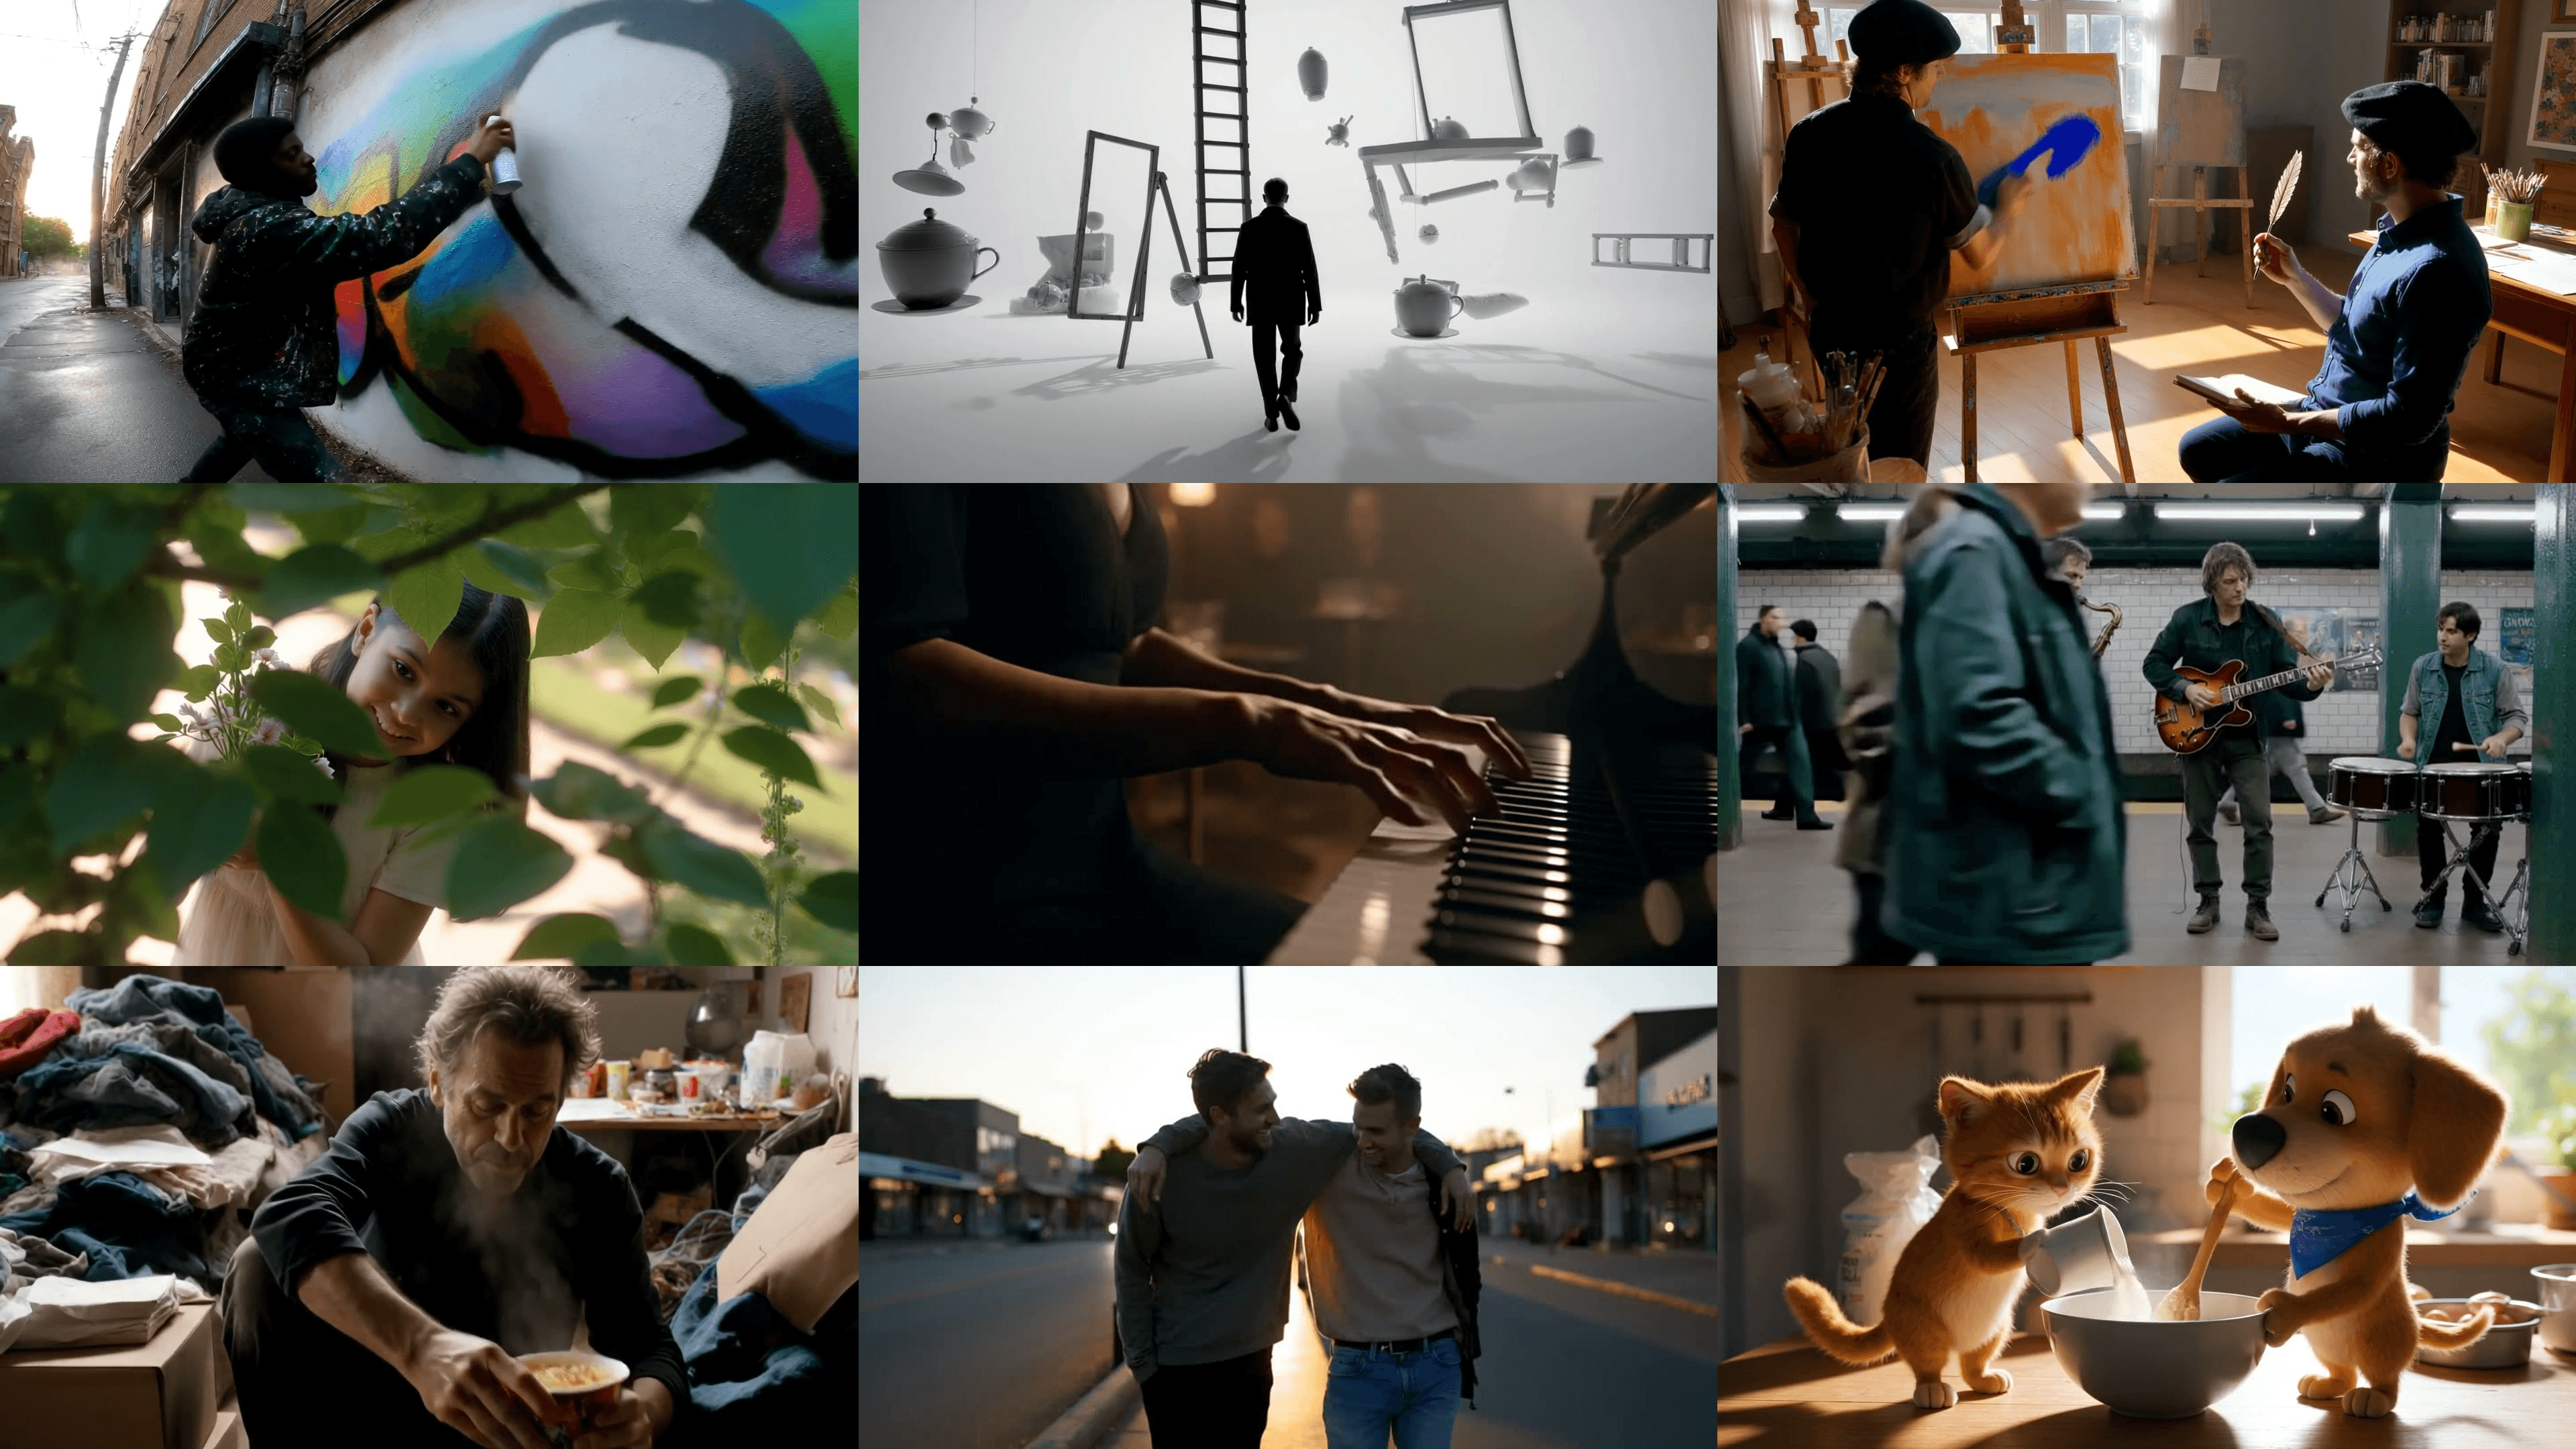
Chinese e-commerce company JD.com has released JoyAI-Echo, a new open-source model for generating video from text. The release marks the company's entry into the competitive field of open-source generative video, adding another major corporate player to the ecosystem.
Unlike many models that produce short, single clips, JoyAI-Echo is designed for creating "long-form, multi-shot" videos. This allows it to generate a sequence of related scenes that can form a more coherent narrative. Crucially, the model also generates synchronized audio to accompany the video, a feature still emerging in many open video tools.
The model is based on the LTX-Video research framework, which focuses on generating temporally consistent and longer video sequences. The full model, code, and weights are available on its Hugging Face repository under an Apache 2.0 license, which permits commercial use.
JoyAI-Echo’s release highlights the growing trend of moving beyond simple clip generation toward more practical, narrative-driven video creation. Its focus on multi-shot storytelling and integrated audio pushes the capabilities of what's available in open-source AI, offering a new tool for creators and researchers exploring long-form generative content.
Sources
- Visit
jdopensource/JoyAI-Echo
Hugging Face
More from JD
All JD releases →
JD.com Releases Open-Source Bilingual Image Editor
The new JoyAI-Image-Edit model allows for instruction-based photo manipulation in both English and Chinese under a permissive Apache 2.0 license.
More in Text → Video
All Text → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
0 comments
No comments yet. Be the first to weigh in.