Microsoft's FastContext is a 4B sub-agent for code
A compact Qwen3-derived model built to explore repositories, released under a permissive MIT license.
Microsoft has published FastContext 1.0 4B SFT, a small language model designed to act as a repository-exploration sub-agent. Rather than a general-purpose assistant, it is tuned for the narrower job of navigating and gathering context from codebases—the kind of grunt work that larger orchestrating models can offload to a cheaper helper.
The model is a supervised fine-tune of Qwen3-4B, weighing in at roughly four billion parameters. That size is deliberate: a 4B model is light enough to run cheaply and quickly, which matters when its role is to be called repeatedly inside a larger agent pipeline.
Why it matters
The interesting signal here is architectural, not benchmark-driven. As coding agents mature, the field is increasingly splitting tasks across specialized models instead of routing everything through one expensive frontier system.
- It targets a specific function—context retrieval across repositories—rather than broad chat.
- It builds on an open Qwen3 base, continuing the pattern of vendors fine-tuning each other's weights.
- It ships under the permissive MIT license, leaving developers free to adapt and deploy it.
Details such as context length and evaluation results are sparse at launch, so the model's real-world usefulness as a sub-agent will be judged by the teams who wire it into their own toolchains. For now, it is a small, openly licensed building block aimed squarely at agentic coding workflows.
Sources
- Visit
microsoft/FastContext-1.0-4B-SFT
Hugging Face
More from Microsoft
All Microsoft releases →
Microsoft Releases FrogNano-4B Under MIT License
The compact 4-billion-parameter text model lands on Hugging Face with a permissive license aimed at developers.
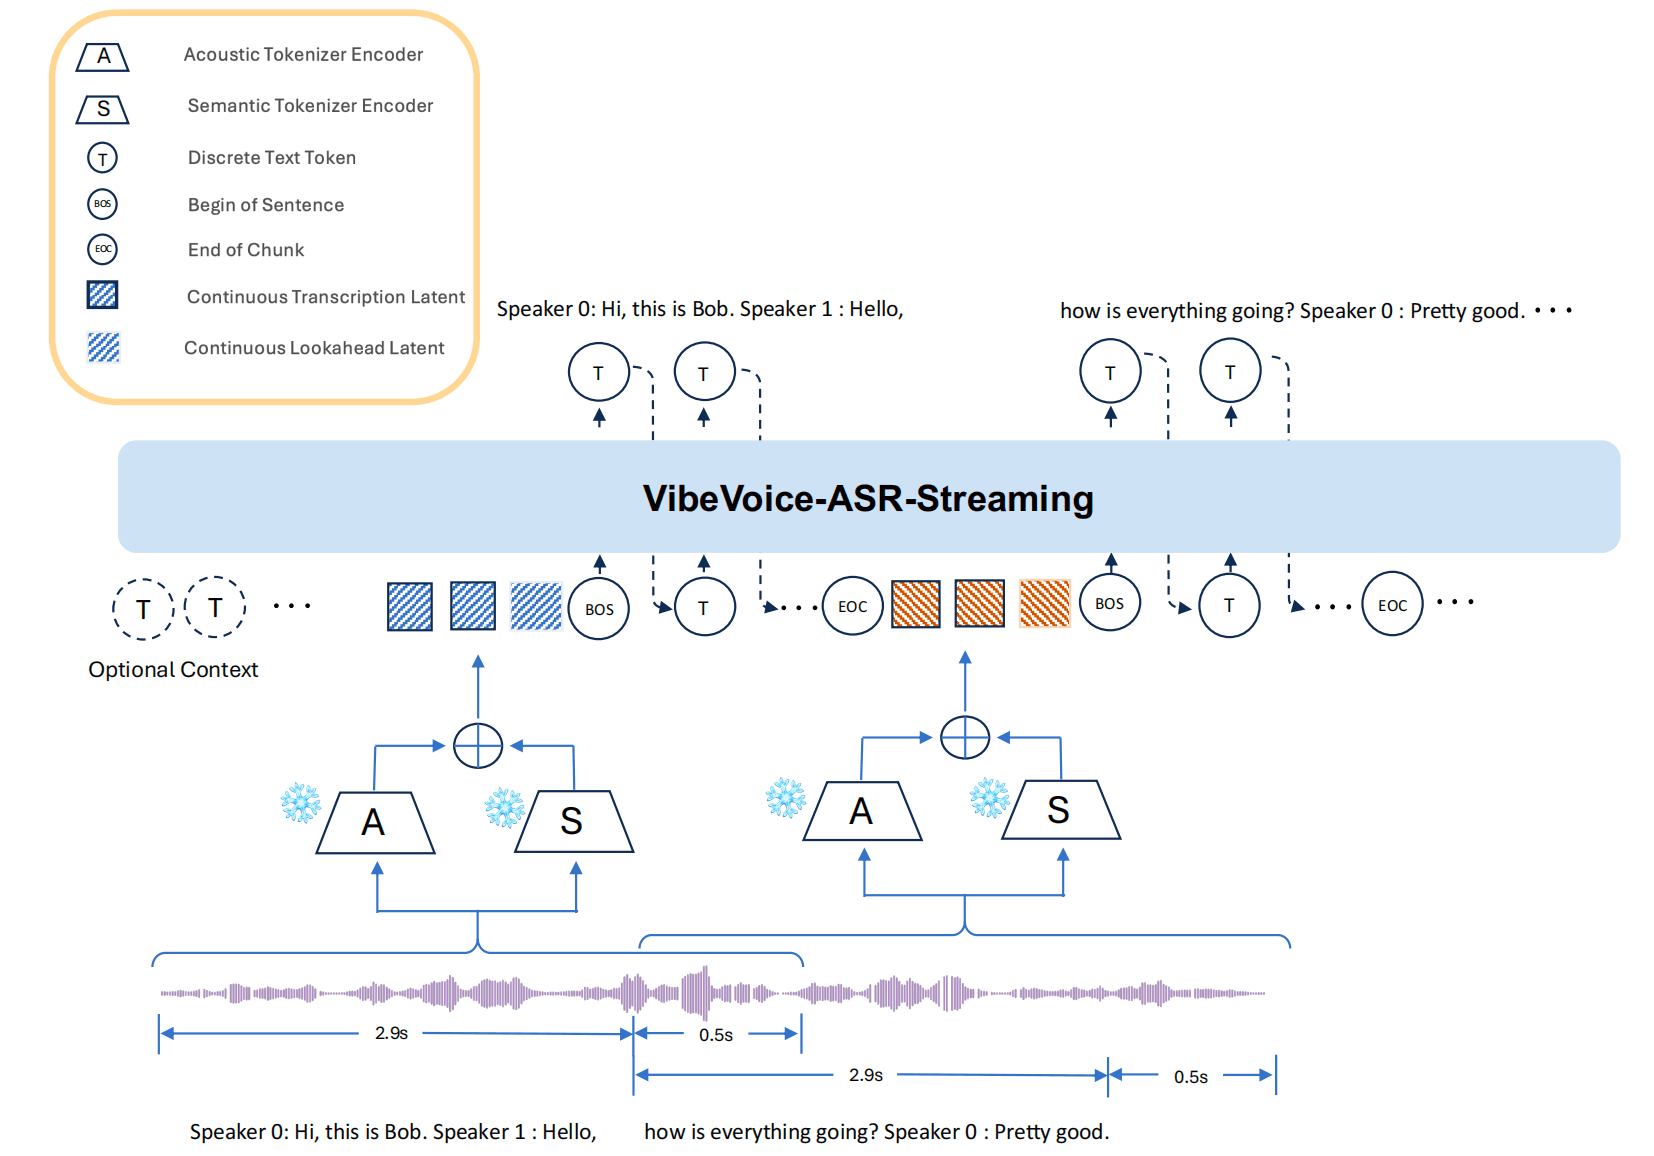
Microsoft's VibeVoice ASR brings streaming speech-to-text
A 7-billion-parameter model targets real-time, multilingual transcription with an open release on Hugging Face.
Microsoft's Mage-VL Streams Video Natively
A codec-native multimodal foundation model aims to understand live video and vision-language input in real time.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.