DeepSeek Announces V4.1 Flash, a Cheaper Reasoning Model
The new mixture-of-experts model is billed as more capable than V4 Pro while costing less to run, and ships under an MIT license.
DeepSeek has announced V4.1 Flash, a new text-and-reasoning model that the company positions as both cheaper and more capable than its V4 Pro tier. The news surfaced through a Hacker News discussion, where the pitch centered on a familiar DeepSeek theme: pushing the price-performance frontier rather than chasing raw scale.
The model uses a mixture-of-experts (MoE) architecture, the same approach that has defined DeepSeek's recent releases and helped it keep inference costs down by activating only a fraction of its parameters per token. DeepSeek has not yet published detailed specifications — parameter counts, active parameters, and context length remain unconfirmed at announcement.
Why it matters
DeepSeek has built its reputation on making frontier-adjacent capability affordable, and a "Flash" variant that reportedly beats the heavier "Pro" model would continue that pattern. A few reasons this release is worth watching:
- It carries an MIT license, keeping the model firmly in open-weights territory for developers and companies.
- It targets reasoning workloads, an area where cost per token matters enormously.
- Undercutting its own Pro tier signals aggressive internal competition on efficiency.
For now, the announcement is early and light on hard numbers. The claims of lower cost and higher capability will need independent benchmarks and published weights to verify, but if they hold, V4.1 Flash could reset expectations for what a budget reasoning model can deliver.
Sources
More from DeepSeek
All DeepSeek releases →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.

DeepSeek adds vision to its V4 Flash line
An experimental, MIT-licensed vision-language model brings image understanding to DeepSeek's fast V4 Flash architecture.
DeepSeek Releases V4-Pro-0813 With Open Weights
The Chinese lab pushes a higher-capability checkpoint of its V4 line to Hugging Face under a permissive MIT license.
More in Text / LLM
All Text / LLM →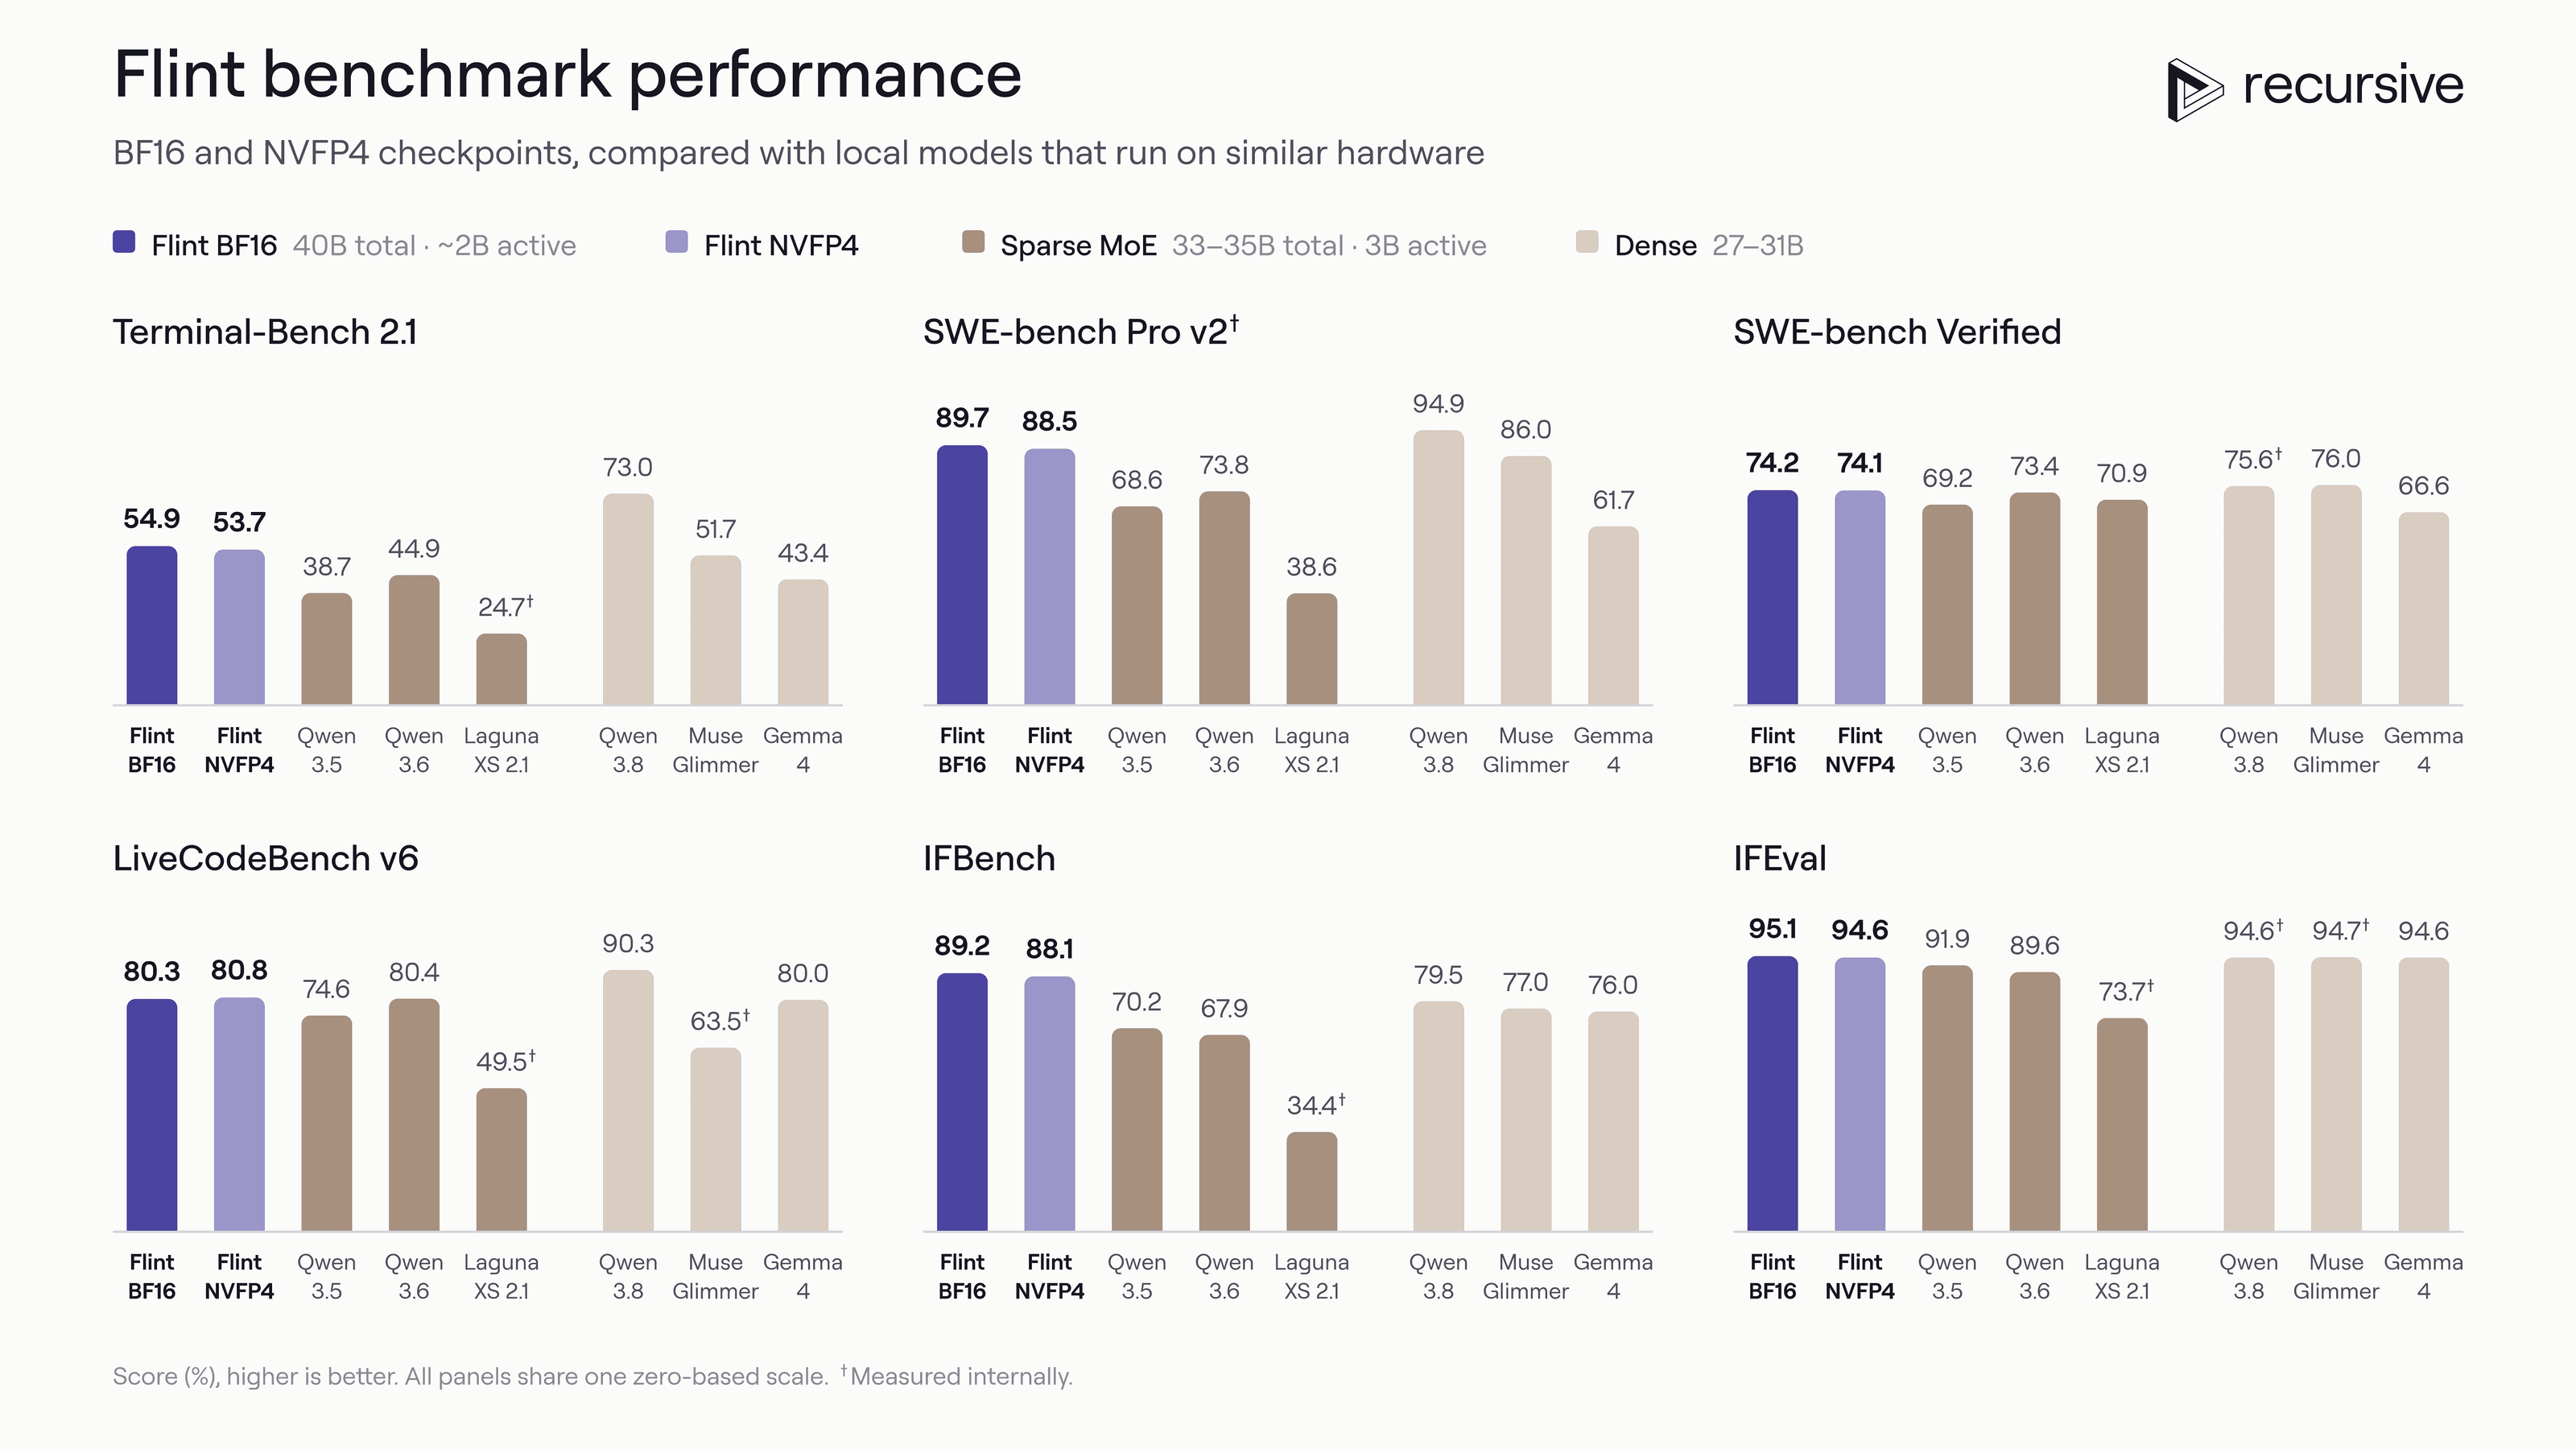
Recursive releases Flint, an Apache-2.0 chat model
The new conversational LLM ships under a permissive license with community GGUF builds already available for local use.
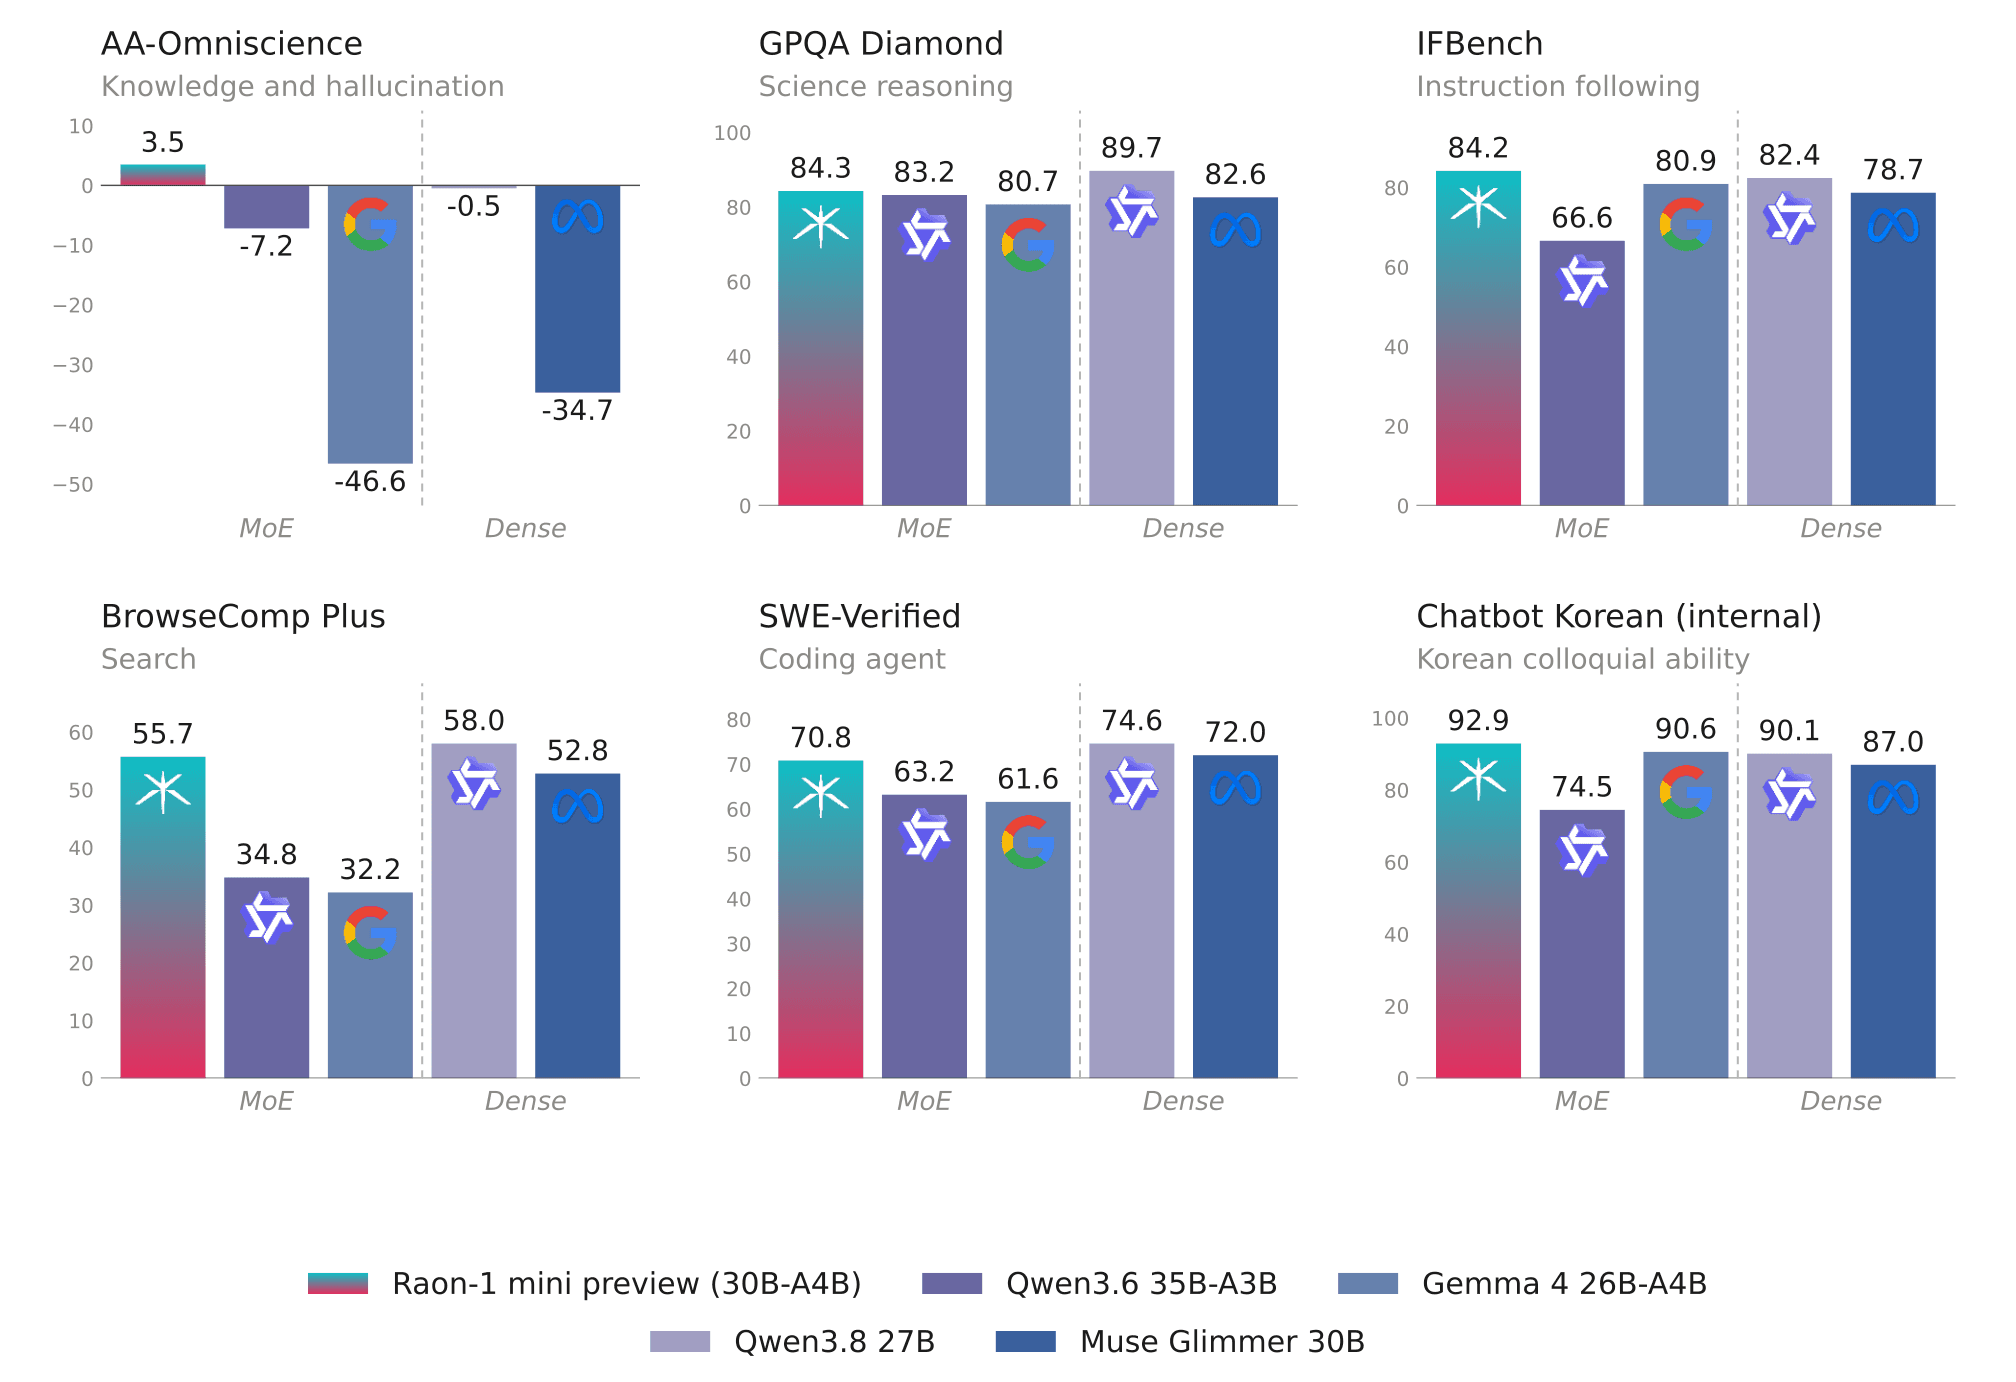
KRAFTON releases Raon-1-mini preview under Apache 2.0
The Korean game studio behind PUBG puts out a compact, permissively licensed language model as an early preview.
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
0 comments
No comments yet. Be the first to weigh in.