Qwen Teases 3.8-Flash-Next, a 125B Sparse MoE
Alibaba's next Qwen release pairs a large parameter pool with a tiny active footprint, promising speed without the full compute bill.
Alibaba's Qwen team is preparing to ship Qwen3.8-Flash-Next, a mixture-of-experts model listed at 125 billion total parameters but activating only about 6 billion per token. The model is expected to land imminently on ModelScope, where its placeholder page has already surfaced ahead of the announcement.
The naming signals the design goal. "Flash" points to inference speed, and the sparse architecture backs that up: by routing each token through a small slice of its experts, the model aims to deliver the knowledge capacity of a large network while keeping the per-query compute closer to that of a much smaller dense model.
Why it matters
Sparse MoE has become the dominant strategy for teams trying to balance capability against serving cost, and Qwen has leaned into it repeatedly across its lineup. A 125B/6B split is aggressive on the efficiency side, which could make the model attractive for high-throughput deployments where latency and cost per token matter as much as raw quality.
A few things to keep in mind:
- The release is billed as covering both general text and reasoning workloads.
- It is expected under the permissive Apache 2.0 license, consistent with Qwen's open-weight track record.
- Context length and benchmark details have not yet been published.
As an announcement rather than a full launch, key specifics remain unconfirmed until weights and documentation go live. If the listed figures hold, though, Qwen3.8-Flash-Next would extend the family's push toward models that are cheap to run without giving up scale.
Sources
More from Qwen · Alibaba
All Qwen · Alibaba releases →
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
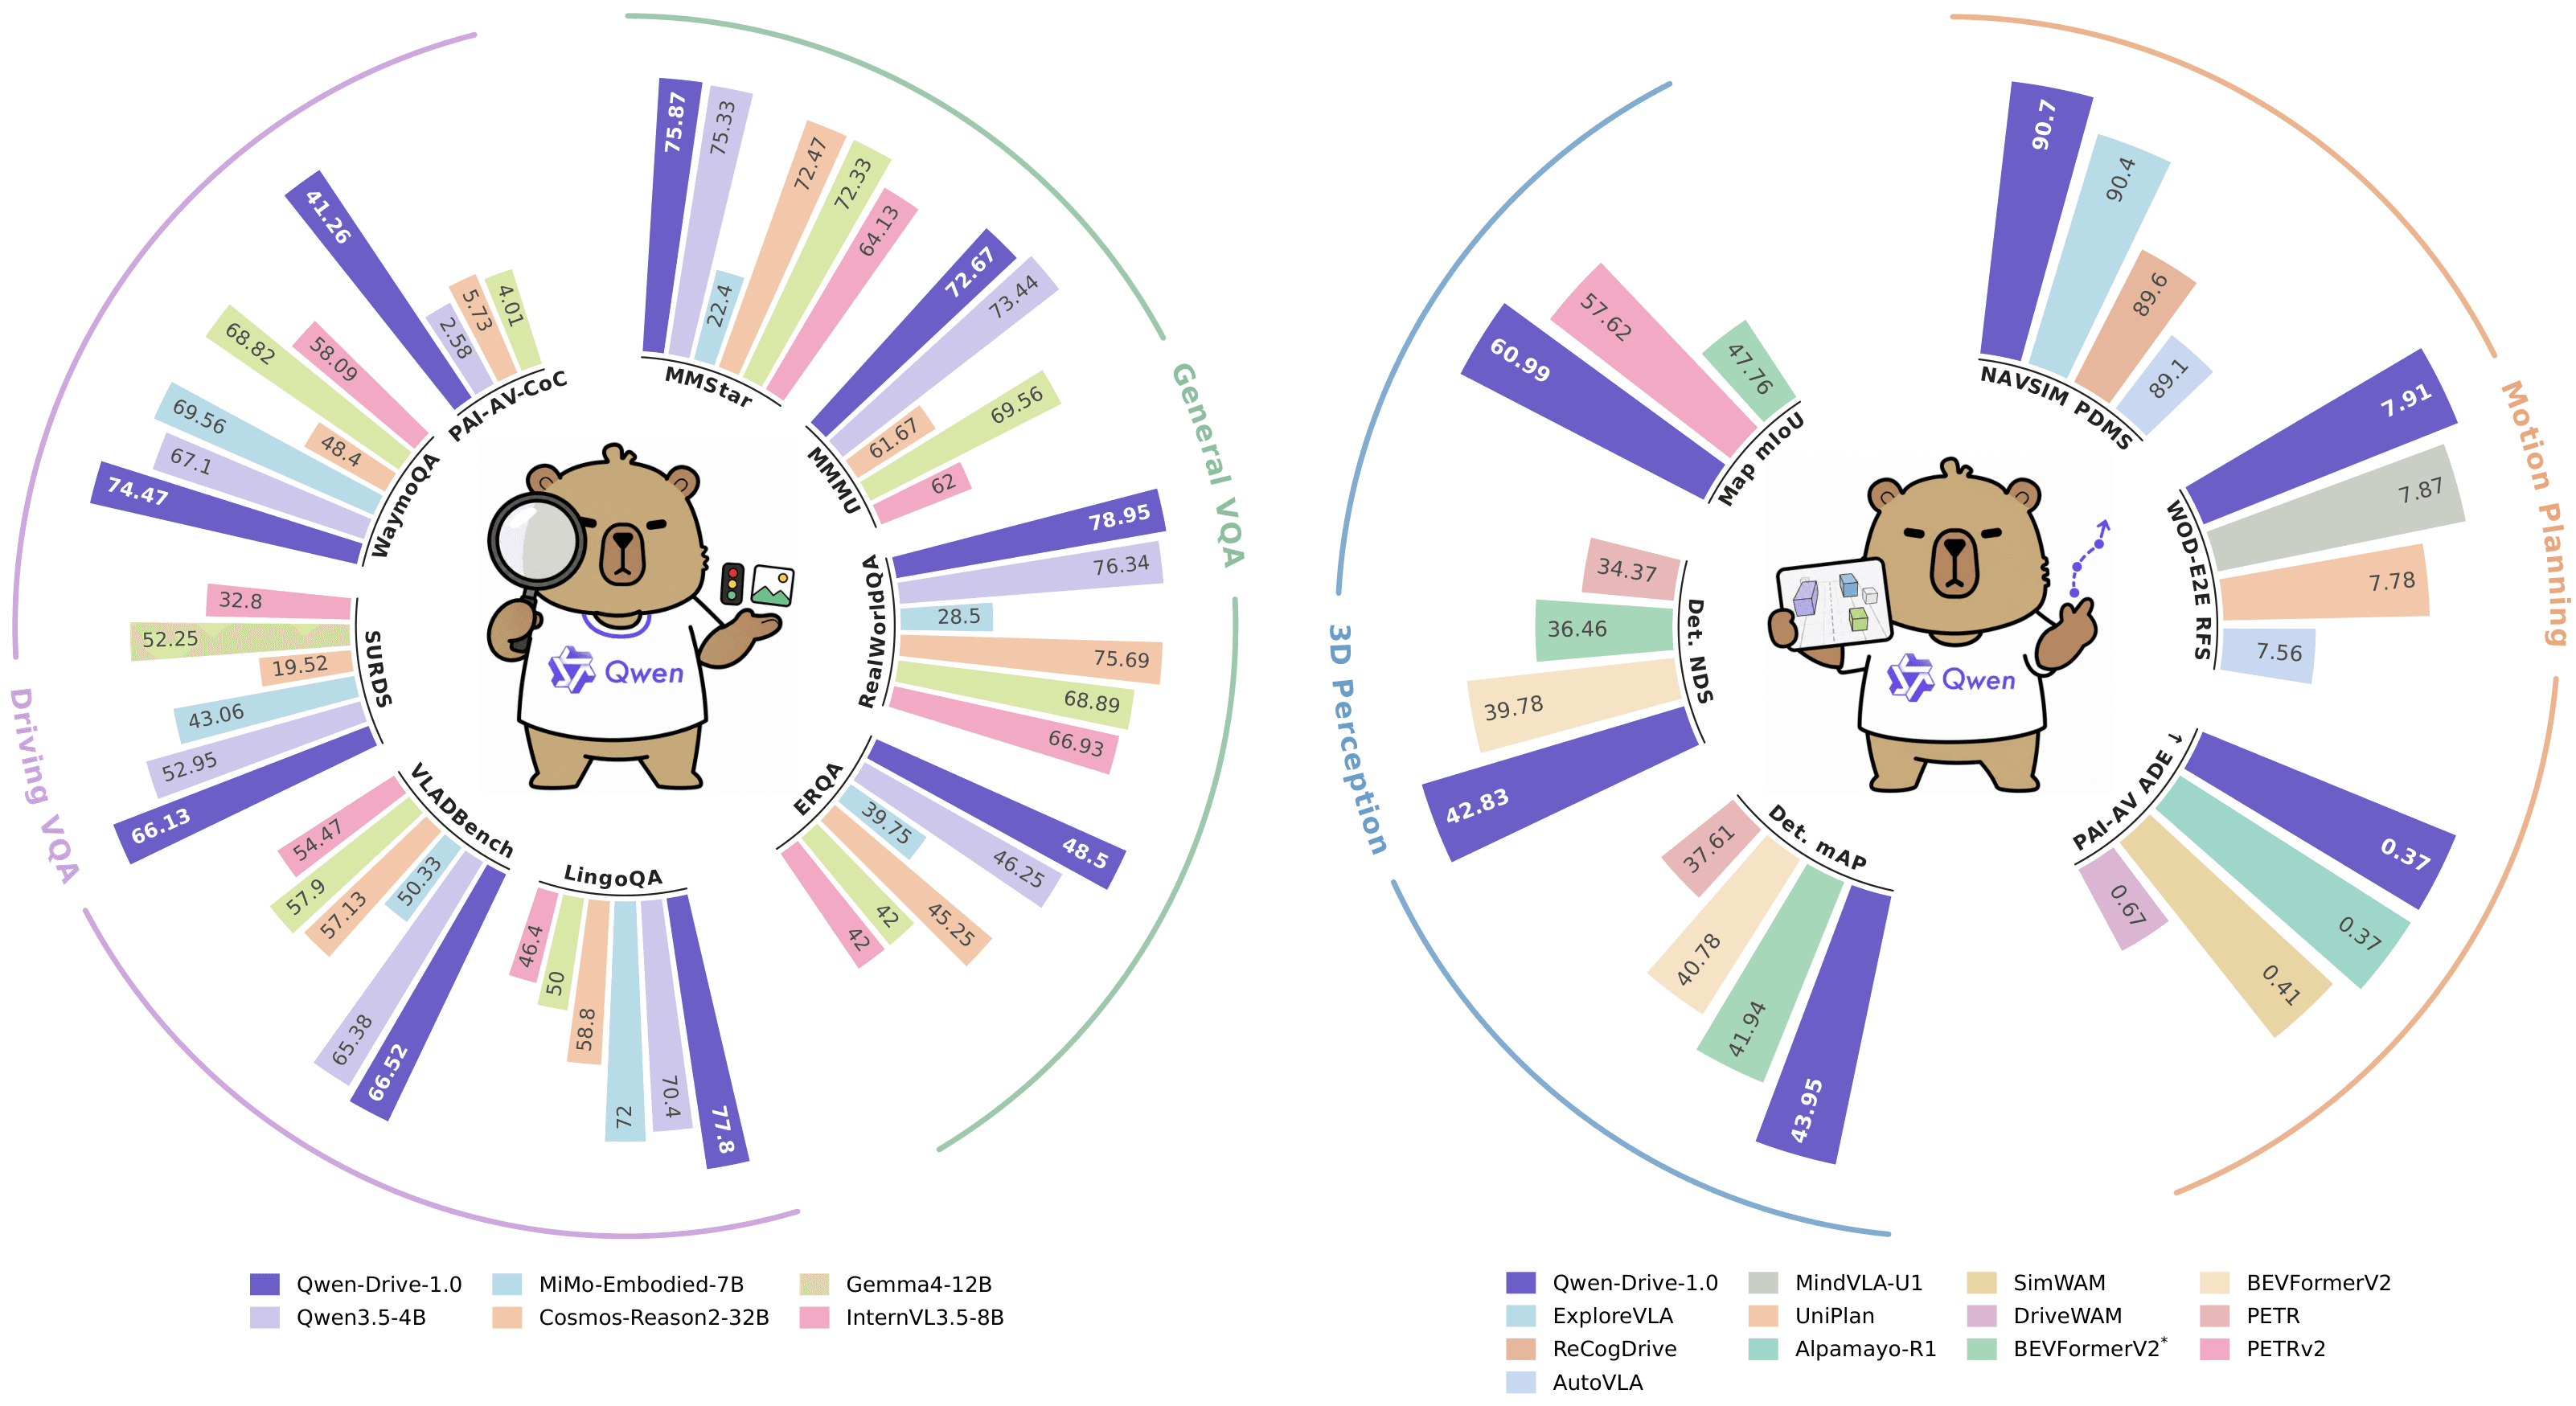
Qwen-Drive 1.0 targets autonomous driving with a 4B VLM
Alibaba's Qwen team brings its vision-language stack to the road with a compact model built for perception and motion planning.

Qwen releases 2.4T-parameter open MoE with 95B active
Alibaba's Qwen team pushes its largest sparse model yet, activating 95 billion parameters per token from a 2.4-trillion-parameter pool.
More in Text / LLM
All Text / LLM →Mistral Large 4 arrives as a trillion-param MoE
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
Falcon-Emirati tunes an LLM for local dialect
TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.
Reflection AI debuts Beam, a 501B open model
The startup's first open-weight release is a dense 501-billion-parameter model aimed at text and reasoning tasks.
0 comments
No comments yet. Be the first to weigh in.