XHToken releases Spark-X2.5, a 4B open LLM
The Apache-2.0 instruction-tuned model targets developers who want a small, permissively licensed text generator.
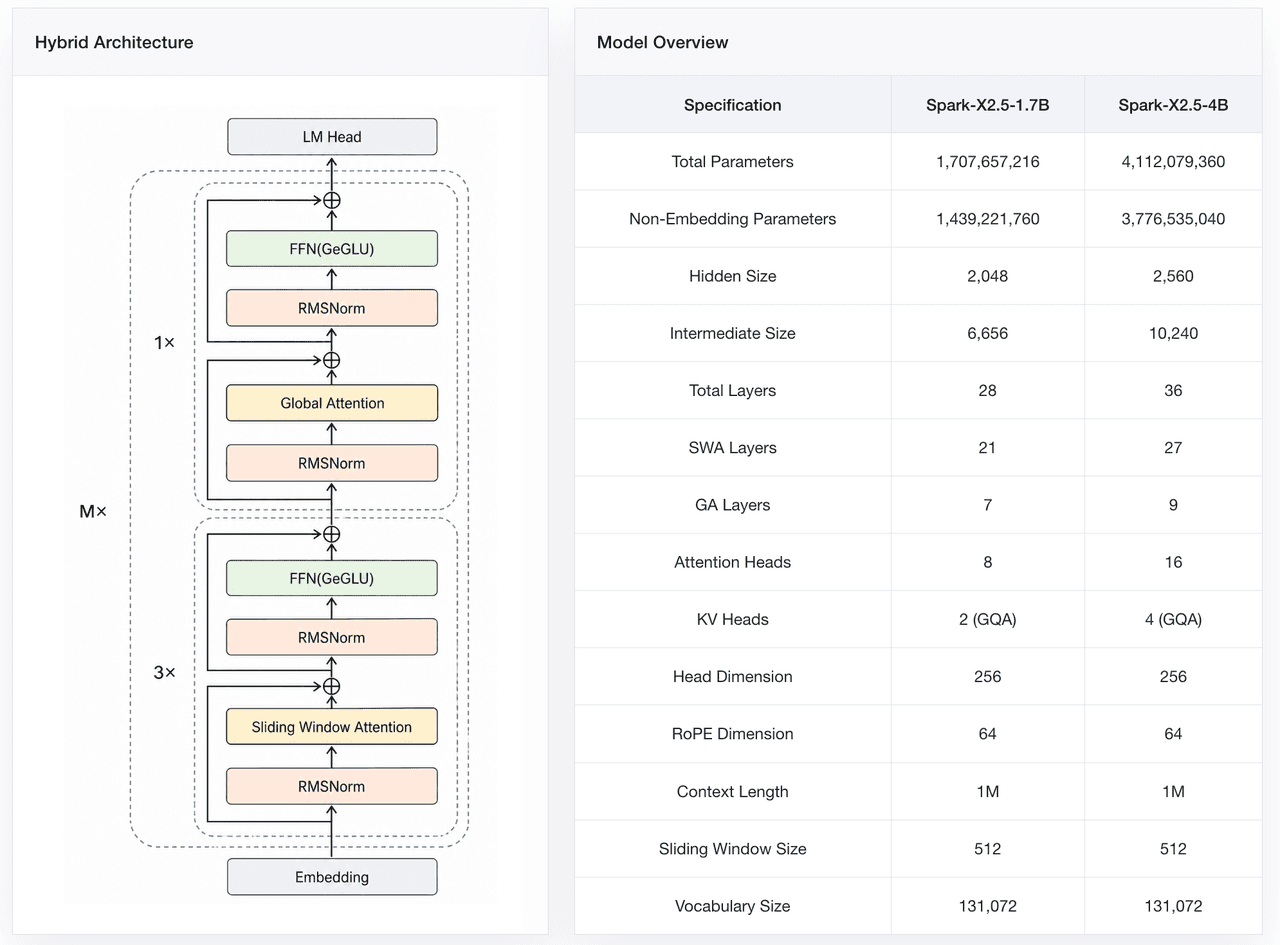
XHToken has published Spark-X2.5-4B, a four-billion-parameter instruction-tuned language model released under the permissive Apache-2.0 license. The model is available now on Hugging Face, where it is listed as a text-only, dense (non-MoE) system.
At 4B parameters, Spark-X2.5 sits in the increasingly crowded small-model tier, where compact instruction-tuned LLMs are prized for running on modest hardware, fine-tuning cheaply, and serving latency-sensitive applications. The Apache-2.0 terms are the notable detail here: they allow commercial use, modification, and redistribution with minimal friction, which matters to teams wary of the usage restrictions attached to some other open-weight releases.
What we know
- Roughly 4B parameters, dense architecture
- Instruction-tuned for chat and task following
- Apache-2.0 license, text-only modality
- Distributed via Hugging Face
The release record leaves several specifics unstated, including context length and benchmark results, so buyers will want to test the model against their own workloads before committing. As an initial entry in the Spark-X line, it establishes a baseline that future revisions can build on.
Why it matters: the value of a small model like this rests less on headline scores than on the combination of size and license. For developers who need a self-hostable, commercially usable 4B model, Spark-X2.5 is worth a look — and worth benchmarking carefully given how much the record leaves open.
Sources
- Visit
XHToken/Spark-X2.5-4B
Hugging Face
More in Text / LLM
All Text / LLM →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
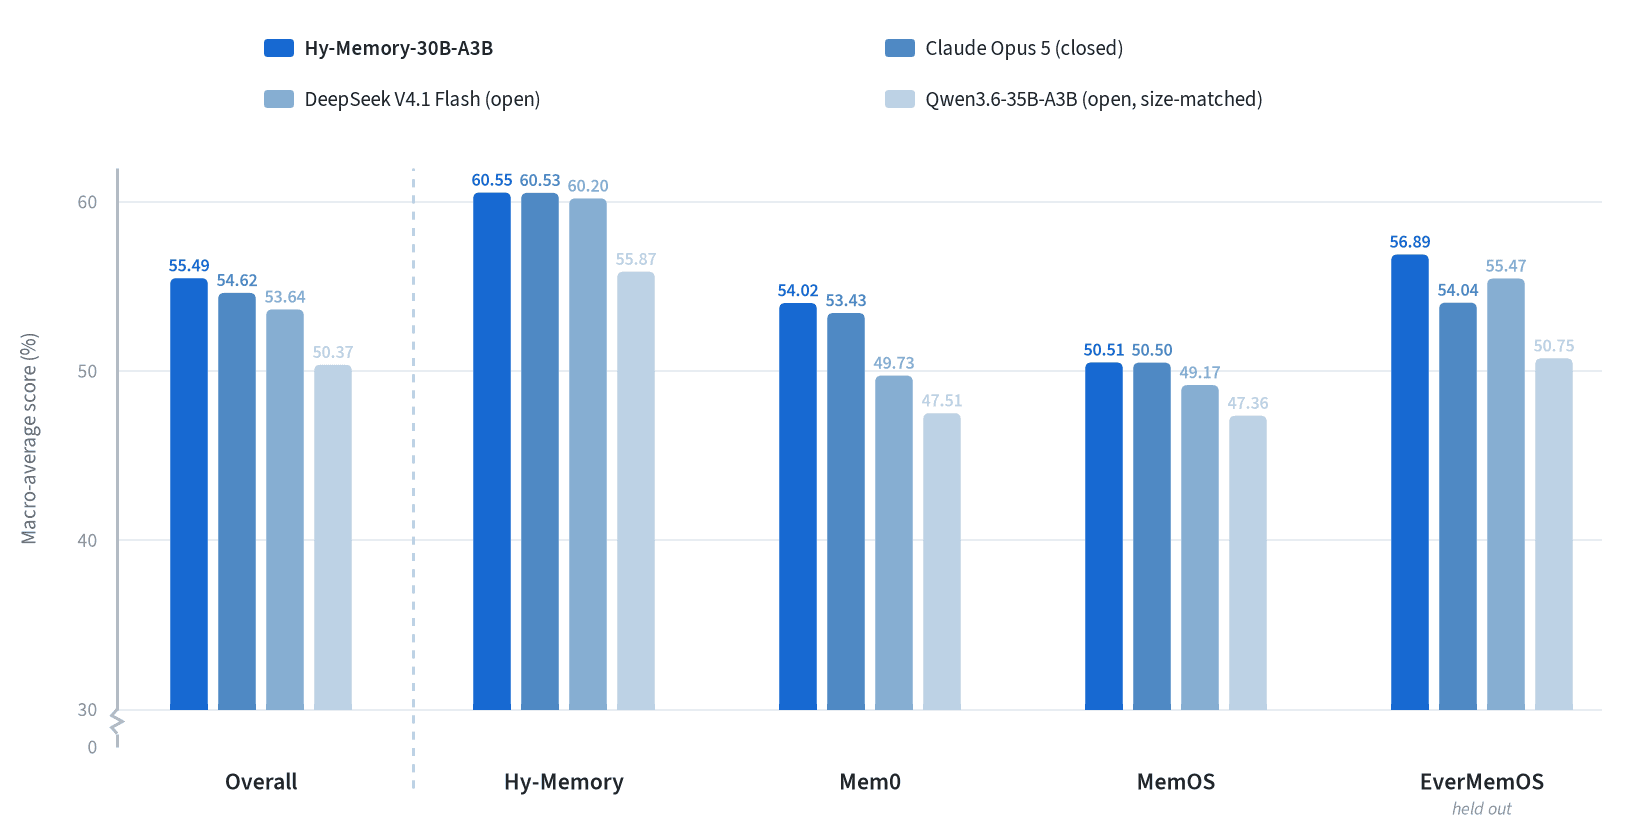
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
0 comments
No comments yet. Be the first to weigh in.