NVIDIA's PhoneLLM Targets Voice Agents on the Line
An early alpha release brings a Nemotron-H mixture-of-experts model tuned for phone-based tool use and function calling.
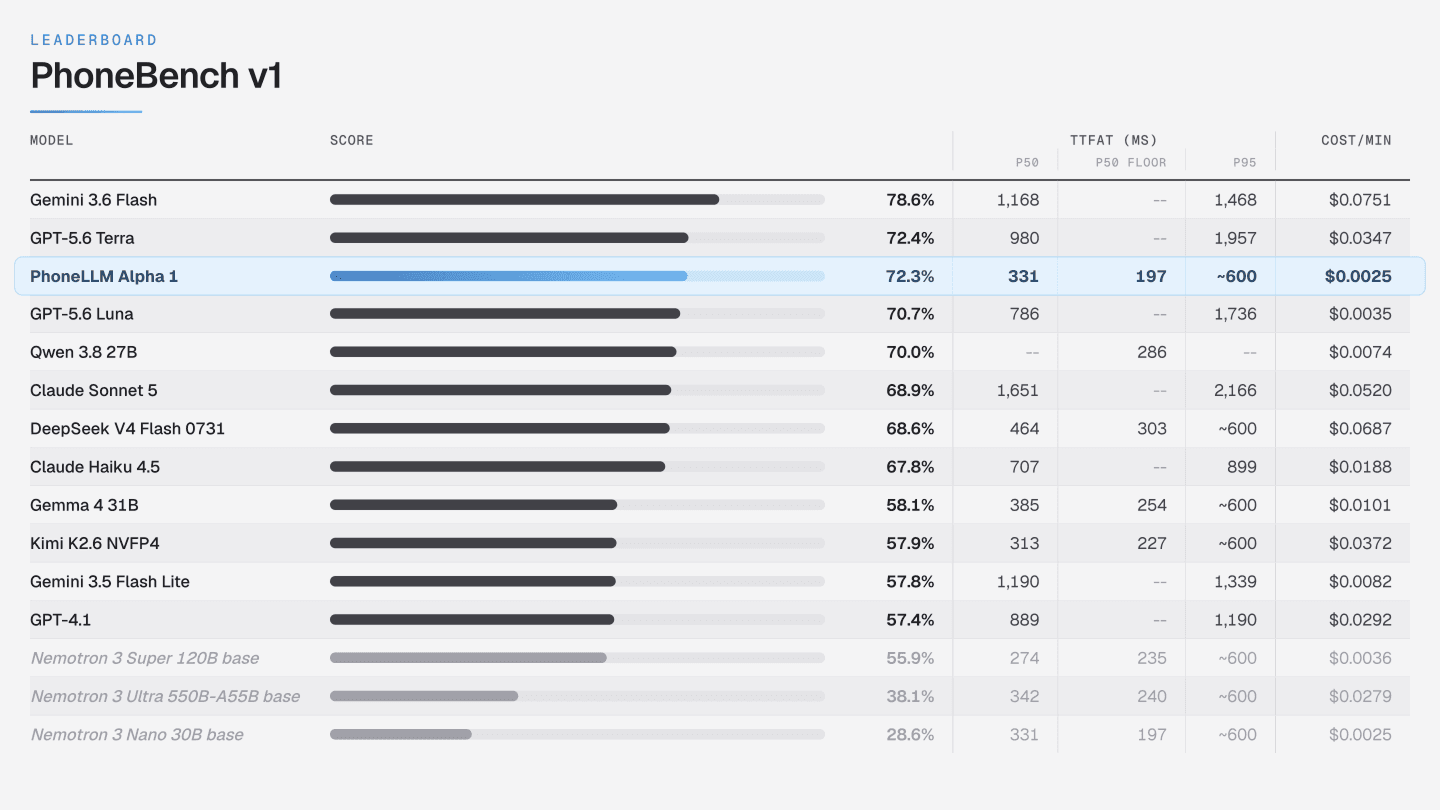
NVIDIA has quietly published PhoneLLM alpha-1, an early text model designed specifically for voice agents that answer and place phone calls. Released through the pipecat-ai organization on Hugging Face, it is built on the Nemotron-H architecture and uses a mixture-of-experts (MoE) design, with a focus on tool use and function calling.
The pipecat-ai connection is telling. Pipecat is an open framework for building real-time voice and multimodal agents, and a model tuned to slot into that pipeline suggests NVIDIA is thinking about the full stack — not just raw language capability, but the practical plumbing of a phone assistant that needs to check a calendar, look up an order, or trigger an action mid-conversation.
Why it matters
Phone-based voice agents place unusual demands on a language model. Latency has to stay low, responses need to be concise and speakable, and the model must reliably call external functions rather than hallucinate answers. A purpose-built model addresses those constraints more directly than adapting a general-purpose chatbot.
- Architecture: Nemotron-H, with a mixture-of-experts configuration
- Focus: tool use and function calling for phone applications
- Ecosystem: ships under the pipecat-ai org, aligning it with the Pipecat voice-agent framework
As an alpha, this is very much a work in progress — parameter counts, context length, and benchmark results aren't detailed in the release, and the license is listed simply as "other." Developers experimenting with voice agents will want to treat it as a preview rather than a production-ready component, but it's a clear signal of where NVIDIA sees conversational AI heading.
Sources
- Visit
pipecat-ai/phonellm-alpha-1
Hugging Face
More in Text / LLM
All Text / LLM →Mistral Large 4 arrives as a trillion-param MoE
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
Falcon-Emirati tunes an LLM for local dialect
TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.
Reflection AI debuts Beam, a 501B open model
The startup's first open-weight release is a dense 501-billion-parameter model aimed at text and reasoning tasks.
0 comments
No comments yet. Be the first to weigh in.