Qwen3.8-27B Brings Vision to a Dense Model
Alibaba's latest Qwen release pairs image understanding with text under a permissive Apache-2.0 license.
Alibaba's Qwen team has published Qwen3.8-27B, a 27-billion-parameter vision-language model that handles both conversational text and image understanding. It arrives under the permissive Apache-2.0 license, making it broadly usable in commercial and research settings.
Unlike the mixture-of-experts designs that have dominated recent large releases, Qwen3.8-27B is a dense model. That means all of its parameters are active on every forward pass — a simpler architecture that tends to be more predictable to serve and fine-tune, even if it trades away some of the efficiency gains MoE offers at larger scales.
What it offers
- Dense 27B parameters, positioned in the mid-size tier between smaller on-device models and frontier-scale systems
- Multimodal input: image-text-to-text alongside standard text chat
- Apache-2.0 licensing, which permits redistribution and commercial use
The combination is notable because open, permissively licensed vision-language models in this size range remain relatively scarce. A 27B dense VLM is large enough to be capable at document, chart, and image reasoning, yet small enough to run on a single high-memory GPU with quantization.
As with prior Qwen drops, the weights are available directly on Hugging Face. Details on context length and benchmark performance were not specified in the release record, so teams evaluating it should confirm those specifics against the model card before committing to production use.
Sources
- Visit
Qwen/Qwen3.8-27B
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
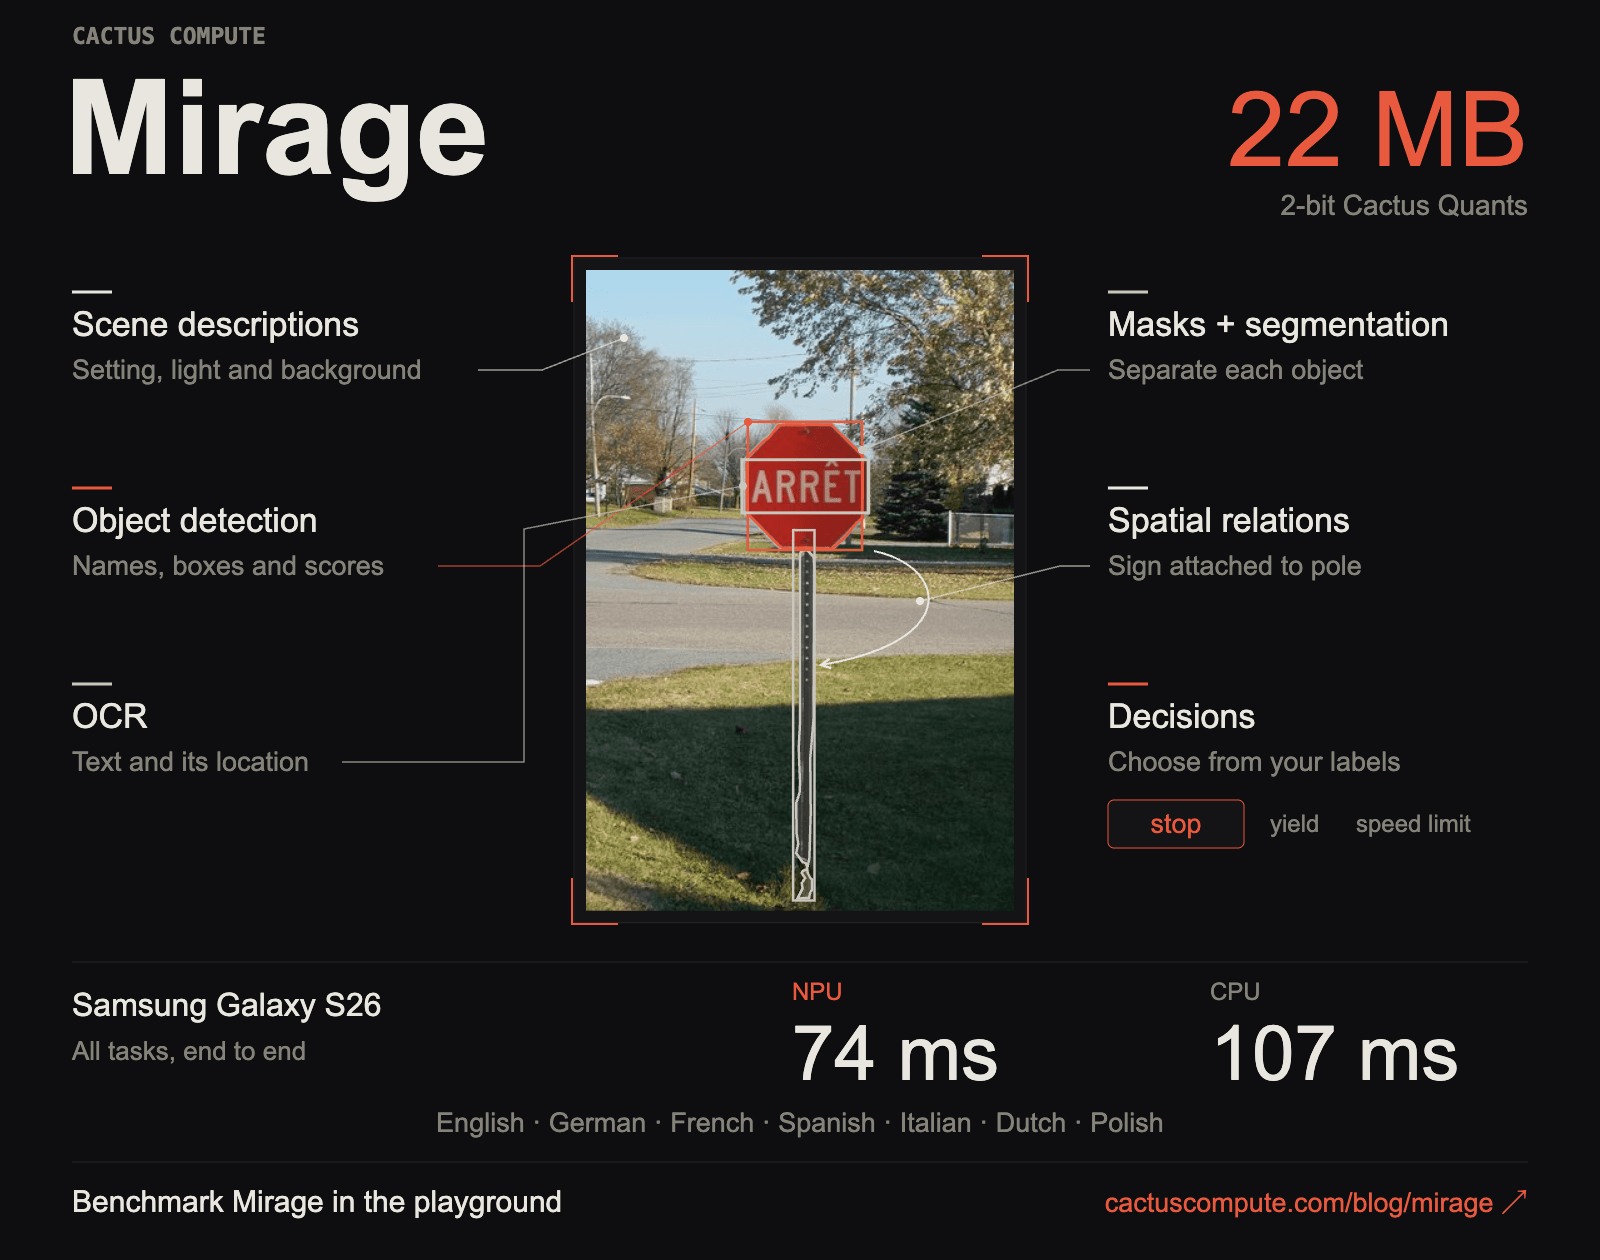
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
0 comments
No comments yet. Be the first to weigh in.