Zhipu AI Releases GLM-4.7-Flash MoE Model
The new Mixture-of-Experts model from the Beijing-based AI company is optimized for speed and released under the permissive MIT license.
Chinese AI firm Zhipu AI has released GLM-4.7-Flash, a new language model designed for high-speed inference. It employs a Mixture-of-Experts (MoE) architecture, a technique that allows models to scale up their parameter counts while keeping computational costs manageable during inference.
The 'Flash' in its name signals the model's primary goal: performance. MoE models achieve this by selectively activating only a fraction of their total parameters—the 'experts'—to process any given input. This makes them significantly faster and more efficient for real-time applications compared to dense models of a similar size.
A Permissive License for Commercial Use
Perhaps most notably for developers and businesses, GLM-4.7-Flash is available under the MIT license. This is one of the most permissive open-source licenses, imposing very few restrictions on reuse and allowing for broad commercial applications. This combination of an efficient architecture and a business-friendly license makes the model an attractive option for integration into products and services.
The model is the latest addition to Zhipu AI's GLM-4 family of models. While specific details on its total parameter count and context length have not been disclosed, developers can access the model weights and resources on its official Hugging Face repository.
Sources
- Visit
zai-org/GLM-4.7-Flash
Hugging Face
More from Zhipu AI
All Zhipu AI releases →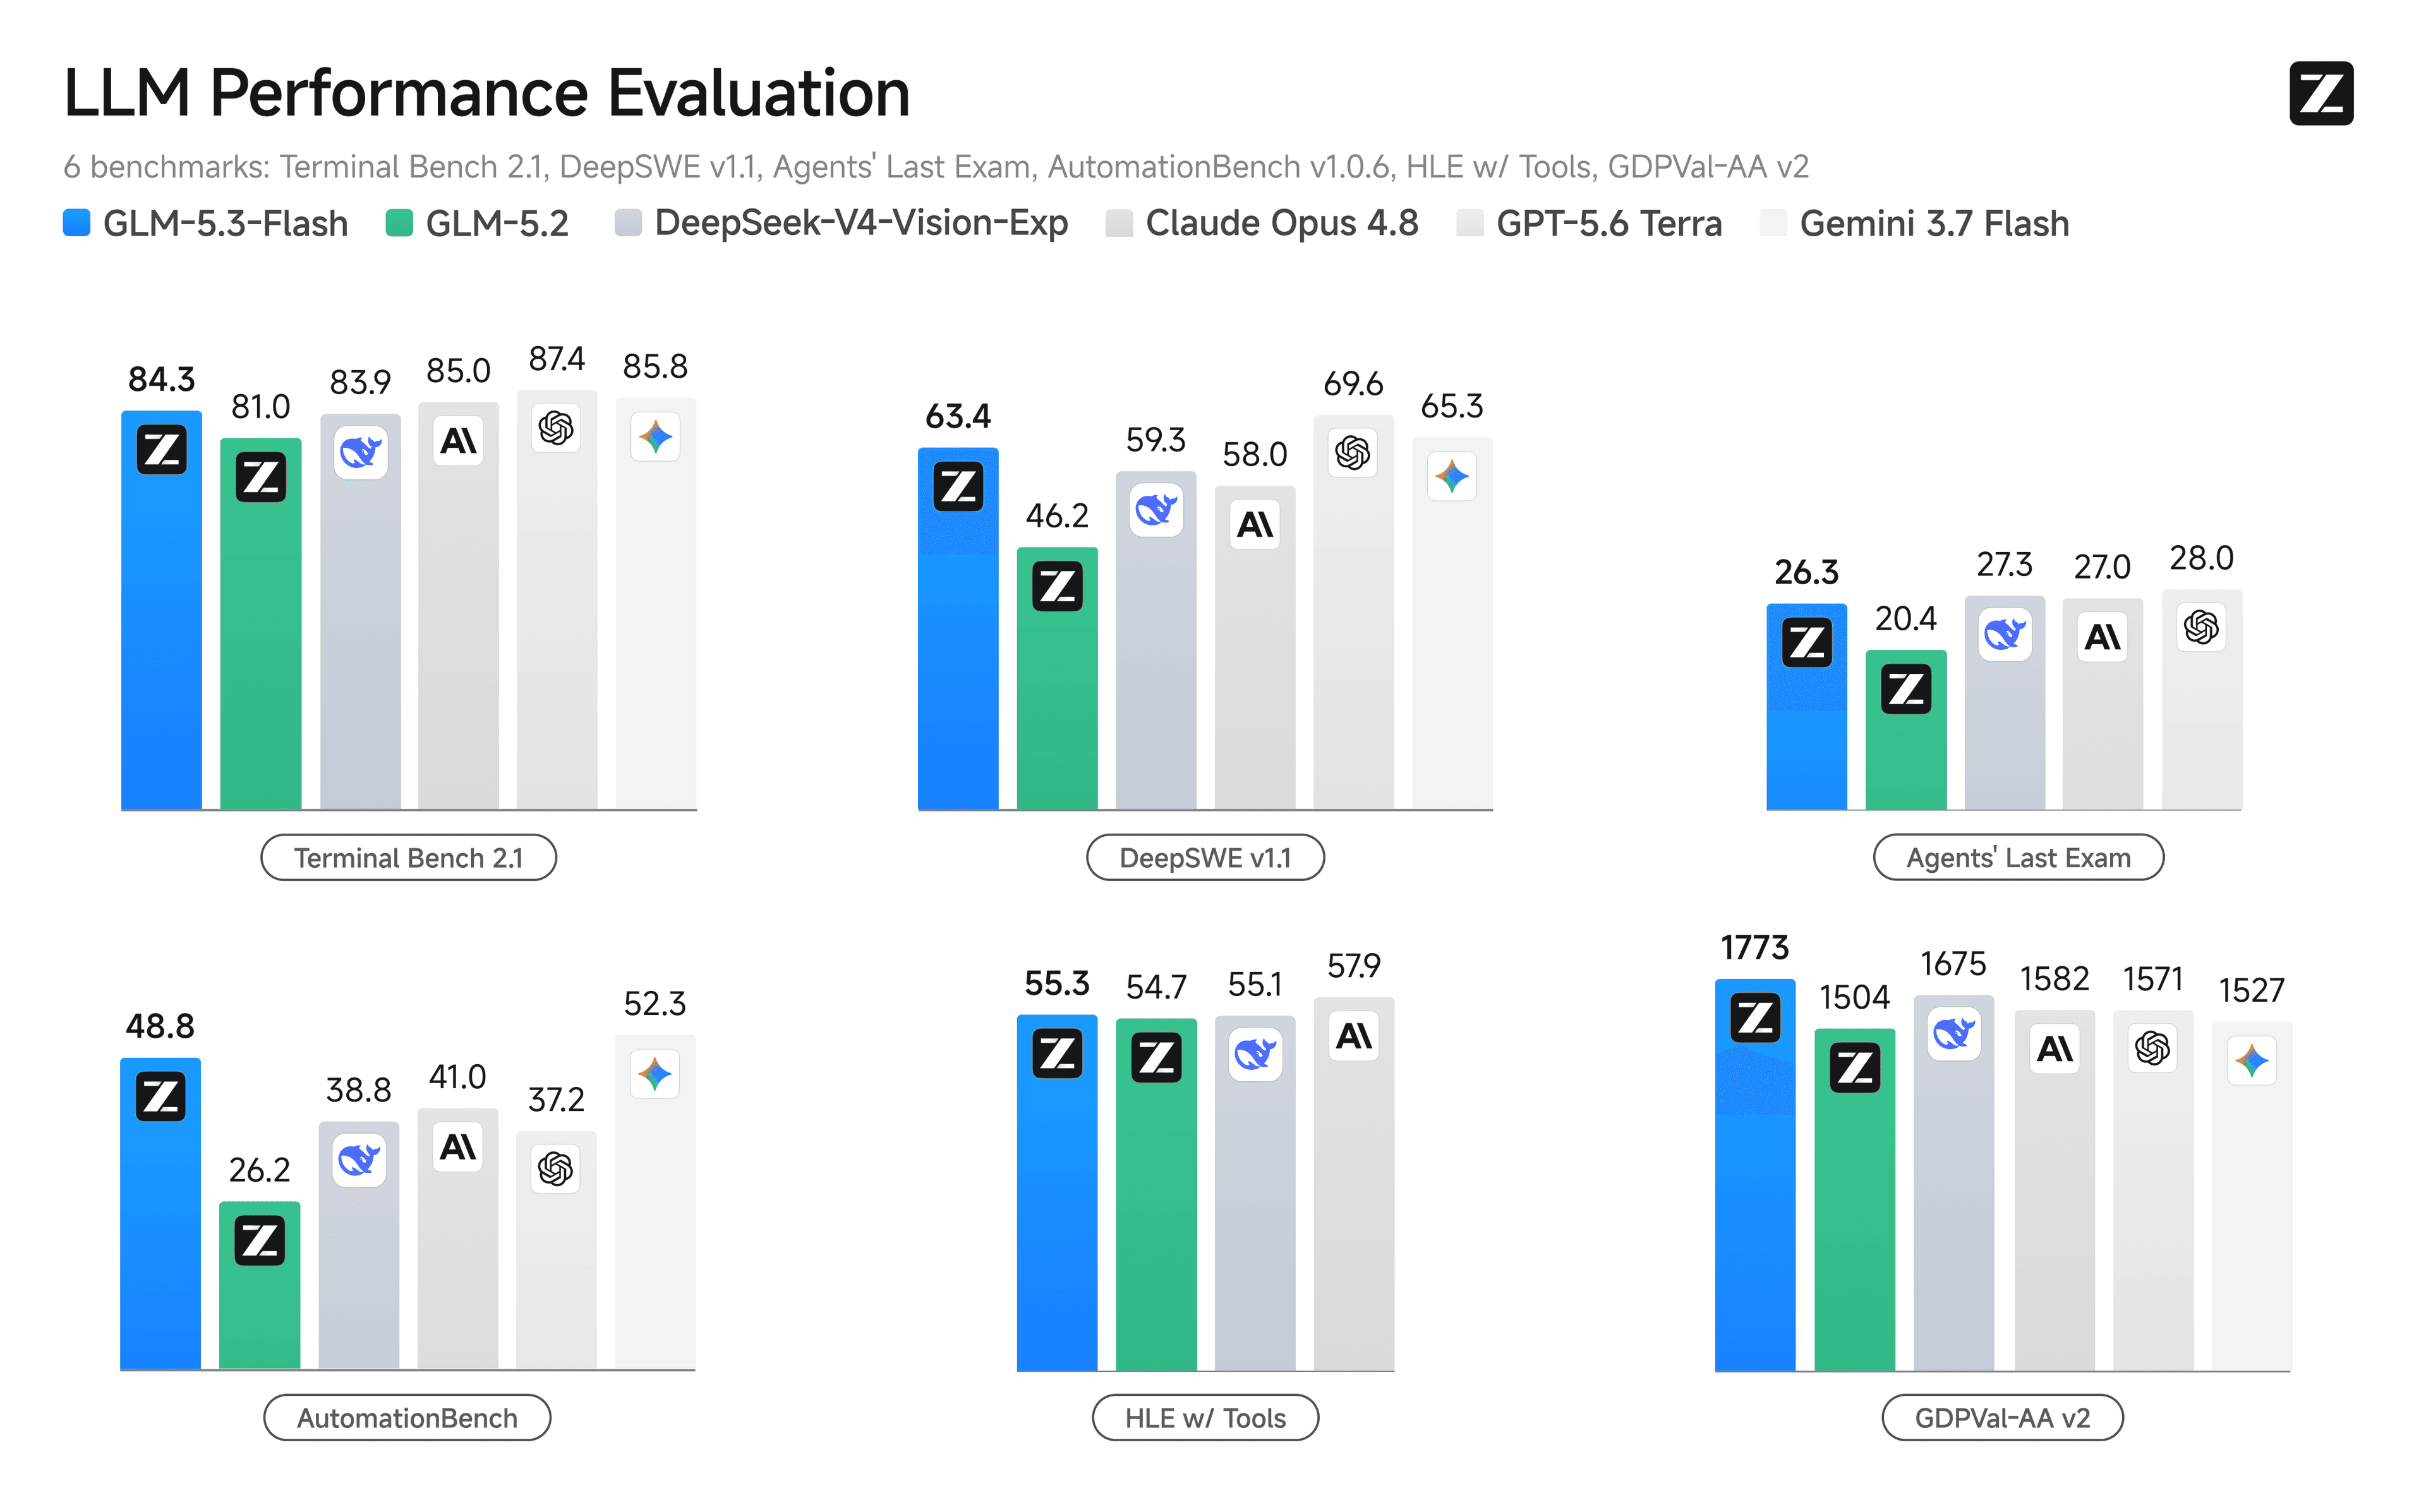
Zhipu releases GLM-5.3-Flash under MIT license
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
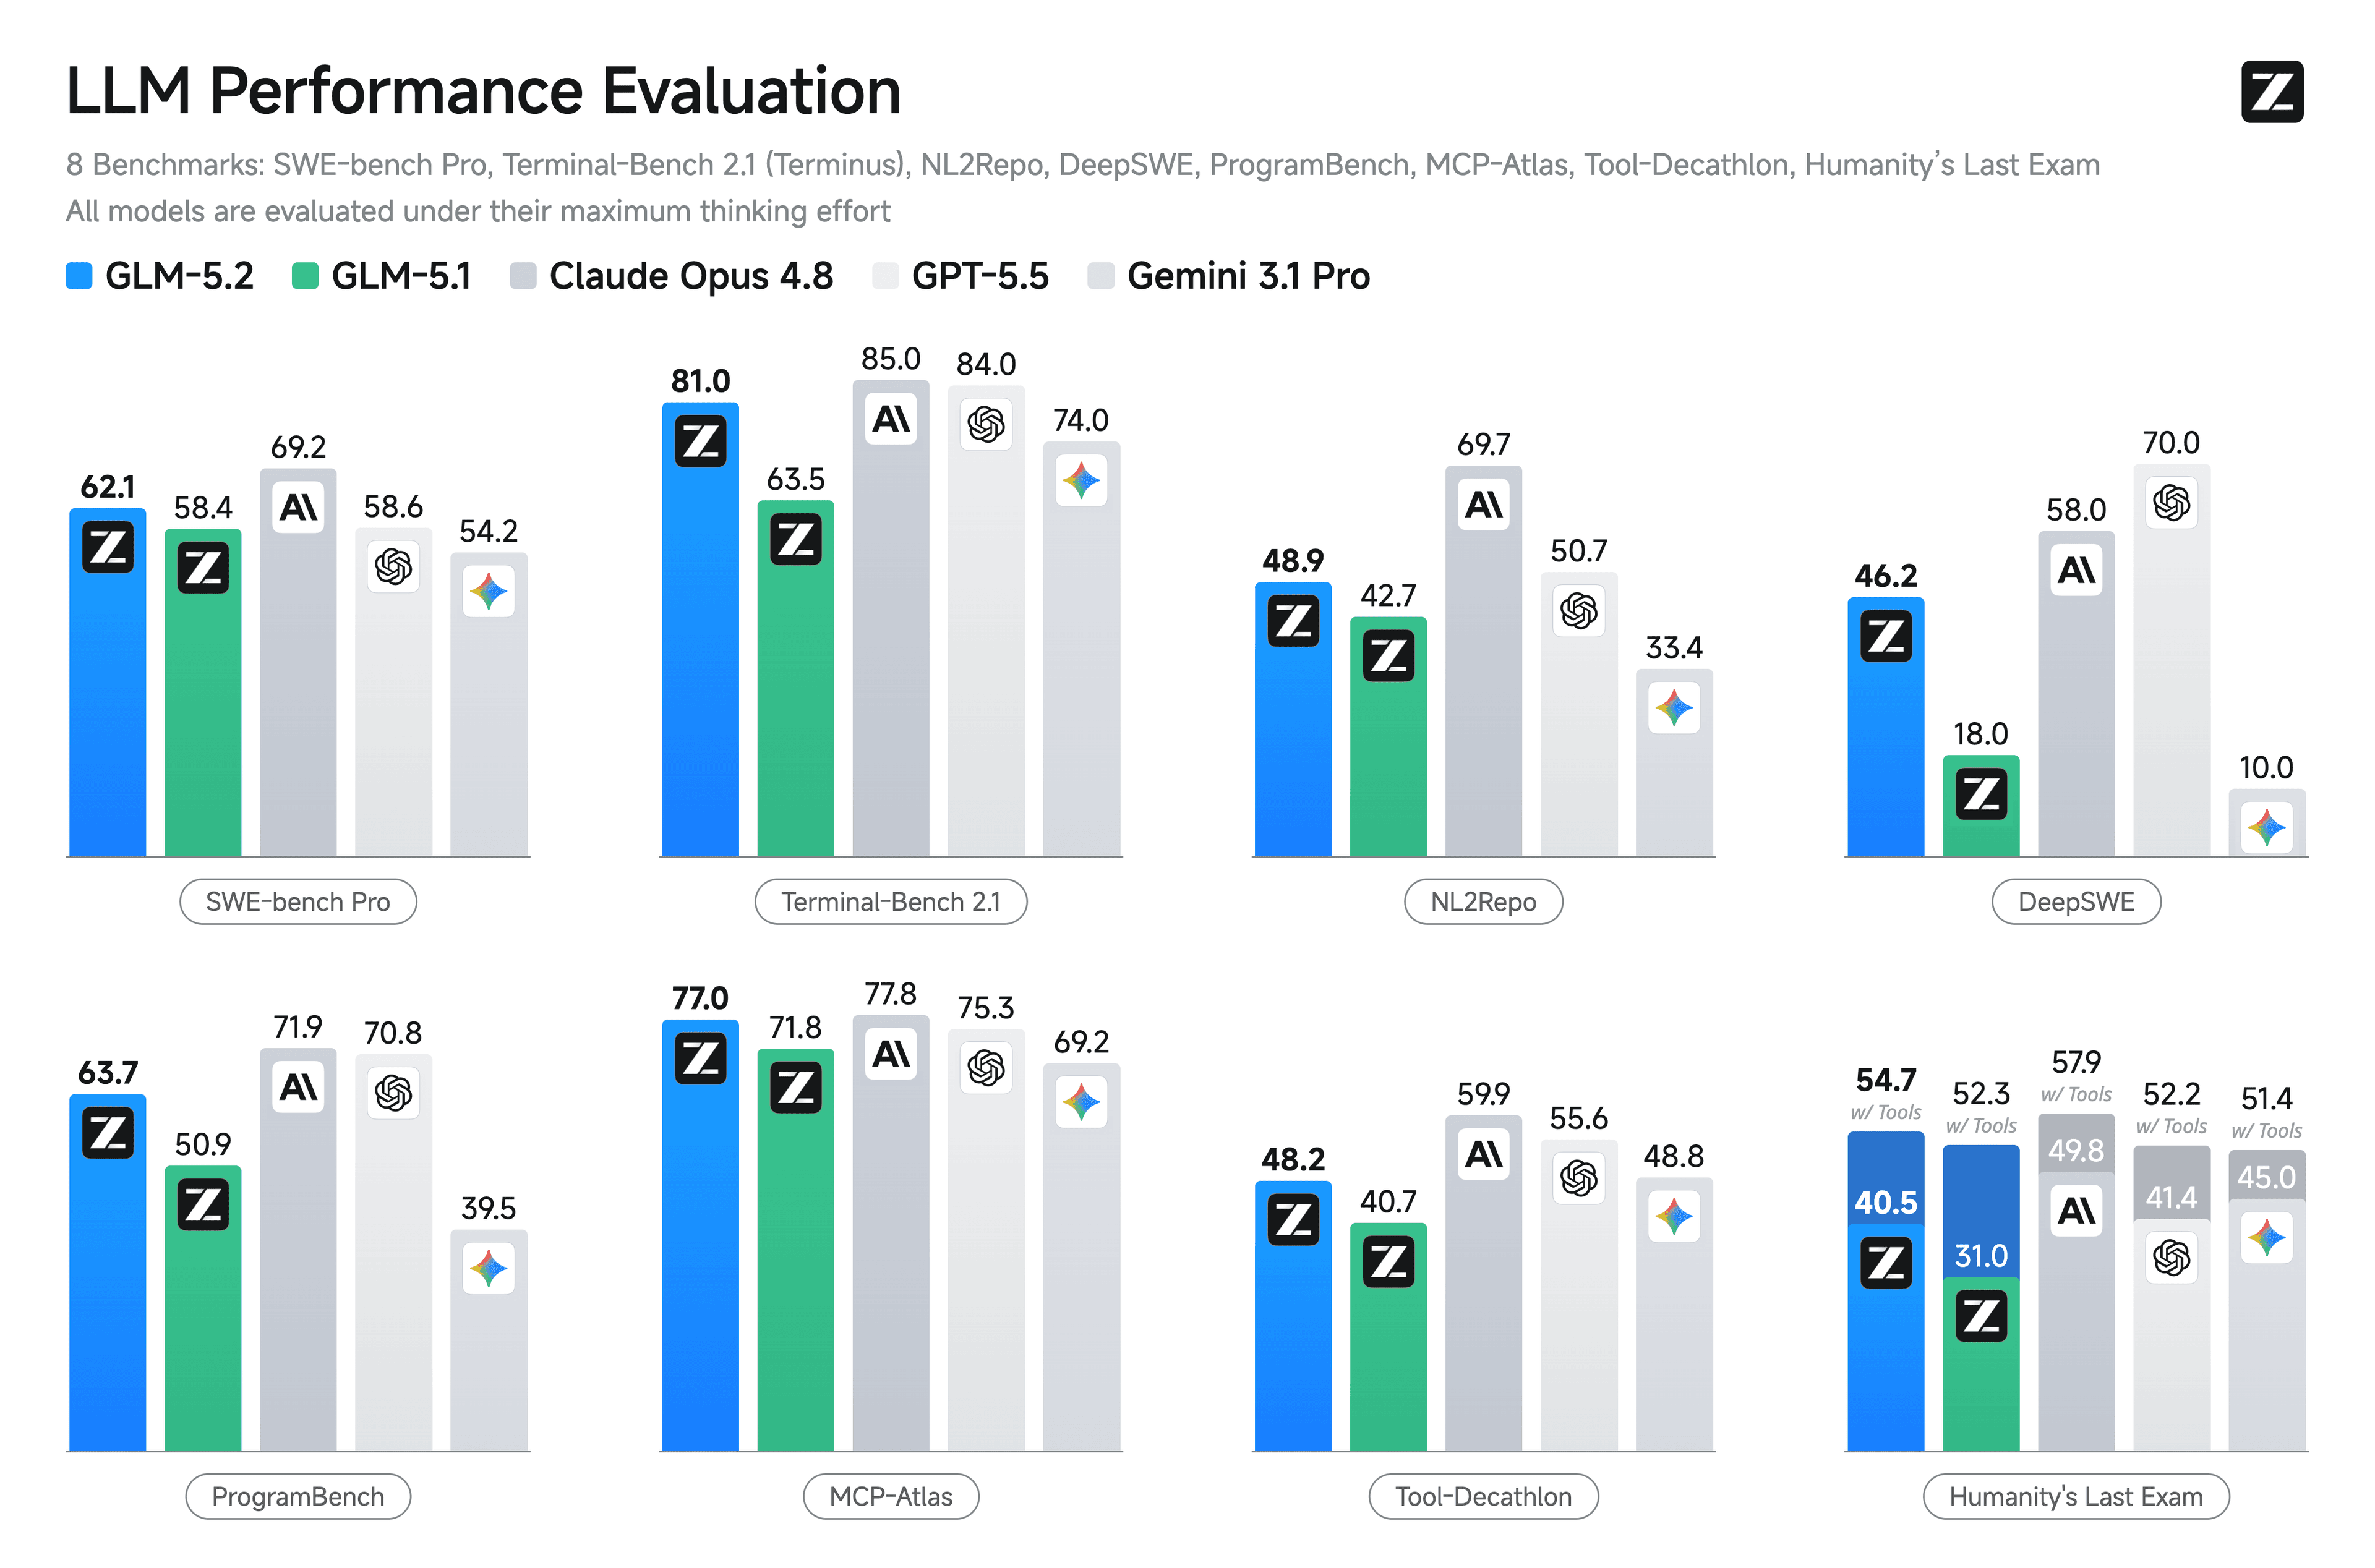
Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.