Nex-N2.5-Pro arrives as an Apache-2.0 MoE vision model
A permissively licensed multimodal mixture-of-experts model built on a Qwen3-style MoE backbone.
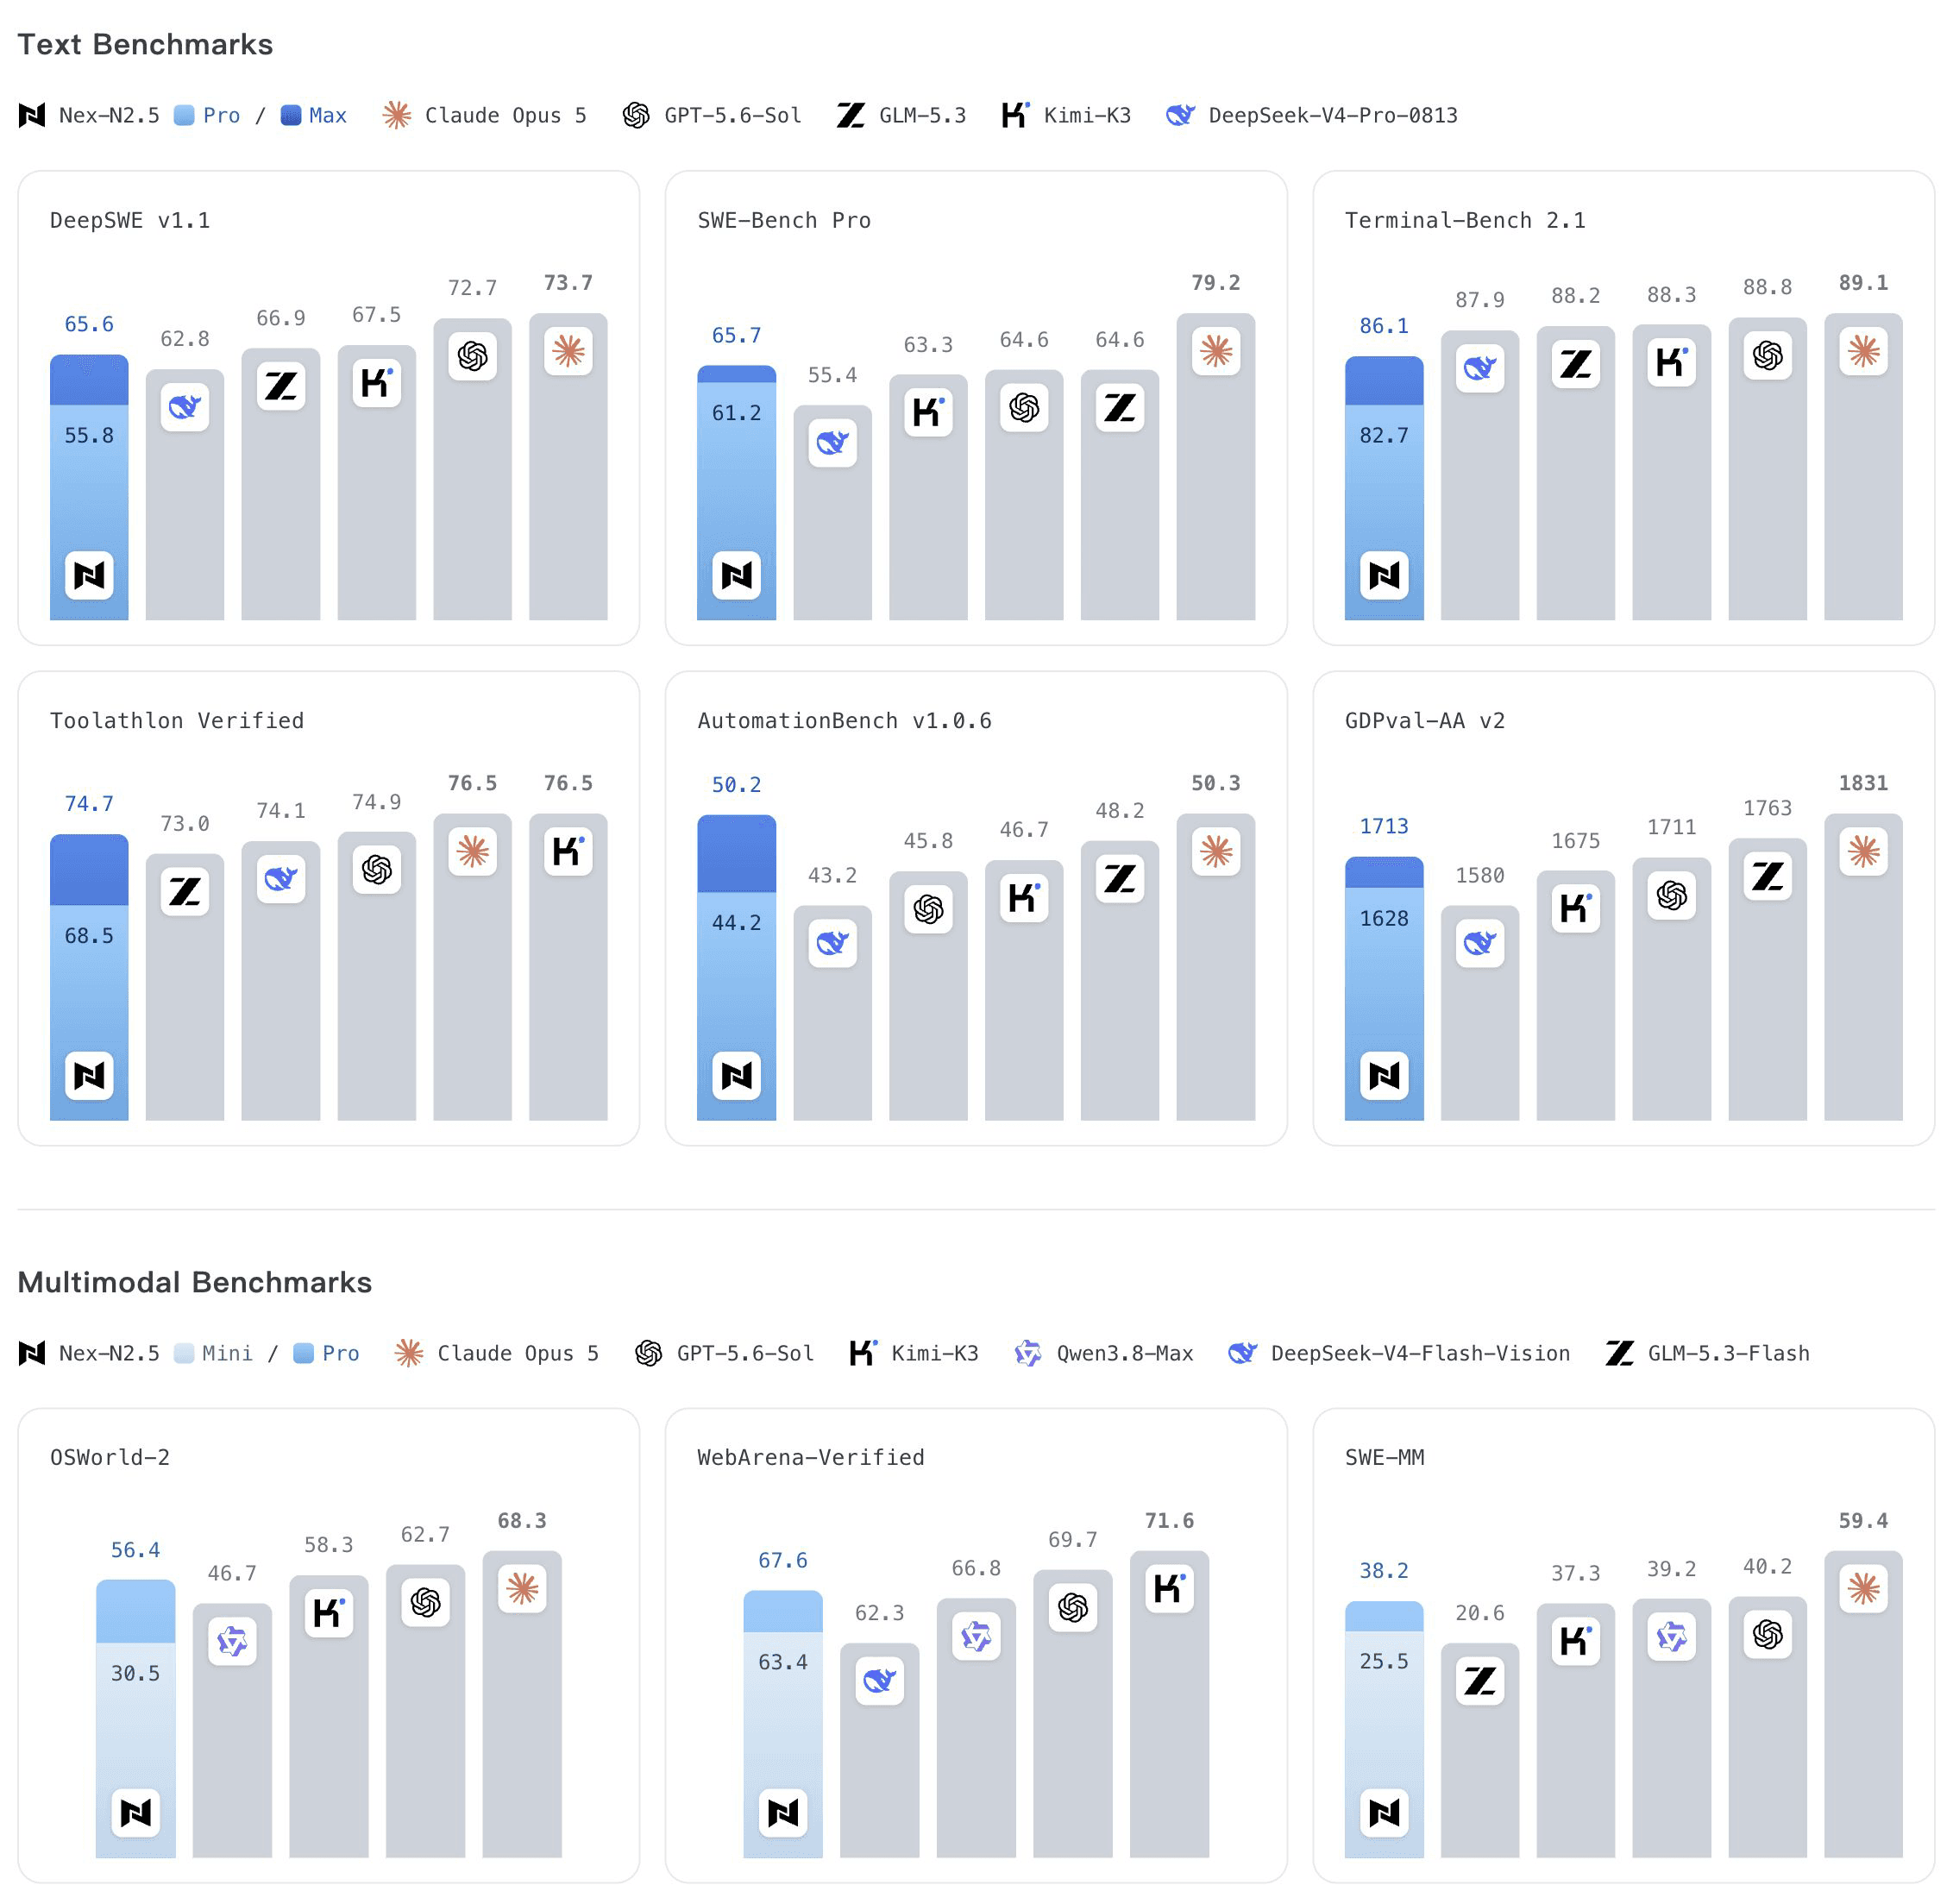
Nex-N2.5-Pro has landed on Hugging Face as a new multimodal model released under the permissive Apache-2.0 license. According to its model page, it is a vision-language model that also handles text-only tasks, built on a mixture-of-experts (MoE) architecture derived from the qwen3_5_moe family.
The MoE design is the notable structural choice here. Rather than activating every parameter for each token, mixture-of-experts models route inputs through a subset of specialized "expert" networks, aiming to deliver larger effective capacity without a proportional jump in inference cost. That approach has become increasingly common among open-weight releases chasing a better quality-per-compute ratio.
Why it matters
The combination of features here is what stands out:
- Multimodal by default, spanning both image understanding and text generation.
- MoE efficiency, inheriting the qwen3_5_moe architecture as a foundation.
- Apache-2.0 licensing, which permits commercial use and modification with minimal restrictions.
Several specifics remain unlisted, including the total and active parameter counts and the supported context length, so teams evaluating the model for production will want to confirm those details directly from the repository. As an initial release in the Nex-N2.5 line, it sets a baseline that any future updates in the family can build on.
For developers, the appeal is straightforward: a permissively licensed, vision-capable MoE model adds another option to the growing shelf of open multimodal systems. The real test will be how it performs against established open-weight peers once independent evaluations arrive.
Sources
- Visit
nex-agi/Nex-N2.5-Pro
Hugging Face
More from Nex Agi
All Nex Agi releases →
Nex AGI releases Nex-N2.5-mini, an open MoE multimodal model
The compact mixture-of-experts model handles both text and vision, and ships under a permissive Apache-2.0 license.
More in Vision-Language
All Vision-Language →
Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
0 comments
No comments yet. Be the first to weigh in.