Qwen Releases 80B Mixture-of-Experts Model
The new Qwen3-Next model from Alibaba combines a large parameter count with an efficient MoE architecture to balance performance and computational cost.

The Qwen team at Alibaba has released Qwen3-Next-80B-A3B-Instruct, a new large language model that employs a Mixture-of-Experts (MoE) architecture. This release marks the introduction of the Qwen3-Next series, signaling a focus on more computationally efficient designs for powerful models.
The key feature of this model is its MoE structure. While it contains a total of 80 billion parameters, only 3 billion are activated for processing any given token. This design aims to provide the knowledge and nuance of a very large model while keeping inference costs significantly lower, making it more accessible for a wider range of applications and hardware setups.
Technical Specifications
Beyond its architecture, Qwen3-Next is an instruction-tuned model designed for chat and task completion. It supports a context length of up to 65,536 tokens, making it suitable for tasks requiring long-form context and analysis. The model is built on a standard Transformer foundation with SwiGLU activations and Group Query Attention for efficiency.
Released under the permissive Apache 2.0 license, the Qwen3-Next-80B-A3B-Instruct model is available for both research and commercial use. This continues the trend of major AI labs contributing powerful, open models that allow developers to build without restrictive licensing, fostering broader innovation in the ecosystem.
Sources
- Visit
Qwen/Qwen3-Next-80B-A3B-Instruct
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Text / LLM
All Text / LLM →Meta AI debuts Muse Ember, a compact open model
The company's smallest, most efficient open-weight language model targets lean, on-device text workloads.
Thinking Machines ships Inkling-2-Small, an open MoE VLM
The Apache-2.0 vision-language model uses a mixture-of-experts design and lands openly on Hugging Face.
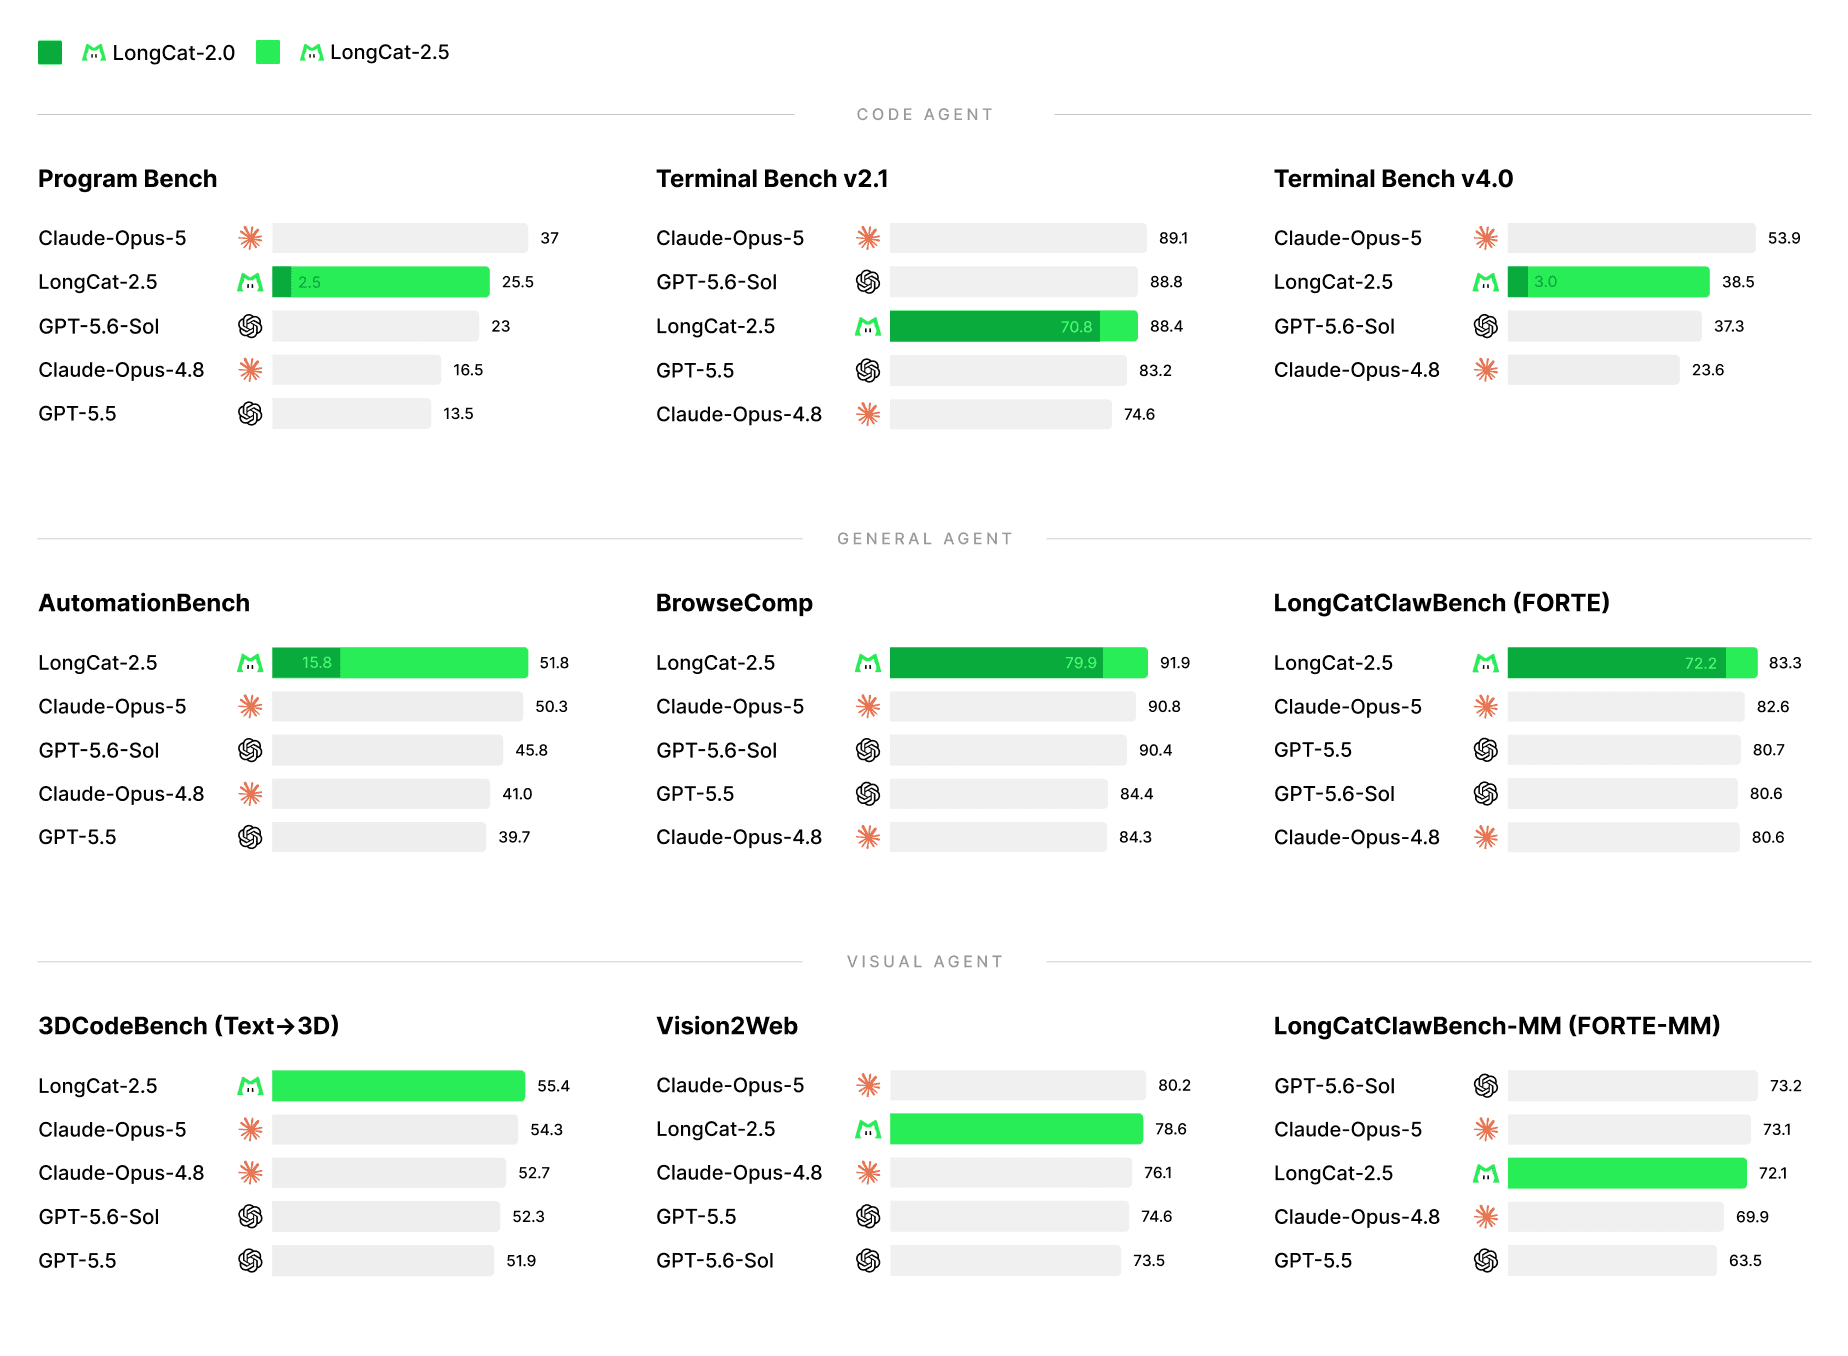
Meituan Releases LongCat 2.5, an MIT-Licensed MoE
The Chinese delivery giant expands its open-model push with a multimodal, agentic mixture-of-experts system.
0 comments
No comments yet. Be the first to weigh in.