Qwen Unveils Wan2.2, a 14B Open Text-to-Video Model
The new Apache 2.0-licensed model from Alibaba's team uses a Mixture-of-Experts architecture for efficient, high-quality video generation.

The Qwen team at Alibaba has introduced a significant new open-source model for generating video from text prompts, called Wan2.2-T2V-A14B. This release expands the team's portfolio of powerful, openly accessible foundation models.
What sets this model apart is its use of a Mixture-of-Experts (MoE) architecture. It features 14 billion active parameters, meaning only a fraction of the model's total size is engaged for any given task. This design aims to deliver the performance of a much larger model while keeping the computational cost of inference more manageable.
The release of Wan2.2 is a notable event in the competitive landscape of generative video. By making the model available under the permissive Apache 2.0 license, the Qwen team provides researchers and developers with a powerful, unrestricted tool for building new applications and pushing the boundaries of video synthesis.
The model is now available for download and experimentation on the Hugging Face Hub, allowing the community to begin exploring its capabilities immediately.
Sources
- Visit
Wan-AI/Wan2.2-T2V-A14B
Hugging Face
More in Text → Video
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
Lightricks Releases LTX-2.5 Video Model
The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.
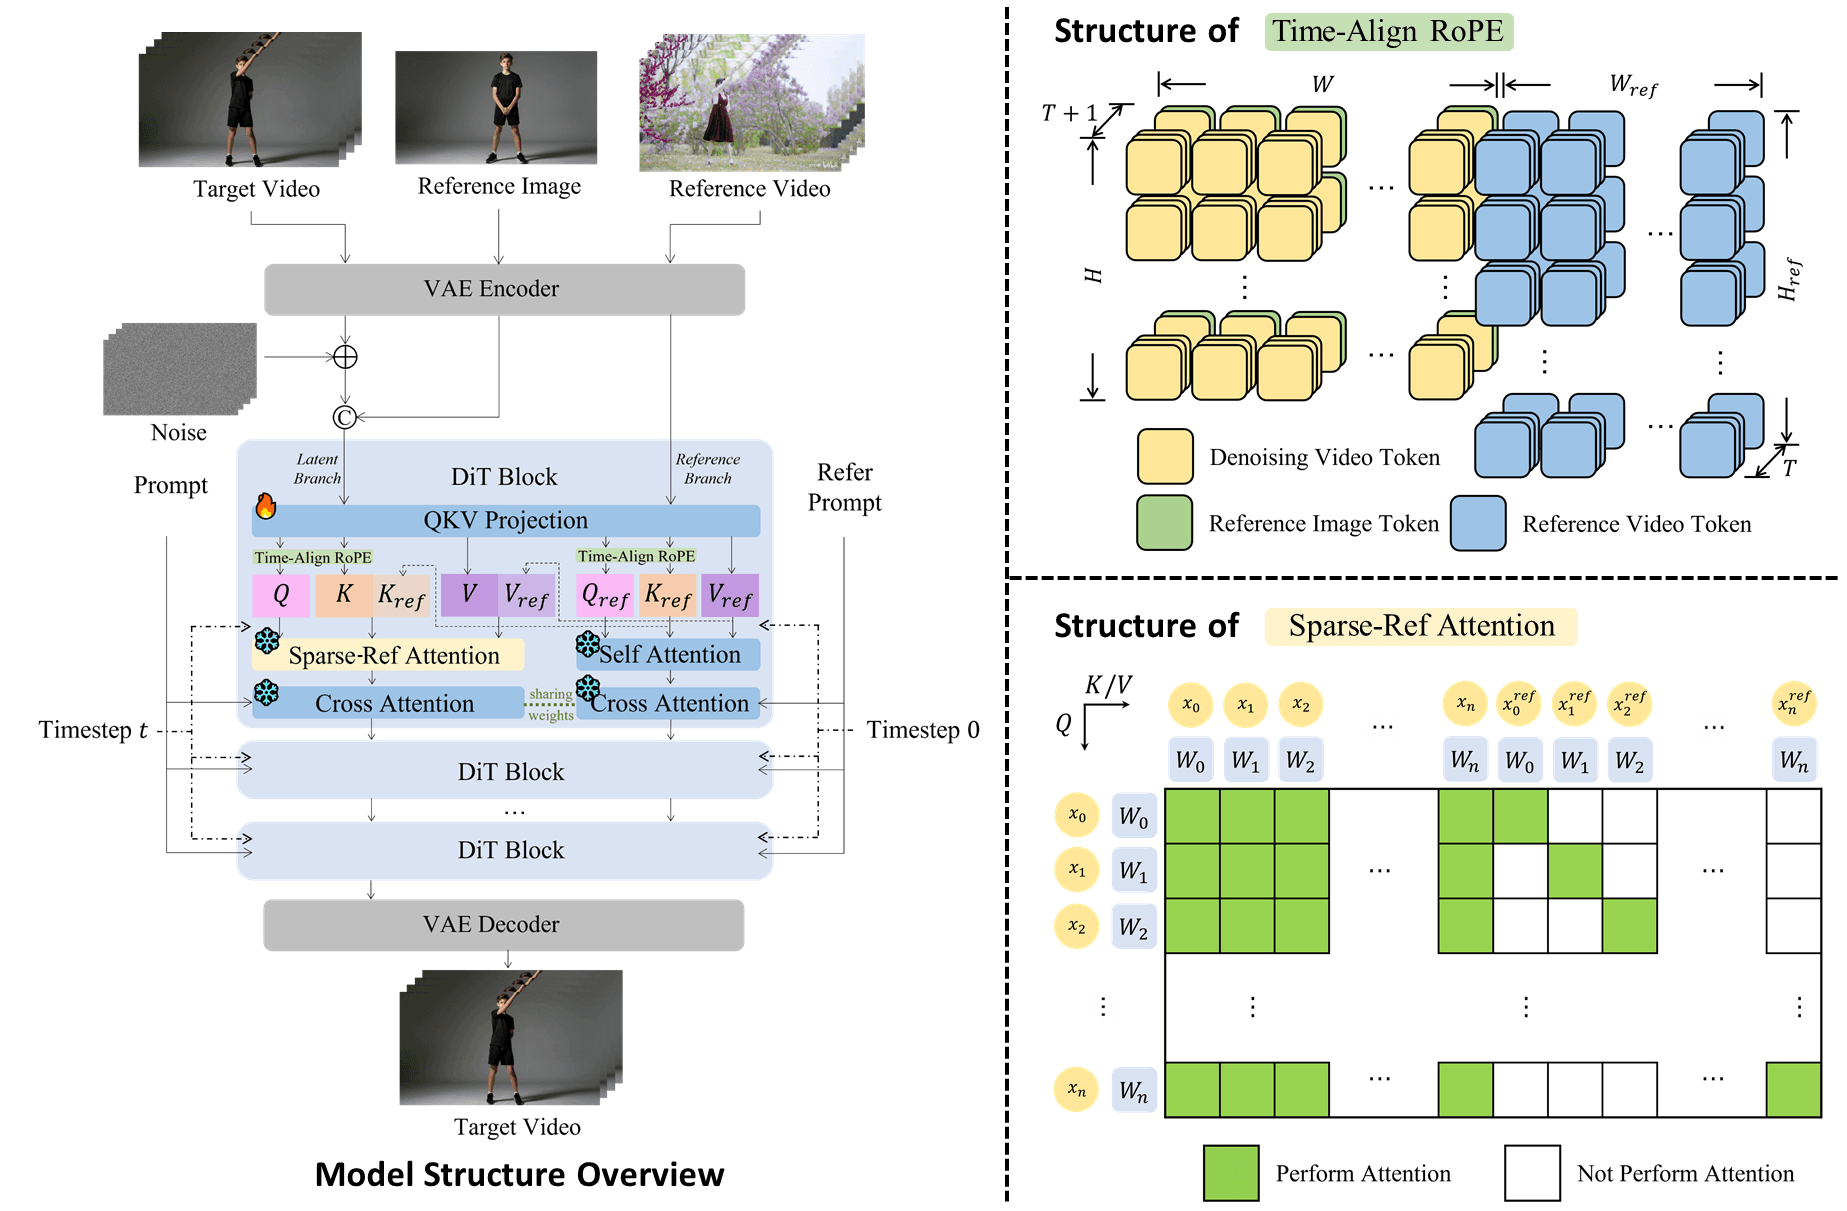
Alibaba's Wan2.2-Animate-2 14B lands under Apache 2.0
A permissively licensed 14B video model aimed at character animation joins the growing Wan family.
0 comments
No comments yet. Be the first to weigh in.