Qwen Releases Wan2.2, a 14B Image-to-Video Model
The new 14-billion parameter model from Alibaba's AI team uses a Mixture-of-Experts design and is available under the permissive Apache 2.0 license.
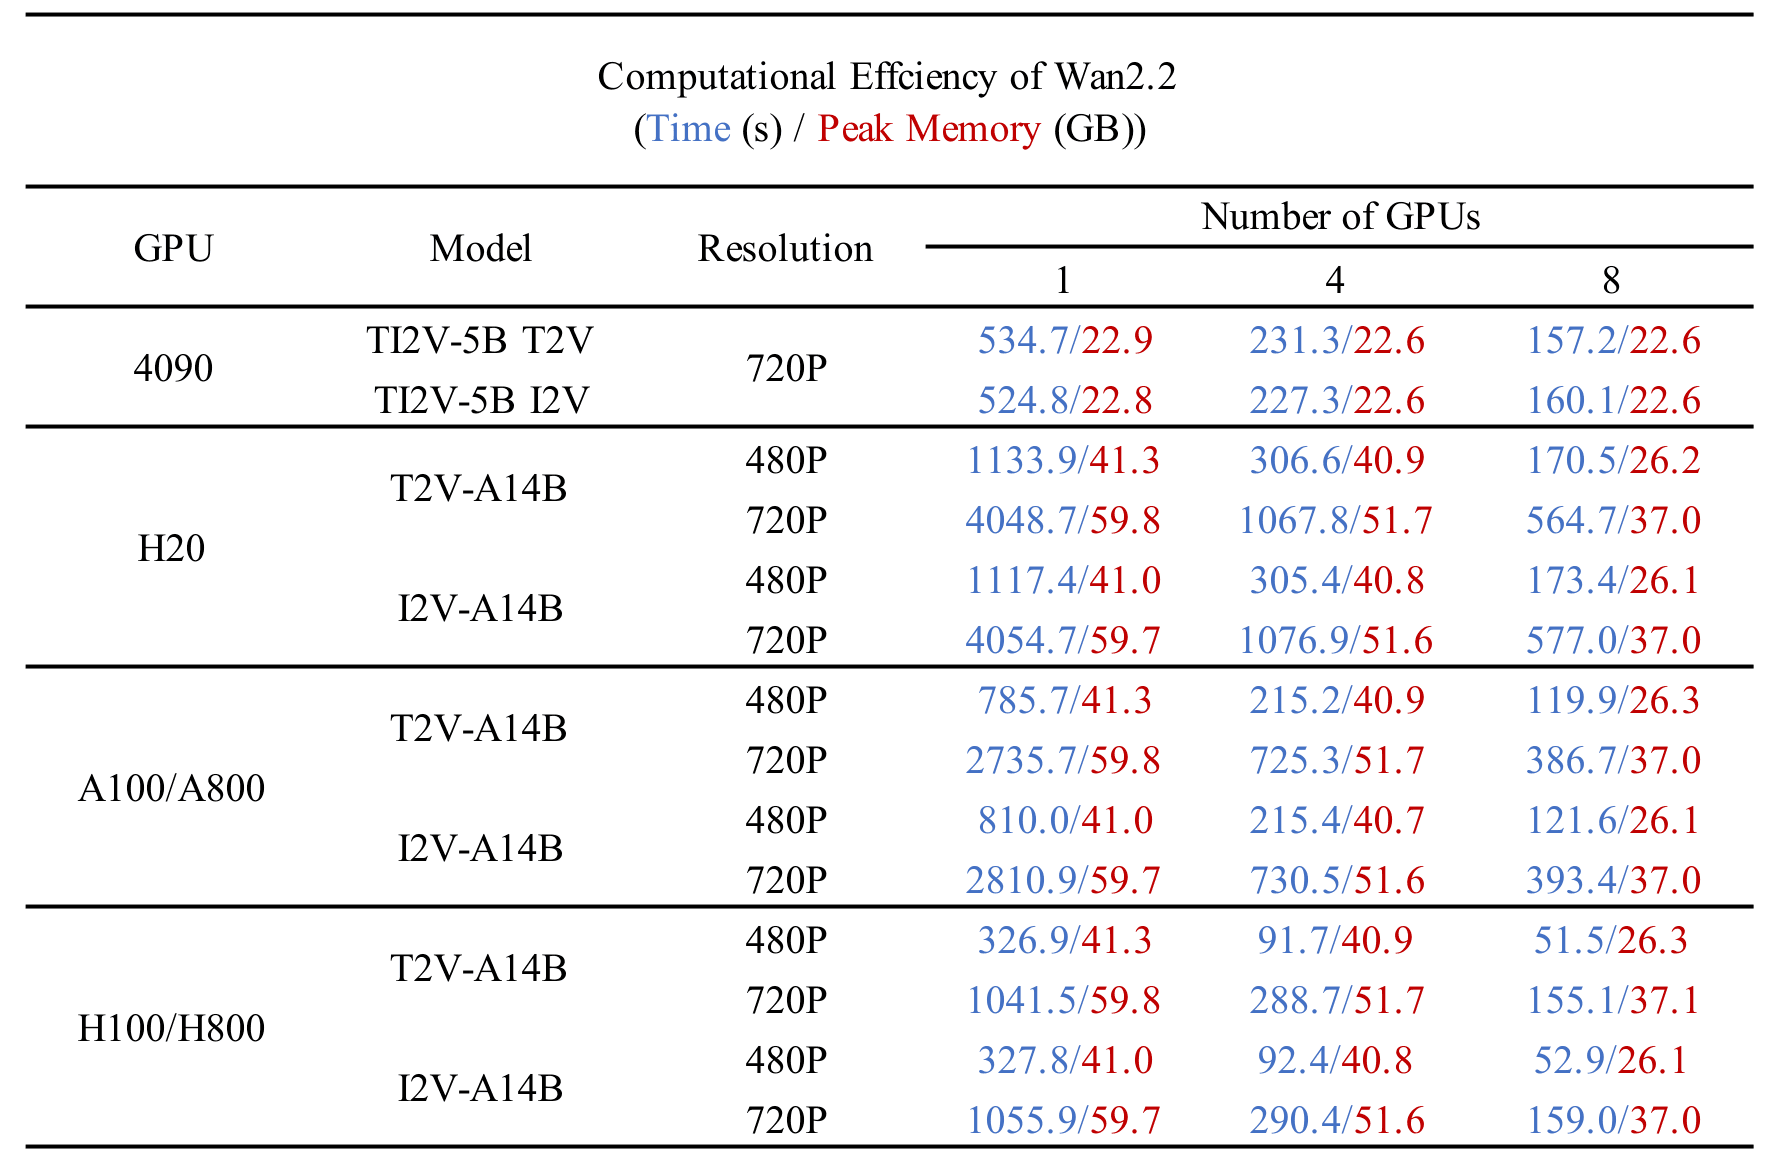
Alibaba's Qwen team has introduced Wan2.2-I2V-A14B, a new open-source model designed for generating short video clips from a single static image. This release adds a powerful new tool to the rapidly expanding field of generative video.
The model features a 14-billion parameter architecture built on a Mixture-of-Experts (MoE) framework. This design allows for more efficient computation by selectively activating parts of the network during inference, a technique that can offer the performance of a much larger dense model while managing computational costs.
Why It Matters
A key aspect of this release is its Apache 2.0 license. Unlike many generative models limited to non-commercial or research-only use, Wan2.2 is available for a wide range of applications, including commercial products. This permissive licensing is a significant contribution to the open-source creative AI ecosystem, enabling developers and businesses to innovate on the technology freely.
The release of Wan2.2 adds another strong contender to the competitive landscape of open video generation. Researchers and developers can access the model and its components directly from the Hugging Face Hub.
Sources
- Visit
Wan-AI/Wan2.2-I2V-A14B
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
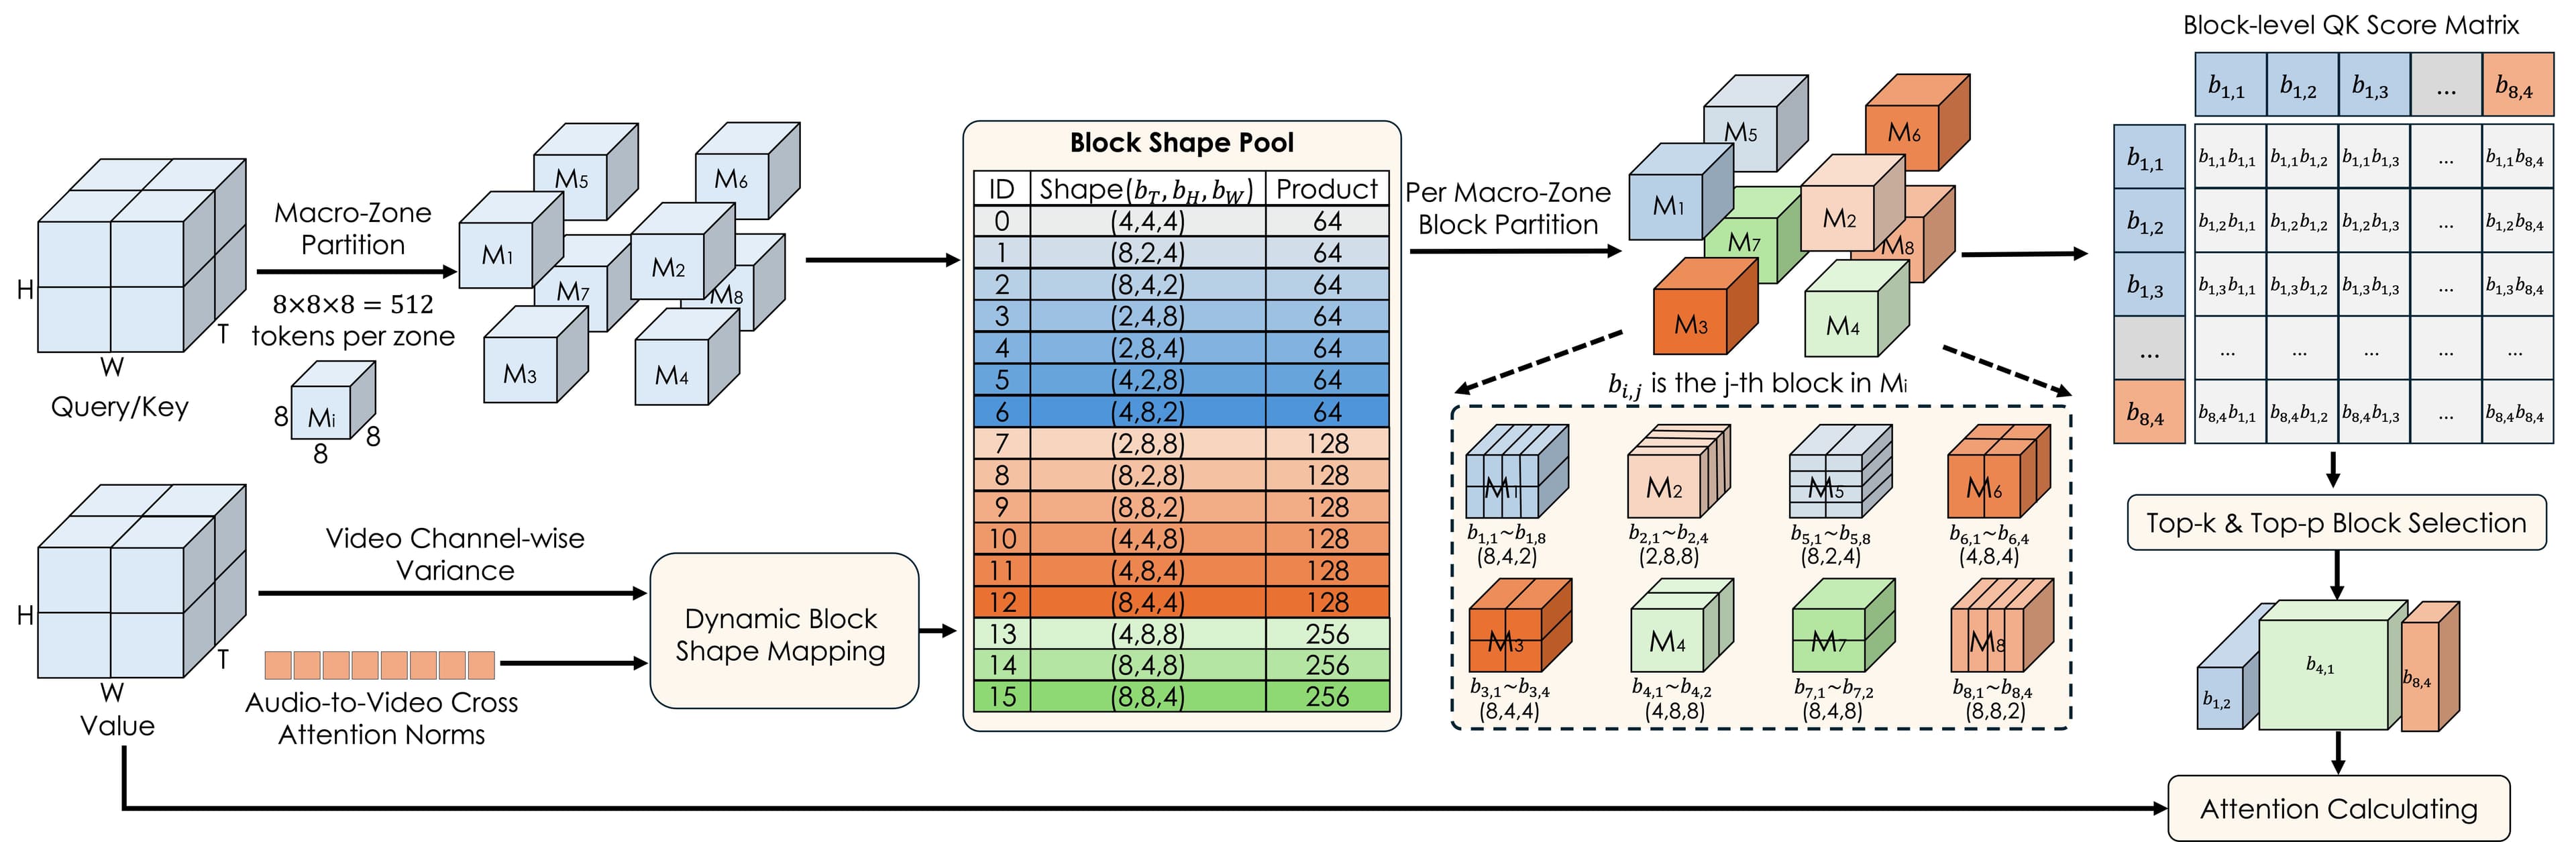
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.