Alibaba Releases 14B Model for Audio-Driven Video
The new Wan2.2-S2V model takes a still image and a speech track to generate a realistic talking-head animation, available under a permissive license.

The team behind Alibaba's Qwen models has released Wan2.2-S2V-14B, a new open-source model designed for a specific creative task: generating talking-head videos from a single image and an audio file. With 14 billion parameters, the model animates a person's face to match a given speech track, effectively creating a lifelike digital puppet.
The 'S2V' in the model's name stands for Speech-to-Video, highlighting its specialized function. Unlike general-purpose text-to-video systems, Wan2.2-S2V focuses exclusively on the challenge of syncing facial movements and lip-sync to an audio source. It analyzes the audio's phonetic components and timing to produce a corresponding, natural-looking animation on the provided static image.
Why it matters
This release provides developers and creators with a powerful tool for applications like creating virtual presenters, dubbing video content into new languages, or generating character animations for digital media. The model's permissive Apache 2.0 license is particularly notable, as it allows for broad commercial use—a key distinction from many research-oriented releases in the space.
Wan2.2-S2V-14B represents a growing trend of specialized, open-source AI tools that excel at one task rather than attempting to be all-purpose generators. It builds on the Qwen team's portfolio of powerful open models and is available for download and experimentation on Hugging Face.
Sources
- Visit
Wan-AI/Wan2.2-S2V-14B
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.

Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
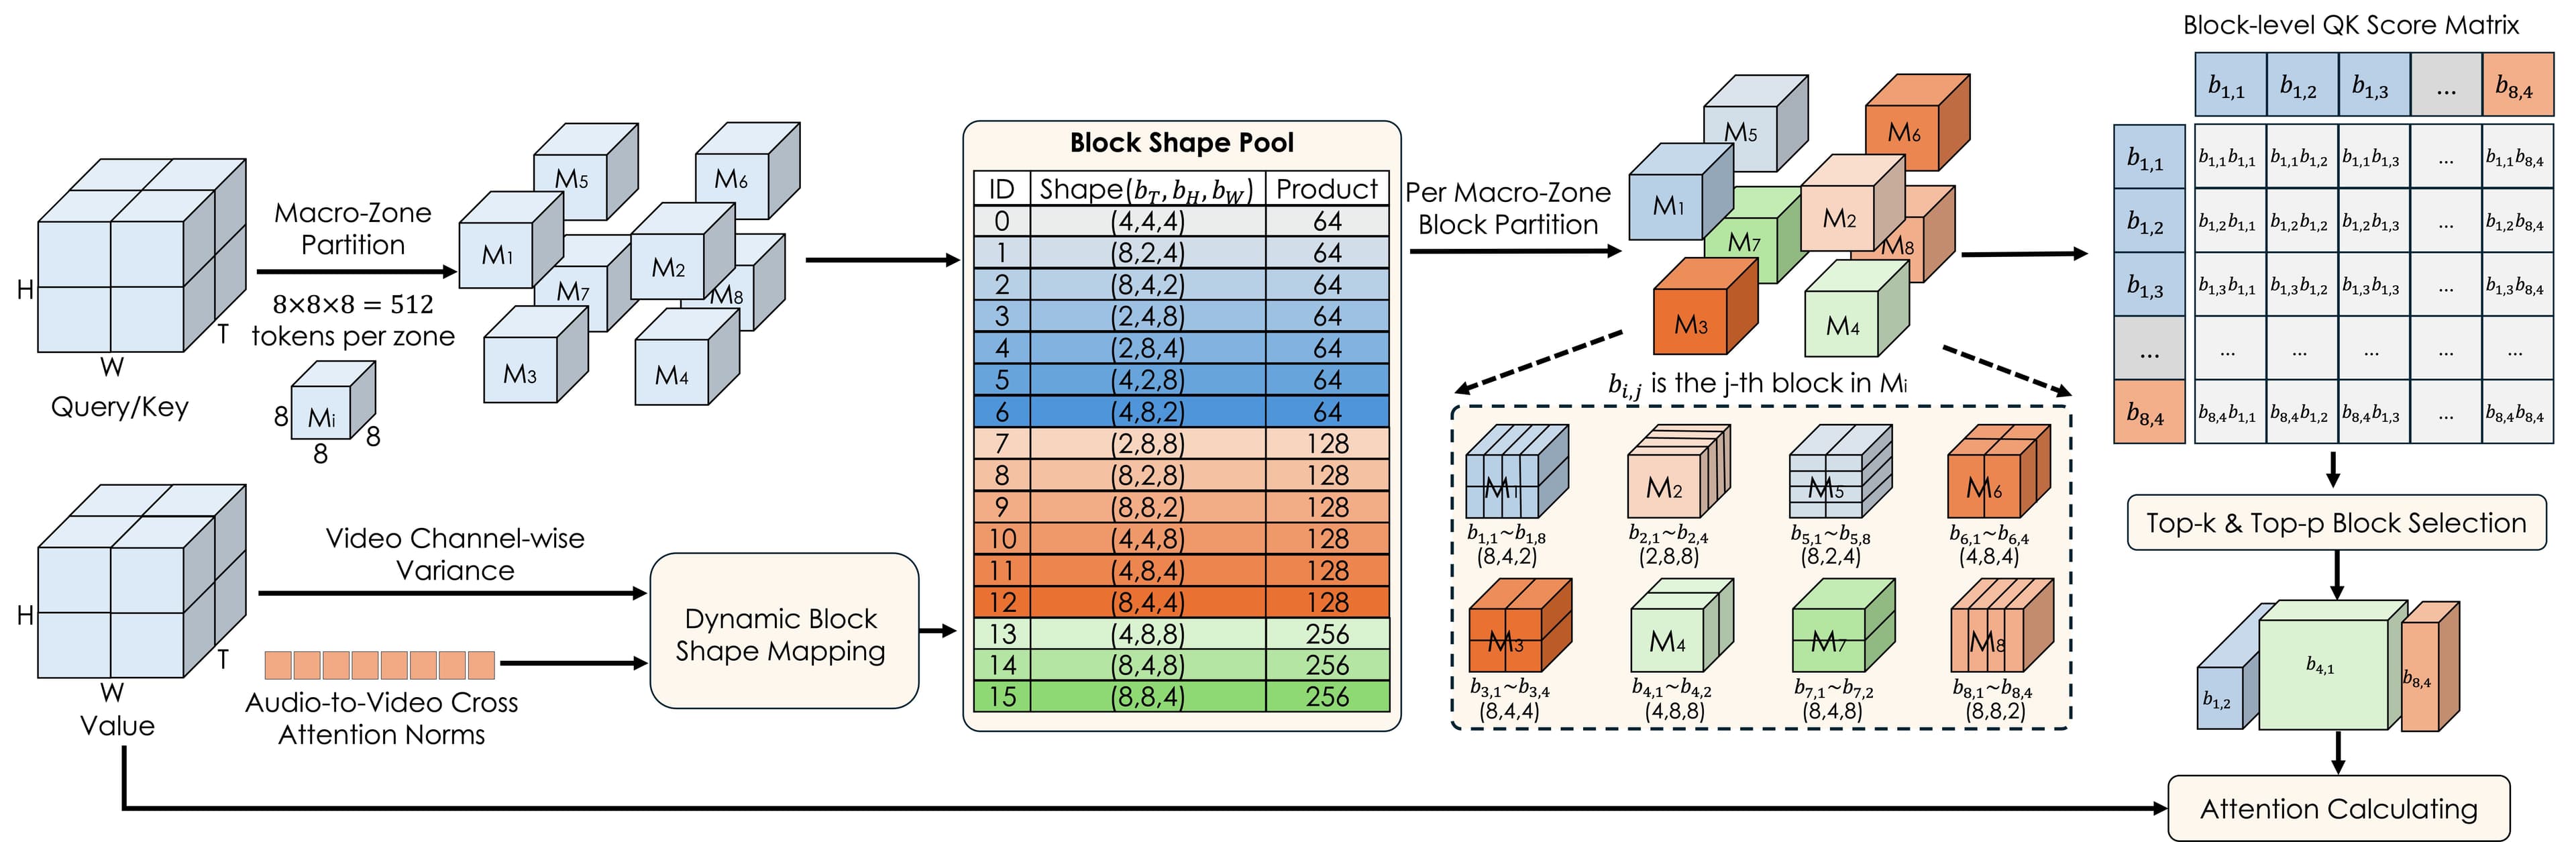
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.