OpenBMB Releases Compact Multimodal Model MiniCPM-V 4.5
The new vision-language model from the open-source research group demonstrates strong OCR and video understanding capabilities in a small package.
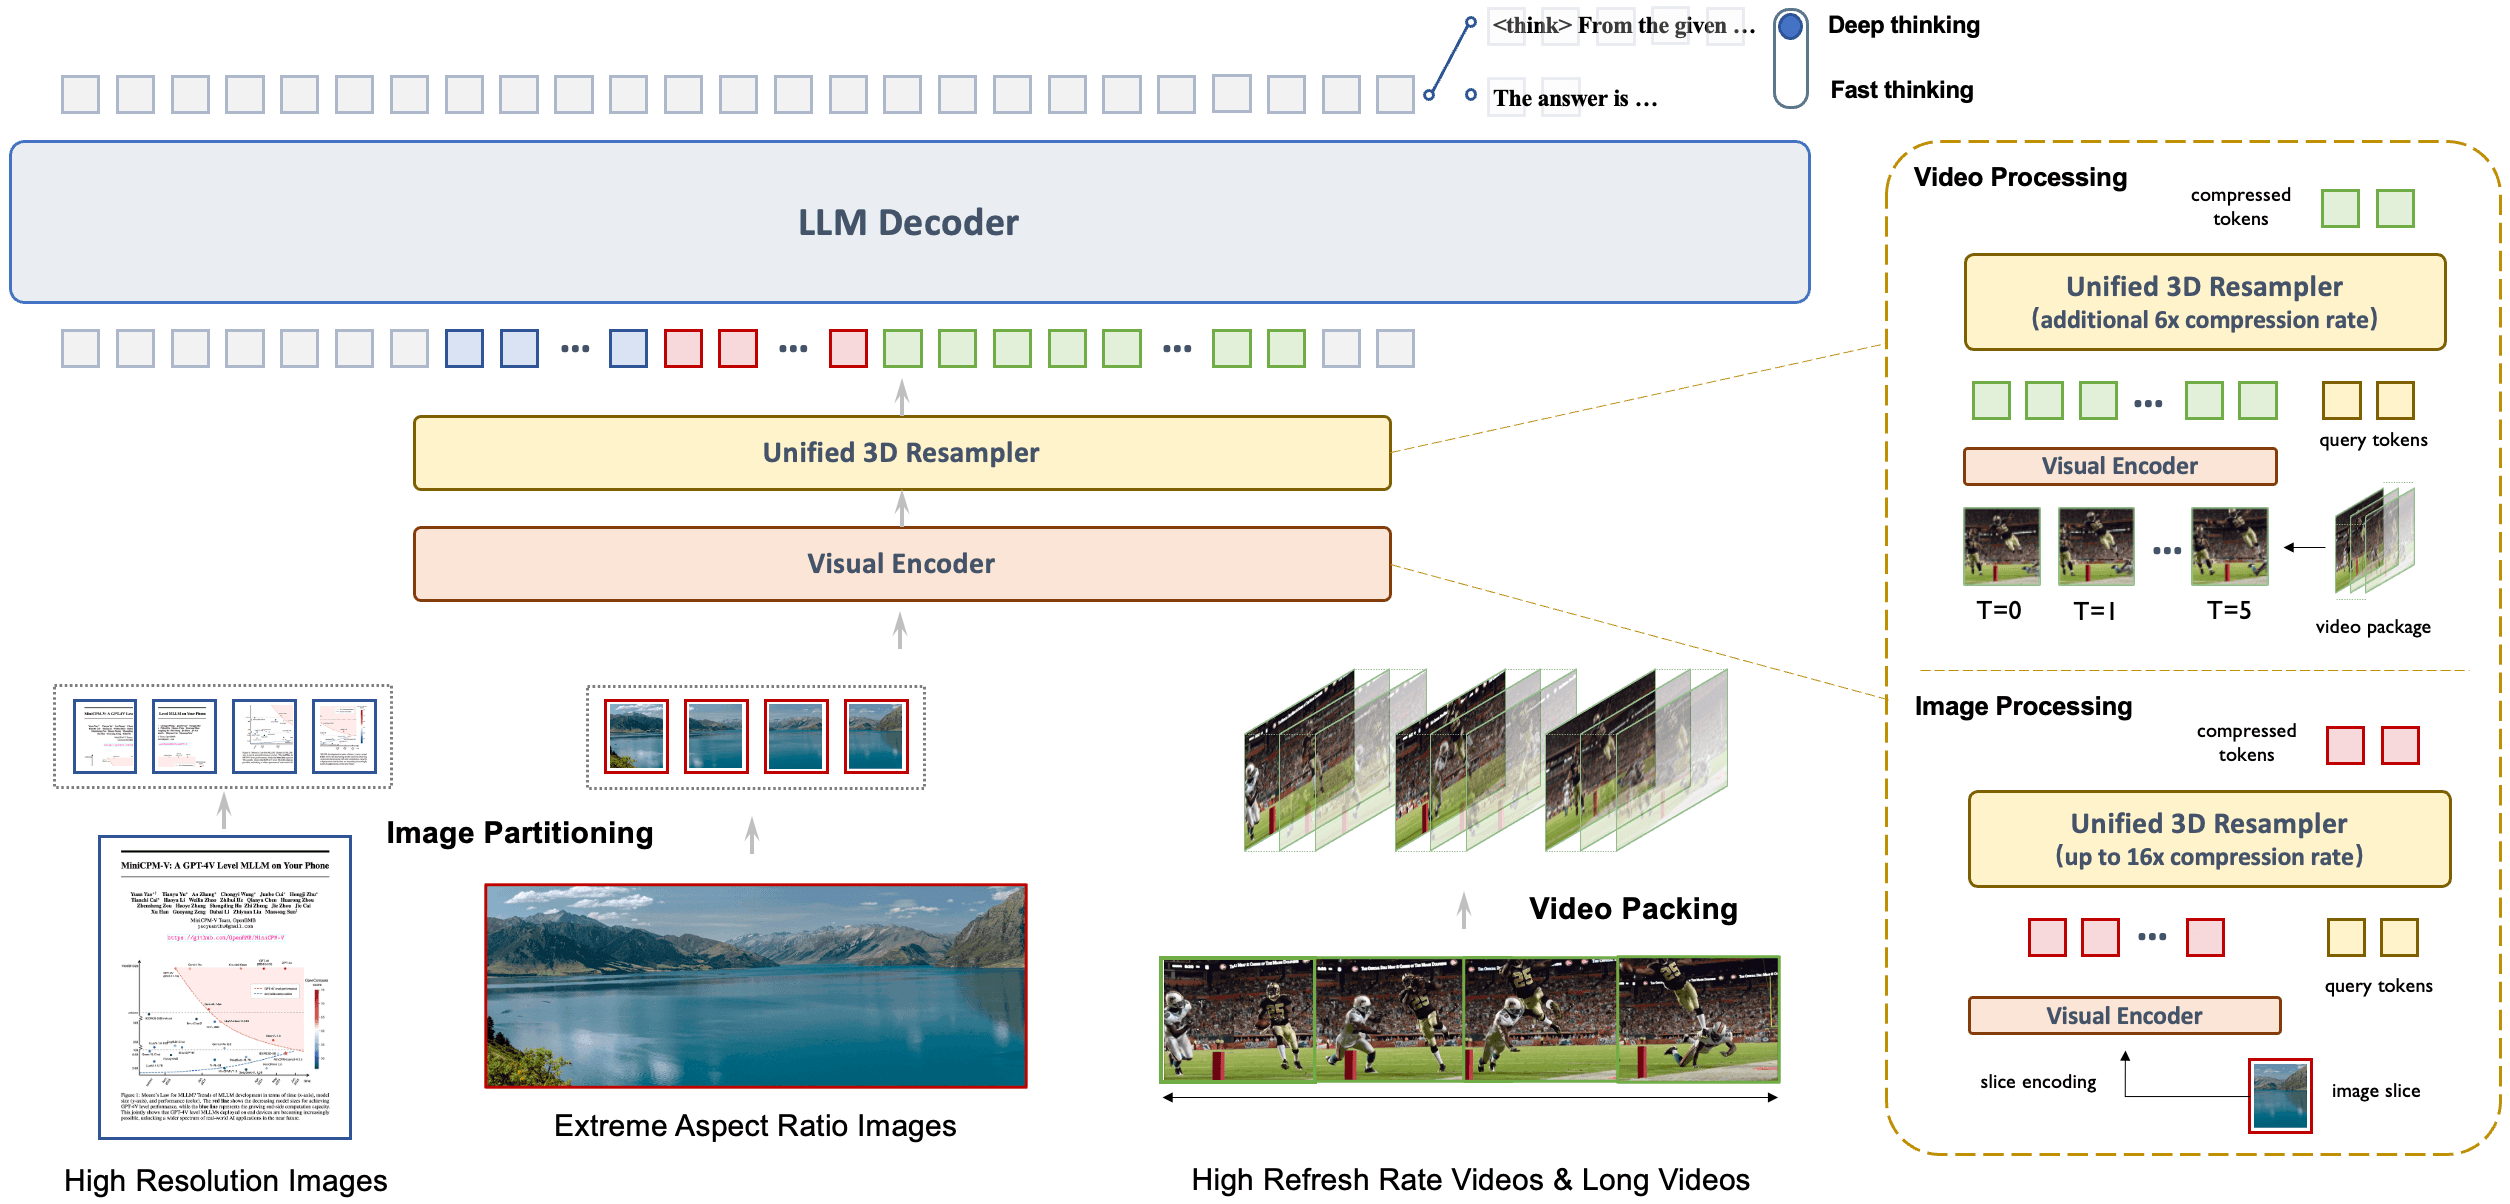
The open-source AI research group OpenBMB has released MiniCPM-V 4.5, a new and notably compact vision-language model (VLM). This model aims to deliver sophisticated multimodal understanding without requiring the massive computational resources often associated with leading-edge vision systems.
According to the release notes, the model demonstrates strong performance on tasks that have historically challenged even larger systems. Its key features include high-accuracy Optical Character Recognition (OCR), the ability to comprehend context across multiple images, and the capacity to understand video content—a significant step for a model in its size class.
Why it matters
The release of a smaller yet powerful VLM like MiniCPM-V is significant for developers working with limited hardware. Its efficiency opens up possibilities for on-device applications and more accessible multimodal AI research, lowering the barrier to entry for building sophisticated vision-based tools.
The model is now available for download and experimentation. Interested developers can find all the resources on the Hugging Face Hub. The model is available under a custom license, so users should review the terms before deployment in production environments.
Sources
- Visit
openbmb/MiniCPM-V-4_5
Hugging Face
More from OpenBMB
All OpenBMB releases →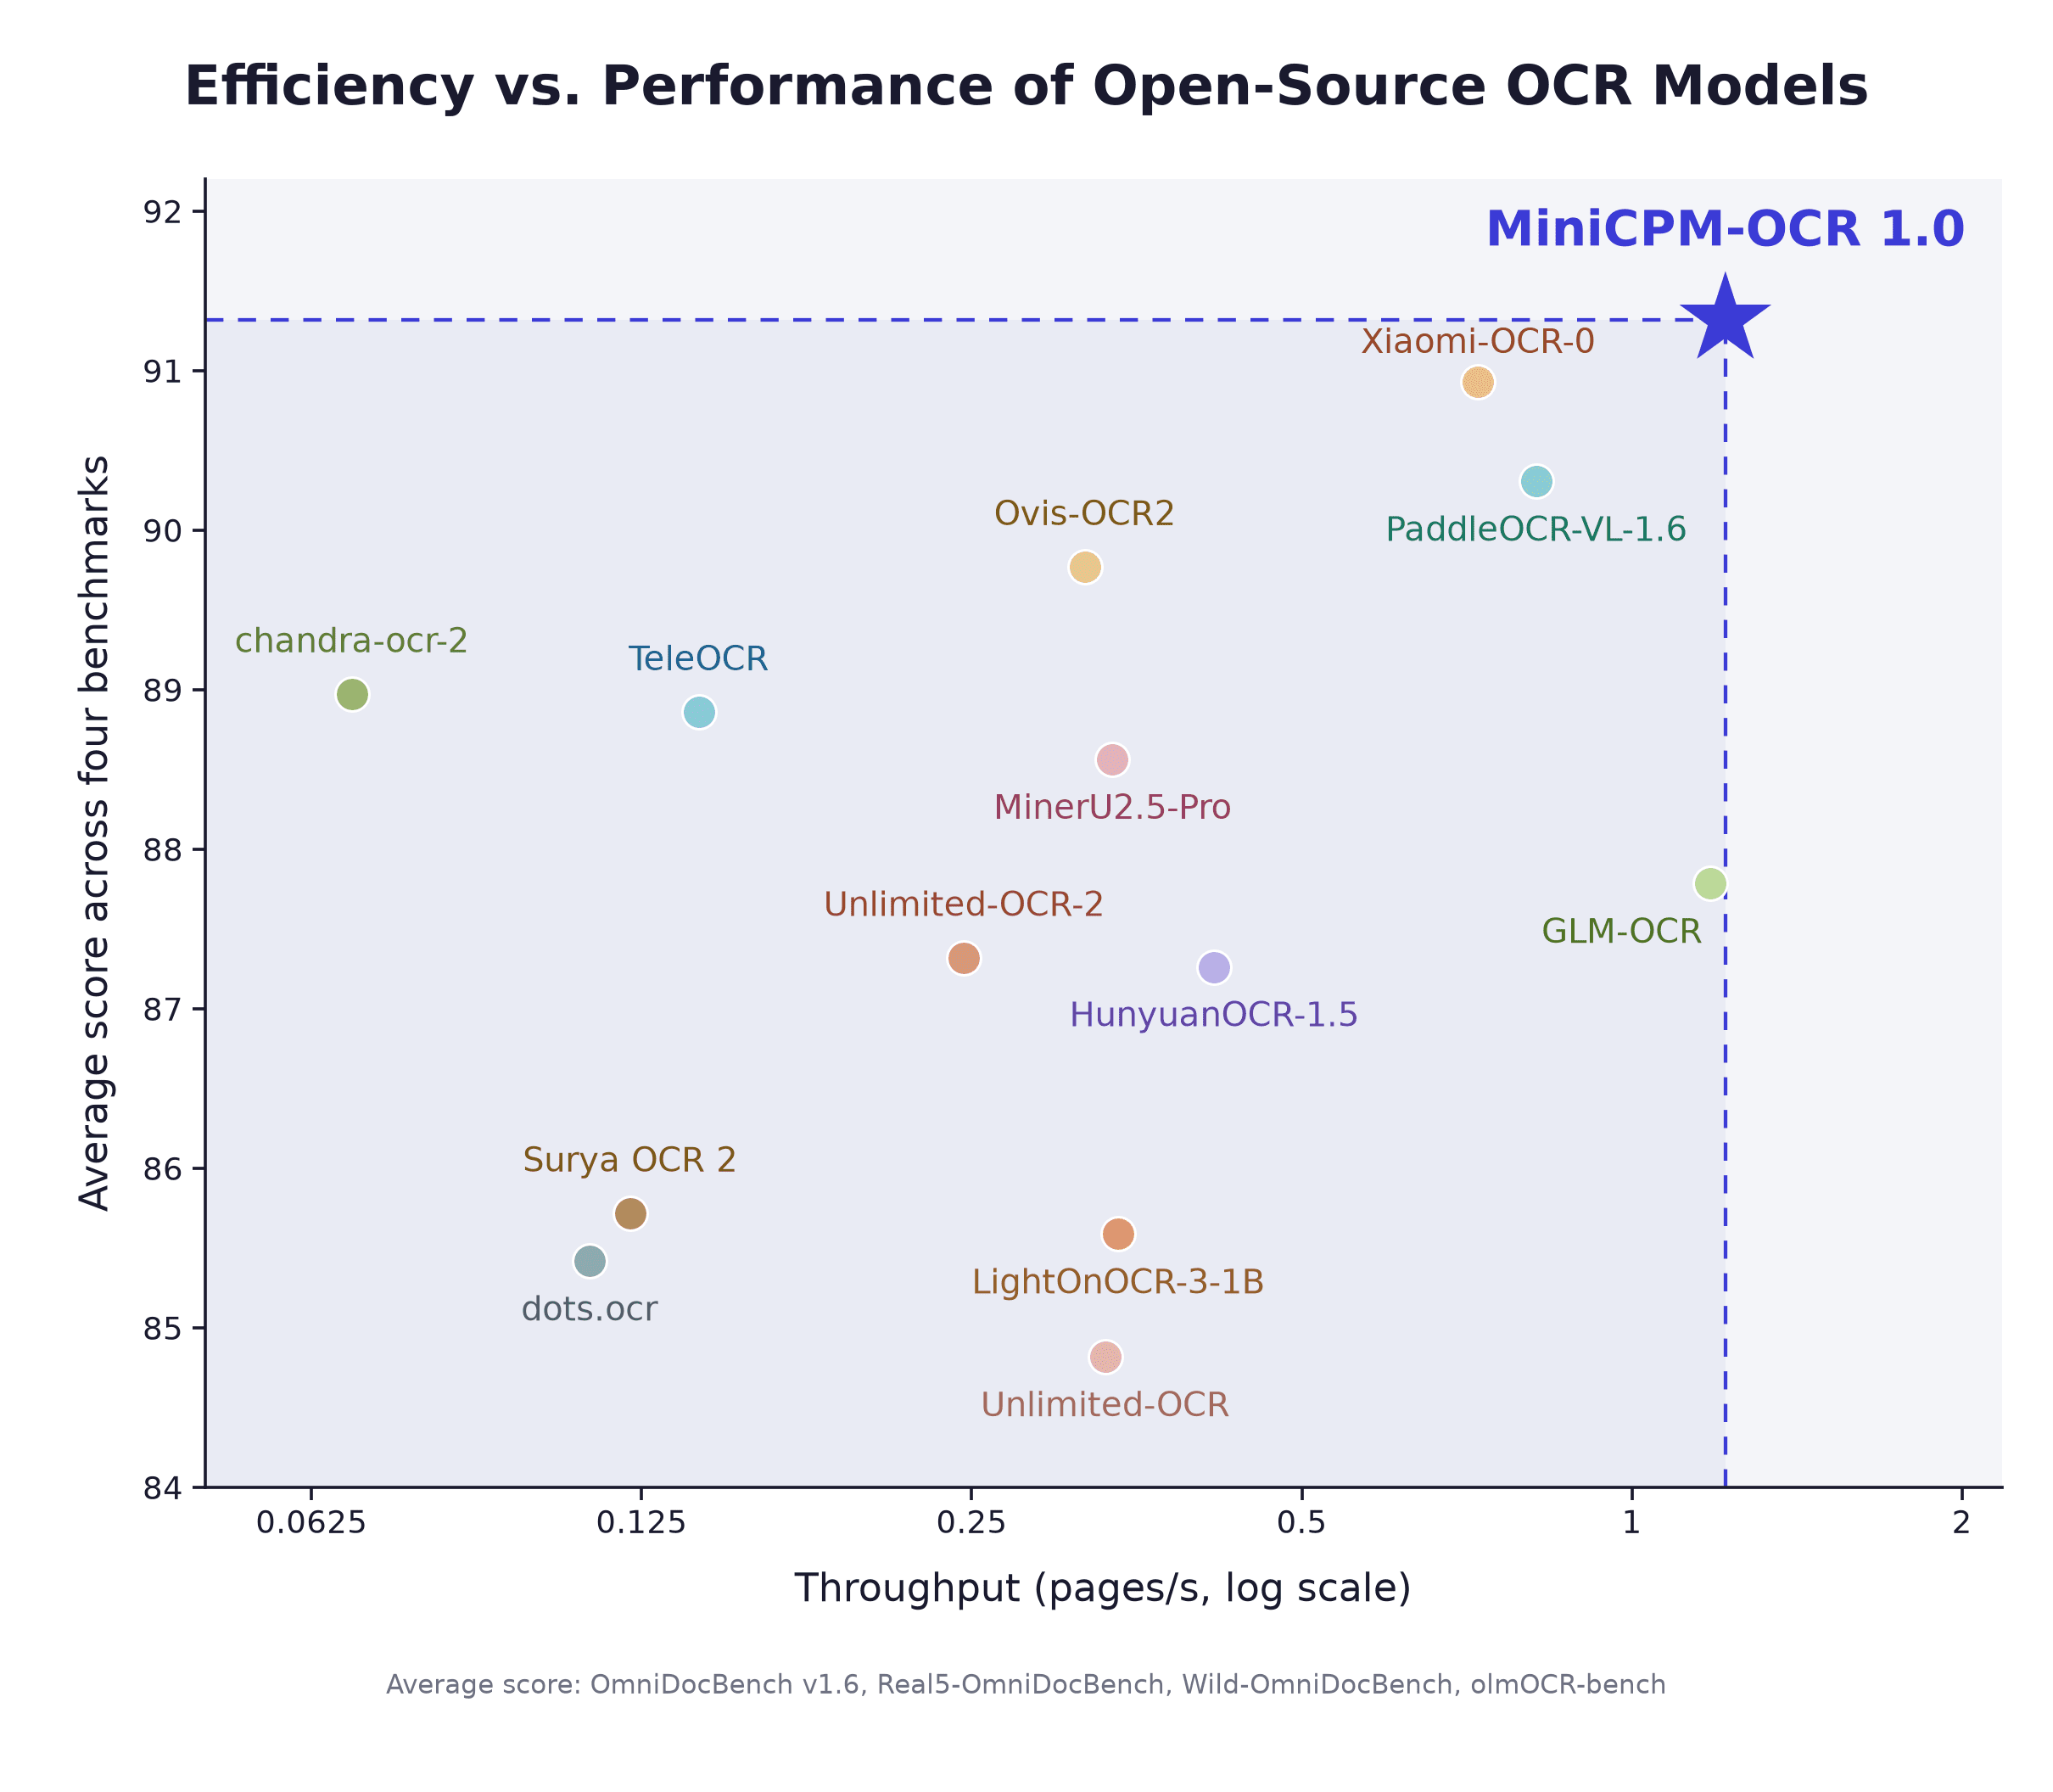
OpenBMB's MiniCPM-OCR 1.0 Targets Document Parsing
A compact vision-language model built to read tables, formulas, and complex page layouts arrives on Hugging Face.
OpenBMB's MiniCPM-V 4.7 brings MoE to vision models
The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.
MiniCPM-V 4.7 brings a 35B MoE vision model on-device
OpenBMB's latest multimodal release activates just 3B parameters per token, aiming to keep capable image understanding local.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.