Tencent's UI-Mate-27B targets desktop automation
A 27B vision-language model built to see and operate graphical interfaces, tested on OSWorld and WindowsAgentArena.
Tencent has published UI-Mate-27B, a 27-billion-parameter vision-language model designed to act as a computer-use agent — reading what's on screen and carrying out multi-step tasks across desktop applications. Unlike a general-purpose chat model, it is tuned specifically for the loop of perceiving an interface, deciding on an action, and executing it.
The model is a dense (non-mixture-of-experts) VLM, placing it in the mid-size tier where capability and deployability meet. Tencent points to evaluation on two well-known agent benchmarks, OSWorld and WindowsAgentArena, which measure how reliably a system can complete real tasks inside actual operating-system environments rather than in simplified sandboxes.
Why it matters
GUI agents are one of the more demanding frontiers in applied AI: a model has to ground language in pixels, track state across steps, and recover from mistakes. Open weights in this category are still relatively scarce, so a 27B model aimed squarely at desktop control gives researchers and builders something concrete to test and fine-tune.
- Purpose-built for computer-use and GUI automation, not generic vision tasks
- 27B dense parameters, released under a custom ("other") license
- Benchmarked on OSWorld and WindowsAgentArena
As always with agent models, the practical questions — latency, reliability on unfamiliar apps, and license terms for commercial use — will determine how far UI-Mate-27B travels beyond the benchmark tables. The weights and details are available now on Hugging Face.
Sources
- Visit
tencent/UI-Mate-27B
Hugging Face
More from Tencent
All Tencent releases →Tencent's T1 Targets Long-Horizon Terminal Work
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.

Tencent Previews Hunyuan Hy4, an Apache MoE Model
The company's next-generation Hunyuan language model arrives as an early preview with a permissive license and a mixture-of-experts design.
Tencent's WeMM-Embedding-9B Unifies Text, Image and Video
The WeChat team releases a 9-billion-parameter multimodal embedding model that maps three modalities into one shared vector space.
More in Vision-Language
All Vision-Language →
Perplexity releases a 27B model for multimodal routing
The open-weight 'decider' model is designed to classify queries and route them inside Perplexity's stack.
Cloudflare's Clef brings structured decisions to open models
The new open-weight vision-language family outputs typed, structured results and arrives alongside a reinforcement-learning fine-tuning platform.
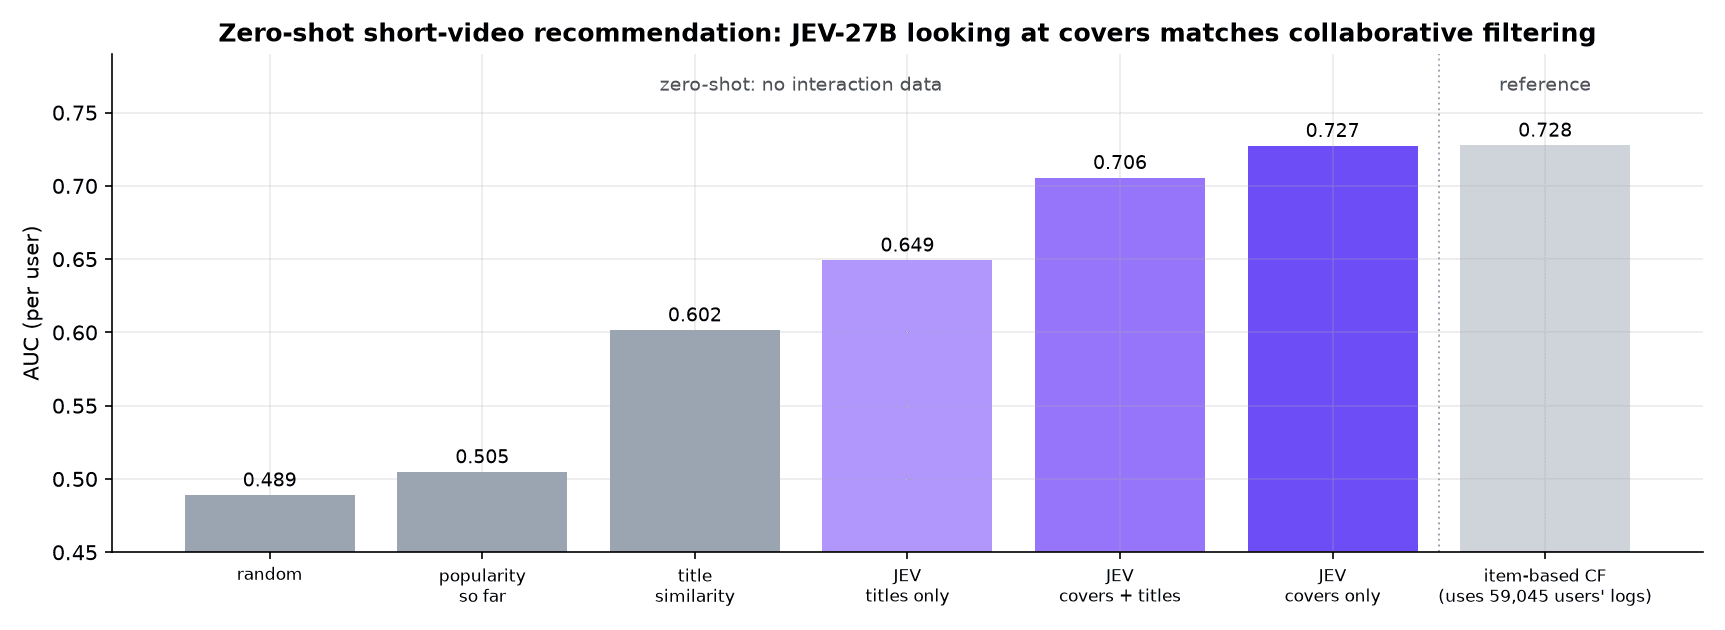
JEV-27B-VL Pairs Vision-Language With Calibrated Odds
A 27B vision-language model from autotrust aims to output typed decisions with probabilities you can actually trust.
0 comments
No comments yet. Be the first to weigh in.