StarDoc-AI Releases TeleOCR for Document Parsing
A vision-language model built on Qwen2.5-VL targets bilingual Chinese and English text extraction from documents.
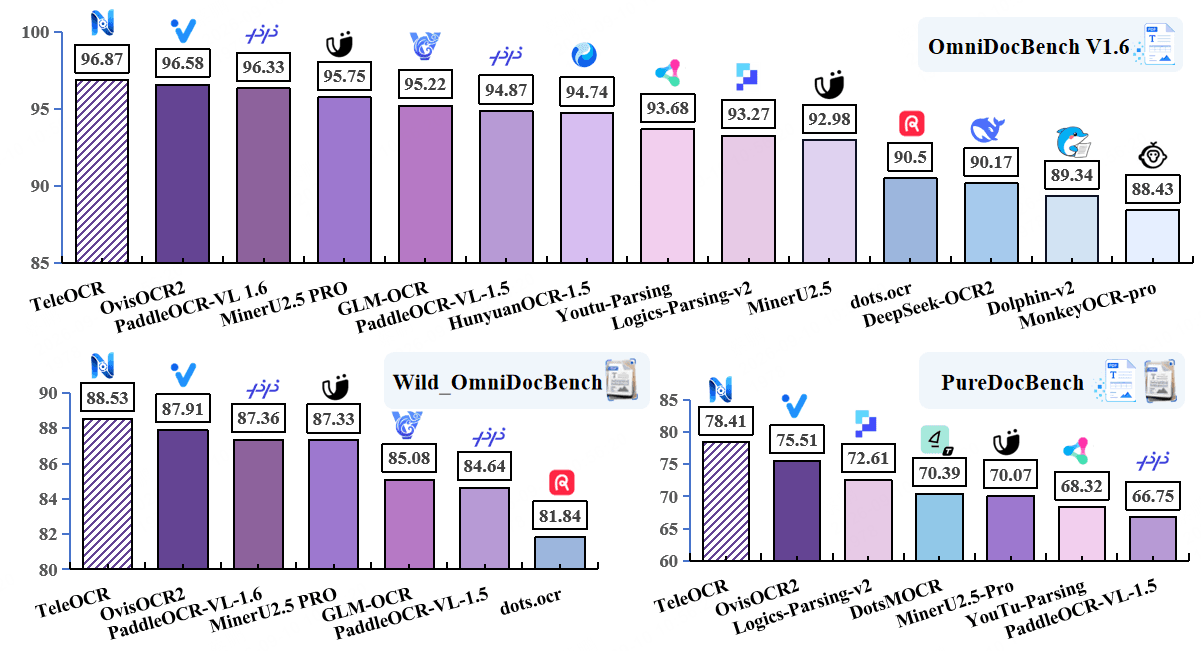
StarDoc-AI has published TeleOCR, a vision-language model aimed squarely at document parsing and optical character recognition. Built on top of Alibaba's Qwen2.5-VL foundation, the model is designed to read and extract text from documents in both Chinese and English.
OCR remains one of the most practical applications of multimodal AI. While general-purpose vision-language models can describe images and answer questions about them, document parsing demands precise handling of dense text, tables, and layout — the kind of structured extraction that businesses rely on for digitizing records, invoices, and forms.
Why it matters
By fine-tuning an established open model rather than training from scratch, StarDoc-AI inherits Qwen2.5-VL's visual grounding while specializing it for a narrower, higher-value task. Bilingual support is notable here:
- Chinese-language document OCR is underserved by many Western-built models
- English coverage keeps the model useful for cross-border workflows
- A specialized OCR model can outperform generalists on layout-heavy pages
The release arrives under a custom license, and the record does not specify parameter count or context length. Teams evaluating document-processing pipelines will want to test TeleOCR against both dedicated OCR engines and the broader family of open vision-language models before committing. The weights and details are available on the model's Hugging Face page.
Sources
- Visit
StarDoc-AI/TeleOCR
Hugging Face
More in Vision-Language
All Vision-Language →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
SenseTime previews a 9B looped-transformer VLM
SenseNova-Loop-9B-Preview puts a recurrent-depth architecture to work on multimodal reasoning.
0 comments
No comments yet. Be the first to weigh in.