Fastino releases GLiNER 2.5 Multi for extraction
A multilingual model built for structured extraction tasks like named-entity recognition, relation extraction, and JSON output.
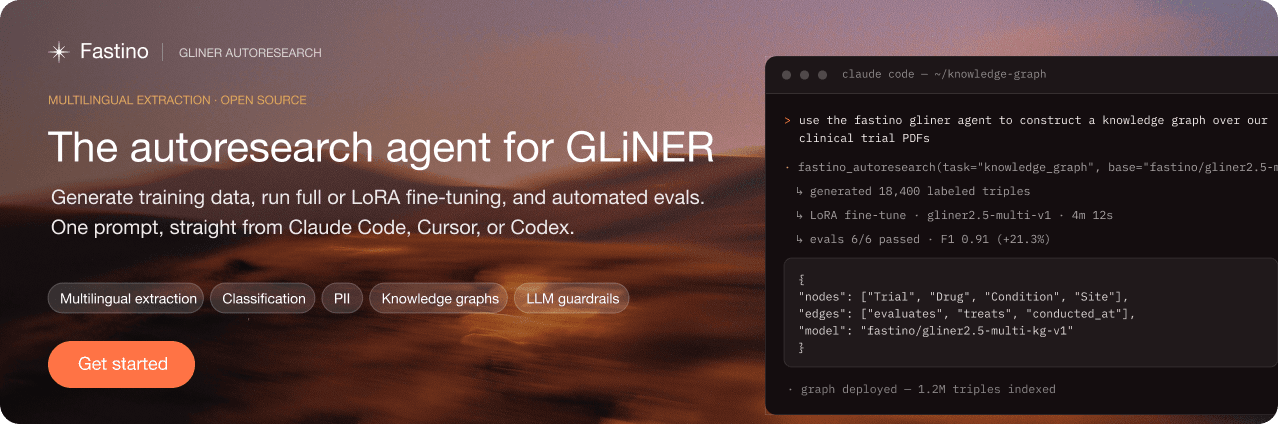
Fastino has published GLiNER 2.5 Multi on Hugging Face, a multilingual model aimed squarely at structured information extraction rather than open-ended chat. According to the release, it covers named-entity recognition, relation extraction, text classification, and JSON extraction, positioning it as a general-purpose tool for turning unstructured text into machine-readable output.
The GLiNER approach has become popular precisely because it fills a gap that large chat models handle awkwardly. Instead of prompting a general assistant and parsing its prose, developers can point a compact extraction model at documents and get consistent labeled spans and structured records. That predictability matters for pipelines feeding databases, search indexes, and downstream analytics.
Why it matters
The multilingual angle is the headline here. Extraction models often skew heavily toward English, so a single model that can identify entities and relations across languages reduces the need to maintain separate systems per locale. For teams working with mixed-language corpora, that consolidation can simplify both deployment and maintenance.
Key capabilities highlighted in the release include:
- Named-entity recognition and relation extraction
- Text classification
- JSON extraction for structured output
- Multilingual coverage
Fastino lists the model under a non-standard license, so teams should review the terms on the model page before building it into production workflows. Detailed benchmarks and parameter counts were not specified in the release, so practical evaluation on target data remains the sensible next step.
Sources
- Visit
fastino/gliner2.5-multi-v1
Hugging Face
More in Text / LLM

Ternary-Bonsai-2 packs a 27B model into 2-bit form
A ternary-quantized 27B model with hybrid attention targets on-device inference across CUDA and Metal.
Xing4.0 arrives as a 29B MoE with 4B active params
inclusionAI's new text model uses a mixture-of-experts design to keep compute low while shipping under an Apache-2.0 license.
Cactus Needle 3: tiny on-device tool-calling models
Cactus Compute's 8–29MB models aim to run automation and tool-calling entirely on-device, rivaling far larger cloud systems.
0 comments
No comments yet. Be the first to weigh in.