Skywork Releases UniPic, a Unified 1.5B Vision Model
The new autoregressive model from the Chinese AI lab can understand, generate, and edit images within a single, compact framework.
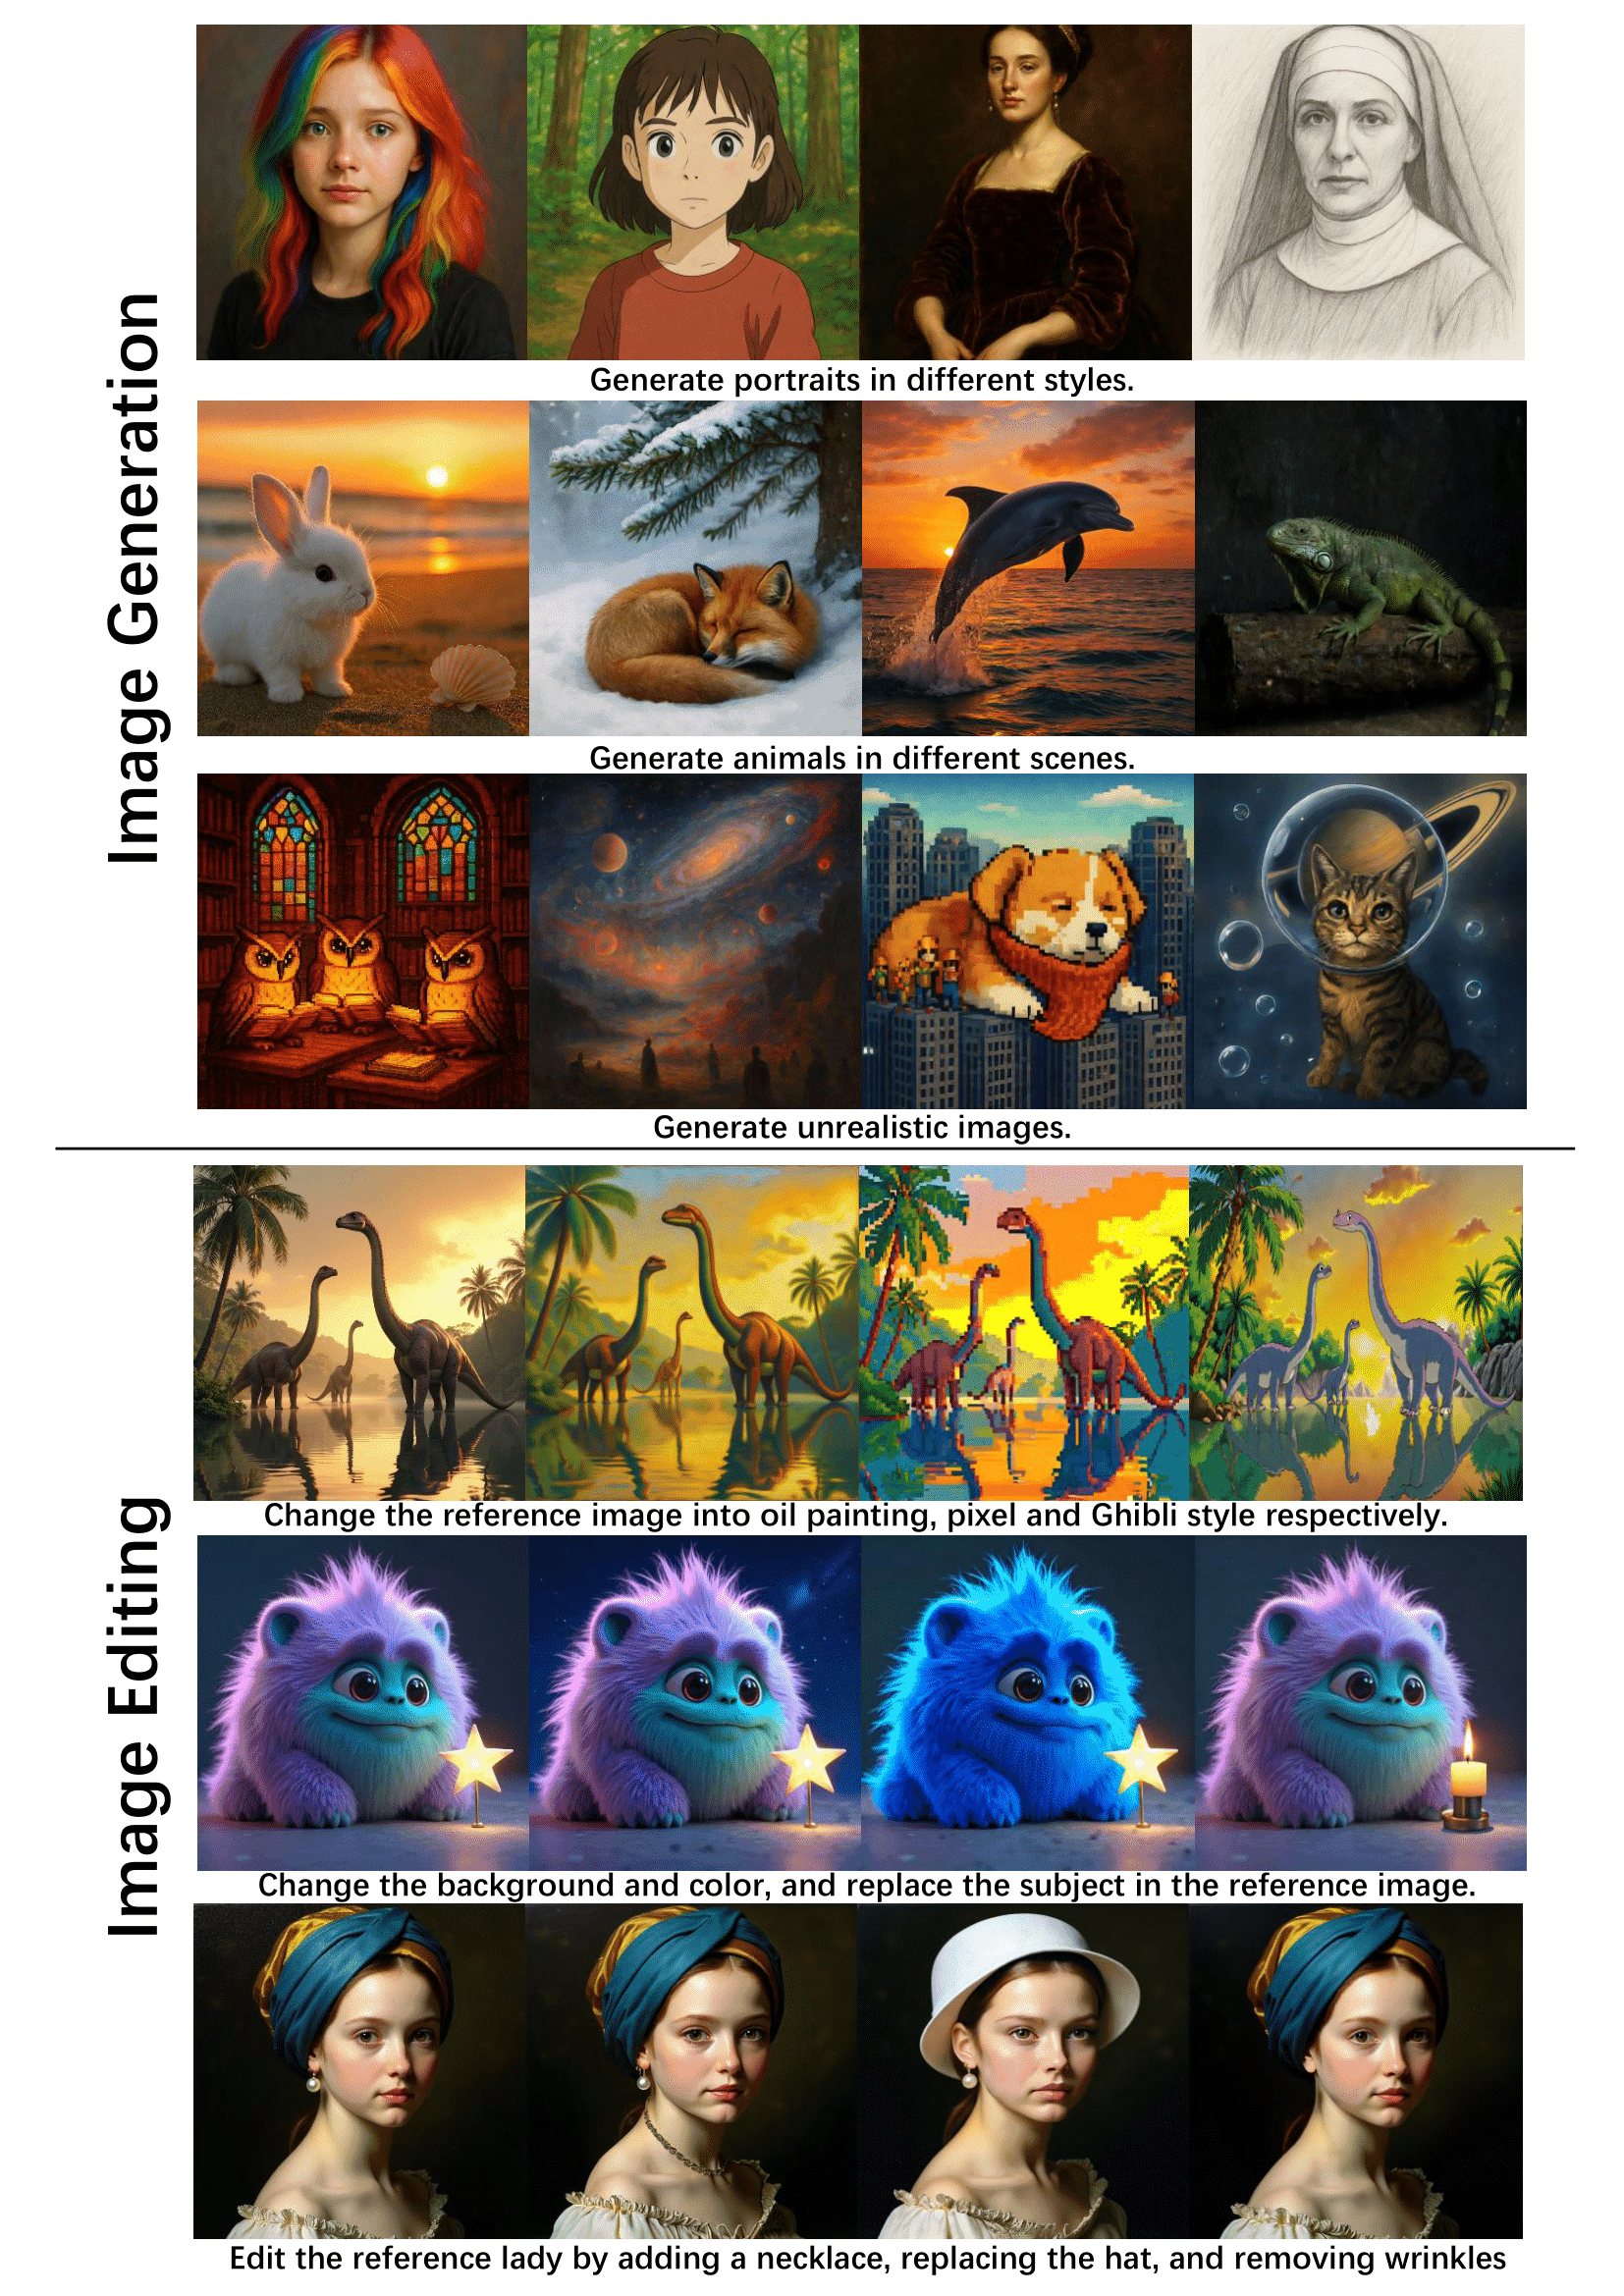
AI lab Skywork, known for its Chinese-language LLMs, has released Skywork-UniPic-1.5B, a compact multimodal model designed to handle a variety of vision tasks within a single architecture. At just 1.5 billion parameters, UniPic uses a unified autoregressive approach to process and create images, a departure from more specialized, single-task models.
The key feature of UniPic is its versatility. Instead of requiring separate models for different functions, it integrates several core capabilities into one system. This multi-task design represents a growing trend towards more efficient and generalized AI systems that can reason about and manipulate visual data more holistically.
A Unified Vision Framework
UniPic is capable of performing three primary functions:
- Image Understanding: The model can interpret the content of an image and answer questions about it.
- Image Generation: It can create new images from descriptive text prompts.
- Image Editing: It can modify existing images based on user instructions.
The model, code, and further details are available on the project's Hugging Face repository. It is released under the Skywork License Agreement, which allows for research and commercial use with certain restrictions. Its relatively small size could make it an accessible tool for researchers and developers experimenting with unified vision architectures.
Sources
- Visit
Skywork/Skywork-UniPic-1.5B
Hugging Face
More in Any-to-Any
StepFun's StepAudio 3 Realtime targets live voice AI
The audio-language foundation model builds a listen-converse-think-act loop aimed at natural, low-latency spoken interaction.
SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.

SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
0 comments
No comments yet. Be the first to weigh in.