NVIDIA's Nemotron VoiceChat 11B Targets Spoken AI
An 11-billion-parameter voice conversation model built atop Nemotron Nano 9B v2 arrives on Hugging Face.
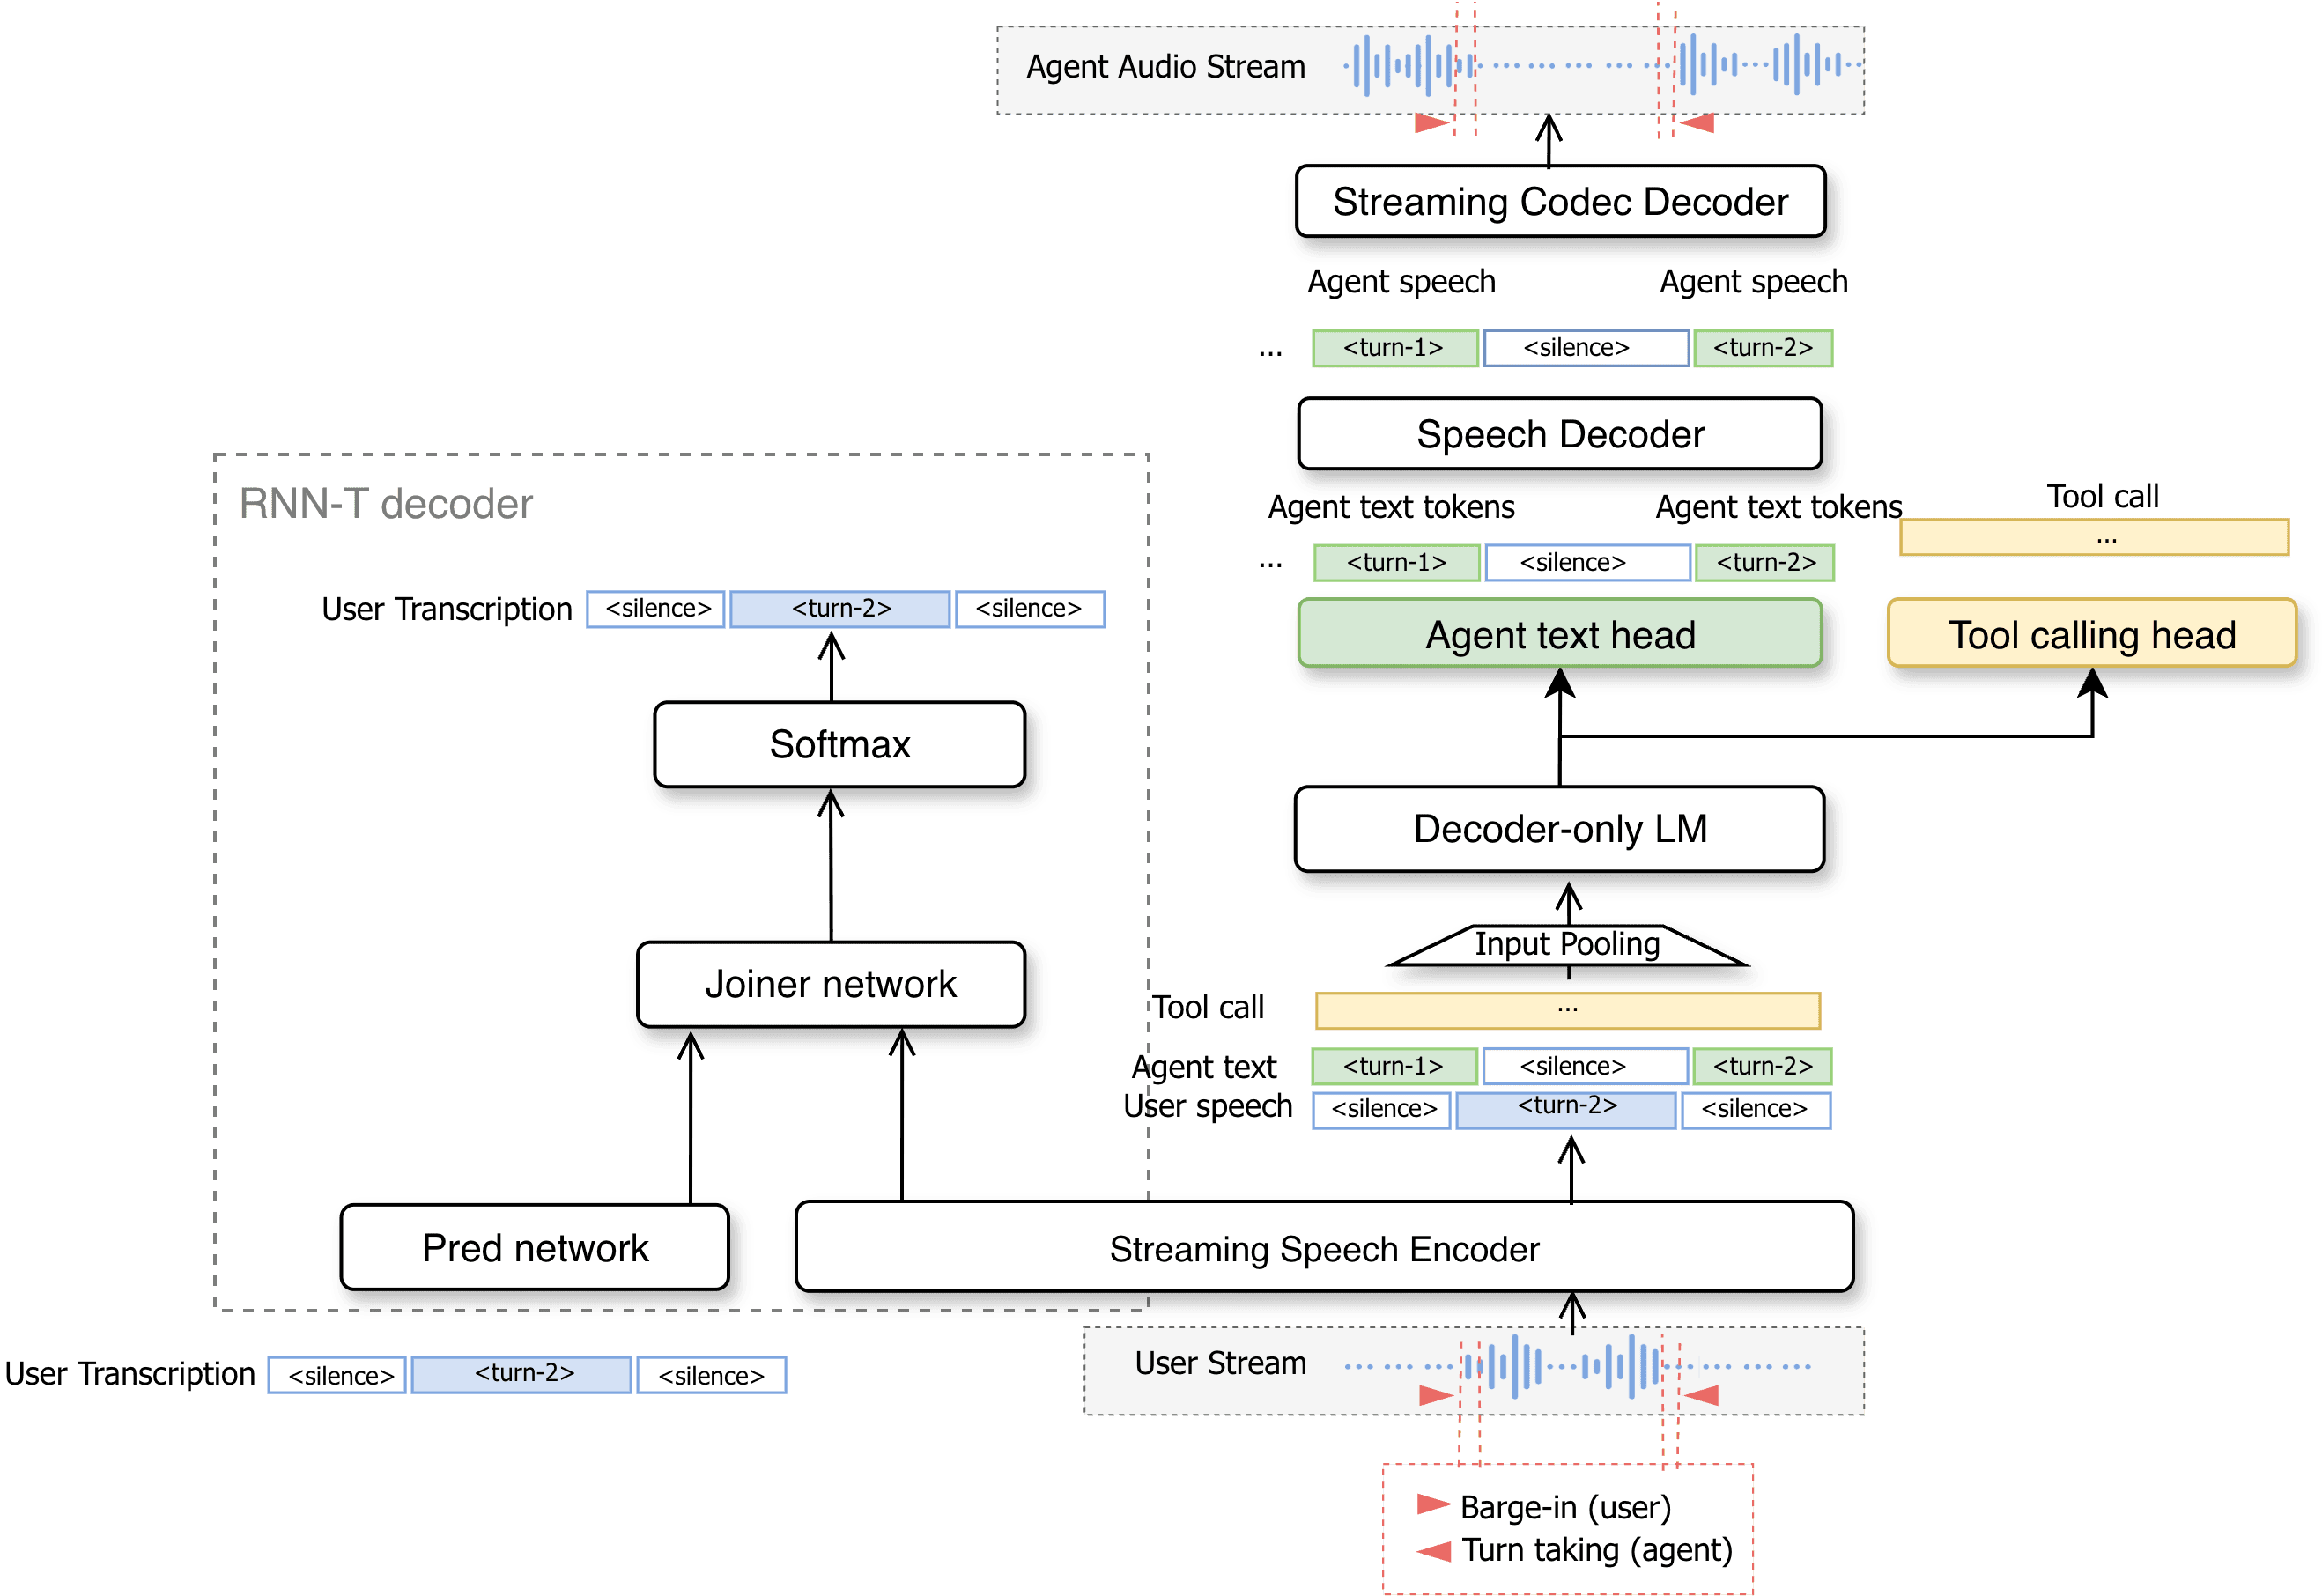
NVIDIA has published Nemotron VoiceChat 11B, a voice conversation model that extends the company's growing Nemotron family into spoken interaction. According to the release, the model is built on top of Nemotron Nano 9B v2, NVIDIA's compact language backbone, and is tuned for text-to-speech and multimodal exchanges.
The model weighs in at roughly 11 billion parameters and is a dense (non-MoE) architecture. Its listed focus is English, and its primary modality is audio generation, positioning it as a component for building voice-driven assistants rather than a general-purpose chatbot.
Why it matters
Voice remains one of the harder problems in open model releases, where most of the momentum has centered on text and image generation. A mid-sized voice conversation model built on an existing, efficiency-minded language backbone is notable for a few reasons:
- It reuses Nemotron Nano 9B v2, suggesting a path to voice on hardware that cannot run frontier-scale systems.
- An 11B footprint is small enough to be practical for on-device or single-GPU deployment.
- English-only support keeps the initial scope narrow but focused.
As with other Nemotron models, the release carries a custom "other" license, so teams evaluating it for production should read the terms on the model card closely before committing. NVIDIA has not published detailed benchmark figures alongside this initial drop, leaving real-world quality an open question for early adopters to test.
Sources
- Visit
nvidia/NVIDIA-NemotronLabs-VoiceChat-11B
Hugging Face
More from NVIDIA
All NVIDIA releases →
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
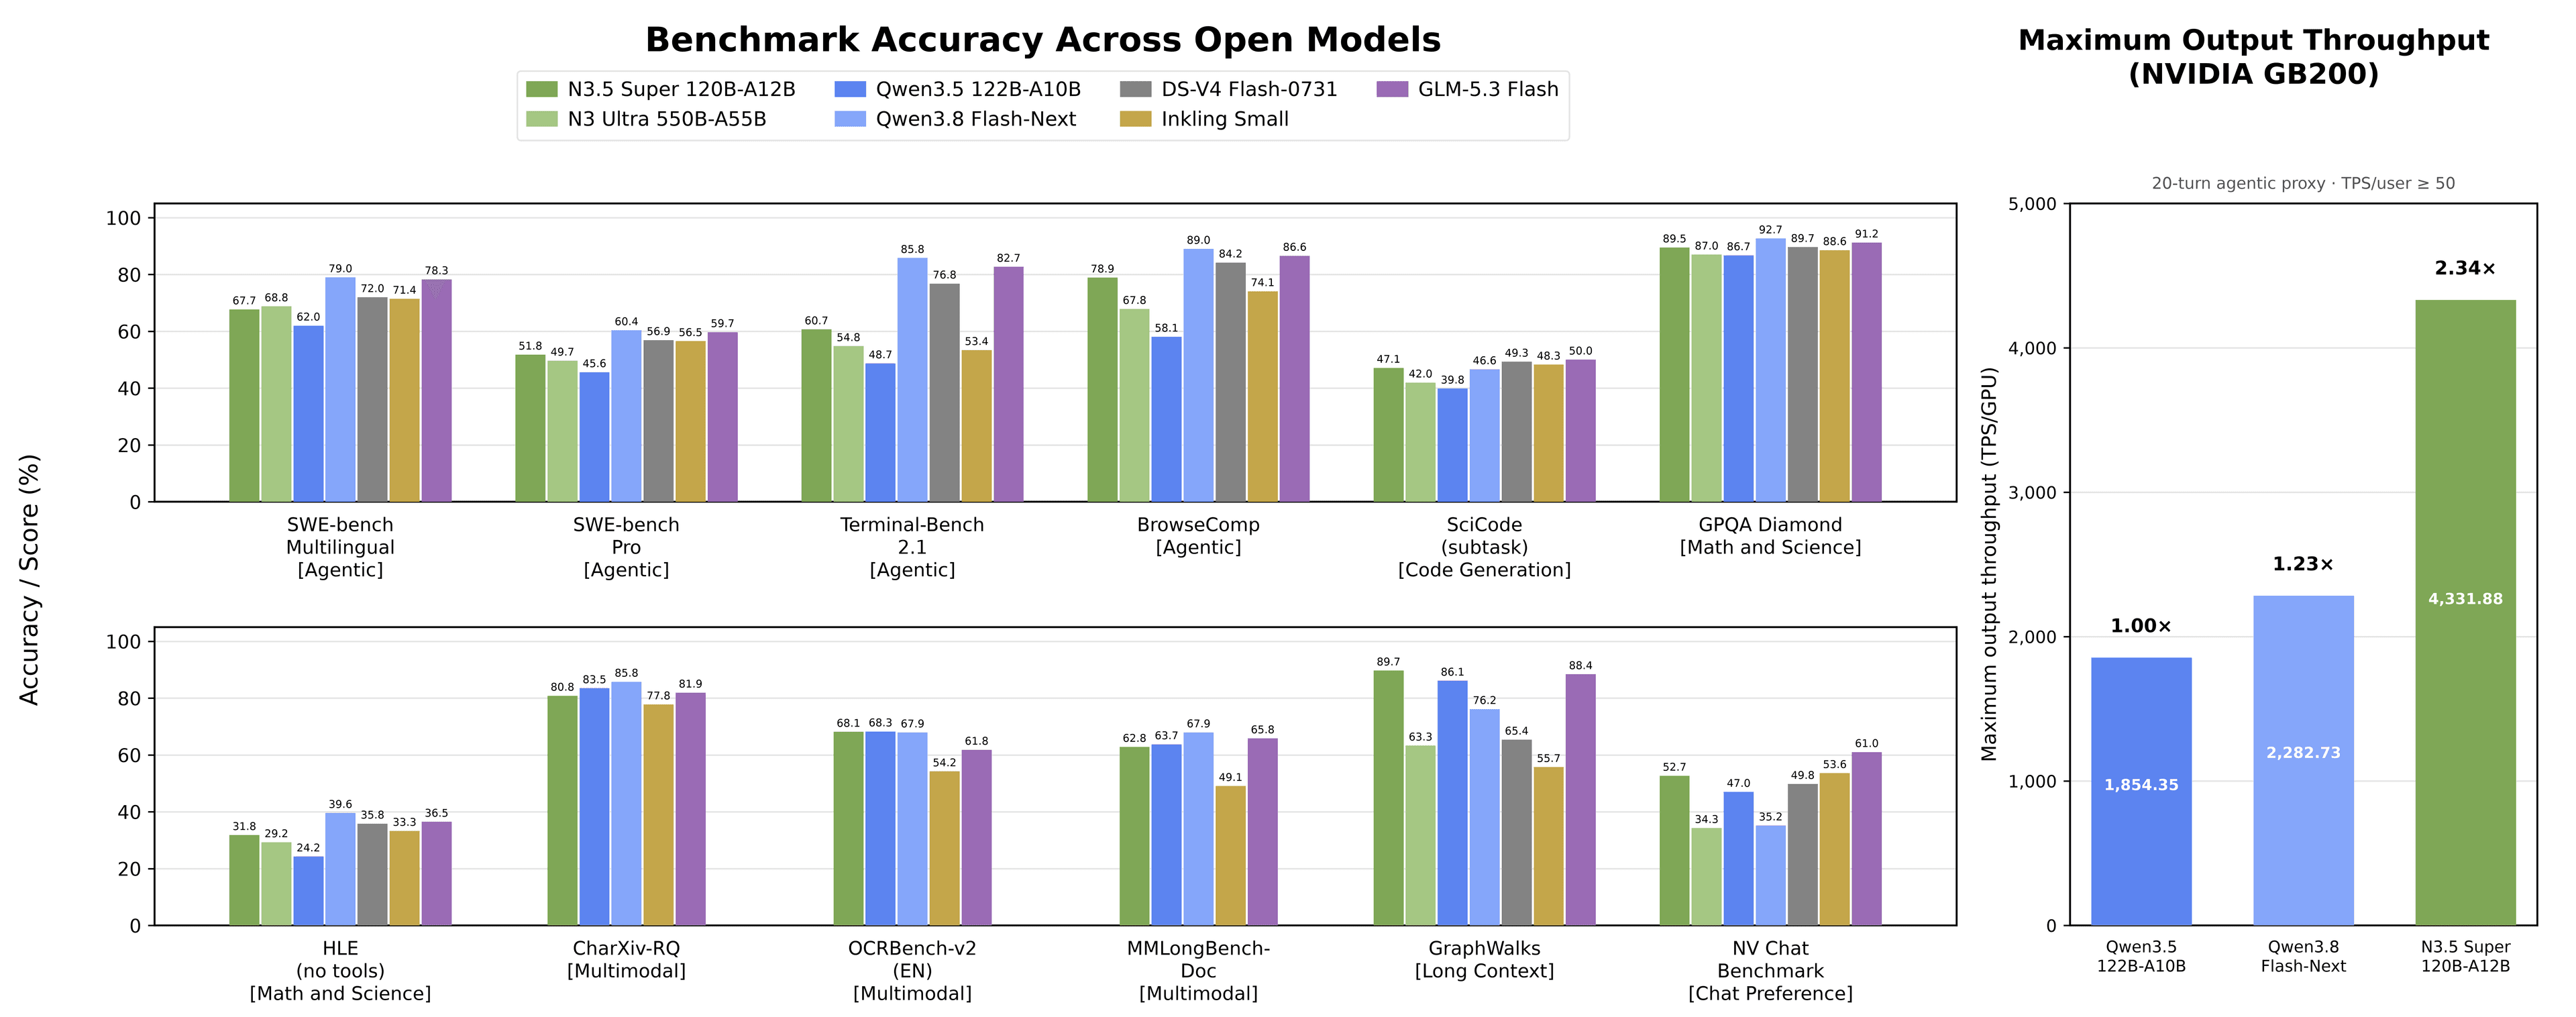
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
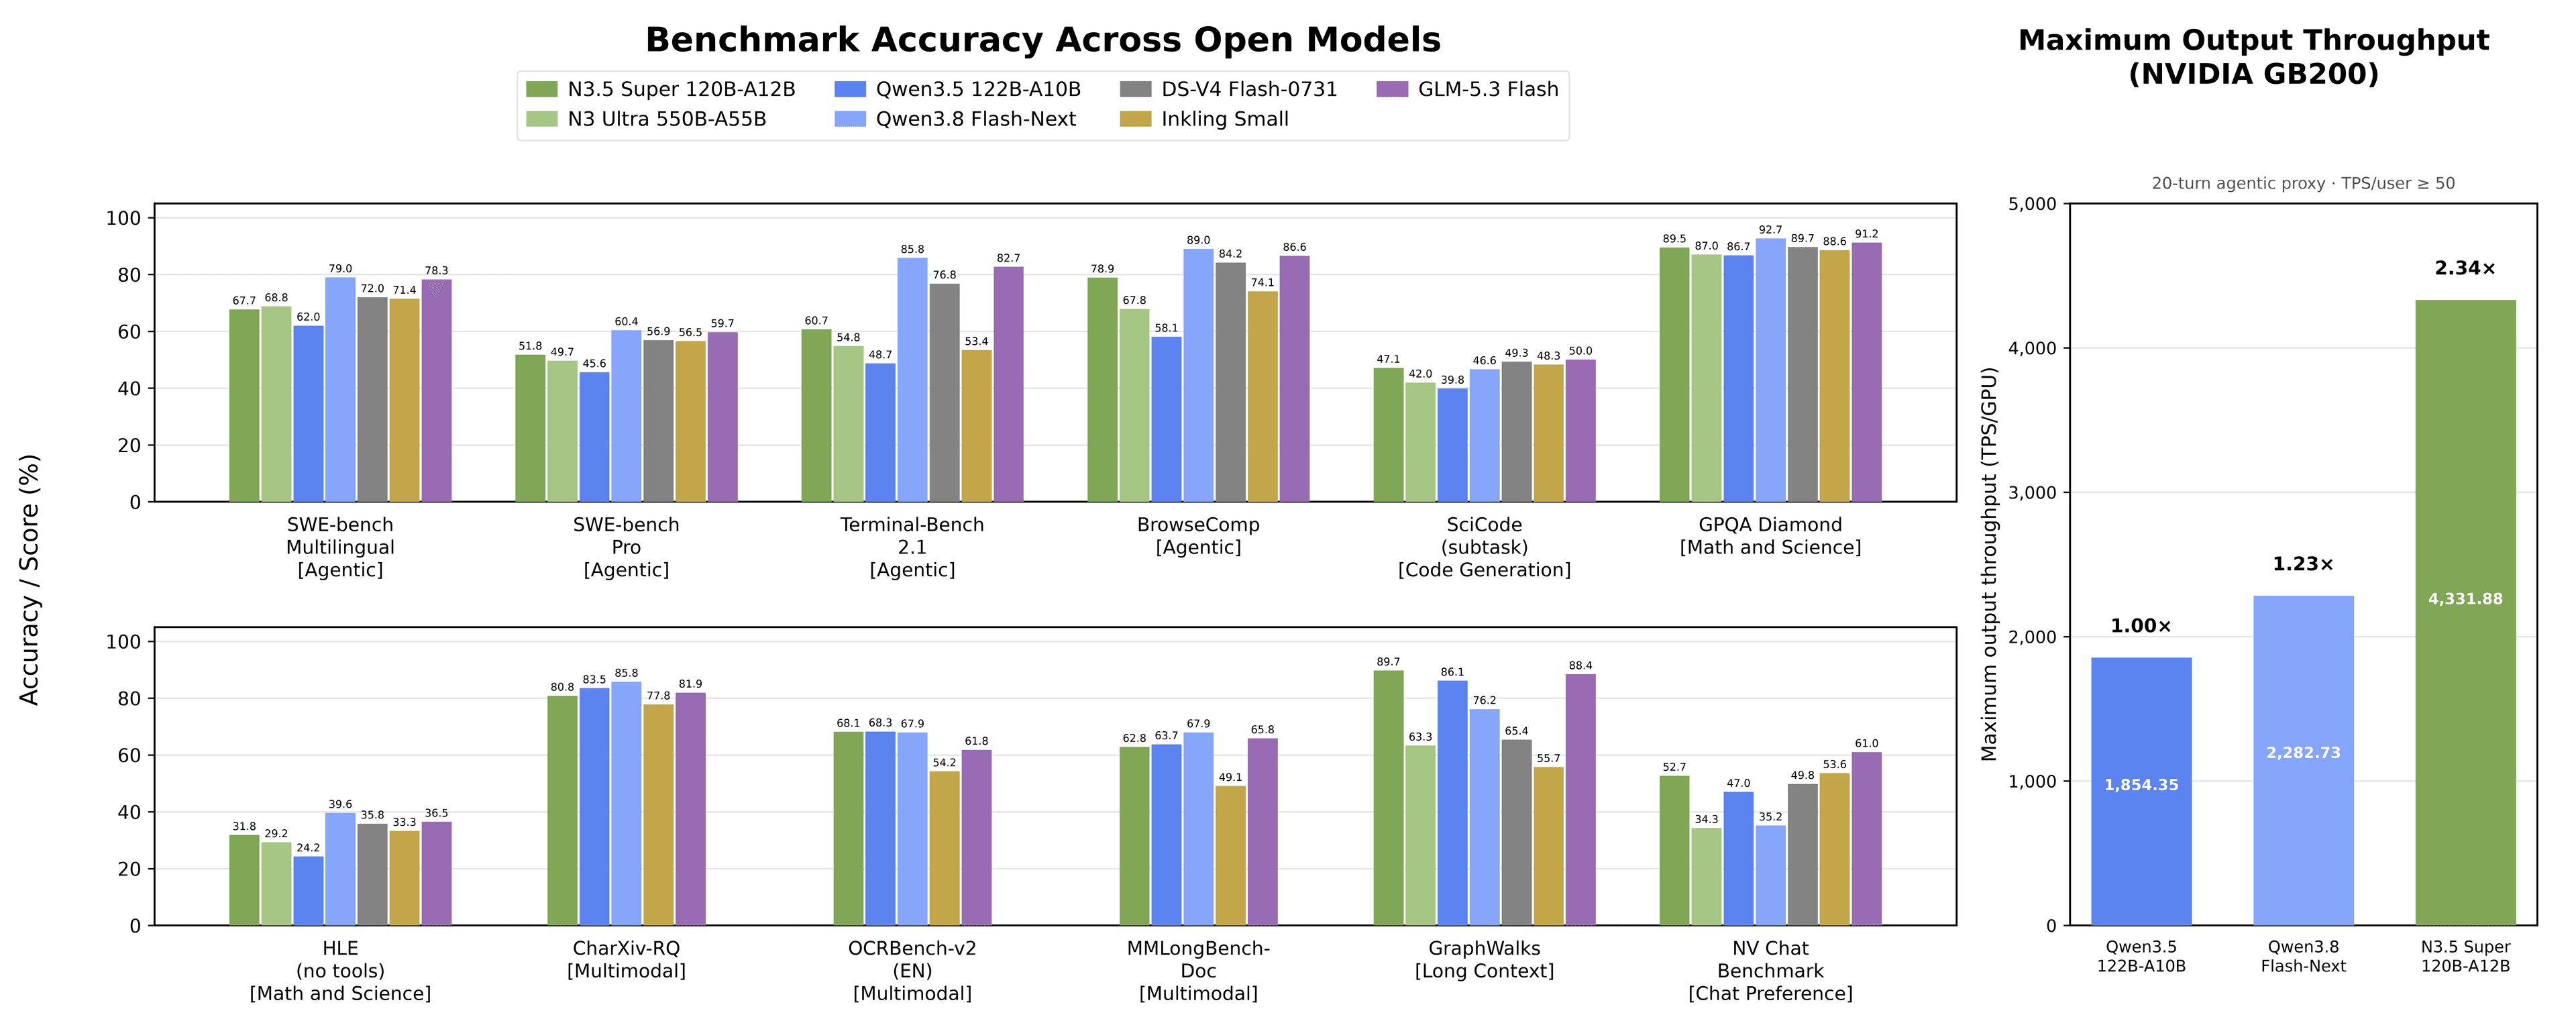
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
More in Text → Speech
All Text → Speech →ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.