Baidu Releases NAVA for Text-to-Video with Audio
The new model from the Chinese tech giant uses a Multimodal Diffusion Transformer to generate synchronized audio and video from text or image prompts.
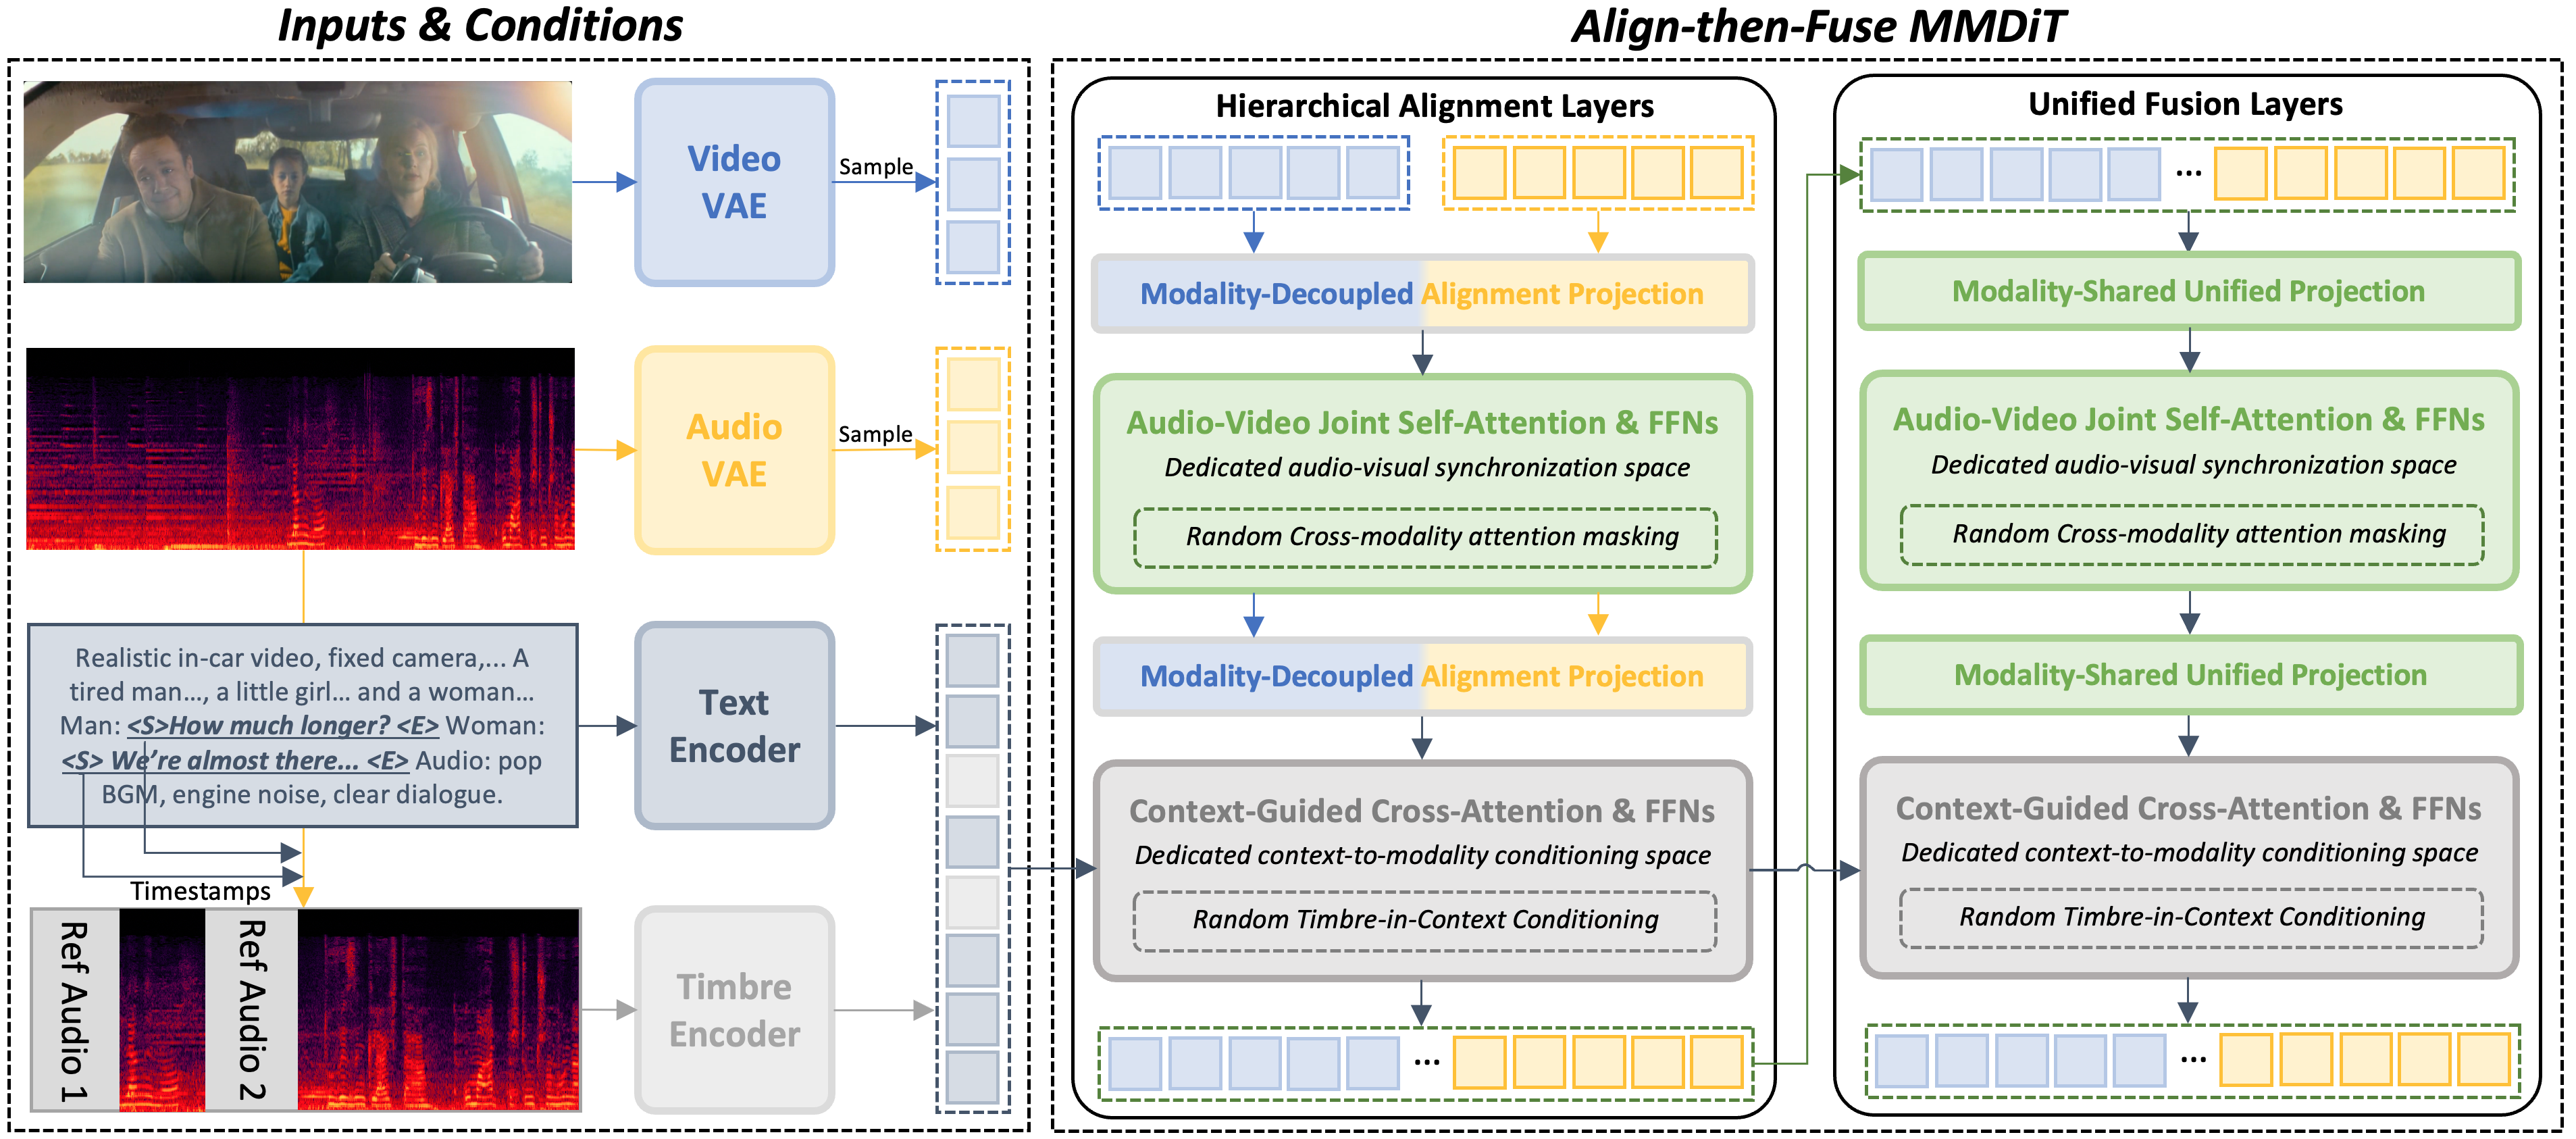
Baidu has released the weights for NAVA, a new generative model capable of producing video complete with synchronized audio from a variety of inputs. NAVA, which stands for Native Audio-Video Animation, can take either a text prompt or a combination of text and an image to generate short video clips. The model and examples are available on its Hugging Face repository.
Under the hood, NAVA employs a sophisticated architecture known as a Multimodal Diffusion Transformer (MMDiT). This design allows the model to process and integrate different data types—like text and image features—within the same transformer blocks, creating a more cohesive understanding of the prompt. The model is built upon Baidu's own Wan2.2 video foundation model, extending its capabilities into multimodal generation.
A More Efficient Method
Instead of traditional diffusion methods, NAVA is trained using a flow-matching technique. This is a more recent approach to training generative models that can lead to more efficient training and faster inference times, as it learns the direct path from noise to a final, coherent output. This choice of technique points to a growing trend toward more computationally efficient generative architectures.
The release of NAVA adds another significant open-weights model to the competitive text-to-video landscape. Its ability to generate audio natively alongside video is a key differentiator, as audio is often a separate, post-processing step for other models. While the model is publicly available, it uses a custom license, so developers and researchers should review the terms before incorporating it into their work.
Sources
- Visit
baidu/NAVA
Hugging Face
More from Baidu
All Baidu releases →
Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
Baidu's PP-OCRv6 packs 50-language OCR into tiny models
The latest release of PaddlePaddle's optical character recognition suite spans models from 1.5M to 34.5M parameters under an Apache 2.0 license.
Baidu releases Unlimited-OCR under permissive MIT license
The Chinese tech giant's multilingual vision-language model targets text extraction across languages and document types.
More in Text → Video
All Text → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
0 comments
No comments yet. Be the first to weigh in.