Baidu Releases Qianfan-OCR for Document Intelligence
The new vision-language model from the Chinese tech giant is designed for complex, multilingual optical character recognition and layout analysis.
Chinese technology company Baidu has released Qianfan-OCR, a new vision-language model specialized for optical character recognition and document understanding. The model is aimed at developers who need to extract text and structural information from complex documents across multiple languages.
As a document intelligence model, Qianfan-OCR is designed to go beyond simple text transcription. Its capabilities include recognizing tables, analyzing page layouts, and handling a wide variety of languages. This makes it suitable for digitizing complex materials like invoices, structured forms, and academic papers that mix text with other elements.
A New Tool for Digitization
The release adds a powerful new option to the growing ecosystem of open models for document processing. Baidu's entry provides a strong multilingual solution for enterprise and archival applications where documents often contain complex formatting. This is a critical task for businesses looking to automate data entry and researchers digitizing large volumes of text.
The model weights and usage instructions are available on the Hugging Face Hub. Potential users should note that it is released under a custom End User License Agreement, which may place restrictions on certain use cases compared to more permissive open-source licenses.
Sources
- Visit
baidu/Qianfan-OCR
Hugging Face
More from Baidu
All Baidu releases →
Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
Baidu's PP-OCRv6 packs 50-language OCR into tiny models
The latest release of PaddlePaddle's optical character recognition suite spans models from 1.5M to 34.5M parameters under an Apache 2.0 license.
Baidu releases Unlimited-OCR under permissive MIT license
The Chinese tech giant's multilingual vision-language model targets text extraction across languages and document types.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
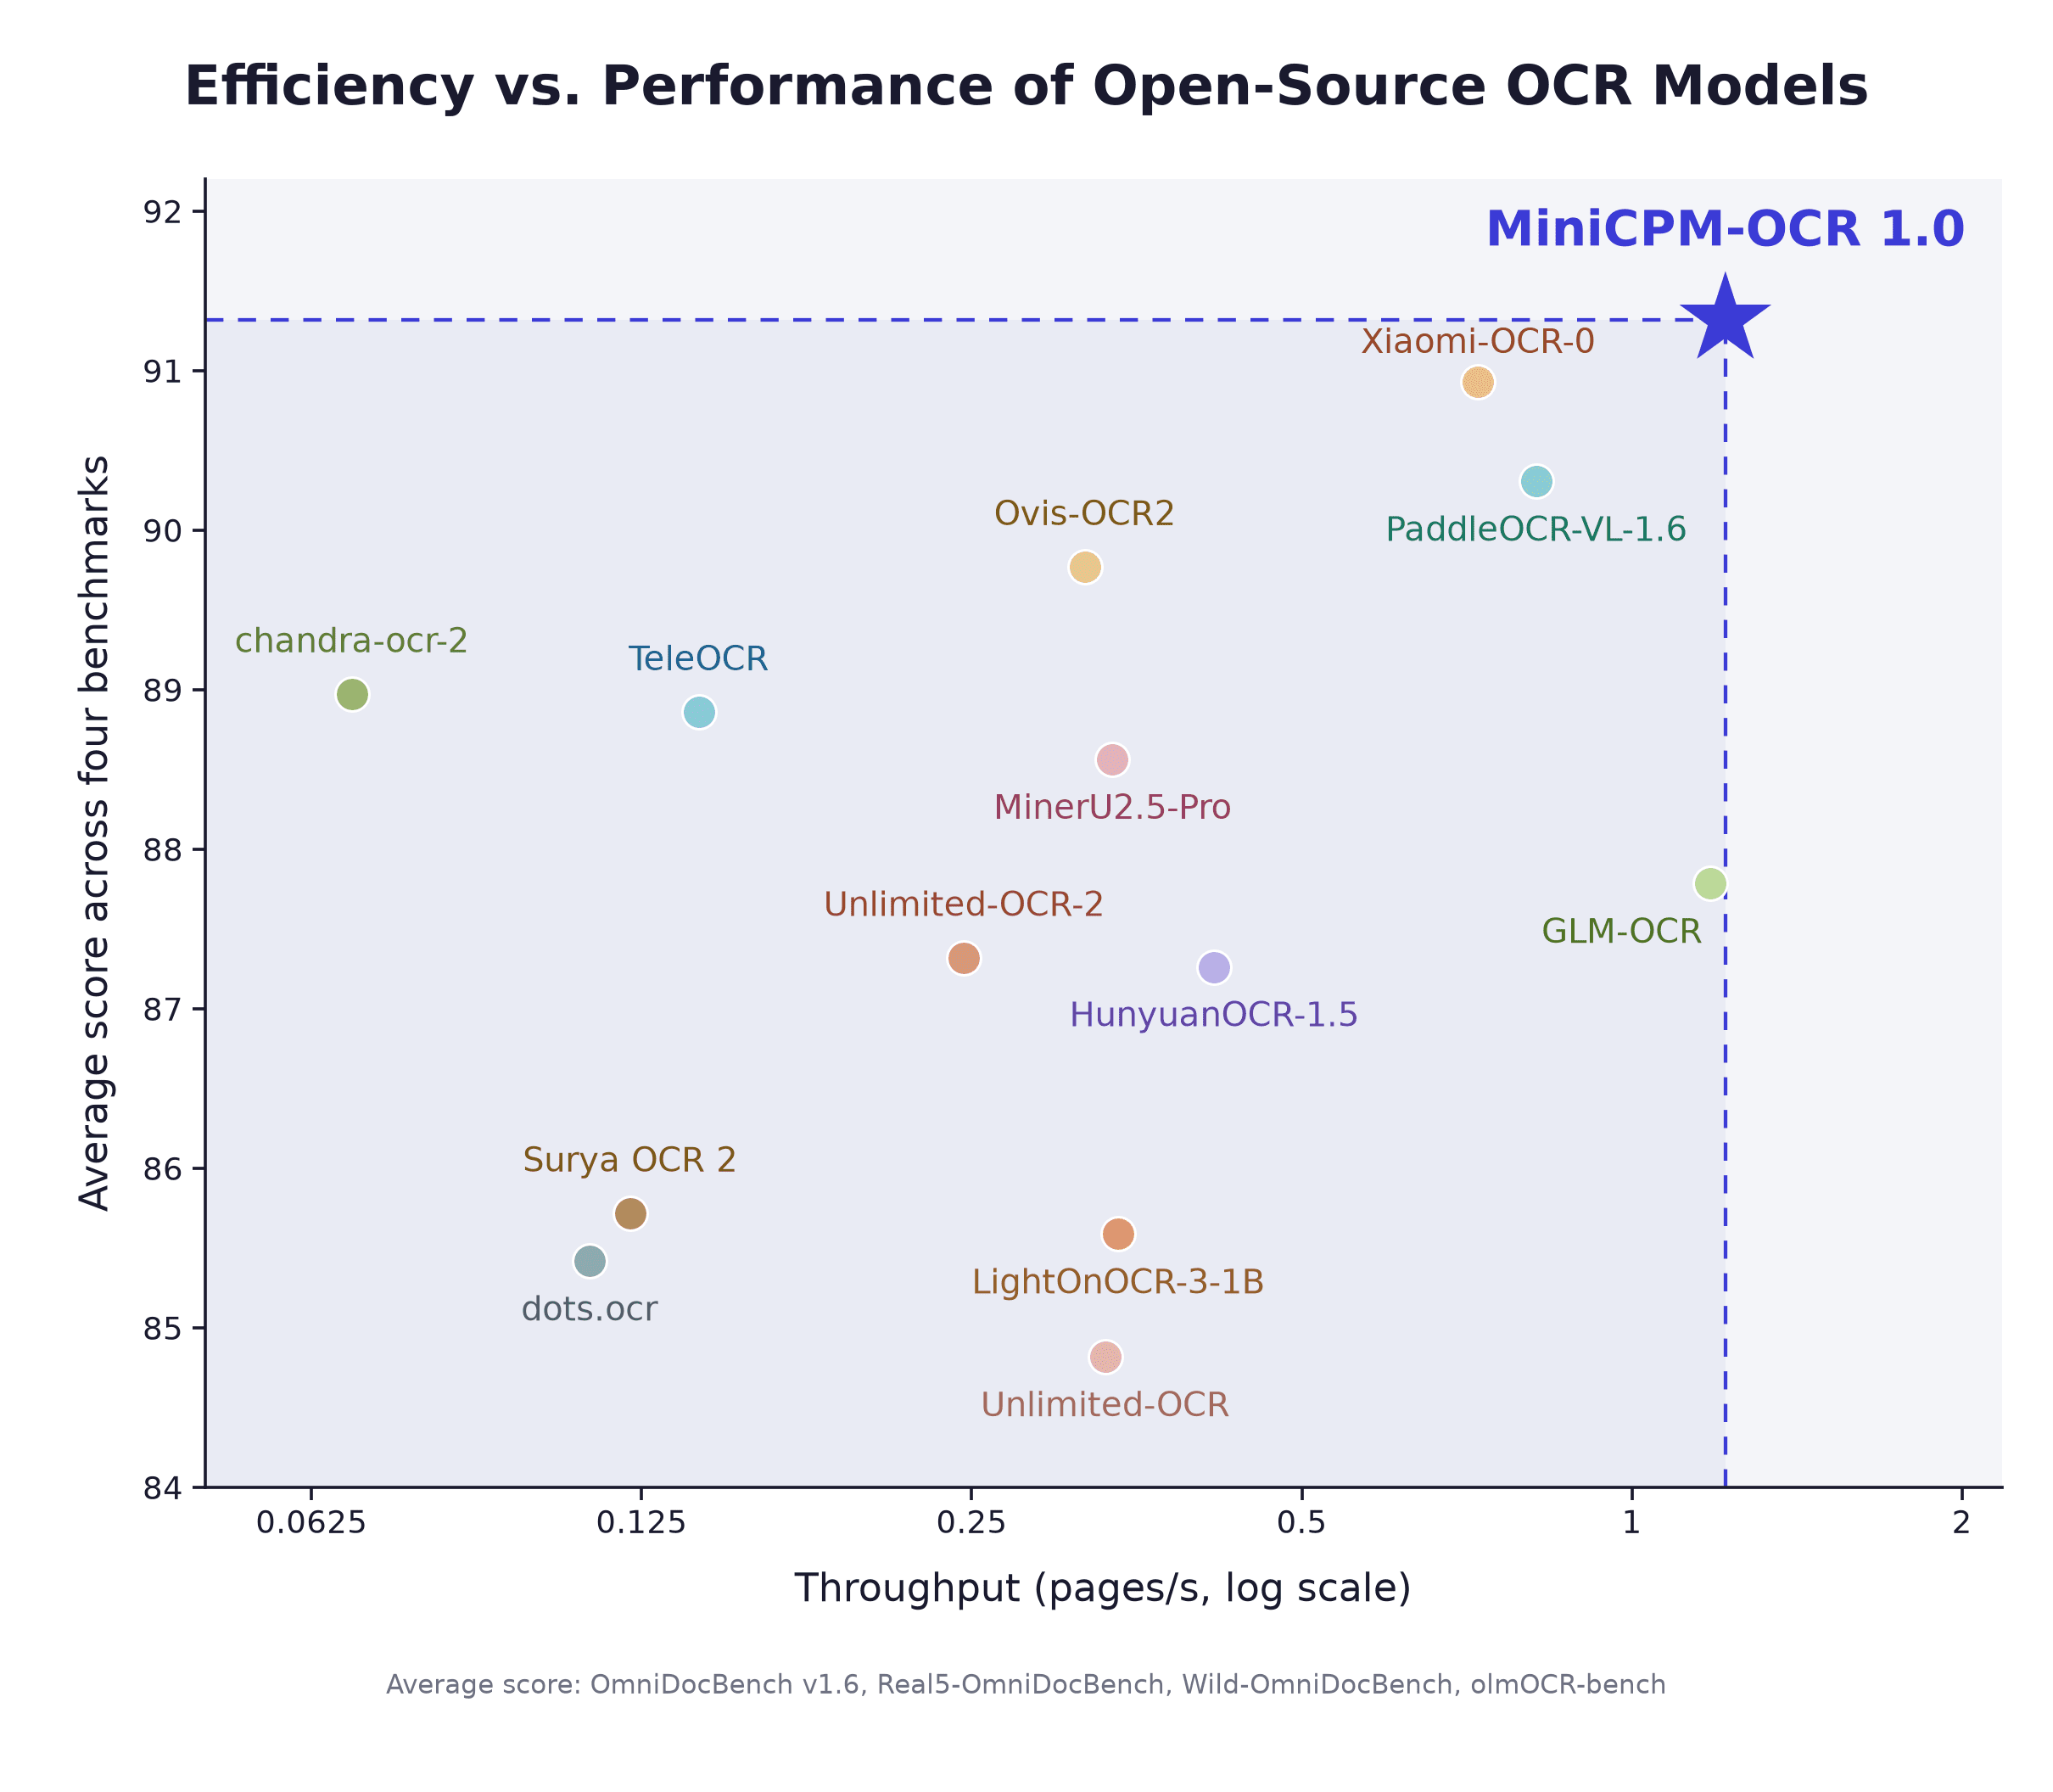
OpenBMB's MiniCPM-OCR 1.0 Targets Document Parsing
A compact vision-language model built to read tables, formulas, and complex page layouts arrives on Hugging Face.
0 comments
No comments yet. Be the first to weigh in.