OpenMOSS Releases MOVA for Joint Video and Audio Gen
The new model generates 360p video from text or images and creates corresponding audio tracks simultaneously, a notable step for integrated audiovisual synthesis.
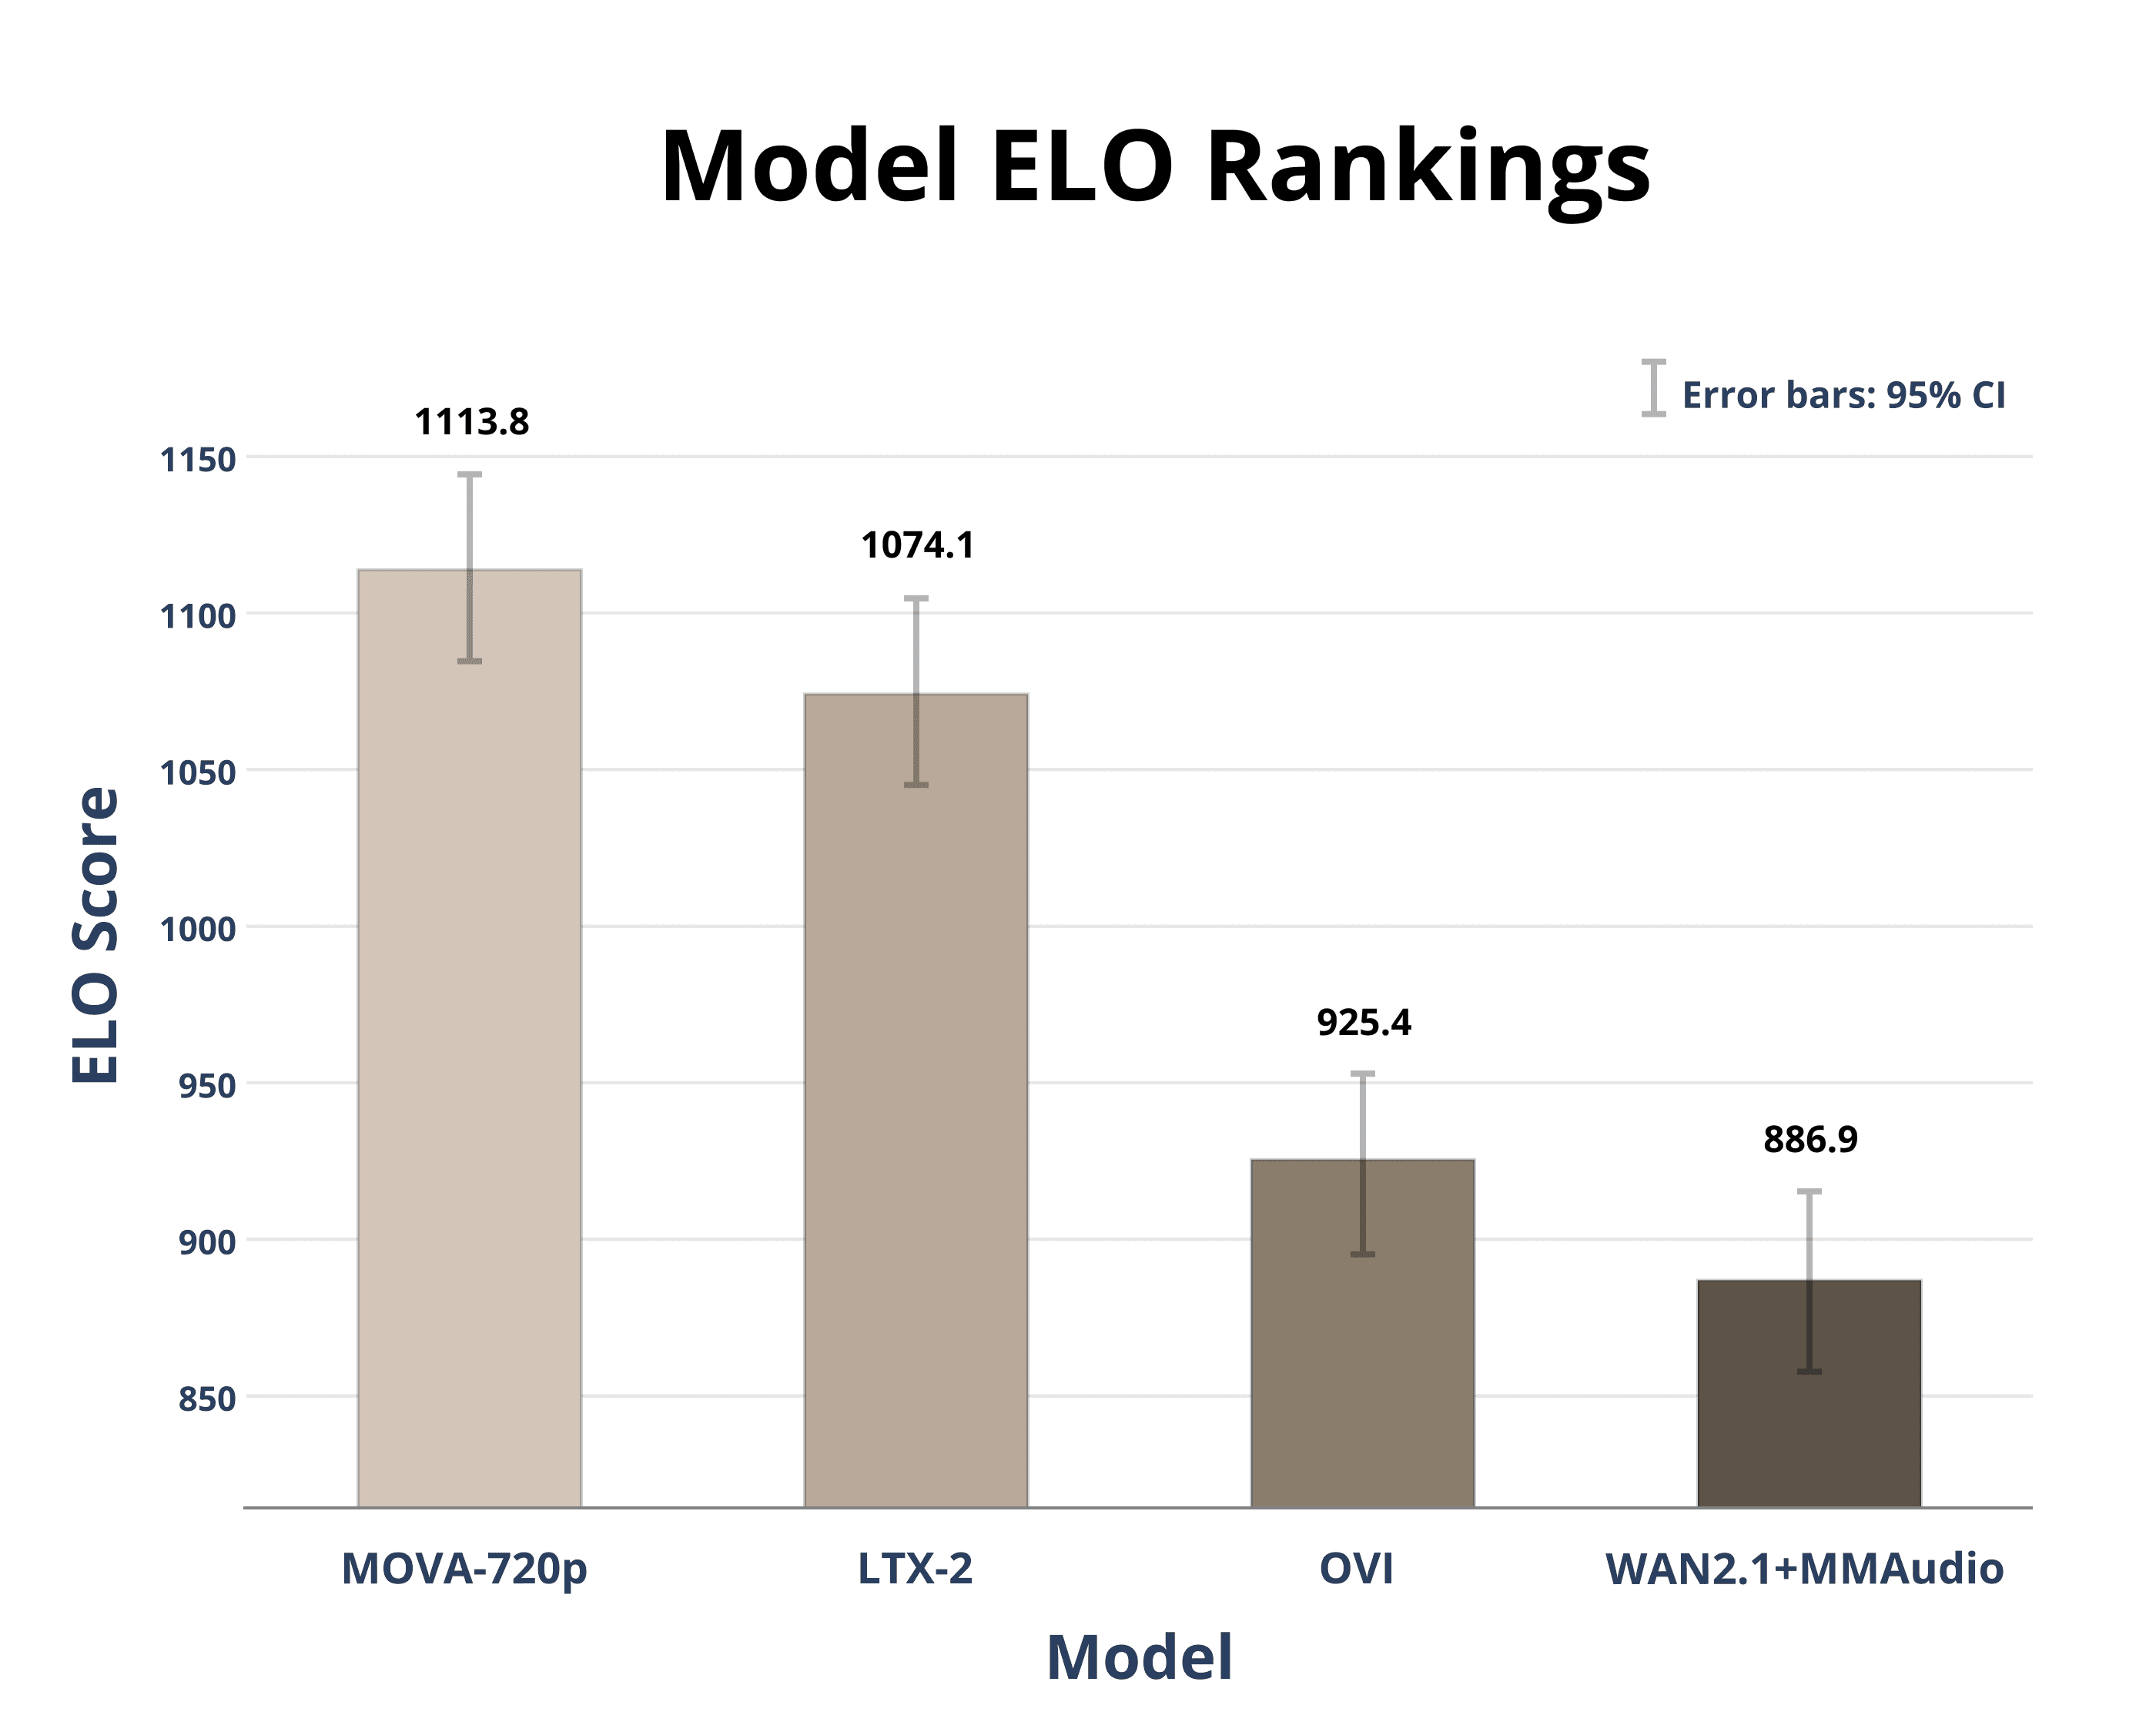
The OpenMOSS team has introduced MOVA-360p, a new generative model that can create short video clips from either a text description or a starting image. While many recent models focus on visual generation, MOVA stands out by tackling both video and audio in a single process.
MOVA's key feature is its ability to perform joint audio-video generation. Instead of producing a silent video that requires a separate soundtrack, the model synthesizes an accompanying audio track that is thematically consistent with the visual content. This integrated approach aims to create more immersive and complete generative media.
The model architecture is built upon established open-source components, using a Stable Diffusion 1.5 foundation for the visual elements and an audio generation model named Tango for the sound. It outputs clips at a resolution of 360p, positioning it as a tool for research and experimentation in multimodal generation.
Researchers and developers can explore the model, which is available on Hugging Face. The release is provided under a custom license, so users should review the terms to ensure compliance for their specific use cases. You can find the model card and download the weights at the official repository.
Sources
- Visit
OpenMOSS-Team/MOVA-360p
Hugging Face
More from OpenMOSS
All OpenMOSS releases →
OpenMOSS Releases MOSS-Image Under Apache 2.0
The academic team behind the MOSS project moves into text-to-image generation with a permissively licensed model and a fine-tuned SFT variant.
OpenMOSS Releases Apache-2.0 Bilingual Image Model
MOSS-Image Base arrives as a permissively licensed text-to-image foundation with English and Chinese support.
OpenMOSS Debuts MOSS-VL for Real-Time Vision Interaction
A new open vision-language model family uses gated cross-attention to enable streaming, low-latency multimodal exchanges.
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
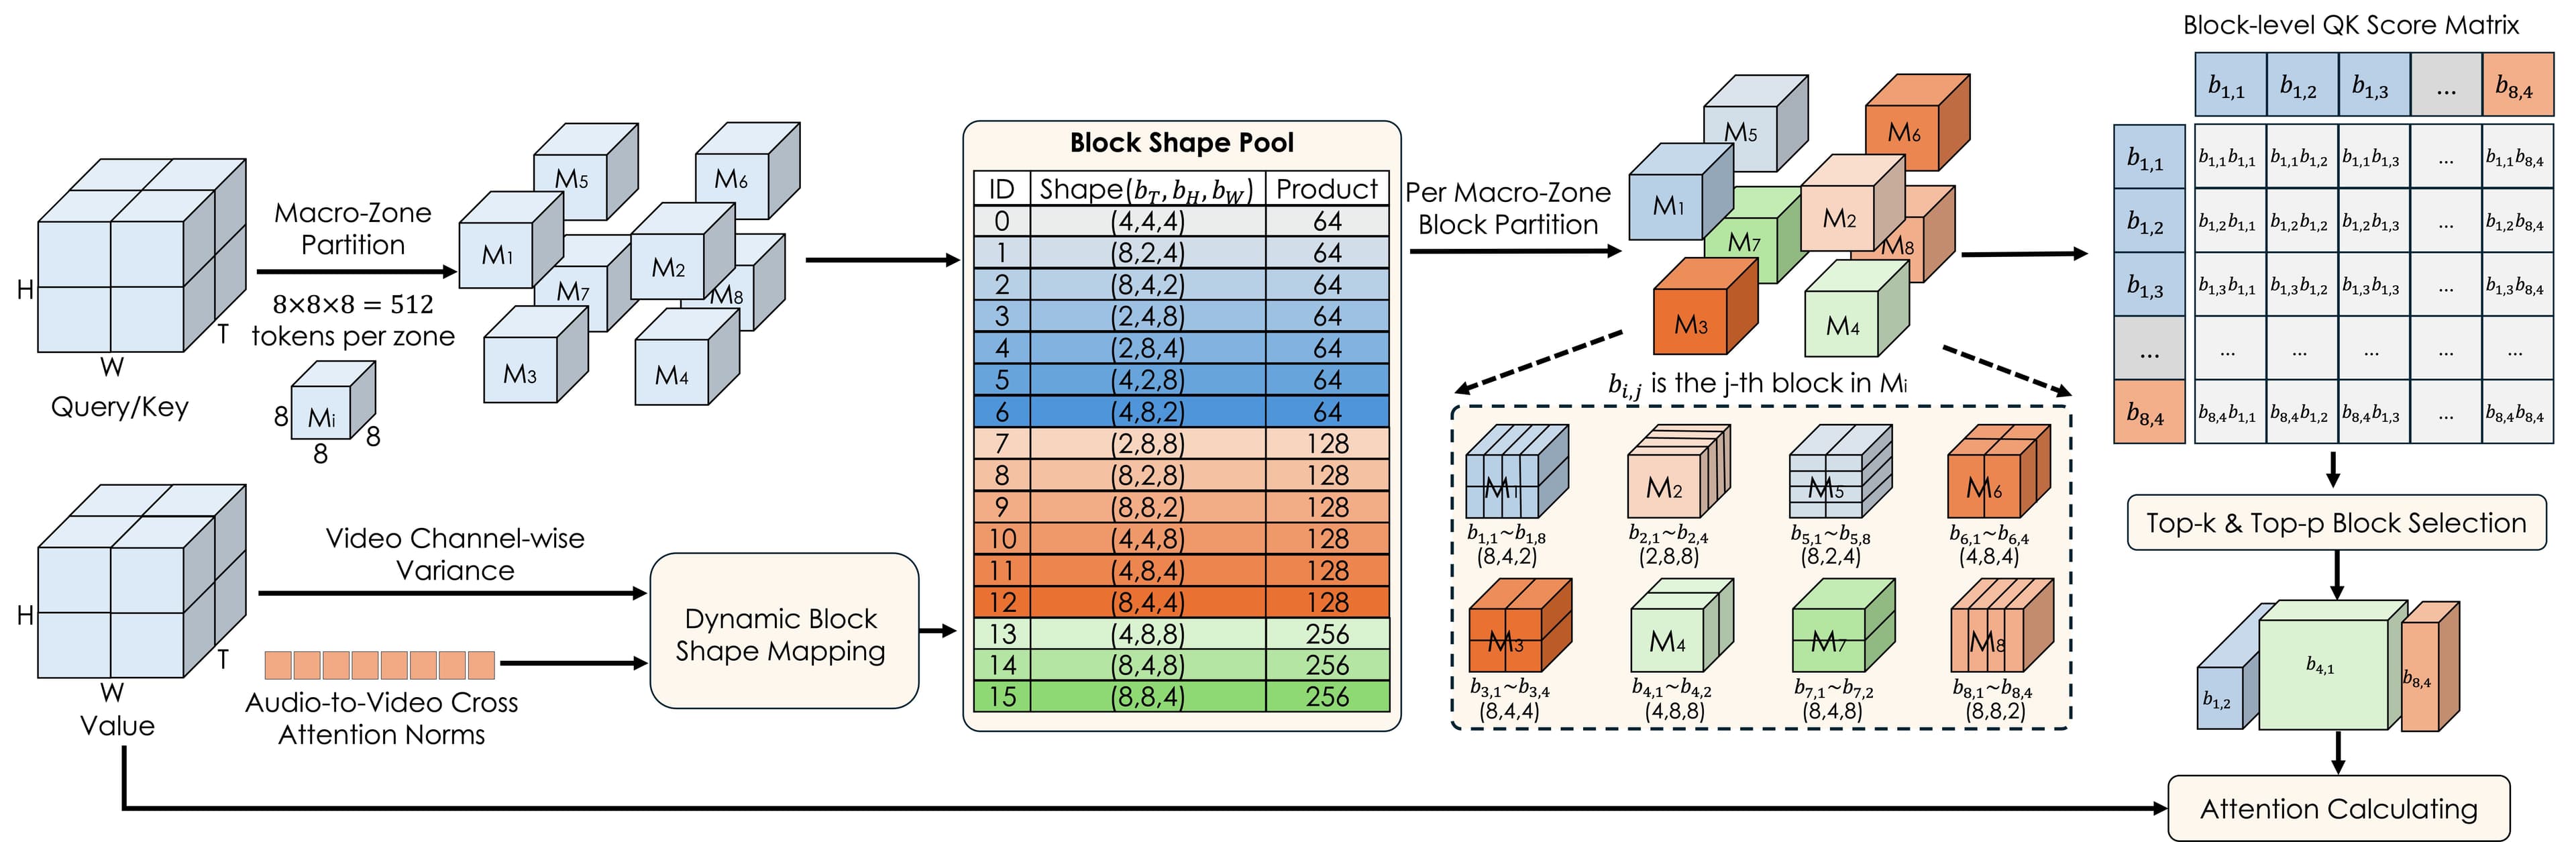
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.