Meituan Releases Open-Source LongCat-Video Model
The Chinese tech giant has released a new MIT-licensed model capable of generating video from text, images, or by continuing existing clips.

Meituan, a major Chinese technology company, has entered the open-source video generation space with the release of LongCat-Video. The new model is available on Hugging Face with a permissive MIT license, allowing for broad use and modification.
LongCat-Video is a versatile diffusion model that creates short video clips from a variety of inputs. Its release adds another strong contender to the rapidly evolving field of open AI video, providing a flexible tool for developers and creators.
Core Capabilities
The model is designed to handle several distinct generation tasks, making it a multi-functional tool for video creation:
- Text-to-video: Generates a video sequence from a descriptive text prompt.
- Image-to-video: Animates a static source image based on a prompt.
- Video continuation: Extends an existing video clip by generating subsequent frames.
The model's permissive license and multifaceted approach make it a significant contribution to the open-source ecosystem. It provides researchers and commercial entities alike with a solid foundation for experimenting with and deploying generative video applications.
Sources
- Visit
meituan-longcat/LongCat-Video
Hugging Face
More from Meituan
All Meituan releases →
Meituan Ships a Lighter, Sparser LongCat-Flash
The food-delivery giant's newest open model trims its mixture-of-experts design for more efficient inference under an MIT license.

Meituan releases LongCat-2.0 language model
The Chinese delivery giant continues its push into open AI with a new text model on Hugging Face.
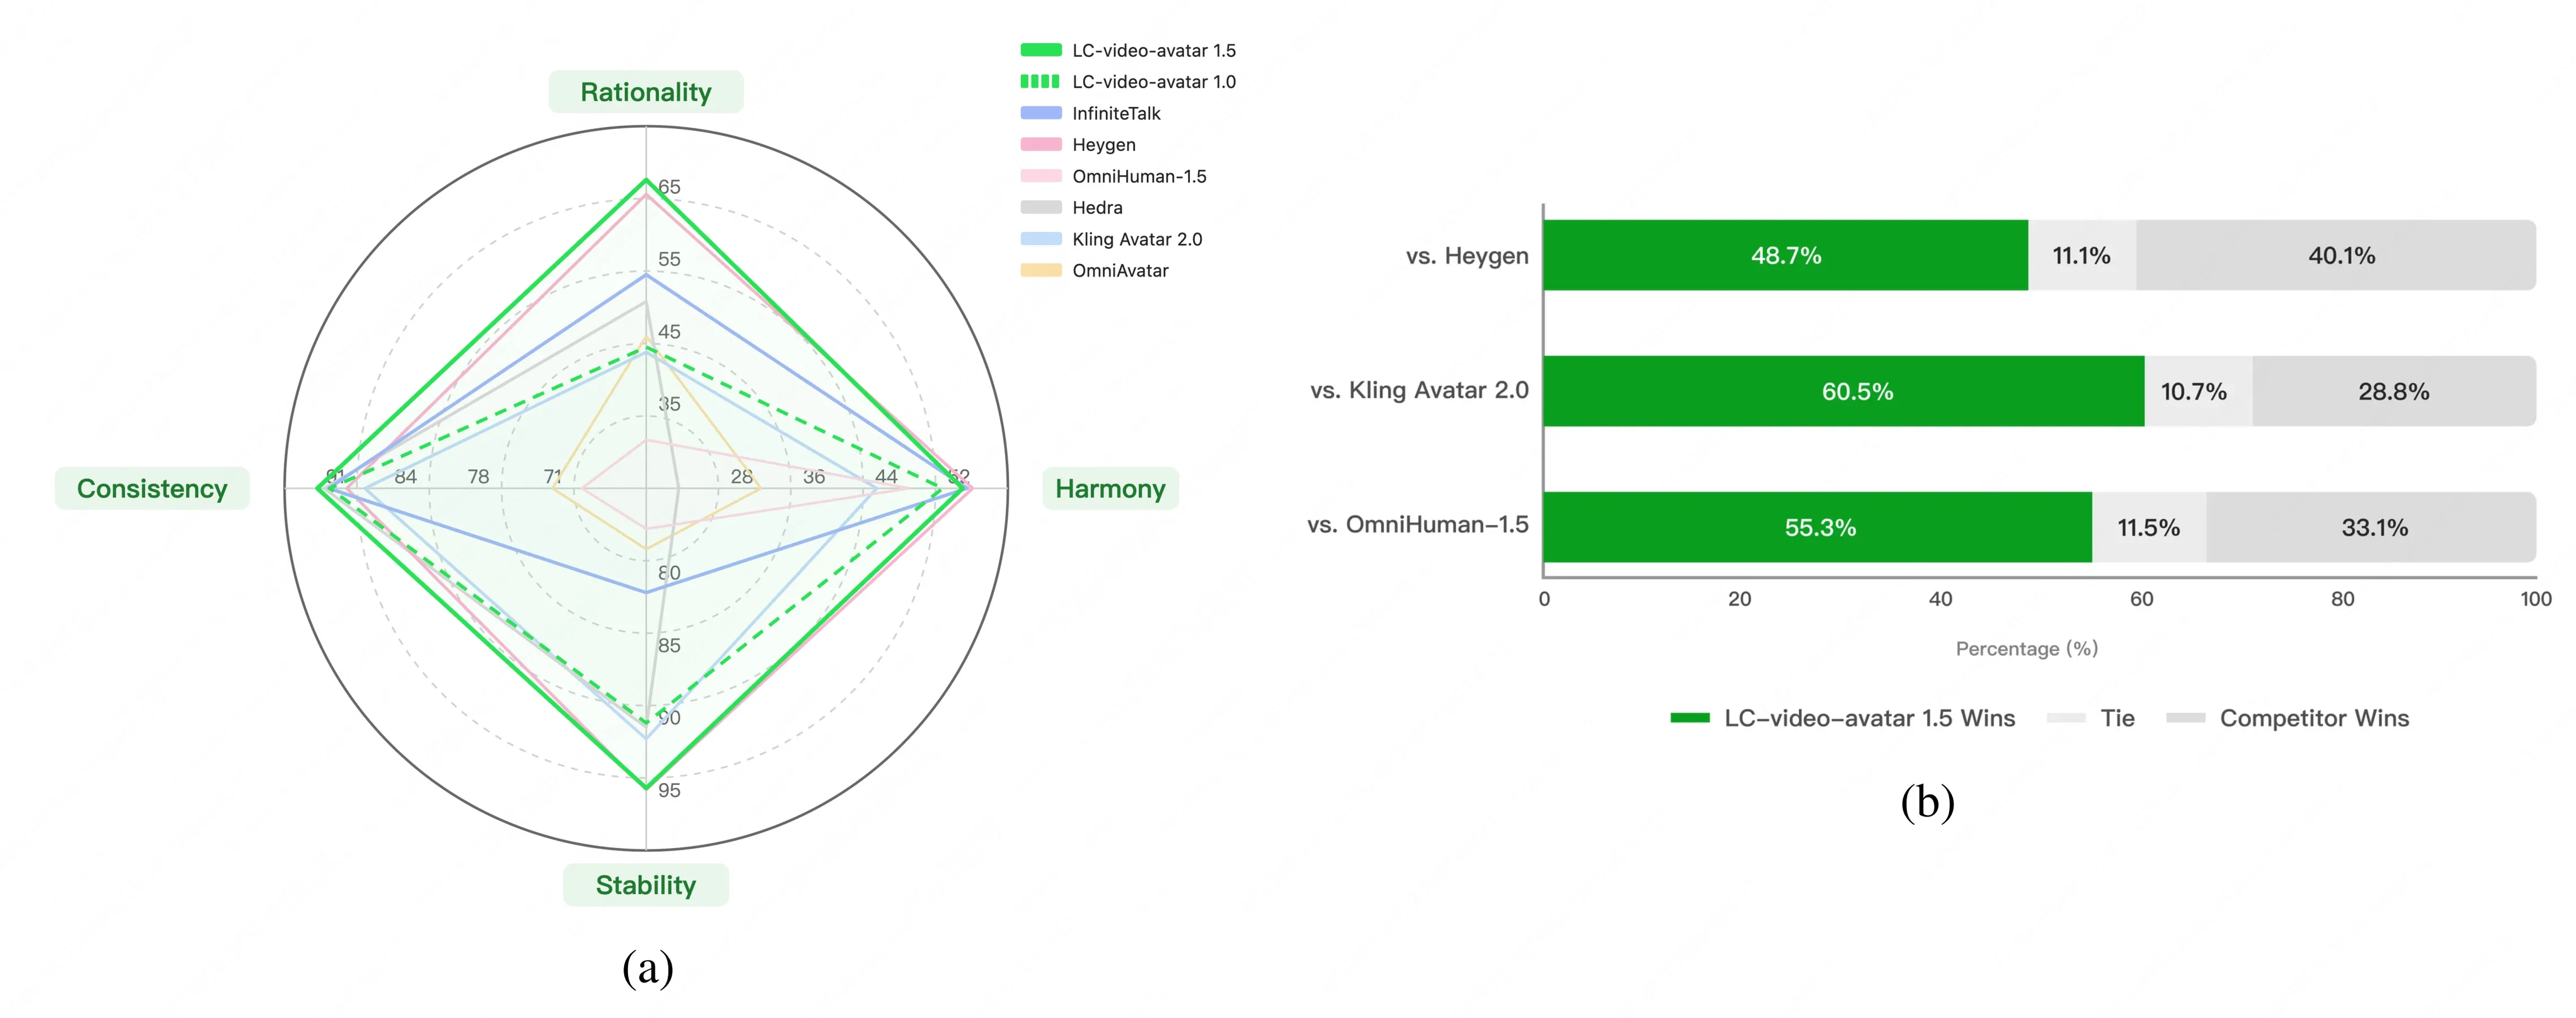
Meituan releases LongCat-Video-Avatar 1.5
An audio-driven avatar model that animates still images into talking video, with support for continuation of longer clips.
More in Text → Video
All Text → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
0 comments
No comments yet. Be the first to weigh in.