Meituan Debuts LongCat-Flash-Omni, an Any-to-Any AI Model
The new open-source Mixture-of-Experts model can process and generate any combination of text, images, video, audio, and 3D data.
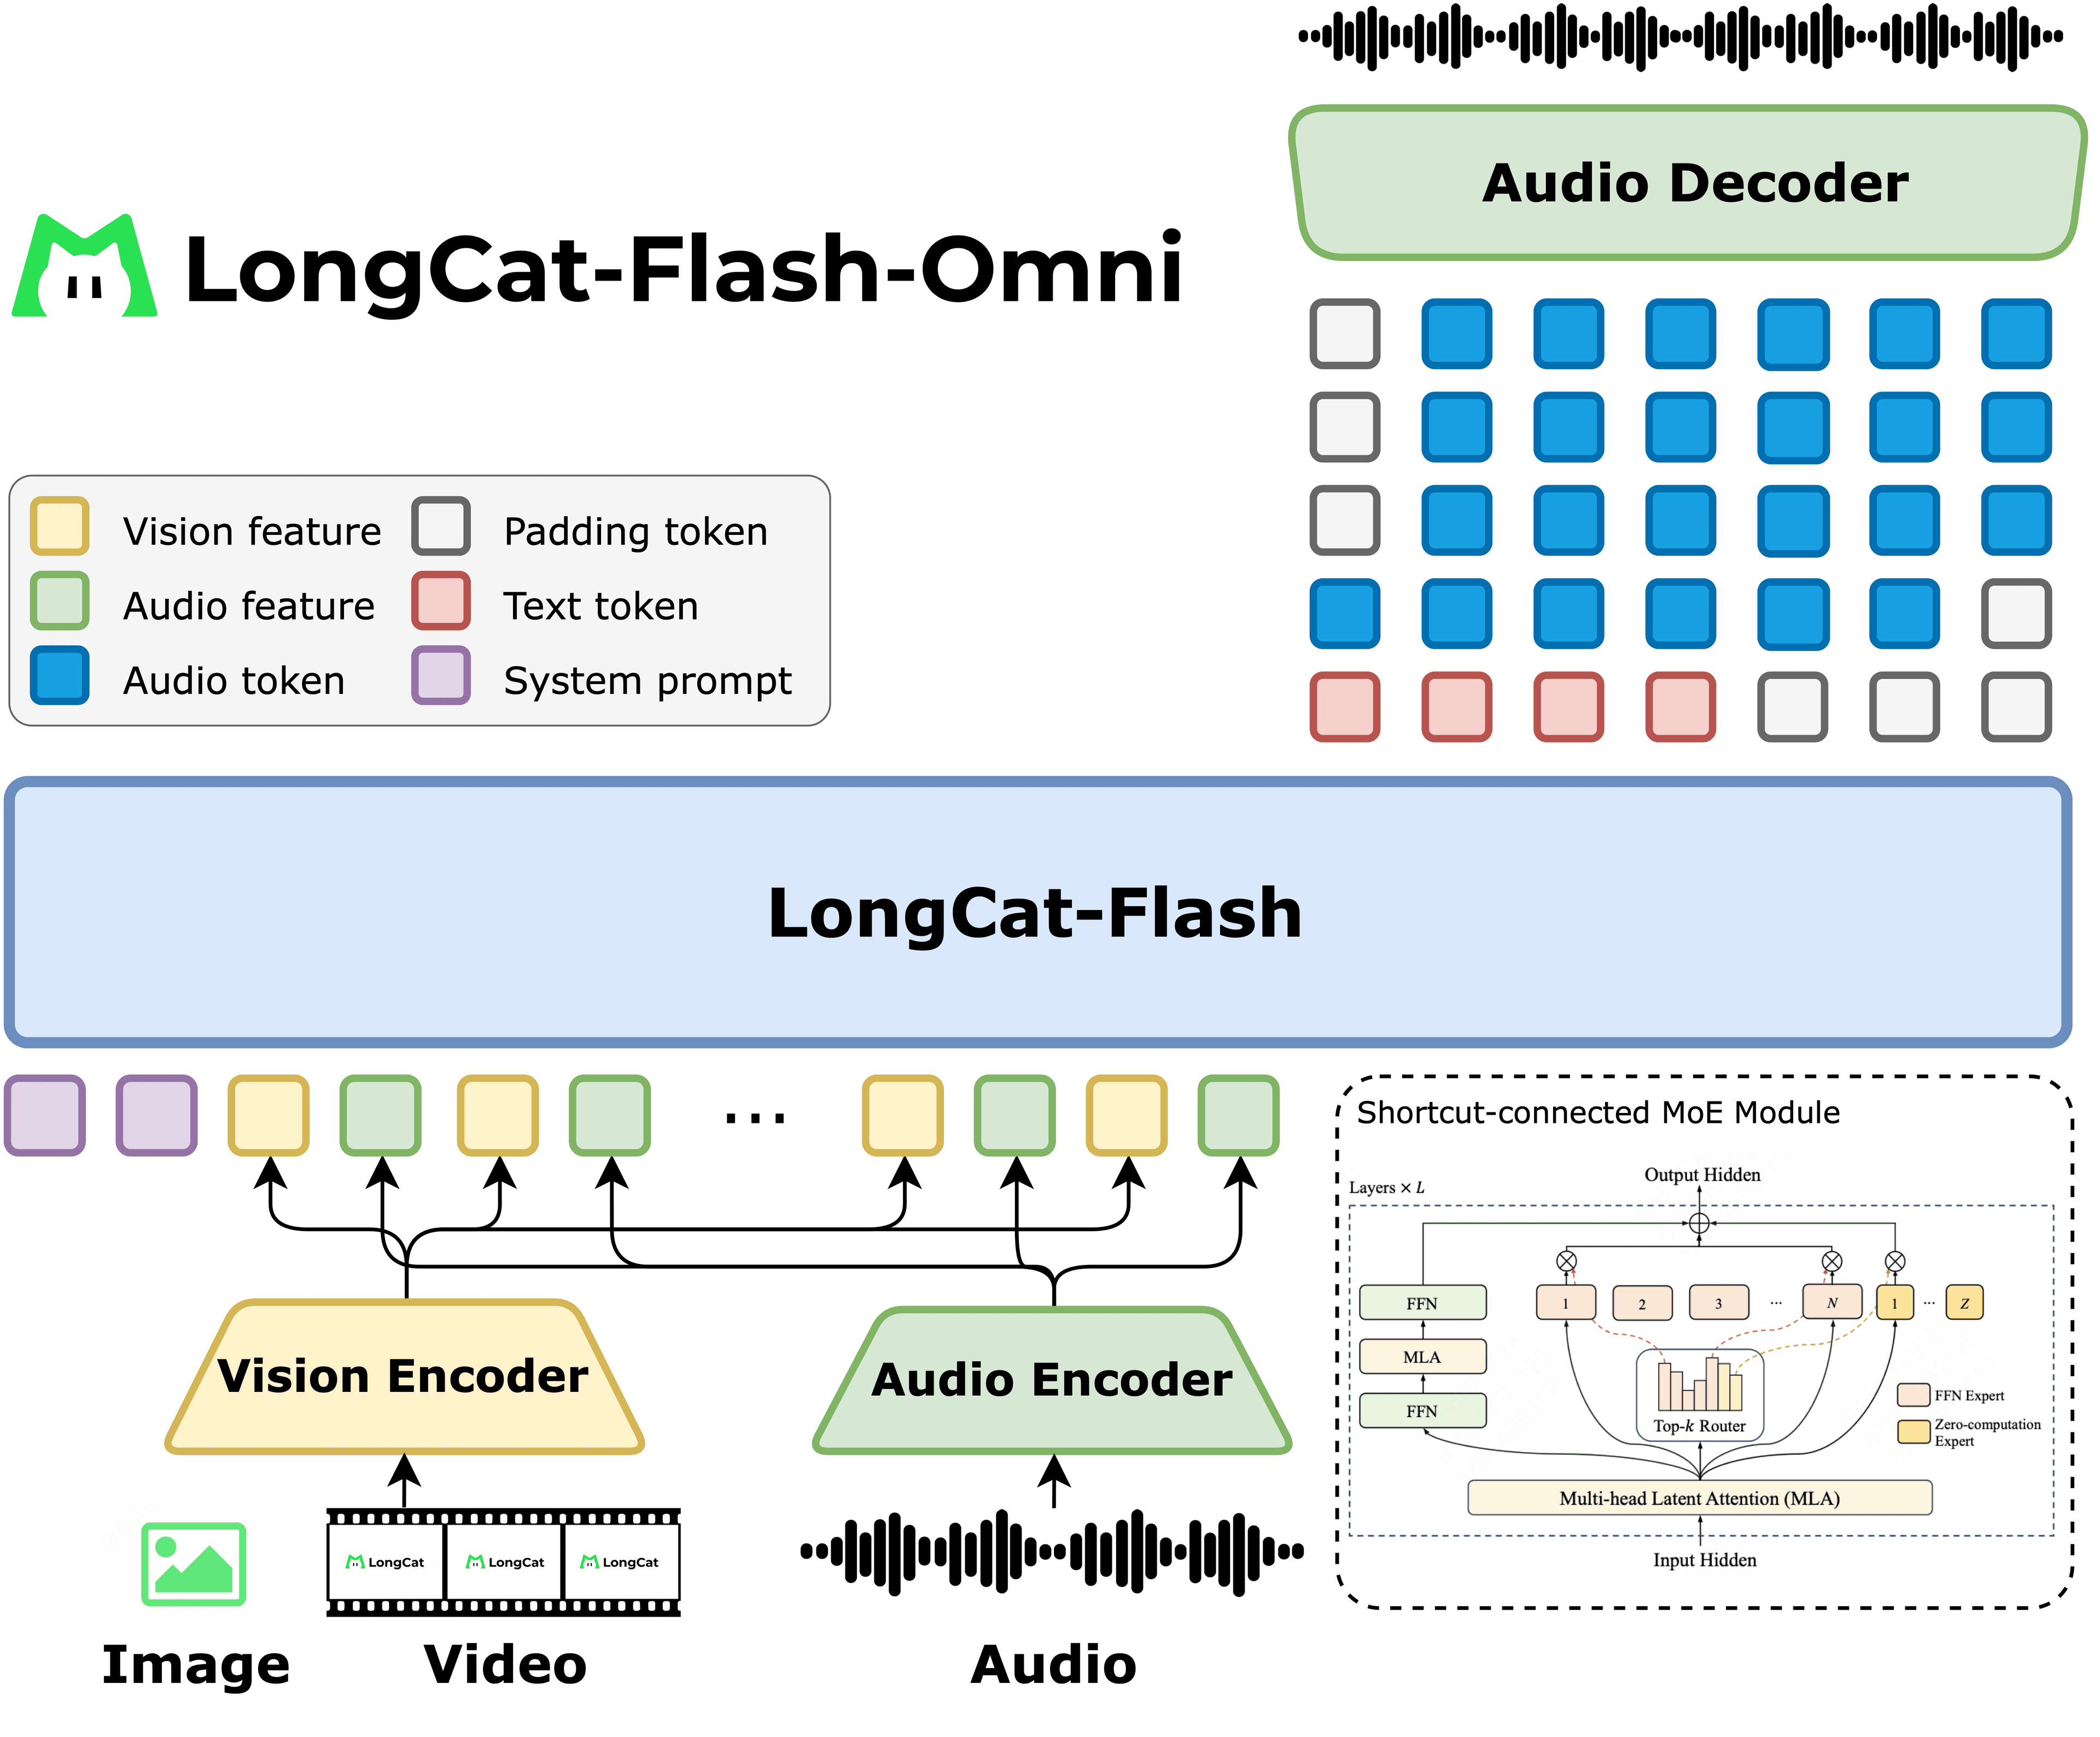
Chinese technology company Meituan has released LongCat-Flash-Omni, a new open-source model designed to handle a vast array of data types. Billed as an "any-to-any" omni-modal system, it aims to process and generate information across different formats seamlessly, a significant step in developing more versatile AI.
According to the release details on Hugging Face, the model's key innovation is its ability to manage multiple data modalities simultaneously within a single framework. This "omni-modal" capability includes:
- Text
- Images
- Video
- Audio
- 3D data
The model is built on a Mixture-of-Experts (MoE) architecture, a technique that activates specialized parts of the network for specific tasks. This allows the model to scale efficiently while managing the complexity of different data encoders. The system projects inputs from various modalities into a shared representational space, allowing the core language model to process them cohesively.
Released under the permissive MIT license, LongCat-Flash-Omni provides the research community with a powerful tool for exploring truly multimodal AI. Its flexible architecture opens up possibilities for complex applications that require understanding and generating content across diverse formats, pushing the boundaries of what's possible with open-source models.
Sources
- Visit
meituan-longcat/LongCat-Flash-Omni
Hugging Face
More from Meituan
All Meituan releases →
Meituan Ships a Lighter, Sparser LongCat-Flash
The food-delivery giant's newest open model trims its mixture-of-experts design for more efficient inference under an MIT license.
Meituan releases LongCat-2.0 language model
The Chinese delivery giant continues its push into open AI with a new text model on Hugging Face.
Meituan releases LongCat-Video-Avatar 1.5
An audio-driven avatar model that animates still images into talking video, with support for continuation of longer clips.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.