Boson AI releases Higgs TTS v3, a 4B speech model
The new open-weights text-to-speech system targets expressive, controllable voice generation across multiple languages with built-in voice cloning.
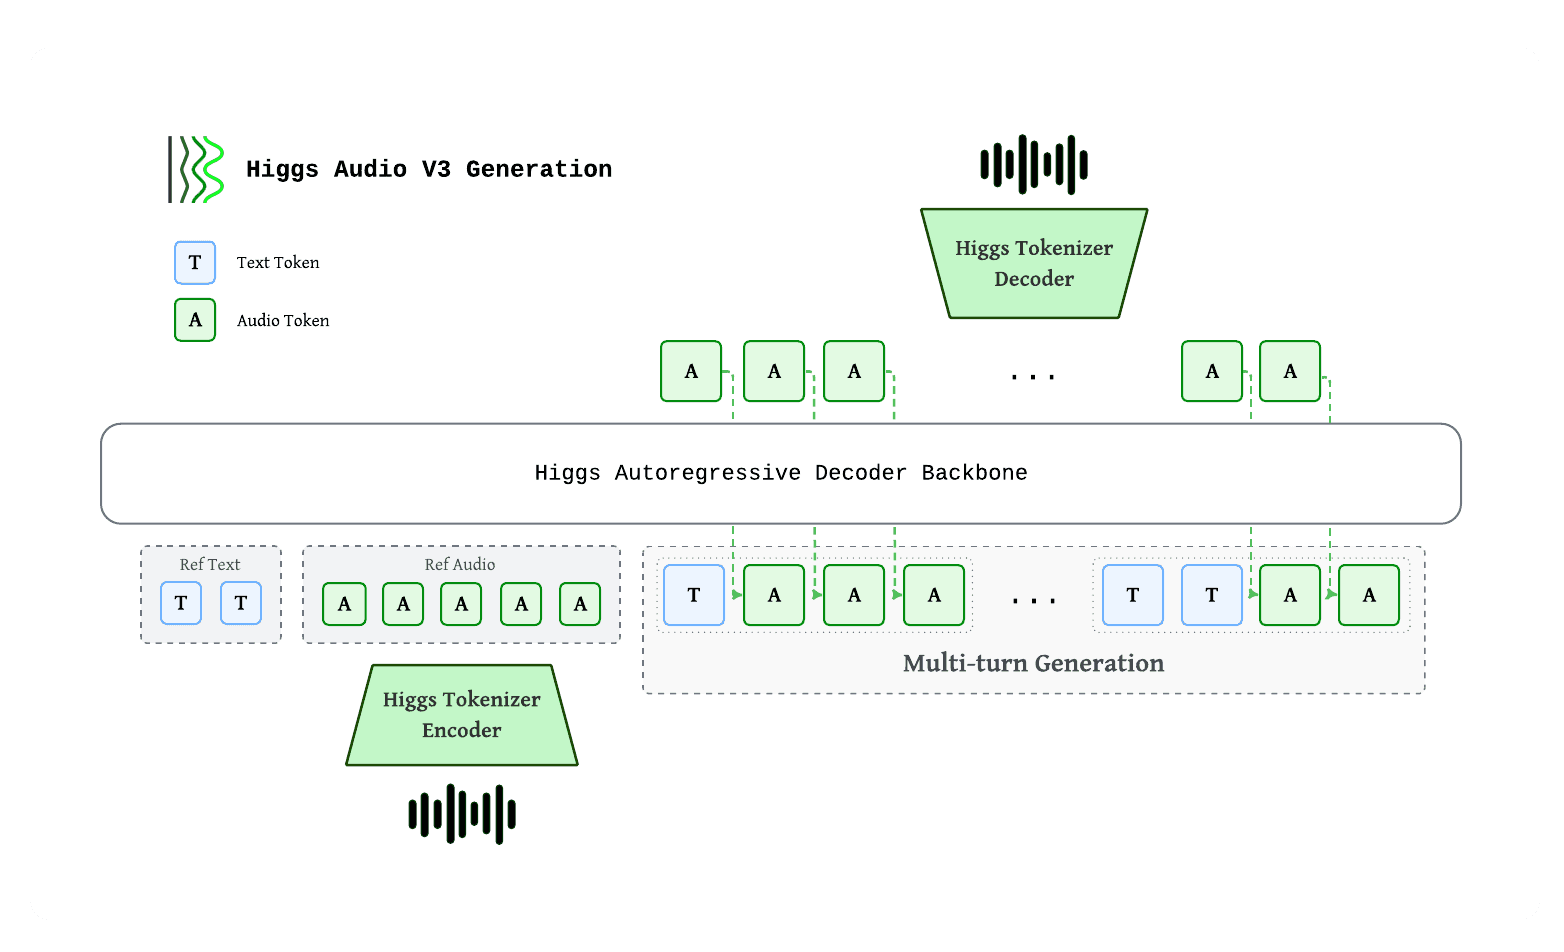
Boson AI has published Higgs TTS v3, a 4-billion-parameter text-to-speech model now available on Hugging Face. The release positions the model as an expressive, controllable system for generating synthetic speech across multiple languages.
According to the model record, Higgs TTS v3 emphasizes three capabilities that increasingly define the modern TTS field:
- Expressive output, aimed at natural prosody and emotional range rather than flat narration
- Controllability, giving developers levers over how speech is rendered
- Voice cloning, allowing the model to reproduce a target voice
At 4B parameters, the model sits in a practical middle ground—large enough to handle nuanced multilingual synthesis, but small enough to be approachable for teams running their own inference rather than relying on closed APIs.
Why it matters
Text-to-speech has become one of the more competitive corners of open-weights AI, where the gap between proprietary services and freely available models has narrowed quickly. A controllable, multilingual model with voice cloning that ships with downloadable weights gives researchers and product builders a foundation they can inspect, fine-tune, and deploy without per-call costs. The model is distributed under a custom license, so teams will want to review the terms before commercial use.
Sources
- Visit
bosonai/higgs-tts-v3-4b
Hugging Face
More from Bosonai
All Bosonai releases →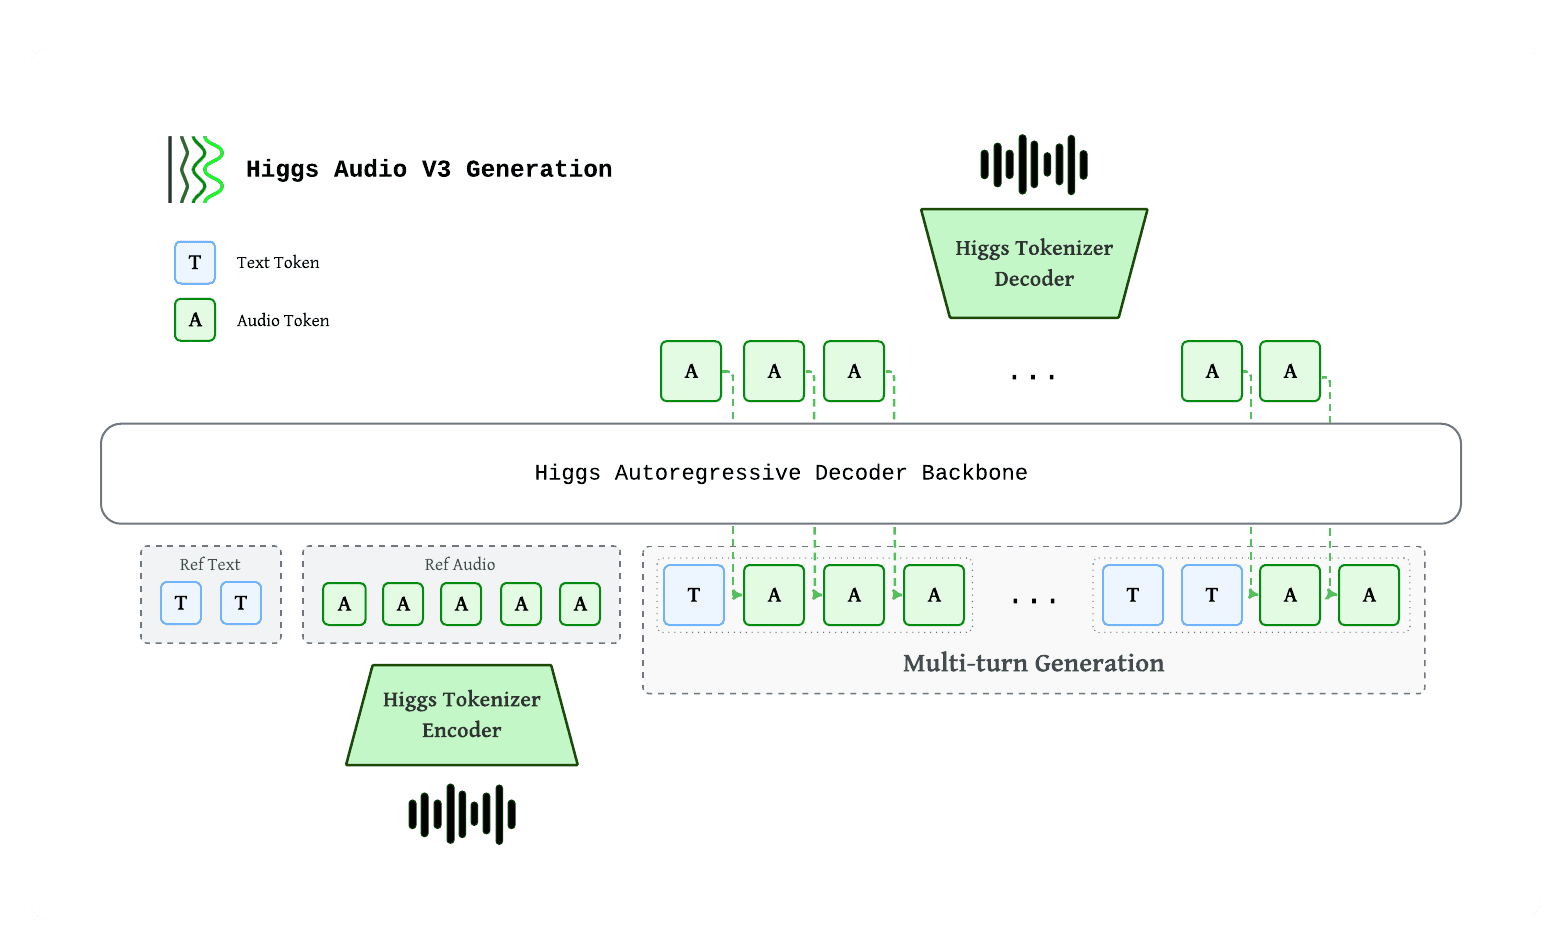
Boson AI's Higgs Audio v3 Offers Expressive, Multilingual TTS
The new 4-billion-parameter text-to-speech model is available for non-commercial use, promising fine-grained control over vocal delivery.
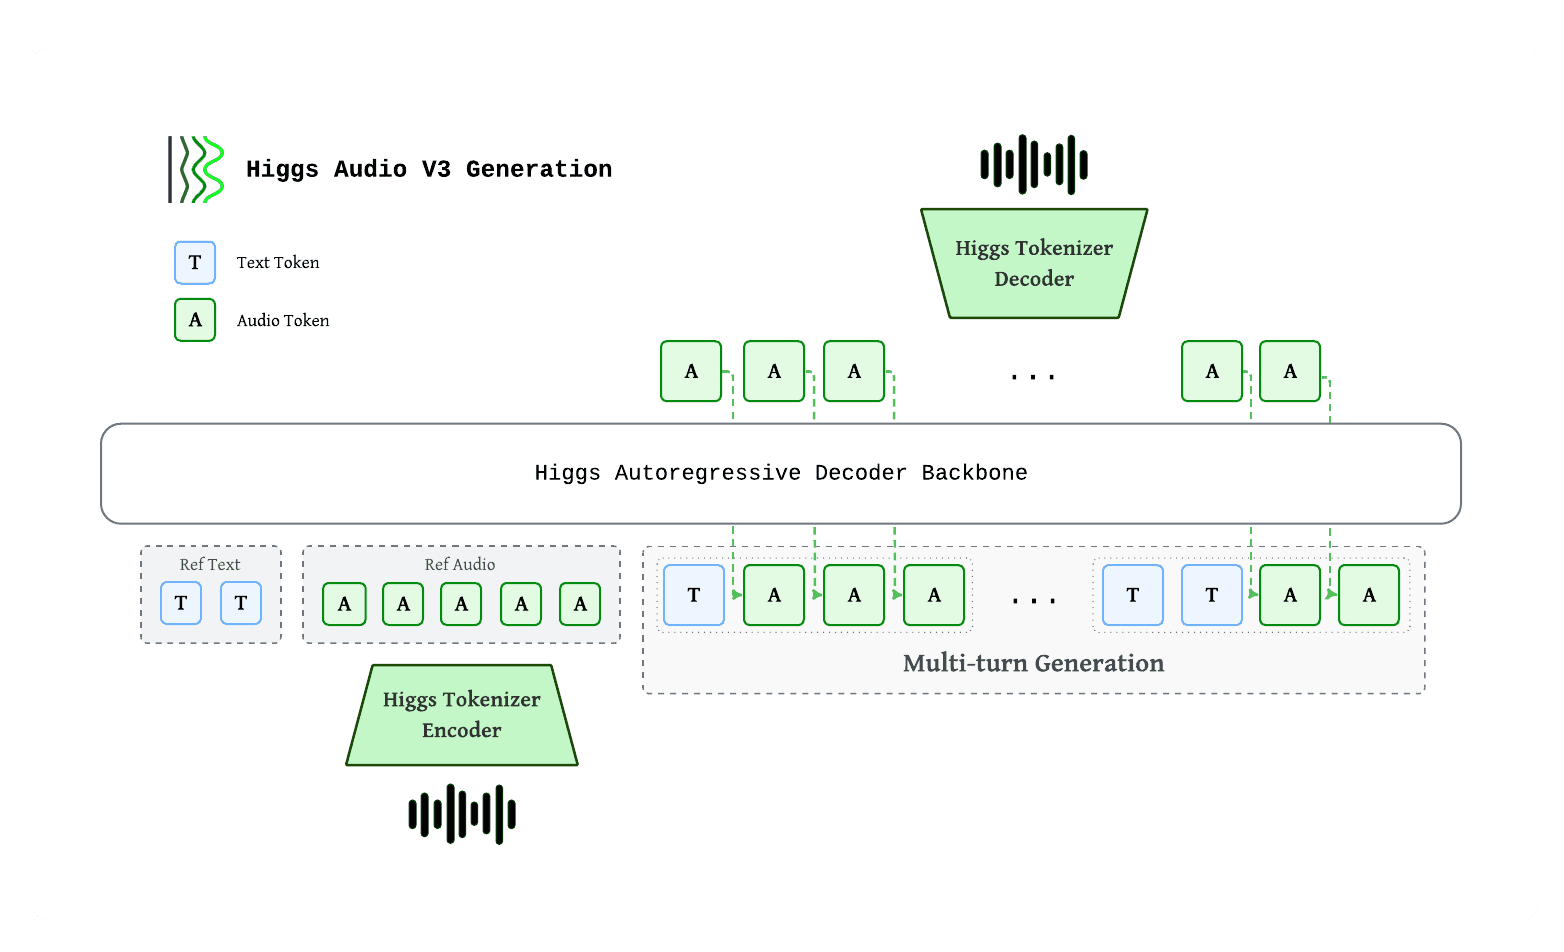
Higgs TTS 3 lands as a 4B multilingual speech model
Boson AI's new text-to-speech release aims for expressive, controllable voice synthesis across multiple languages.
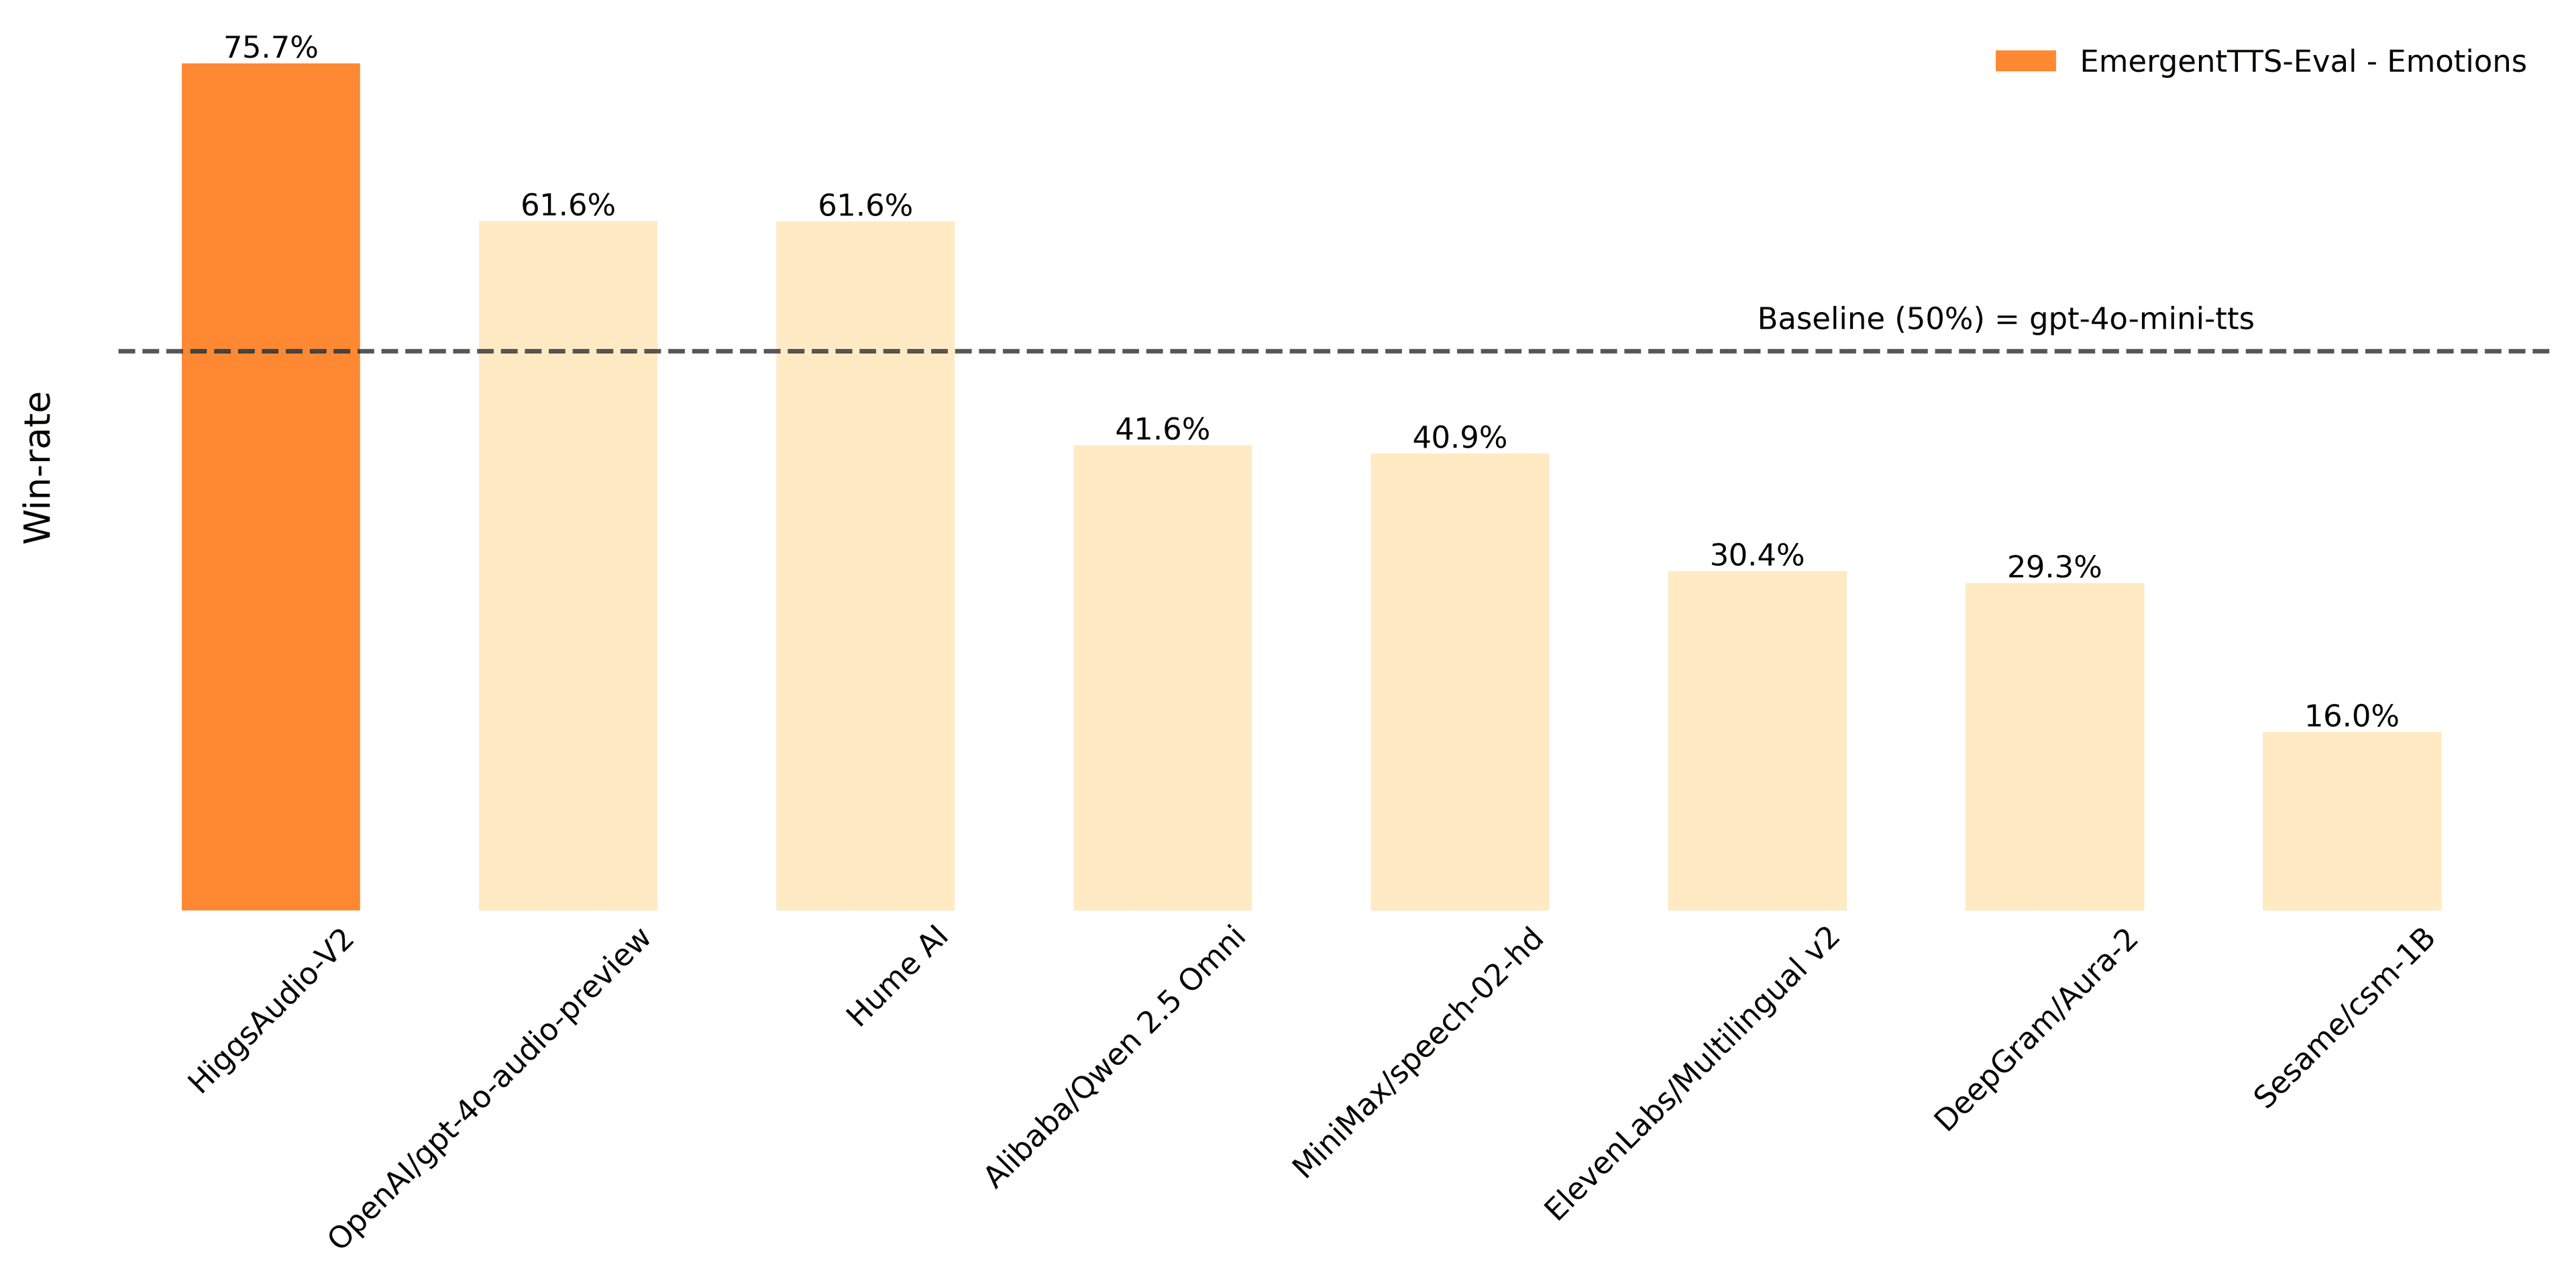
Boson AI Releases Higgs Audio v2 for Expressive TTS
The new 3-billion-parameter model focuses on generating expressive, multilingual speech and is fully open for commercial use under an Apache 2.0 license.
More in Text → Speech
All Text → Speech →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.

Fish Audio's Drama 3 brings MoE to open TTS
The open-source speech model pairs a 35B mixture-of-experts backbone with voice cloning and directed performance control.
0 comments
No comments yet. Be the first to weigh in.