Higgs TTS 3 lands as a 4B multilingual speech model
Boson AI's new text-to-speech release aims for expressive, controllable voice synthesis across multiple languages.
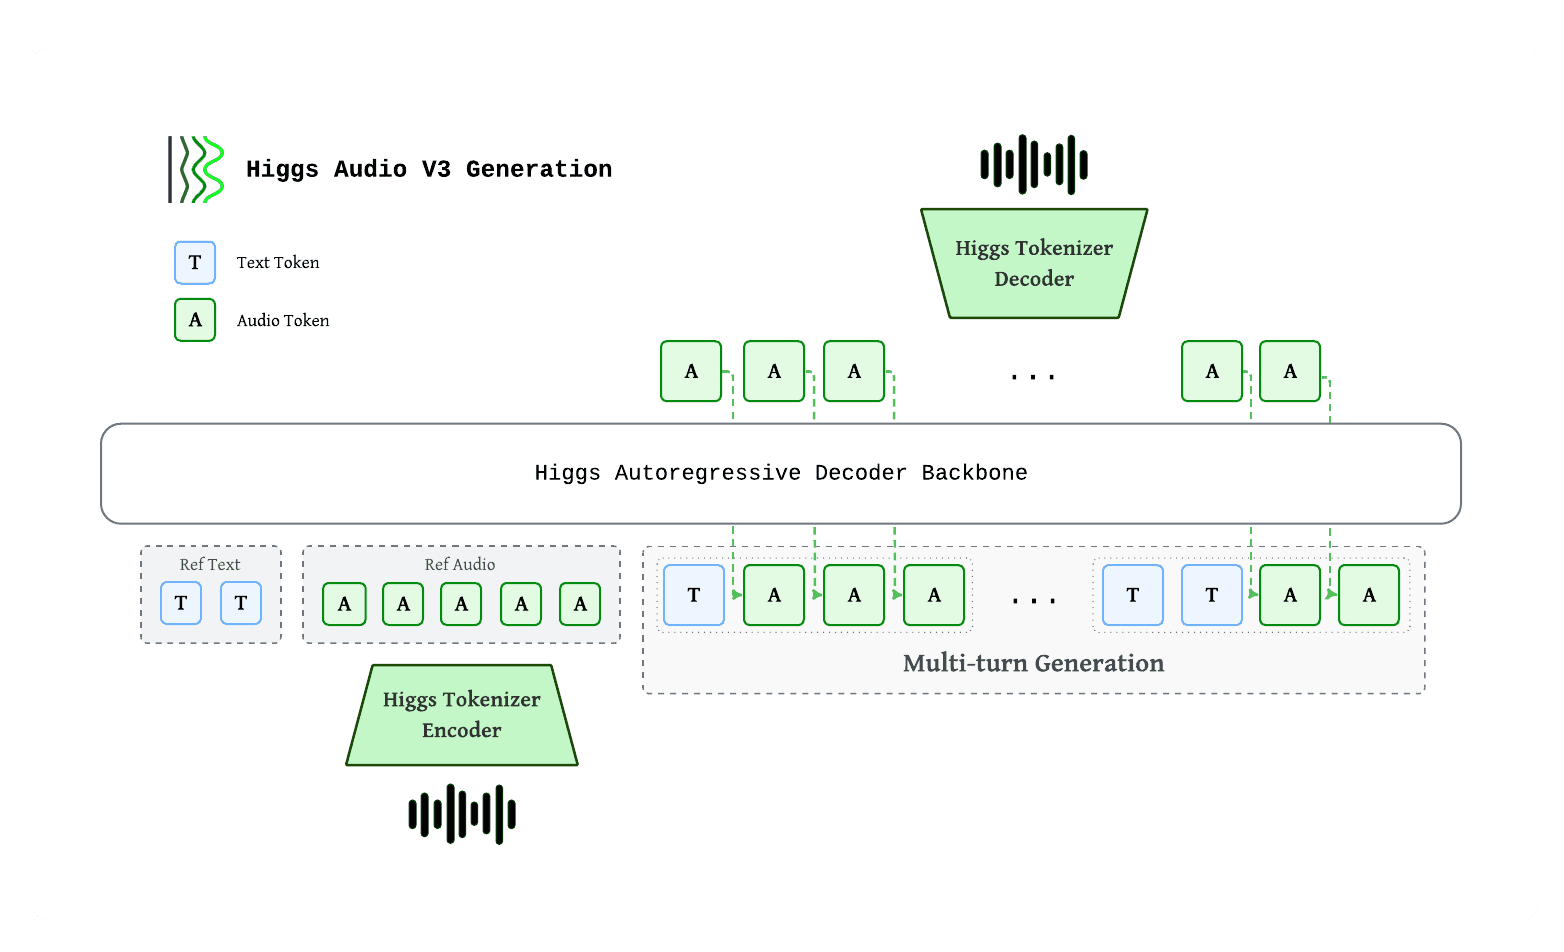
A new entry in the text-to-speech space has arrived: Higgs TTS 3, a 4-billion-parameter model published under the bosonai namespace on Hugging Face. It targets expressive, controllable speech generation with multilingual support, positioning itself for developers who want more than flat, robotic narration.
At 4B parameters, the model sits in a practical middle ground — large enough to capture nuanced prosody and timbre, but small enough to run without the heaviest infrastructure. The emphasis on controllability suggests it is built for use cases where tone, emphasis, and delivery matter, such as audiobooks, virtual assistants, and dubbing.
Why it matters
Open text-to-speech has lagged behind text and image generation, and high-quality multilingual voices have often been locked behind commercial APIs. A capable, openly distributed model shifts more of that capability into the hands of builders who want to self-host or fine-tune.
Key details from the release:
- 4B dense parameters (not a mixture-of-experts design)
- Multilingual text-to-speech output
- Framed around expressive and controllable generation
- Released under a non-standard "other" license
Prospective adopters should review the license terms before deploying commercially, since the "other" designation means usage rights are not a standard permissive grant. As always, real-world quality will depend on how the model handles edge cases across languages and speaking styles — something worth testing against your own audio benchmarks.
Sources
- Visit
bosonai/higgs-tts-3-4b
Hugging Face
More from Bosonai
All Bosonai releases →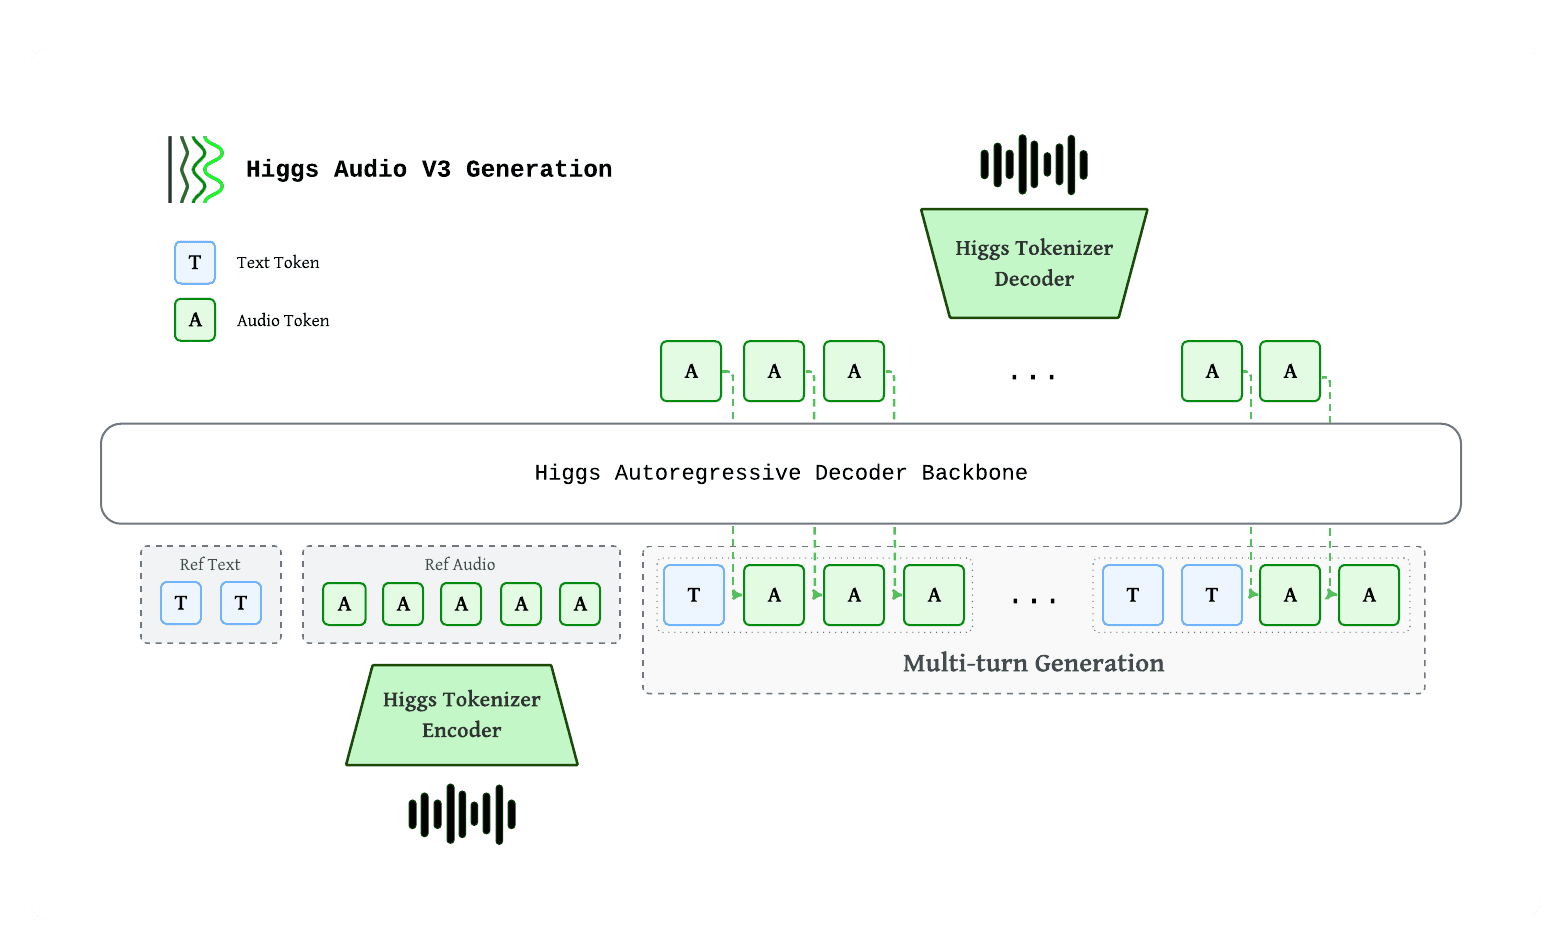
Boson AI's Higgs Audio v3 Offers Expressive, Multilingual TTS
The new 4-billion-parameter text-to-speech model is available for non-commercial use, promising fine-grained control over vocal delivery.
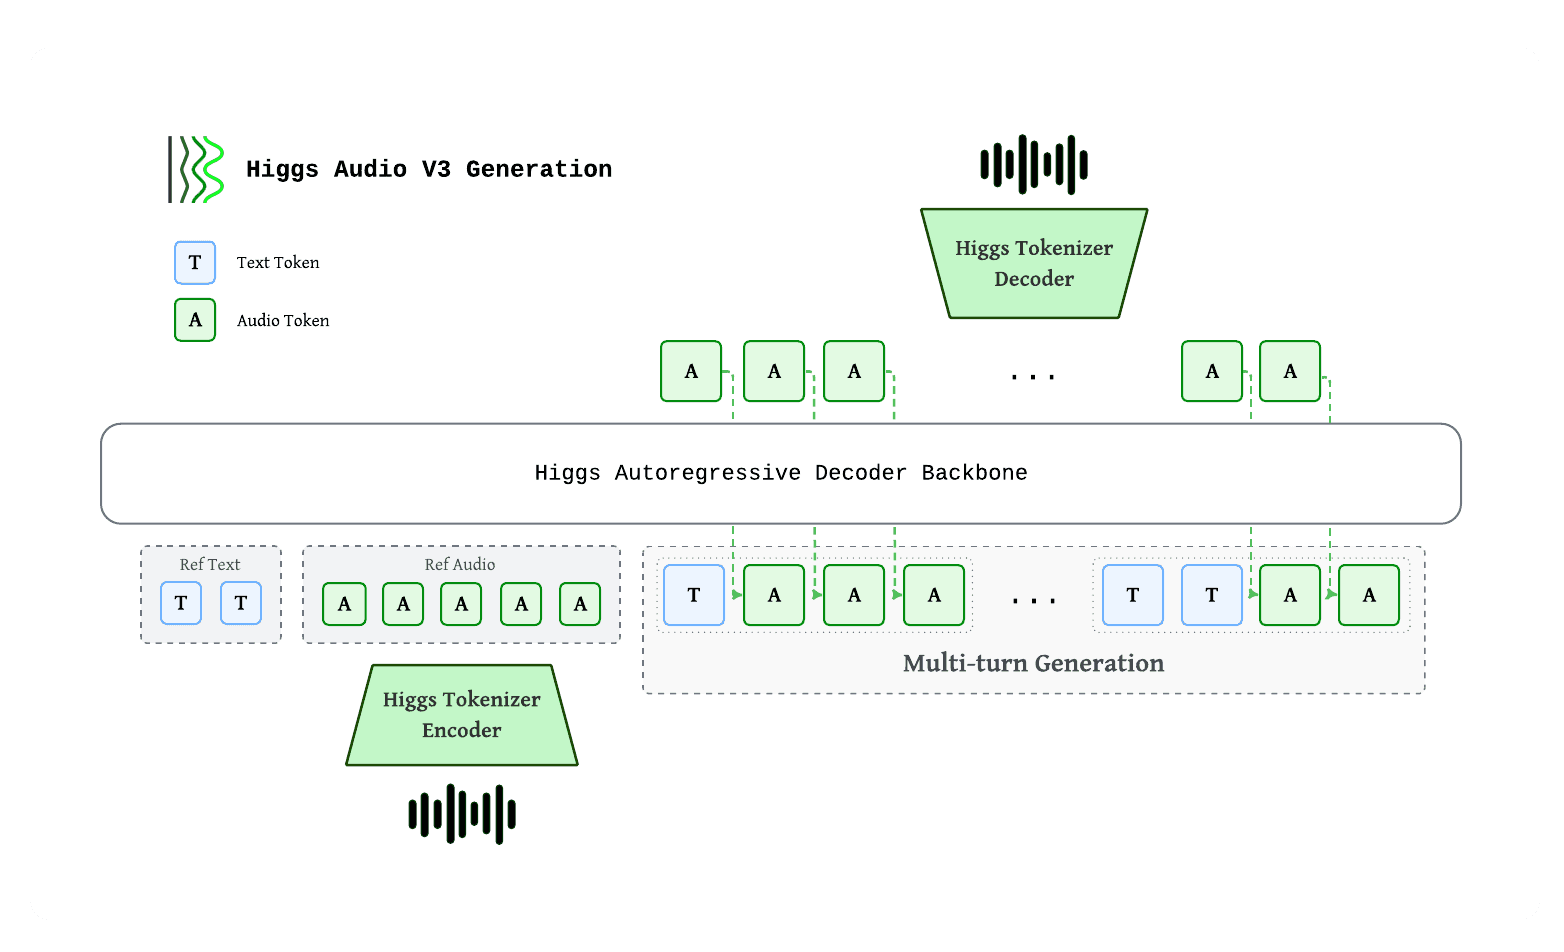
Boson AI releases Higgs TTS v3, a 4B speech model
The new open-weights text-to-speech system targets expressive, controllable voice generation across multiple languages with built-in voice cloning.
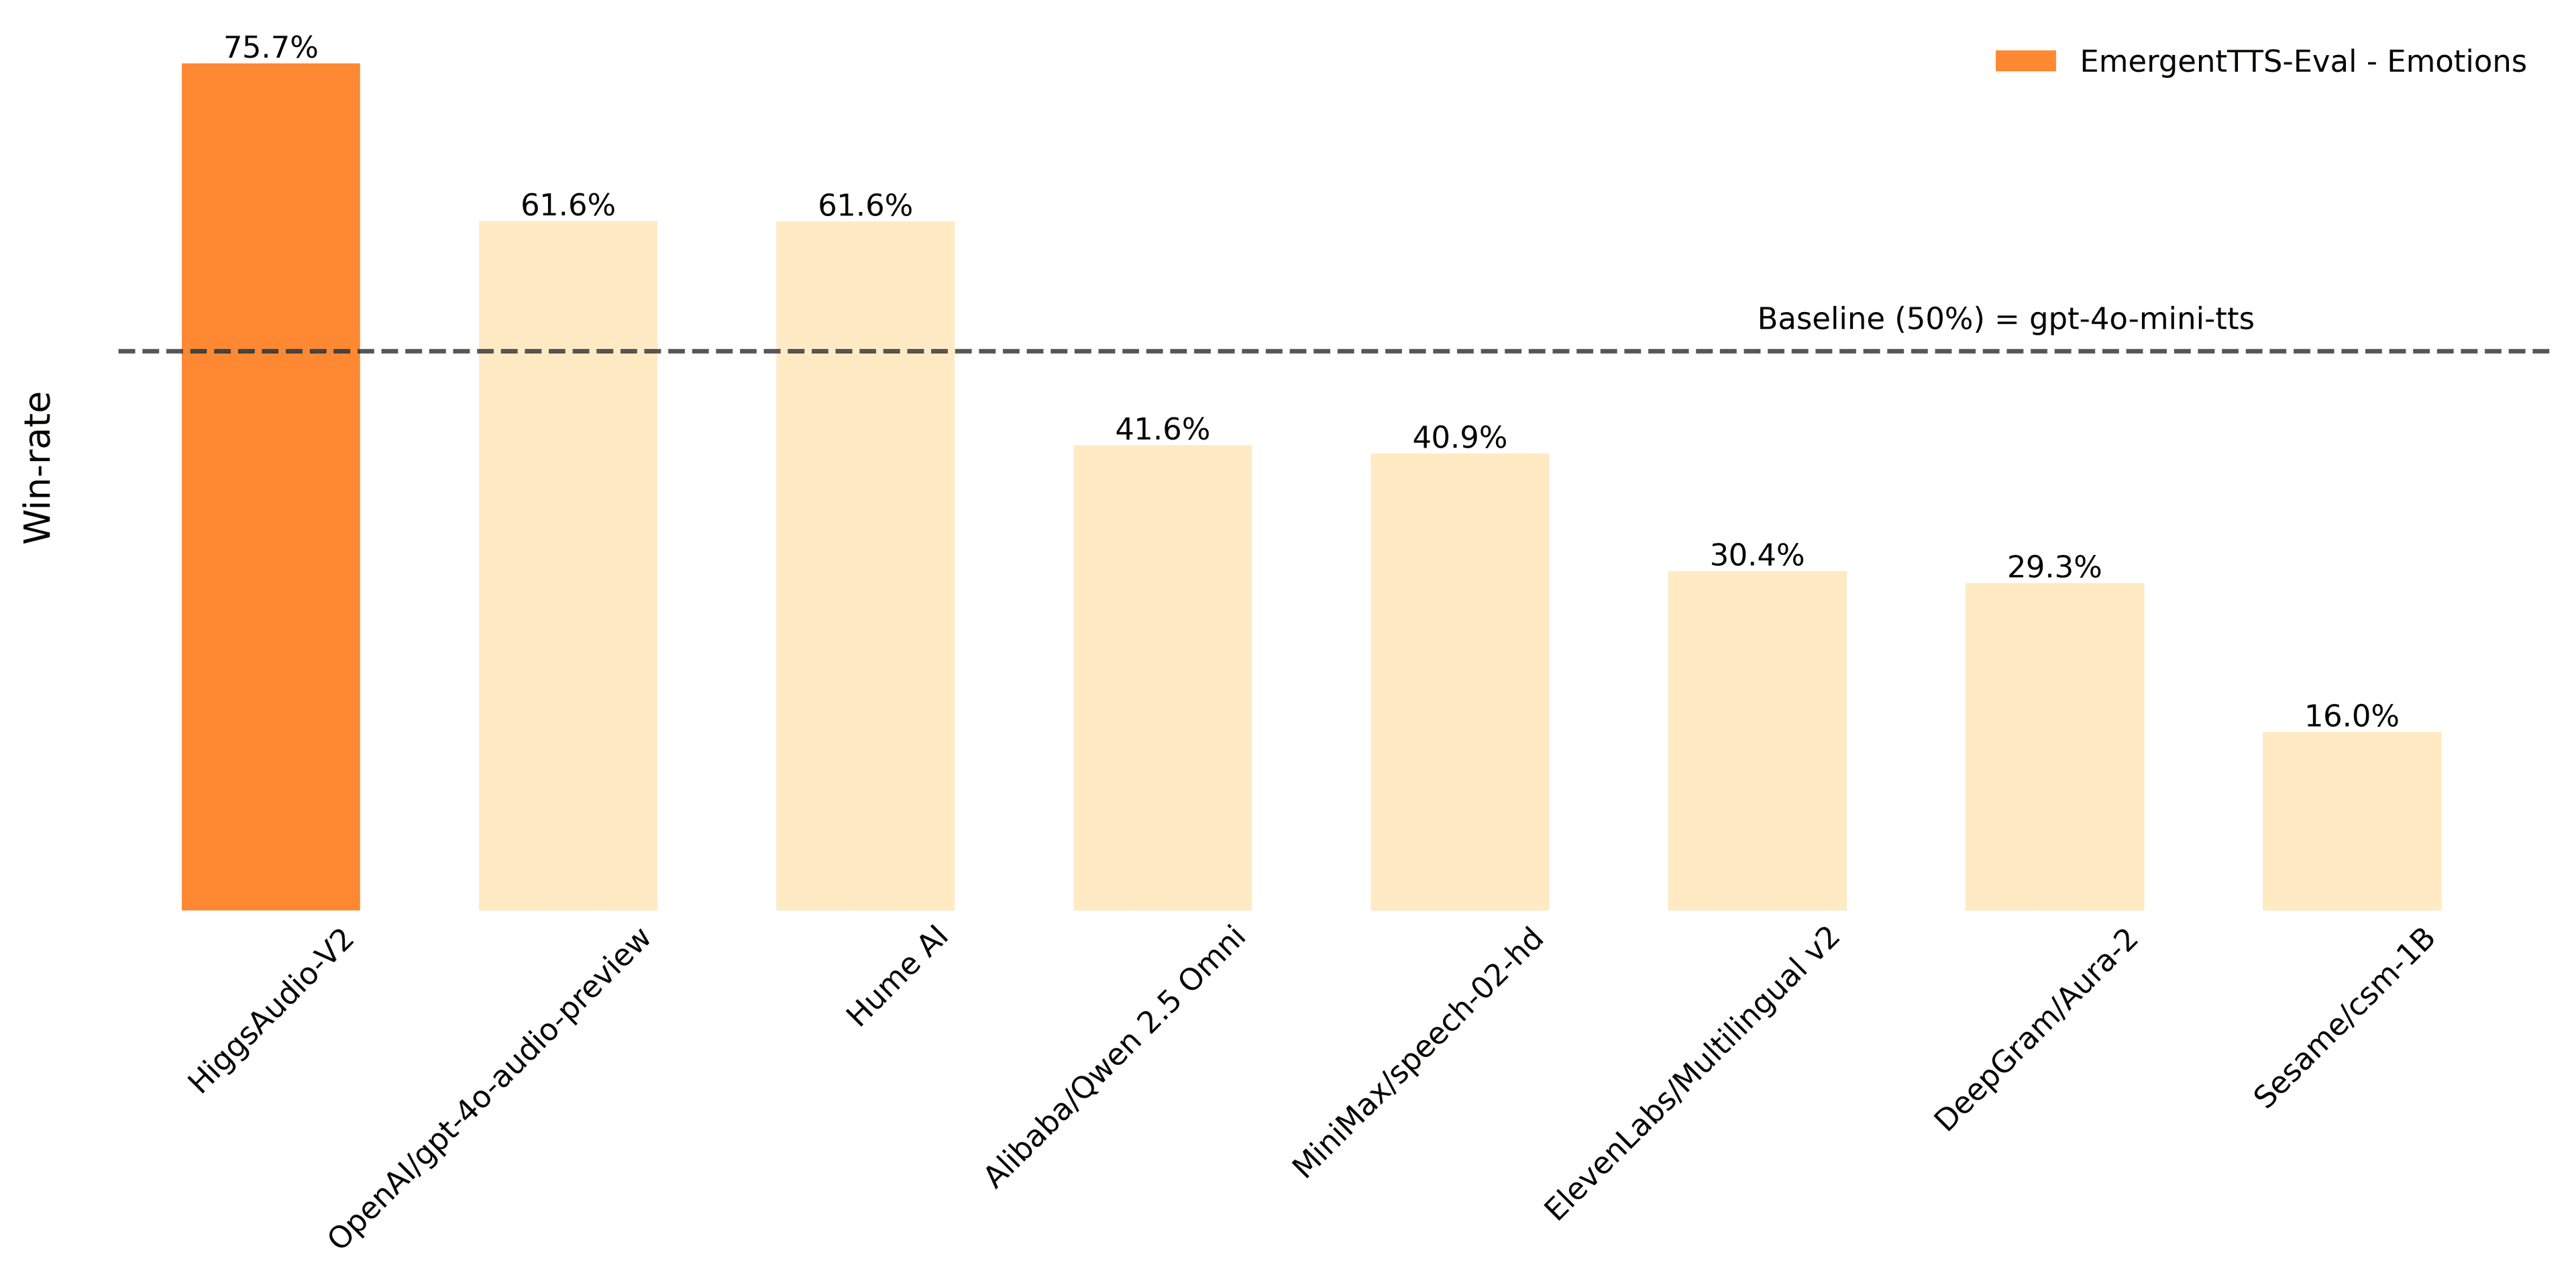
Boson AI Releases Higgs Audio v2 for Expressive TTS
The new 3-billion-parameter model focuses on generating expressive, multilingual speech and is fully open for commercial use under an Apache 2.0 license.
More in Text → Speech
All Text → Speech →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.

Fish Audio's Drama 3 brings MoE to open TTS
The open-source speech model pairs a 35B mixture-of-experts backbone with voice cloning and directed performance control.
0 comments
No comments yet. Be the first to weigh in.