Zhipu AI Releases Fast, Open Vision Model GLM-4.6V-Flash
The new model from the GLM-4.6V family offers a fast, MIT-licensed option for developers working with both text and images.
Zhipu AI has released GLM-4.6V-Flash, a new open-source vision-language model. As its name suggests, this "Flash" version is designed for speed and efficiency, joining the company's growing GLM-4.6V family of multimodal models.
The model's most significant feature for the open-source community is its permissive MIT license. This allows for broad adoption, including in commercial products, without the usage restrictions common to many research-oriented releases. This choice lowers the barrier for developers looking to build and deploy applications that can understand both images and text.
While technical details like parameter count and architecture specifics were not detailed in the initial release card, GLM-4.6V-Flash's focus on performance is clear. It provides another strong alternative in the competitive landscape of open vision-language models, particularly for use cases where low latency is a key requirement, such as real-time visual analysis or interactive chatbots.
This release solidifies Zhipu AI's position as a consistent contributor to the open-source ecosystem. By providing a fast, commercially-friendly VLM, the company offers developers a valuable new tool for building the next wave of multimodal applications.
Sources
- Visit
zai-org/GLM-4.6V-Flash
Hugging Face
More from Zhipu AI
All Zhipu AI releases →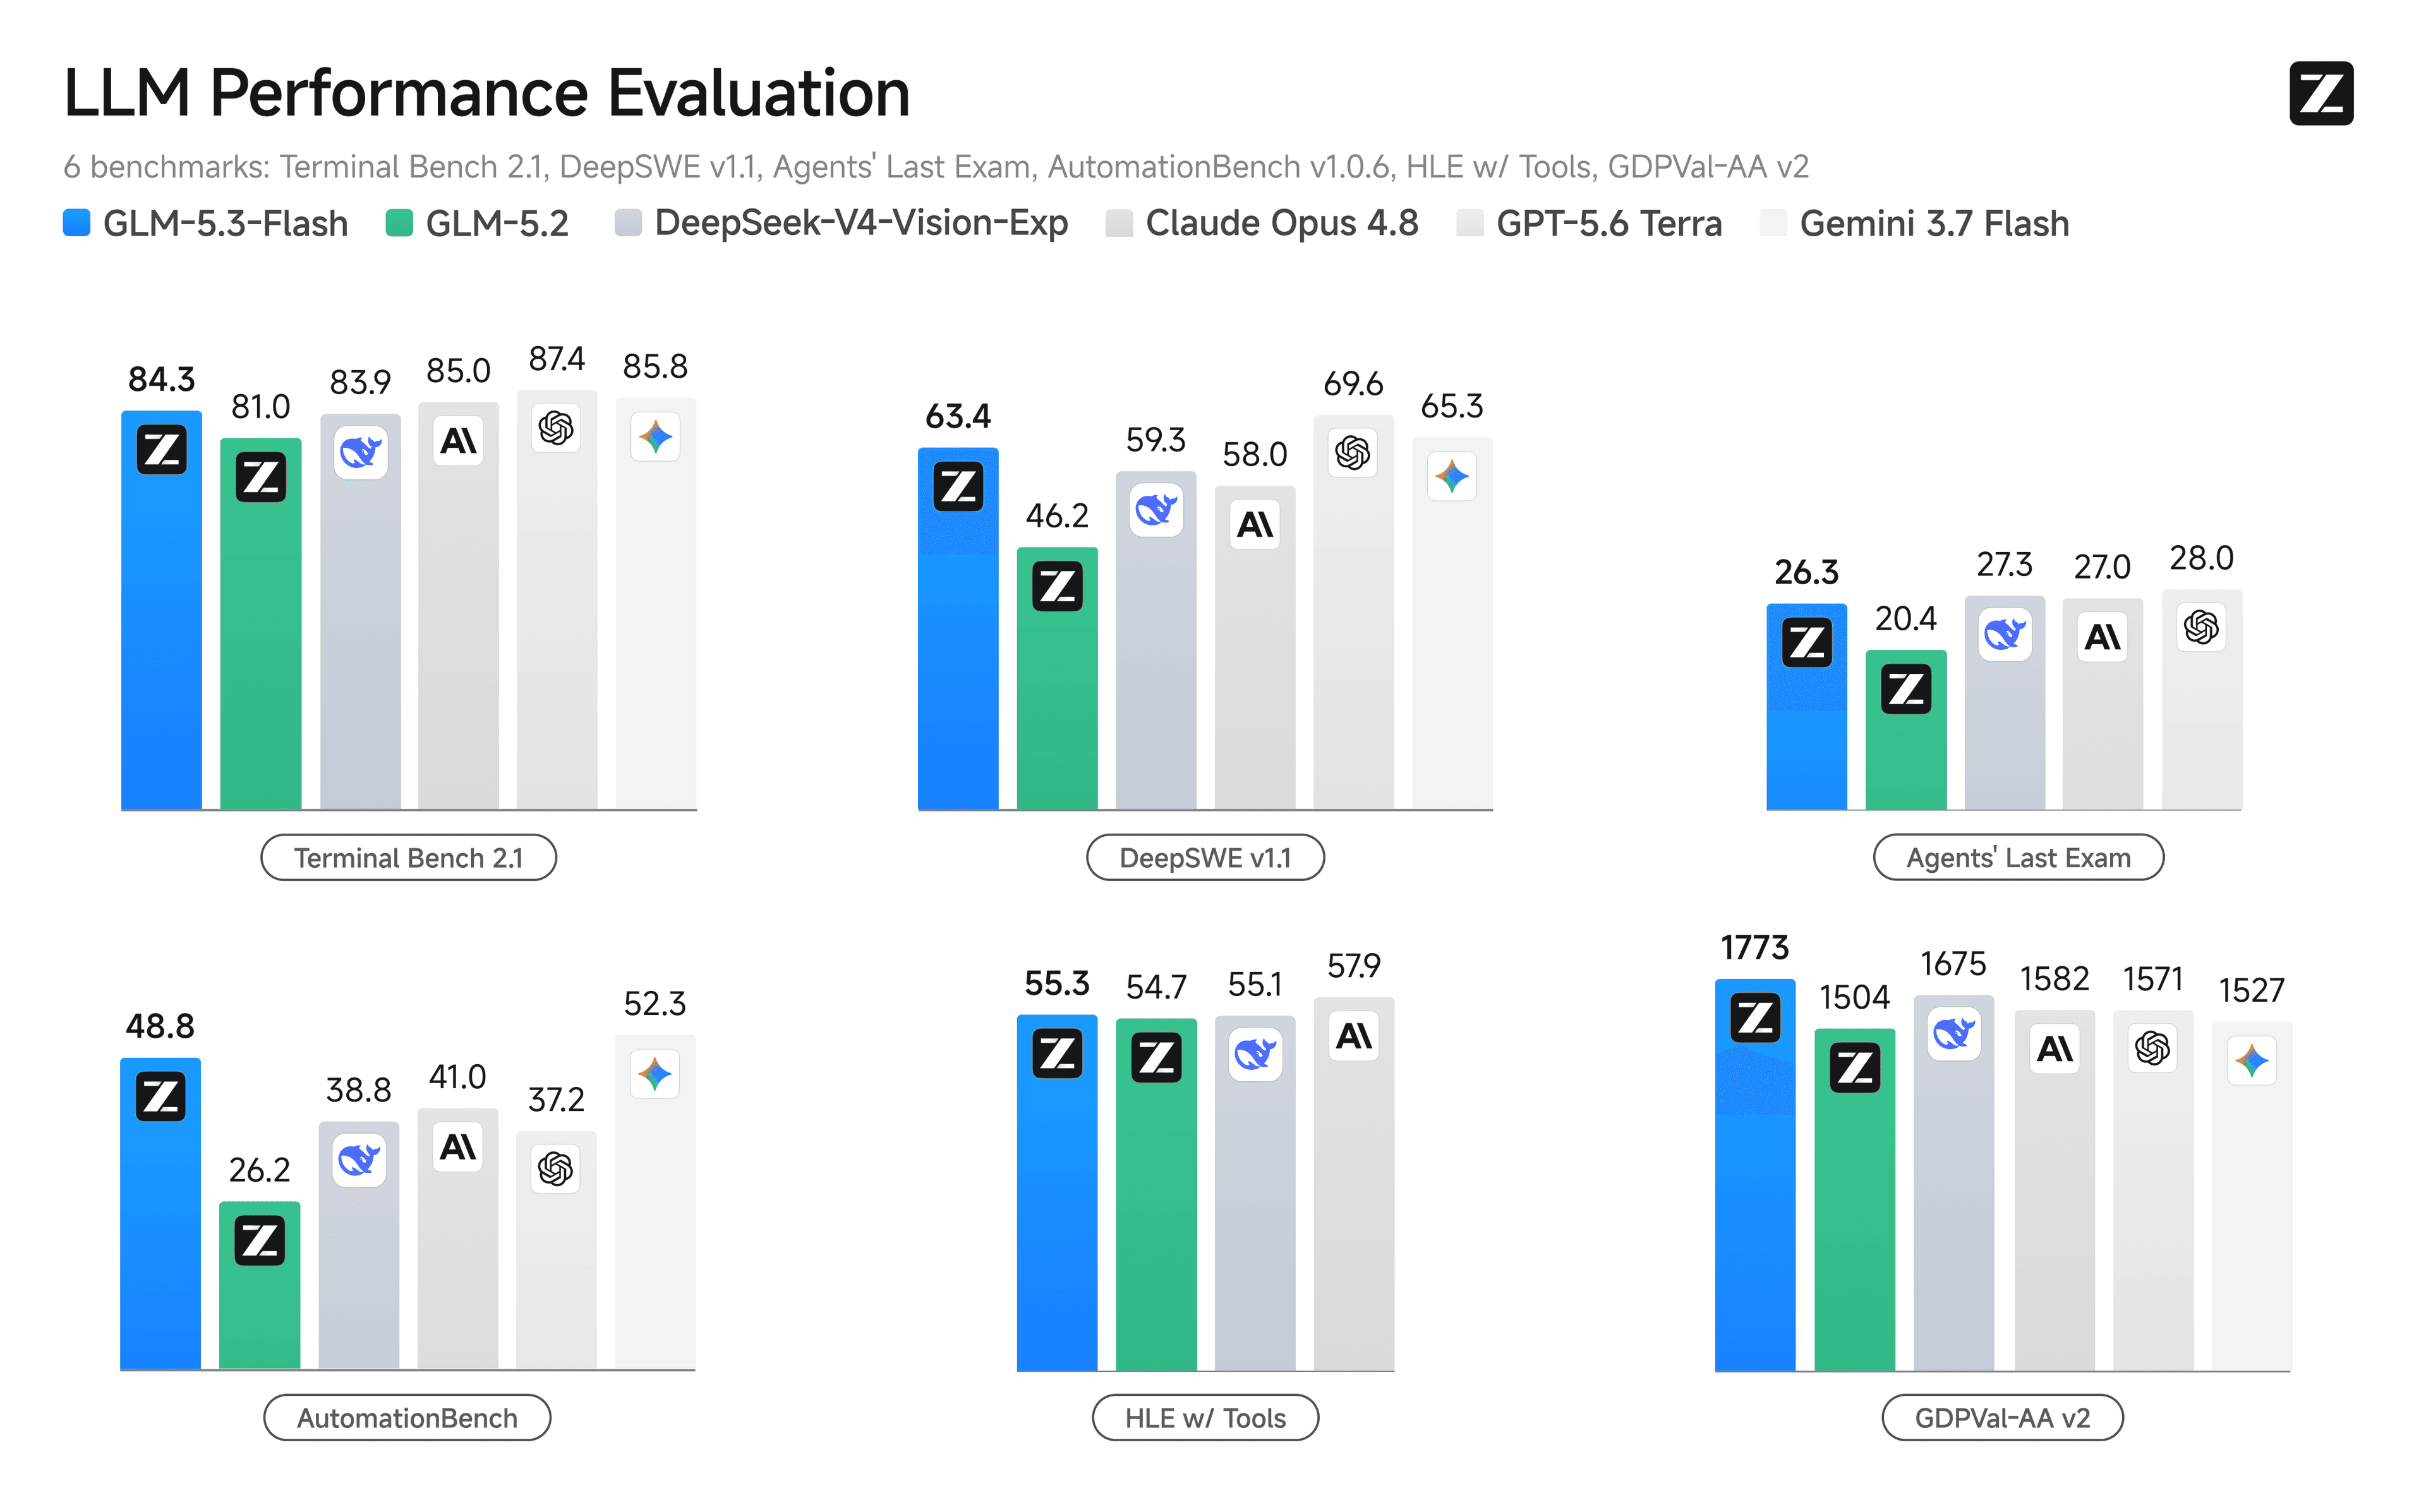
Zhipu releases GLM-5.3-Flash under MIT license
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
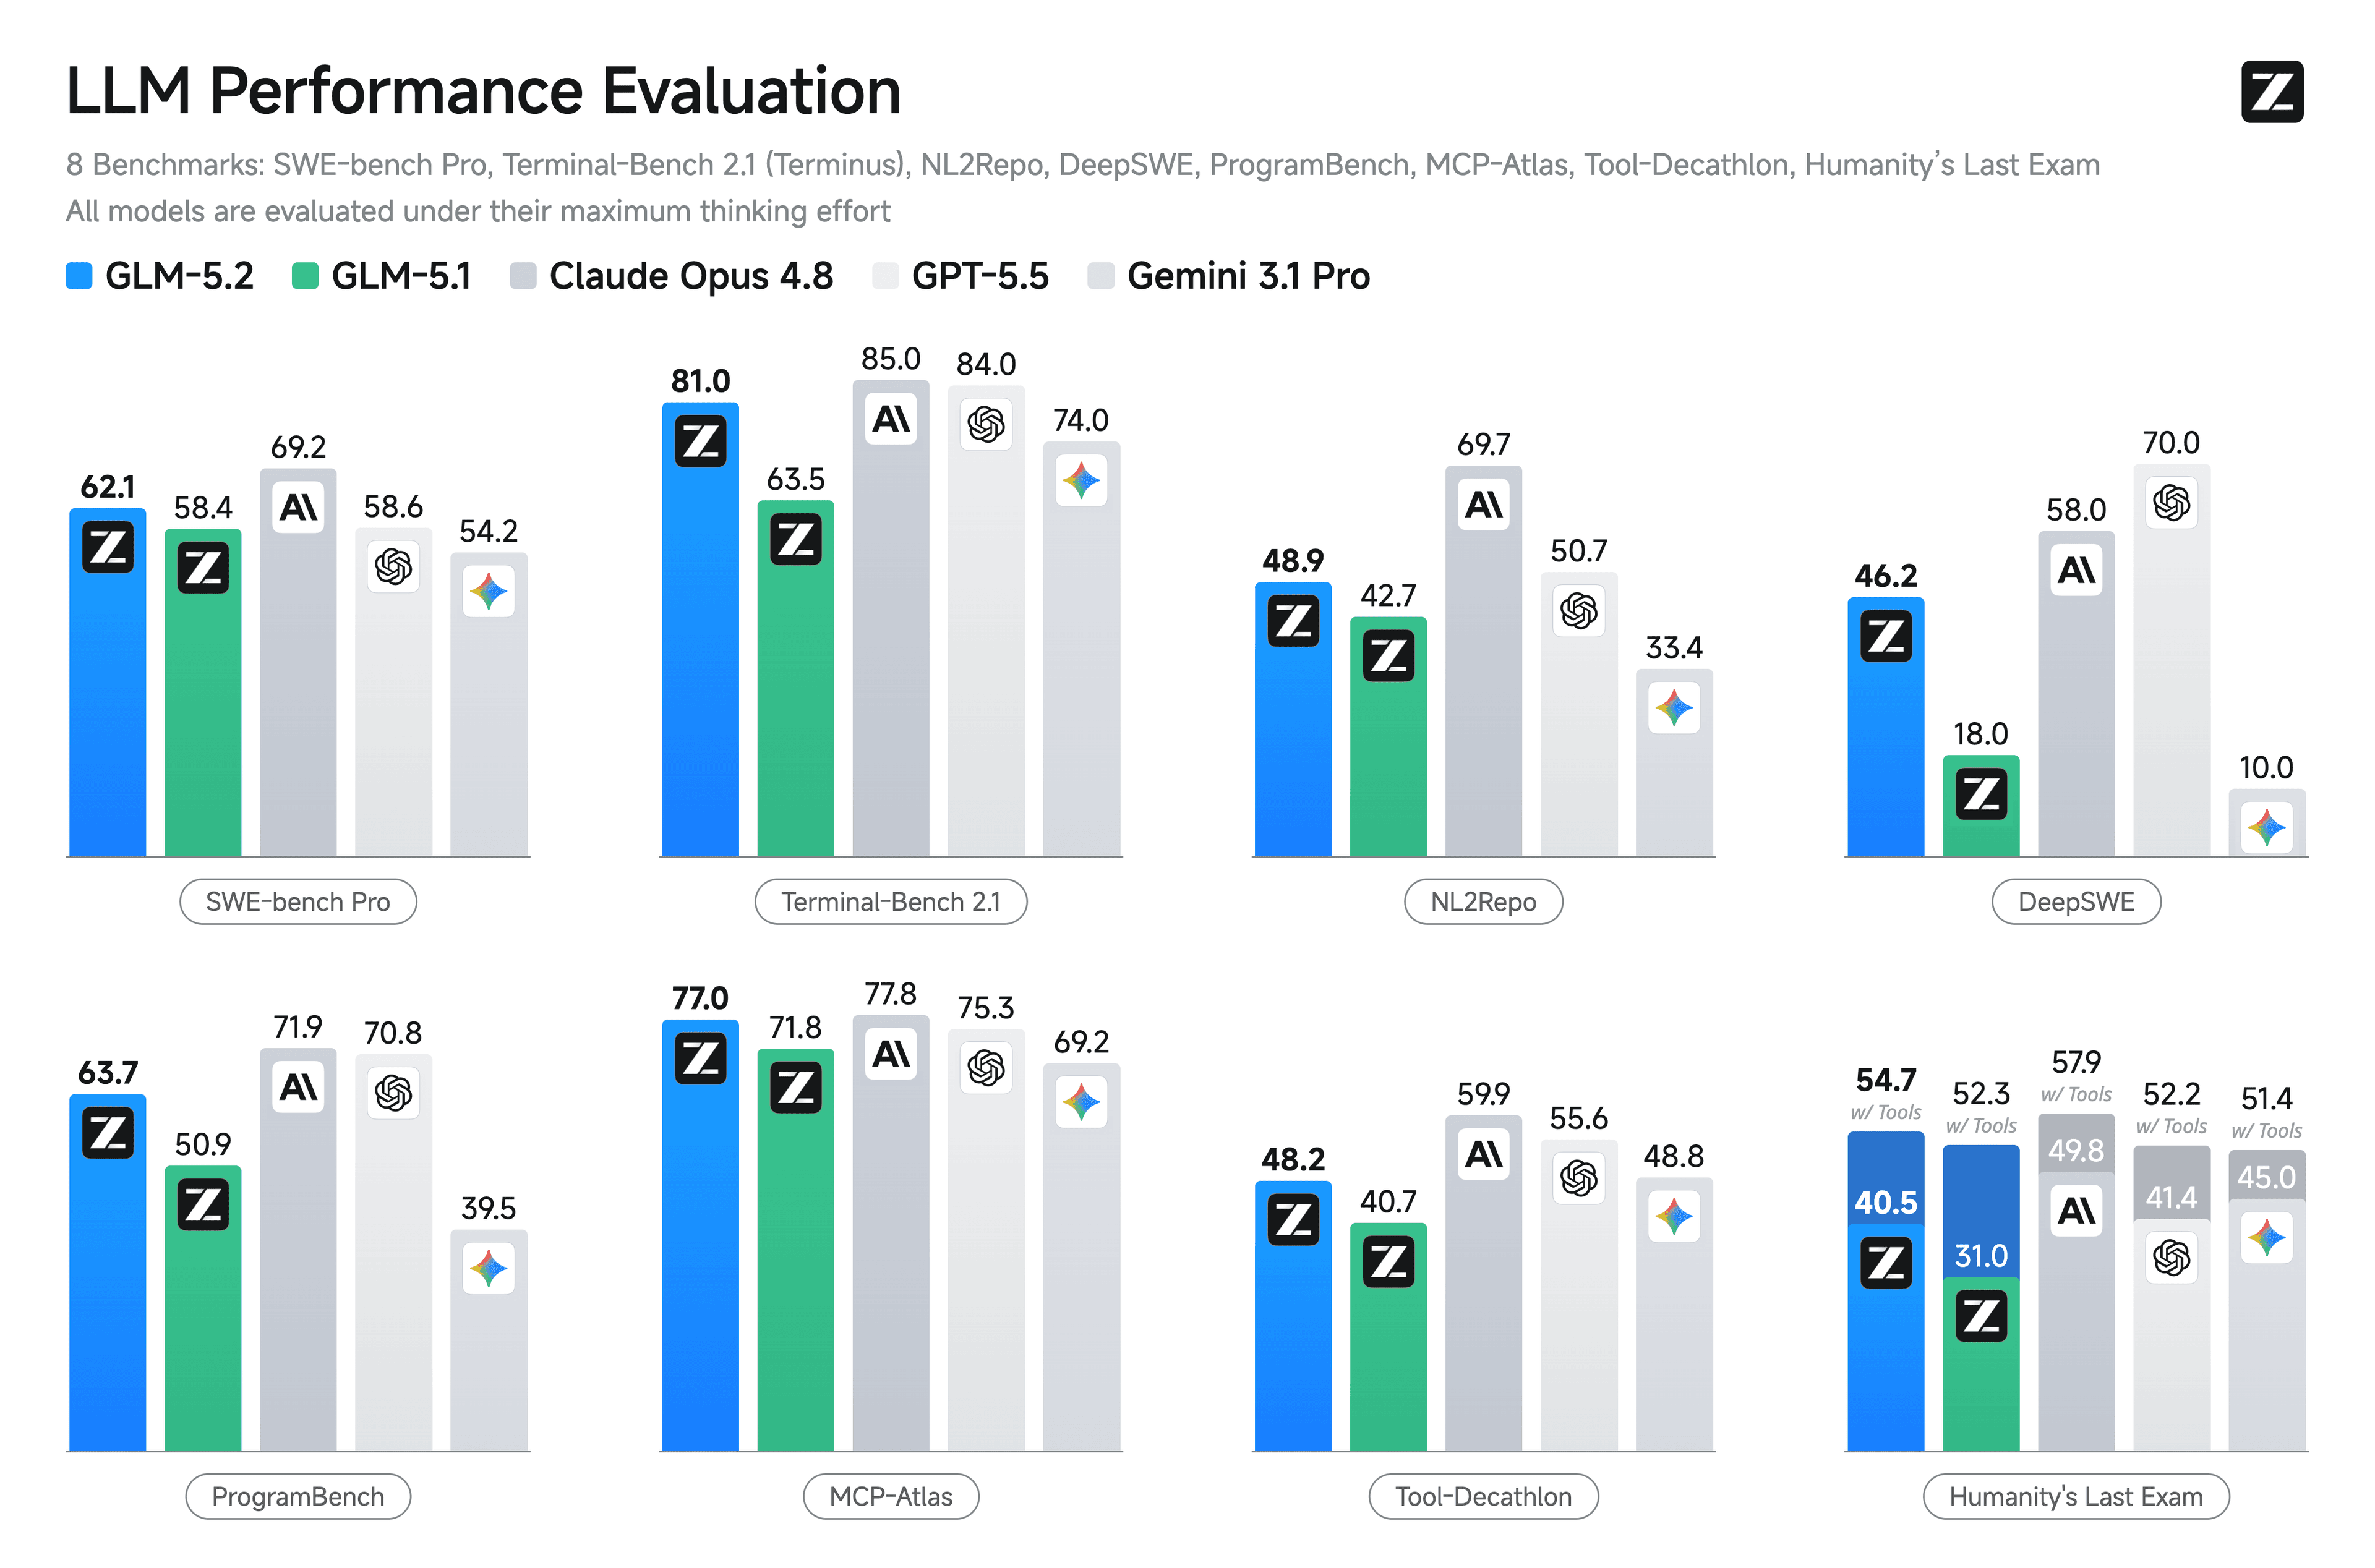
Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
More in Vision-Language
All Vision-Language →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
0 comments
No comments yet. Be the first to weigh in.