Microsoft previews GELab-Zero-4B, a compact GUI agent
The 4-billion-parameter vision-language model targets on-screen and mobile automation, built atop Qwen3-VL.

Microsoft has quietly posted a preview of GELab-Zero-4B, a compact vision-language model aimed at graphical user interface and mobile automation. According to the model's Hugging Face page, the roughly 4-billion-parameter model is built on Alibaba's Qwen3-VL foundation and framed as an agent that can perceive and act on screens.
GUI agents are a fast-growing niche in applied AI: rather than just describing an image, these models are trained to interpret app layouts, buttons, and text fields, then plan and execute the taps or clicks needed to complete a task. The vision component is what lets the model "see" an interface the way a user would, which is essential when there's no clean API to work against.
Why it matters
- At 4B parameters, GELab-Zero-4B sits in a size range that can plausibly run closer to the edge, which matters for mobile control where latency and privacy are concerns.
- Building on Qwen3-VL rather than a proprietary base signals Microsoft's continued use of open weights as a starting point for specialized agents.
- The "preview" and "Zero" labeling suggests this is an early, experimental checkpoint rather than a finished product.
Microsoft has released the model under an "other" license, and key details such as context length and formal benchmarks aren't specified in the record. As a preview, it's best read as a research artifact and a signal of where Microsoft's GUI-agent work is heading rather than a production-ready release.
Sources
- Visit
microsoft/GELab-Zero-4B-preview-Sico-Evolution
Hugging Face
More from Microsoft
All Microsoft releases →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.
Microsoft Releases FrogNano-4B Under MIT License
The compact 4-billion-parameter text model lands on Hugging Face with a permissive license aimed at developers.
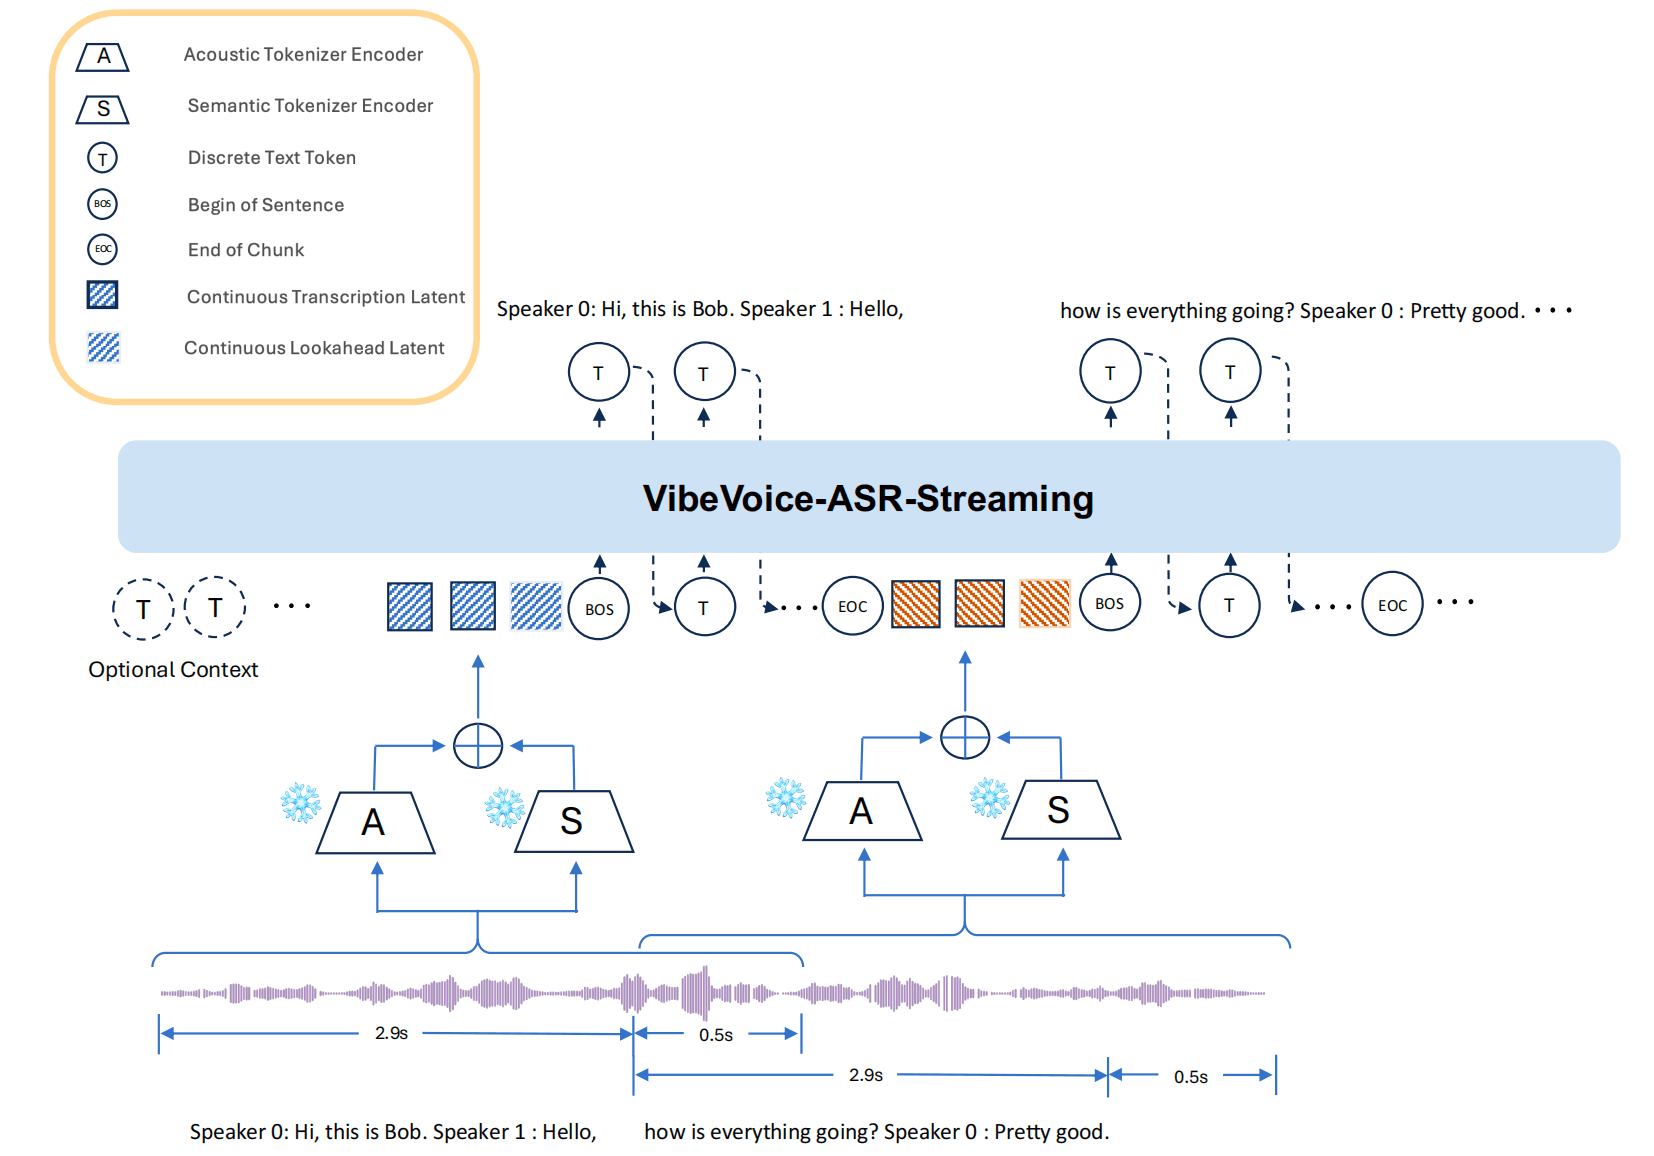
Microsoft's VibeVoice ASR brings streaming speech-to-text
A 7-billion-parameter model targets real-time, multilingual transcription with an open release on Hugging Face.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.