MuScriptor Large Turns Real Music Into MIDI
A new open model tackles multi-instrument transcription of real audio mixes, converting songs directly into editable MIDI.

Automatic music transcription has long been one of the harder problems in machine listening: pulling clean, note-level information out of a dense recording where several instruments overlap. MuScriptor Large, newly published on Hugging Face, takes aim squarely at that challenge, offering an open model for multi-instrument transcription that converts real audio mixes into MIDI.
The pitch is straightforward but ambitious. Rather than handling a single isolated instrument or clean studio stems, the model is built to work on real mixes — the kind of layered, messy audio that most listeners actually encounter. The output is symbolic MIDI, which means transcriptions can be edited, re-scored, or fed into downstream music tools.
Why it matters
Reliable audio-to-MIDI on full arrangements would be useful across a range of workflows:
- Musicians and educators who want to study or reproduce parts from recordings
- Producers looking to convert audio ideas into editable sequences
- Researchers building datasets and tools for music information retrieval
A few practical notes temper the enthusiasm. The model ships under a CC BY-NC 4.0 license, which restricts commercial use, so it lands most naturally in research and personal projects for now. The record also leaves parameter count and other technical specifications unstated, and the accompanying paper reference will be the place to look for benchmark details.
Still, an openly available model focused specifically on multi-instrument transcription of real recordings is a meaningful addition to the open music tooling landscape. For anyone working on the audio-to-symbolic pipeline, MuScriptor Large is worth a look.
Sources
- Visit
MuScriptor/muscriptor-large
Hugging Face
More in Music
StepFun's StepAudio 3 Music Plans Before It Plays
The new open model separates musical structure from sound, generating long-form tracks from text prompts with an explicit planning stage.
StepFun's StepAudio 3 Gen Unifies TTS and Music
A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.
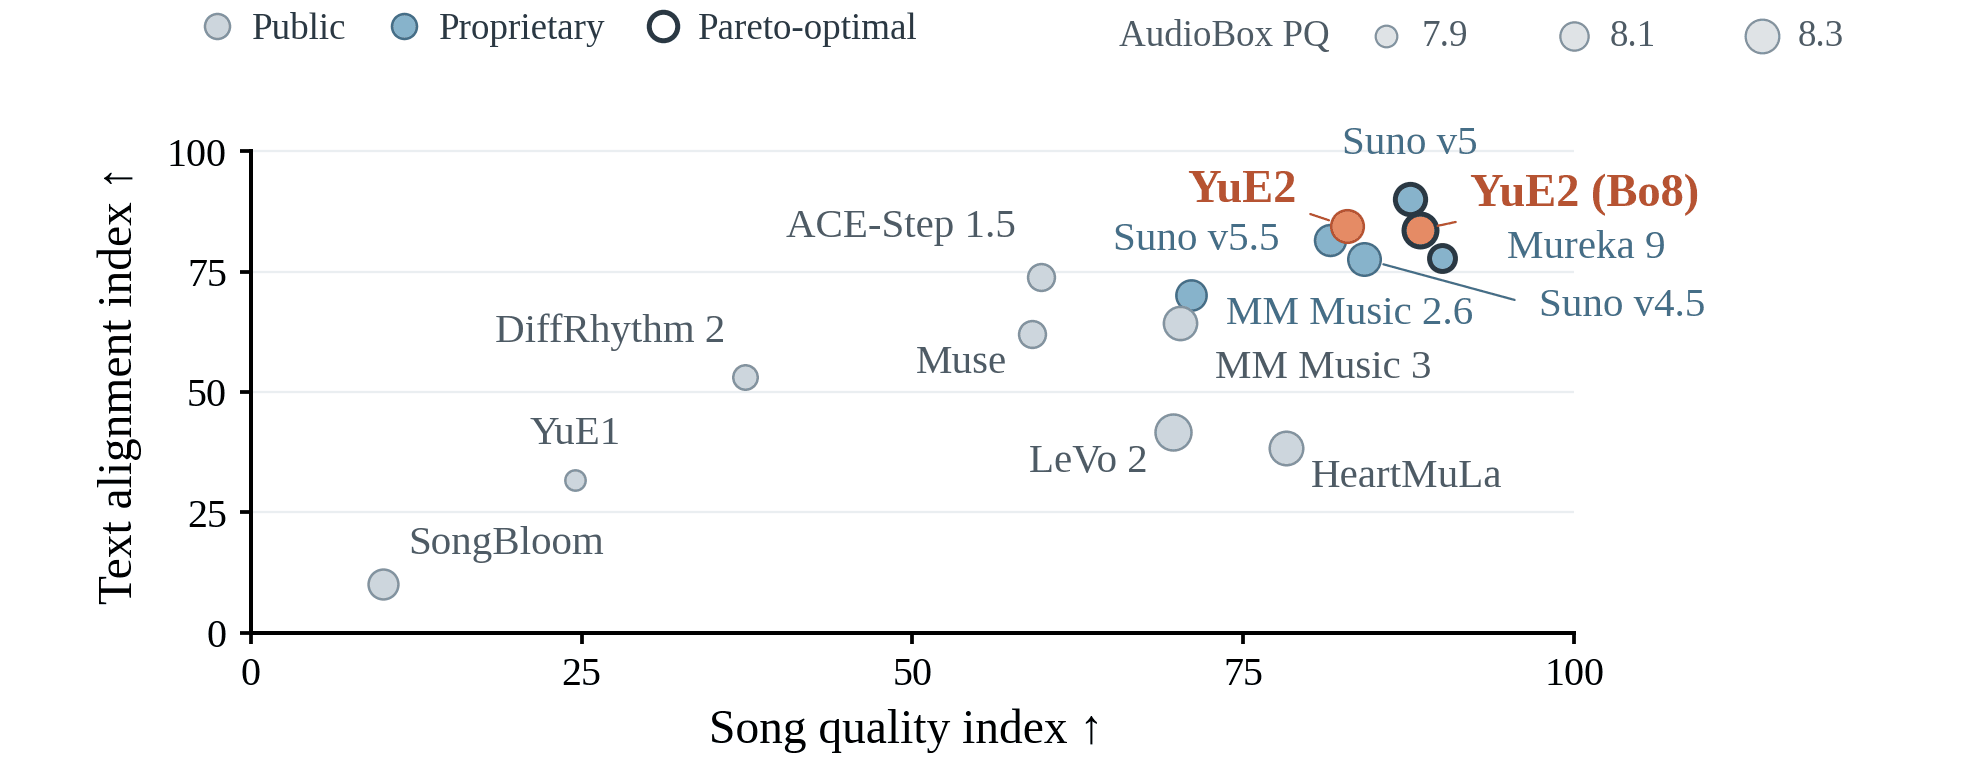
OpenMOSS Unveils YuE2-3B Music Generation Model
The 3-billion-parameter model adds symbolic planning and agentic editing to open-source music generation.
0 comments
No comments yet. Be the first to weigh in.