NVIDIA's Nemotron-Parse 2.0 targets document OCR
A compact vision-language model built to turn scanned pages and complex layouts into structured, machine-readable text.
NVIDIA has published Nemotron-Parse 2.0, a vision-language model aimed squarely at optical character recognition and document parsing. Rather than serving as a general chat assistant, the model is purpose-built to read images of documents and extract their text and structure.
Document parsing sits at the messy intersection of vision and language: forms, invoices, receipts, and scientific papers mix dense text with tables, columns, and figures that trip up naive OCR pipelines. A model tuned for this task is meant to preserve layout and reading order, not just dump characters.
Why it matters
Extracting clean, structured data from documents is one of the most common enterprise uses of AI, and it increasingly feeds retrieval and agent workflows that depend on accurate source text. Specialized parsers like this are attractive because they can be smaller and cheaper to run than routing every page through a large general-purpose model.
A few things to note from the release:
- It is distributed as a vision-language model on Hugging Face under a custom ("other") license, so teams should review the terms before production use.
- NVIDIA has not published parameter counts or context details in the record, so evaluation on your own documents remains the best guide.
As the first entry in the Nemotron-Parse line, version 2.0 signals NVIDIA's continued push to broaden its open-weight Nemotron family beyond text generation into practical document intelligence.
Sources
- Visit
nvidia/NVIDIA-Nemotron-Parse-2.0
Hugging Face
More from NVIDIA
All NVIDIA releases →NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
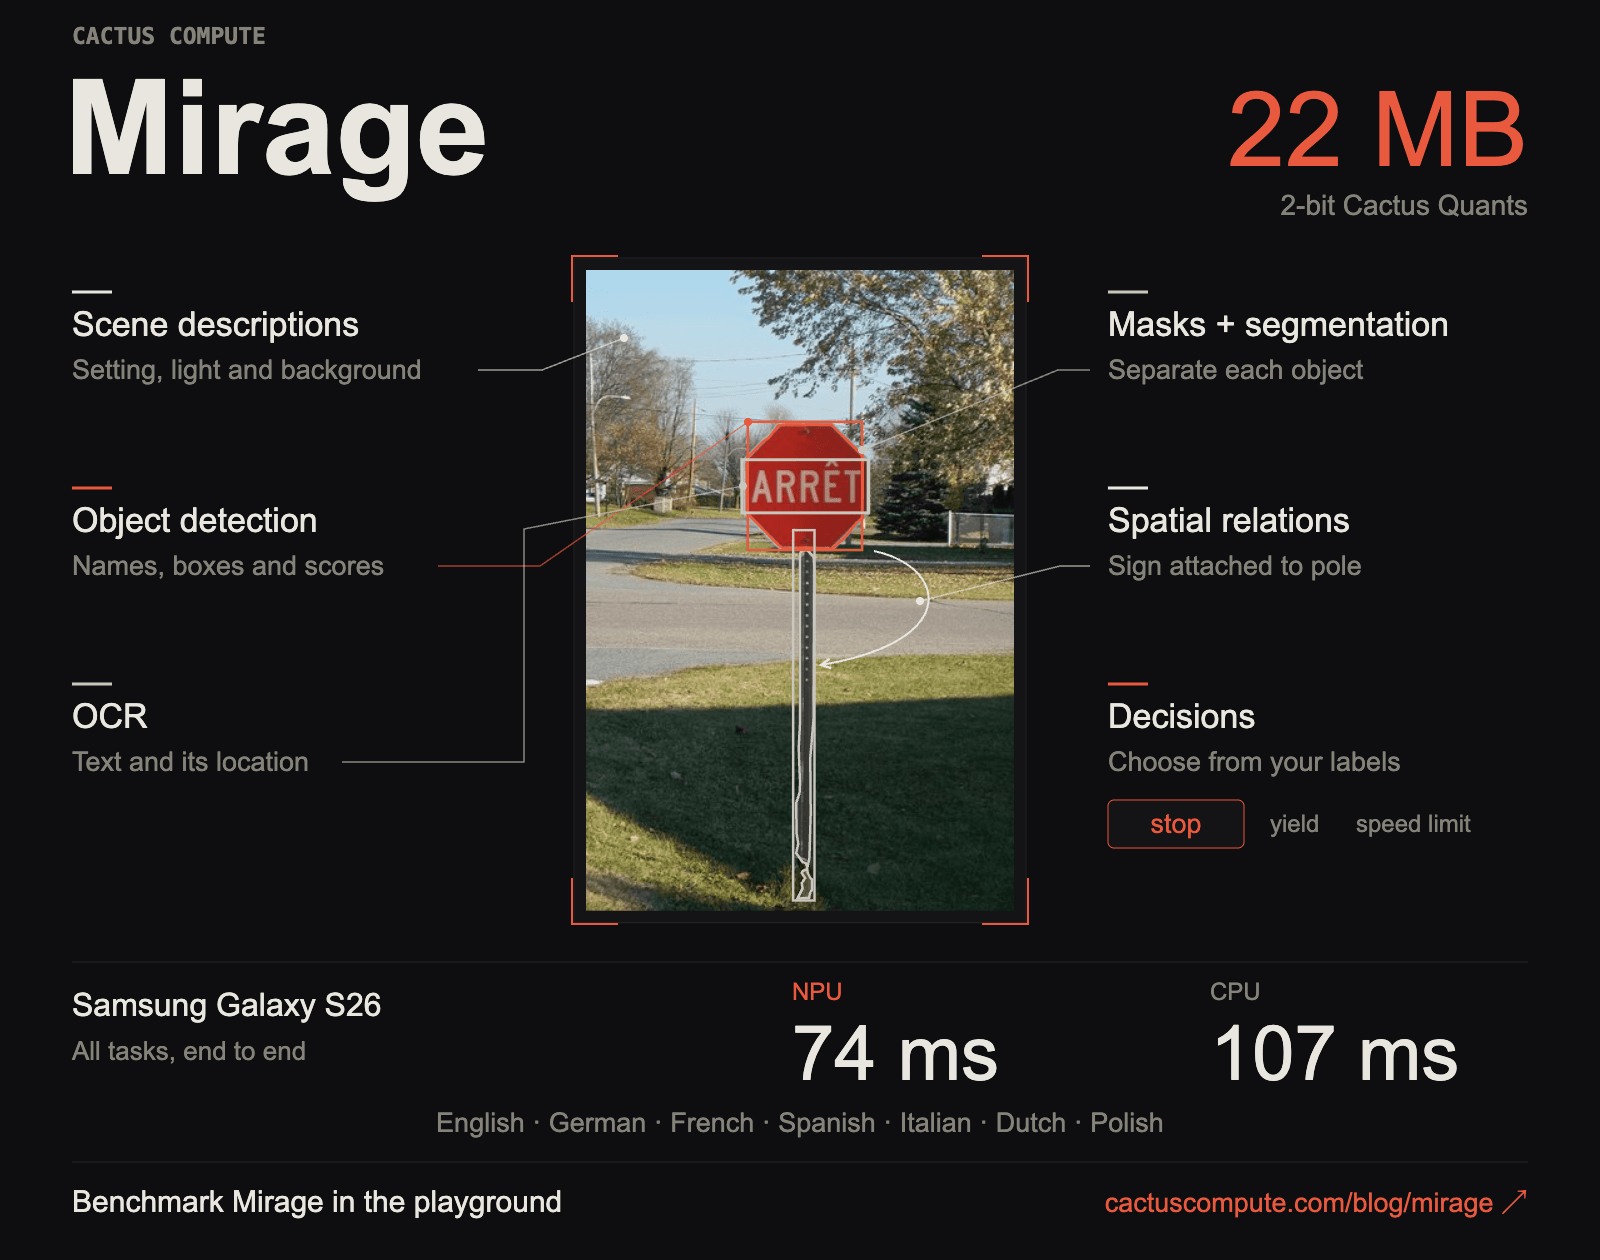
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
0 comments
No comments yet. Be the first to weigh in.