Apple's Depth Pro 2 extends metric depth to video
The latest monocular depth model aims for sharp, temporally consistent distance estimates across both stills and moving footage.
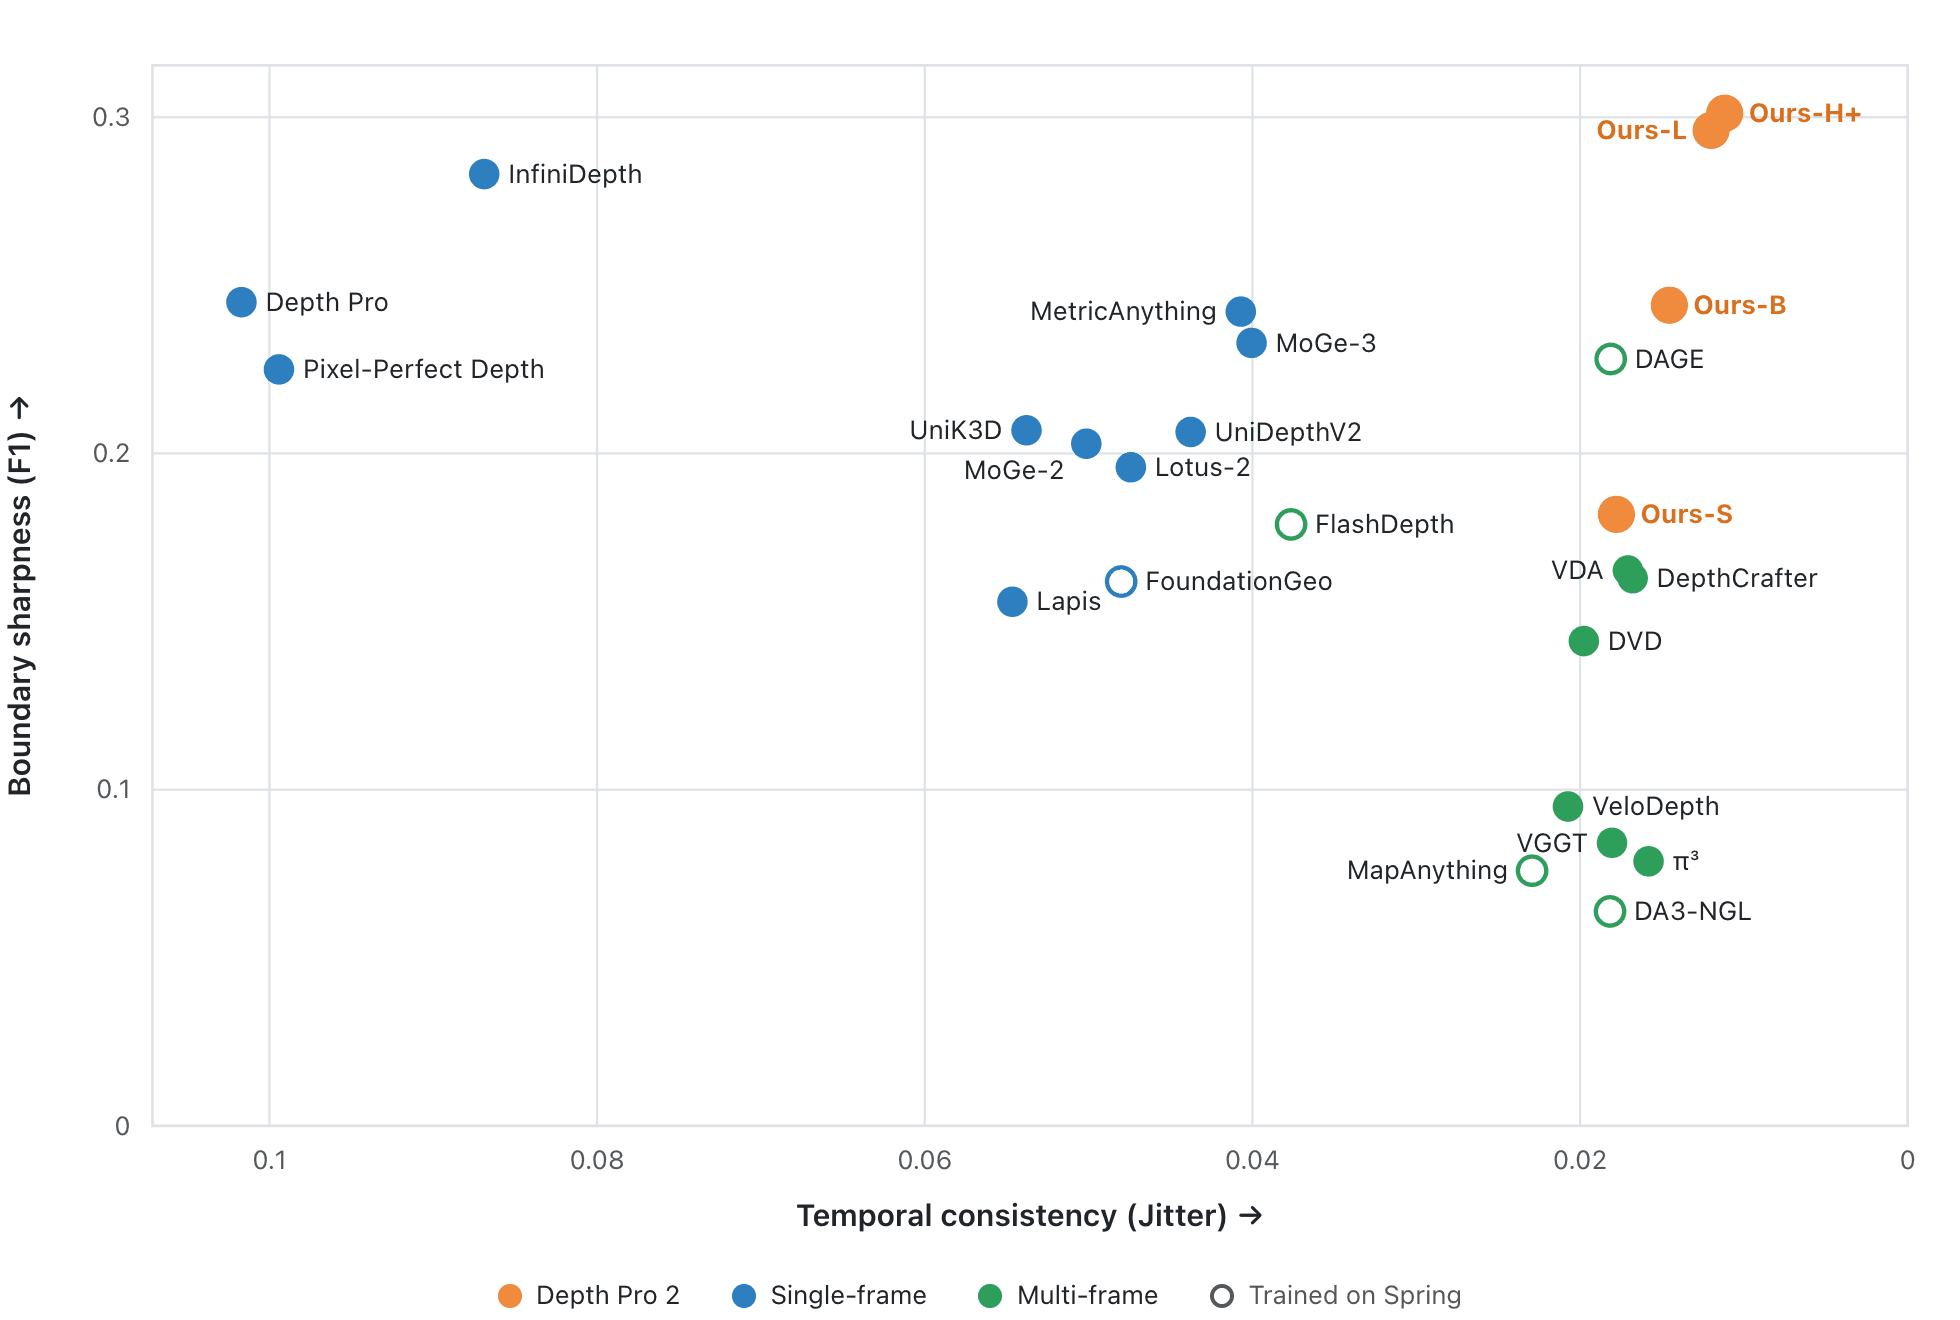
Apple has published Depth Pro 2 on Hugging Face, a monocular depth estimation model that infers real-world distances from a single camera input. The release extends Apple's depth work beyond still images to video, with an emphasis on temporal consistency so that depth maps stay stable from frame to frame rather than flickering.
The pitch is metric depth: instead of relative ordering of near and far, the model estimates actual distances, and it does so from ordinary imagery without specialized sensors. According to the model page, the focus is on sharp boundaries and consistency across time, two of the hardest problems in single-camera depth.
Why it matters
Reliable monocular depth is a building block for a wide range of downstream systems, and doing it well from a single camera lowers the hardware bar considerably.
- Sharp depth edges help with object segmentation and scene reconstruction.
- Temporal stability matters for anything that processes video rather than isolated frames.
- Metric output is directly useful for AR, robotics, and computational photography.
The model is distributed under a custom "other" license, so teams planning to build on it should read Apple's terms on the repository before integrating it. Full architectural details and benchmarks were not included in this record; the Hugging Face page is the authoritative reference.
Sources
- Visit
apple/DepthPro2
Hugging Face
More from Apple
All Apple releases →
Apple's FastFrames-L Targets Real-Time Video Generation
The company's new autoregressive text-to-video model aims for interactive latency, a notable shift for a field still dominated by slow batch rendering.
Apple's LensVLM-9B targets long-context vision tasks
A 9-billion-parameter vision-language model built on Qwen3.5-9B leans on visual-text compression to stretch its usable context.
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
Thinking Machines releases Inkling 2 Mini, a compact open MoE
The Apache-2.0 multimodal model uses a mixture-of-experts design aimed at running locally rather than in the cloud.
0 comments
No comments yet. Be the first to weigh in.